
Blink
Blink scores declared options in one forward pass through an embeddable C99 runtime, with cached state and WebAssembly support.
0.1.0Add to Favorites
Source
Get it from source
Spark does not host a copy of it.
Open sourceReports
Agent outcome reports
No reports yet
Overview
Blink returns probabilities over caller-declared options in one forward pass. Its C runtime supports caller-owned memory and exact cached-state reuse, with a browser-compatible WebAssembly build. Use it for structured, form-based decisions that can be evaluated on your workload. Its language-understanding limits and backend memory tradeoffs constrain broader use.
What it does
Blink is a typed-decision model with an embeddable C runtime and a WebAssembly build. Given state bytes, a question, and a menu of options, it returns one probability per option in a single forward pass. It generates no output tokens and needs no decoding loop or JSON repair. Applications can use confidence thresholds to choose an answer or escalate a decision.
The C99 runtime depends only on libc and libm. Default-build weights are mapped read-only and shared without copying. A caller-owned arena holds session working memory, so scoring requires no allocations. State, question, and options are encoded separately, allowing an unchanged state and menu to be reused exactly across questions. The byte-level architecture accepts identifiers, arbitrary languages, and embedded NULs without a tokenizer. It combines convolutional encoding, pooling, attention, and question-conditioned option scoring; the FiLM conditioning design has no demonstrated benefit at the measured scale.
When to use - and when NOT to
Use Blink for structured decisions where wording or form carries the answer, such as ticket routing or agreement between a claim and a state. It can link into services, daemons, devices, or browser applications. The supplied blink-tiny performs well on some form-based tasks, but it does not read text like a pretrained language model. Natural-language inference and binding names to the correct sentence remain near chance or only slightly above it. A larger experimental blink-small is slower and worse on the measured corpora, so its containers are not shipped.
Choose a backend according to memory and numerical requirements. Default C and W8A8 preserve allocation-free scoring. W8A8 rounds activations to int8 and changes the model numerically, although its integer kernels agree with each other. Accelerate trades allocation guarantees, memory, and batch bit-identity for macOS throughput; cached states still reuse exactly. Confidence and latency need evaluation on the intended workload.
Inputs and outputs
Inputs are a model container, session limits and arena, state, question, and declared options. Outputs include option probabilities and the selected result. The committed model can be queried from the shell without training:
./build/blink artifacts/blink-tiny-synthetic-s7.blink \
  --state "The parcel left the depot on Monday and has not arrived." \
  --question "Which team should handle this ticket?" \
  --option "delivery and logistics" \
  --option "billing and payments" \
  --option "account access and sign-in"
For that example, the delivery choice has probability 0.56, below an illustrative 0.8 escalation threshold. Training and evaluation use Python with PyTorch and NumPy; the C runtime builds without Python. Corpus generation splits related scenario groups together to prevent state leakage. Evaluation includes calibration, shuffled controls, untrained models, perturbations, and held-out groups.
Runtime options and examples
On one Apple M5 Pro core, blink-tiny over a 256-byte state and four options has reported median fresh-decision latency of 406 microseconds for default C, 221 for W8A8, and 172 for Accelerate. Reusing the state reduces these to 54, 33, and 32 microseconds respectively. These figures describe that setup. Default tiny weights occupy 452 KiB, with a 260 KiB default arena or 22 KiB at the smallest limits. Accelerate additionally copies projection matrices and increases memory use.
NEON, x86 SSE2/AVX2, and optional SDOT/I8MM kernels support native execution. The same sources produce a 66 KB WebAssembly reactor running in browsers and Node with stubbed WASI calls and no filesystem access. Snake and BlinkPilot rank textual outcomes computed by a game or planner; their results do not establish board reasoning or autonomous driving. The Doom demonstration uses a JavaScript rules model rather than a bit-exact ViZDoom port, so its Jev comparison is contextual. Single-MPS-seed demonstration runs are not bit-reproducible. Blink uses Apache-2.0 licensing; imported datasets and fixtures retain their own terms.
Source README
Blink
A one-pass typed-decision model with an embeddable C runtime that also builds to WebAssembly.
TypeSafe released Jev, a closed model in a class they call System One Models: fast structured decisions for software rather than conversation, with calibrated confidence and no output tokens to pay for. Blink puts that interface behind a C library you can link into a service, a daemon or a device, or load as WebAssembly in a web page.
Blink answers questions of the form "given this state and this criterion, which of these options?" in a single forward pass. There is no token generation, no decoding loop, no JSON to parse and nothing to repair: the output is one probability per option you declared at call time.
The runtime is C99 with no dependencies beyond libc and libm. Weights are mapped read-only and never copied. Scoring performs zero allocations - a property the test suite checks mechanically, not by inspection.
The same sources build to a 66 KB WebAssembly module that runs unchanged in browsers and in Node, with no file system and no server (details).
#include "blink.h"

blink_model  *model   = blink_model_open_file("blink-tiny.blink", 1, &status);
blink_session *session = blink_session_init(arena, sizeof arena, model, &limits, &status);

blink_state_set(session, ticket, strlen(ticket));           /* encode once  */
blink_menu_set(session, queues, lengths, 4);                /* encode once  */
blink_score(session, "Which team should handle this?", 29,  /* cheap        */
            probabilities, &result);
What it is good for, in one paragraph. Blink recognises the form of a decision; it does not read text the way a pretrained language model does. Where the answer is carried by form - which queue a ticket's wording points at, whether a claim's verb agrees with the state - blink-tiny is near perfect and well calibrated. Where the answer requires reading - natural language inference, binding a name to the right sentence - it is at or a little above chance, and a frozen 4B model is far ahead. Its confidence is calibrated enough to branch on: answer when it is sure, escalate when it is not.
Performance
blink-tiny on one core of an Apple M5 Pro: one decision over a 256-byte state, a question and four options, p50.
| build | fresh decision | same state, new question | decisions/s, state reused |
|---|---|---|---|
| default (C99, NEON) | 406 µs | 54 µs | 18,211 |
| W8A8 (int8 activations, SDOT) | 221 µs | 33 µs | 29,481 |
| Accelerate (macOS) | 172 µs | 32 µs | 31,290 |
A fresh decision encodes the state, the options and the question. Software usually asks several questions of the same state, and then only the question is encoded: the cached state is reused exactly, bit for bit. On x86-64 the AVX2 kernel does the same decision in 760 µs, and 90 µs with the state reused, on a GitHub-hosted runner.
Memory. Nothing is allocated while scoring: not per decision, not per
question, not per option. All the working memory a session needs is one
arena, sized before the session exists and placed wherever you choose, a static
array or a stack buffer included, so Blink runs where malloc is unavailable
or not allowed. This is checked, not assumed: tests/c/check_no_malloc.sh
fails the build if the scoring code references any allocator.
blink-tiny's weights are 452 KiB of int8, mapped read-only and shared by every session and every process that opens the same file. The arena is 260 KiB with the model's default limits and 22 KiB with the smallest. One decision from the command line peaks at 2.5 MiB of resident memory, the whole process included. The W8A8 build keeps the no-allocation guarantee; the Accelerate build gives it up, because the framework allocates inside its matrix products (details).
A larger preset, blink-small (7.9M parameters), is experimental: it is worse than blink-tiny on every corpus measured and about ten times slower to encode, so its containers are not shipped (why).
All the benchmark tables, and a comparison with other systems that expose the same interface, are in docs/RESULTS.md.
Quick start
git clone https://github.com/sqliteai/blink
cd blink
make                     # C runtime, tools, benchmarks. No Python needed.
make test                # unit tests + the no-allocation check
make bench               # latency and memory as JSON
make install             # blink, libblink, blink.h, blink.pc, man page under /usr/local
make ACCELERATE=1 test   # macOS only: the Accelerate backend, in build-accelerate/
make W8A8=1 test         # int8 activations with SDOT/I8MM, in build-w8a8/
Training and evaluation need Python:
uv venv --python 3.12 .venv
uv pip install --python .venv/bin/python torch numpy pytest
export PYTHONPATH=python

.venv/bin/python scripts/make_data.py                    # deterministic corpus
.venv/bin/python -m blink_train.train \
    data/synthetic/train.jsonl \
    --validation data/synthetic/validation.jsonl \
    --preset tiny --output artifacts/blink-tiny.blink \
    --epochs 60 --learning-rate 3e-3 --device auto

.venv/bin/python eval/evaluate.py \
    artifacts/blink-tiny.blink data/synthetic/test.jsonl
One decision from the shell, with the committed blink-tiny (no training needed):
./build/blink artifacts/blink-tiny-synthetic-s7.blink \
  --state "The parcel left the depot on Monday and has not arrived." \
  --question "Which team should handle this ticket?" \
  --option "delivery and logistics" \
  --option "billing and payments" \
  --option "account access and sign-in"
It answers delivery and logistics with probability 0.56: the right queue, with a confidence low enough that a caller branching at 0.8 would escalate it.
./build/blink --version prints the library version and the numeric
backend it runs on this CPU, for example blink 0.1.0 (neon). Every option,
the output fields and the exit codes are in docs/CLI.md, also
installed as the blink(1) man page.
make install puts blink, libblink.a, the shared library, blink.h, a
blink.pc for pkg-config and the man page under /usr/local. Use
PREFIX=... to choose another place and DESTDIR=... to stage a package;
make uninstall removes them again. The shared library is named after the ABI
version, libblink.so.1 on Linux and libblink.1.dylib on macOS.
To reproduce everything - build, tests, data, training, accuracy, controls, perturbations, benchmarks, and a manifest of every checksum:
bash scripts/run_all.sh            # the published protocol, about 2 h on an M-series laptop
bash scripts/run_all.sh --smoke    # every stage on a small corpus, a few minutes
The architecture in one diagram
  state bytes              question bytes           option bytes
       │                         │                        │
   unigram + hashed bigram + position + segment embedding (each separately)
       │                         │                        │
   stem: depthwise conv + pointwise projection, full resolution
       │                         │                        │
   mean-pool by stride 4, then blocks: conv + global mean + FFN, self-attention mixer
       │                         │                        │
   state K, V  ◄──── cross ──── question                  │
   (cached)          (the question attends to the state)  │
       │                         │                        │
       │                  question summary ──── FiLM ──► option vectors
       │                                                  │
       └─────────► multi-head cosine option attention ◄───┘
                                 │
            Σ head cosines × scale / temperature → softmax over the options
Four decisions carry most of the design, and each is explained with its rationale in docs/ARCHITECTURE.md:
- Byte level, no tokenizer. Program state is not curated text. Bytes accept JSON, identifiers, any language and embedded NULs, and there is no second artefact to keep in sync.
- Stem, then pool, then blocks. Running a feed-forward at every byte is what makes byte-level encoders expensive. Blink runs one cheap full-resolution stem, pools by the stride, and only then pays for the blocks. A 512-byte state is 64 positions before any block executes.
- State and question are encoded separately. Reusing an encoded state is
therefore exact, not approximate:
tests/c/test_session.cchecks it withmemcmp. - Queries are conditioned on the question. An option query built from the option text alone lets the question reach the score by one indirect route: the keys and values it adds to the shared context. Blink additionally modulates each option vector with a summary of the question, which gives the two a direct place to meet. A three-run ablation finds no demonstrated effect at this scale - between-seed spread exceeds the gap between the arms - so this is a motivated design choice, not a measured win. The table is in docs/RESULTS.md.
Memory
Blink allocates no memory while scoring. Its memory comes in three parts, and the third is zero:
- Weights - mapped read-only, never copied, shared by every process and every session.
- Session arena - one contiguous block whose size is a pure function of the
model and the limits you declare.
blink_session_sizetells you the number andblink_session_initplaces the session in a buffer you own: a static array, a stack frame, a pool. - Scoring - no allocation at all.
tests/c/check_no_malloc.shasserts thatblink_runtime.oandblink_kernels.oreference no allocator symbol.
examples/embed_static.c is the whole pattern in 100 lines with no heap.
These guarantees describe the default build. The W8A8 backend keeps all of them except exact agreement with the W8A32 definition. The Accelerate backend trades two of them for speed.
W8A8 backend (SDOT / I8MM)
make W8A8=1 builds into build-w8a8/, with the activations quantized to
int8 too. Each input row of a projection gets its own scale and the product
becomes an exact integer sum. It runs on SDOT. I8MM is chosen at run time on
non-Apple cores that have it; on Apple silicon it measured level with SDOT
and would need an extra copy of the weights, so SDOT stays the default there
(BLINK_W8A8_KERNEL=scalar|sdot|i8mm overrides the choice). On
a CPU without either, a plain integer loop computes the same thing.
| 4 options, p50 | default | W8A8 | speed-up |
|---|---|---|---|
| blink-tiny, fresh decision, 256-byte state | 406 µs | 221 µs | 1.8× |
| blink-tiny, state reused | 54 µs | 33 µs | 1.6× |
| blink-small, fresh decision, 512-byte state | 4.29 ms | 1.45 ms | 3.0× |
| blink-small, state reused | 314 µs | 115 µs | 2.7× |
What it keeps: nothing allocates while scoring, a cached state is reused
exactly, a batch is bit-identical to single questions, and the scalar, SDOT
and I8MM kernels are bit-identical to each other. What it changes is the
model, since activations are rounded to 8 bits. On all 15 published models,
top-1 moved by −0.15 to +0.42 points and calibration did not change. The
decisions that flip are near-ties, almost all in task families the model sits
at chance on (details). The parity suite
checks it against the float64 reference with the same rounding.
blink_backend() says which build and kernel is running.
Accelerate backend (macOS)
make ACCELERATE=1 builds the same library into build-accelerate/, with
the matrix products routed through Apple's Accelerate framework. On Apple
silicon Accelerate runs them on the CPU's matrix unit instead of on NEON. The
layer norms and the attention reads go through vDSP and BLAS as well. The
default build/ is untouched.
| state 256 bytes, 4 options, p50 | default | Accelerate | speed-up |
|---|---|---|---|
| blink-tiny, fresh decision | 406 µs | 172 µs | 2.4× |
| blink-tiny, state reused | 54 µs | 32 µs | 1.7× |
| blink-small, fresh decision, 512-byte state | 4.29 ms | 824 µs | 5.2× |
| blink-small, state reused, 512-byte state | 314 µs | 135 µs | 2.3× |
What it costs, all measured:
- Allocation. Blink's own code still references no allocator. Accelerate allocates a buffer inside every large matrix product, 16 times per blink-tiny decision. No product size is both fast and allocation-free: the sizes that avoid it are the ones that do not use the matrix unit.
- Memory. The model keeps a dense fp32 copy of the projection matrices (352 KiB for blink-tiny), next to the mapped int8 weights. The per-session arena grows from 260 KiB to 335 KiB, because the matrix unit needs groups of 64 rows instead of 4. Peak RSS for one decision goes from 2.5 MiB to 7.0 MiB, mostly the framework itself.
- Bit-identity. Probabilities agree with the default build to fp32 rounding: on the 4,000 test rows of the synthetic corpus, no argmax changed and the largest difference was 1.5e-6. A cached state is still reused exactly. A batch of questions is no longer bit-identical to the same questions scored one at a time; it agrees to within 1e-5.
So the default build stays the one for embedding, real-time paths and anything that must not allocate. The Accelerate build is for macOS services where throughput matters more. The C, wasm and Python parity suites pass on both.
WebAssembly
The three demos below run in the browser from GitHub Pages, with nothing installed: BlinkPilot, Blink plays Snake and Blink plays Doom.
The same five C sources build to a 66 KB wasm32-wasip1 reactor with the
scalar kernel. Its only imports are seven WASI calls, which
wasm/blink.mjs stubs. None of them touches a file system. The
module runs unchanged in browsers and in Node.
brew install lld wasi-libc wasi-runtimes   # macOS; any clang + wasm-ld + wasi-libc works
make wasm                                  # build/wasm/blink.wasm
make test-wasm                             # against the native build
make test-wasm checks the wasm build against the native one on the three
synthesised fixtures. Probabilities agree to 5e-7 (the CLI prints six
decimals), and reusing an encoded state is bit-identical.
Test: Blink plays Snake
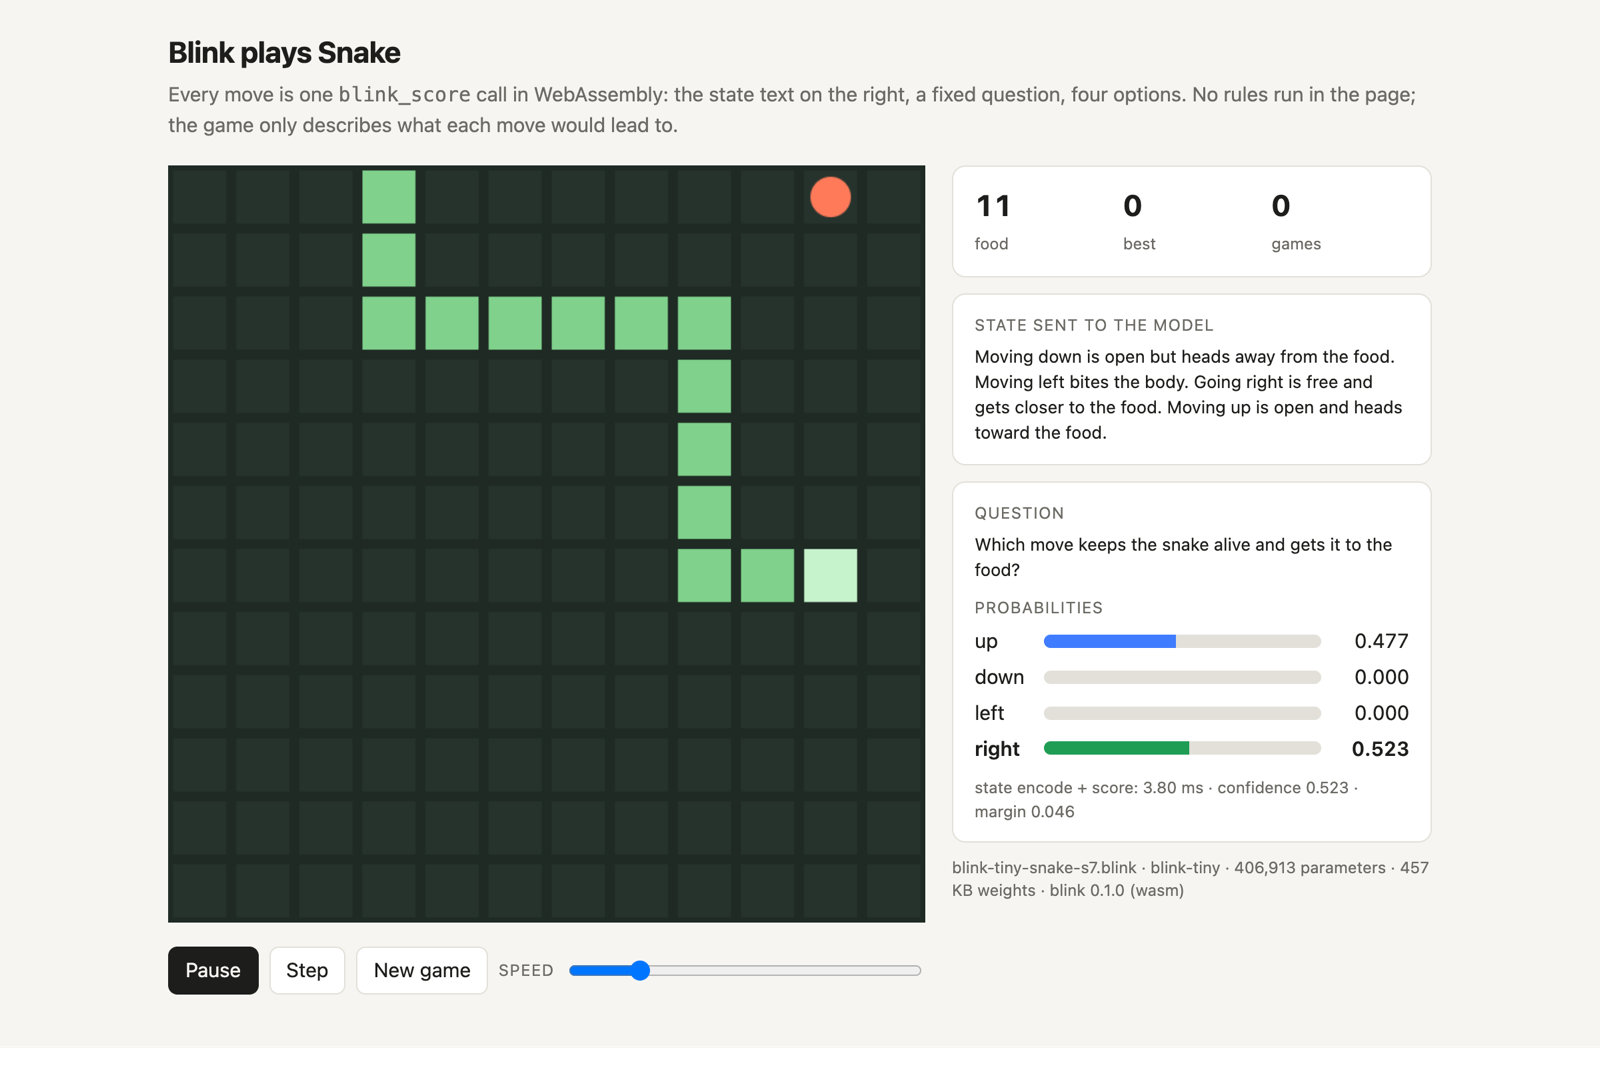
examples/snake/ trains a blink-tiny on Snake and plays it
through the wasm runtime. Each turn, the game describes in shuffled order what
each of the four moves would lead to ("Going left bites the body.", "Moving up
is open and heads toward the food."). The model scores up/down/left/right
against that text. The menu is encoded once per game. The model is not given
the board: it has to find the sentence about each option and rank the outcomes.
node examples/snake/make_data.mjs data/snake           # 150 games, 47,600 rows
PYTHONPATH=python .venv/bin/python -m blink_train.train data/snake/train.jsonl \
    --validation data/snake/validation.jsonl --preset tiny --epochs 8 \
    --output artifacts/blink-tiny-snake-s7.blink
node examples/snake/play.mjs artifacts/blink-tiny-snake-s7.blink --games 100
python3 -m http.server 8000   # then open http://localhost:8000/examples/snake/
Live at sqliteai.github.io/blink/examples/snake/.
Results from 100 seeded games on 12×12, with the same seeds for every policy. The run used one MPS seed, so it is not bit-reproducible:
| policy | mean food | median | picks an optimal move |
|---|---|---|---|
| blink-tiny (wasm) | 41.6 | 43 | 99.96% |
| oracle that labelled the data | 42.5 | 43 | 100% |
| random among non-lethal moves | 2.1 | 2 | 56.2% |
| random | 0.0 | 0 | 37.0% |
Row-level results on the held-out test games (eval/evaluate.py):
- top-1 is 0.789 against a ceiling of 0.782. When two moves tie, the label is drawn at random between them, so no model can do better than the ceiling.
- ECE is 0.003.
- The shuffled-state control scores 0.258, against a majority baseline of 0.258: the decision comes from the state.
- The shuffled-question control changes nothing, as expected, because the question never varies.
This is a test of the runtime and the training pipeline, not a claim about
reasoning over boards. The flood fill and the distance to the food are computed
by the game. What the model learns is to read and rank them. In wasm a move
costs about 0.85 ms: 0.61 ms for blink_state_set and 0.24 ms for blink_score,
on the scalar kernel.
Test: Blink plays Doom
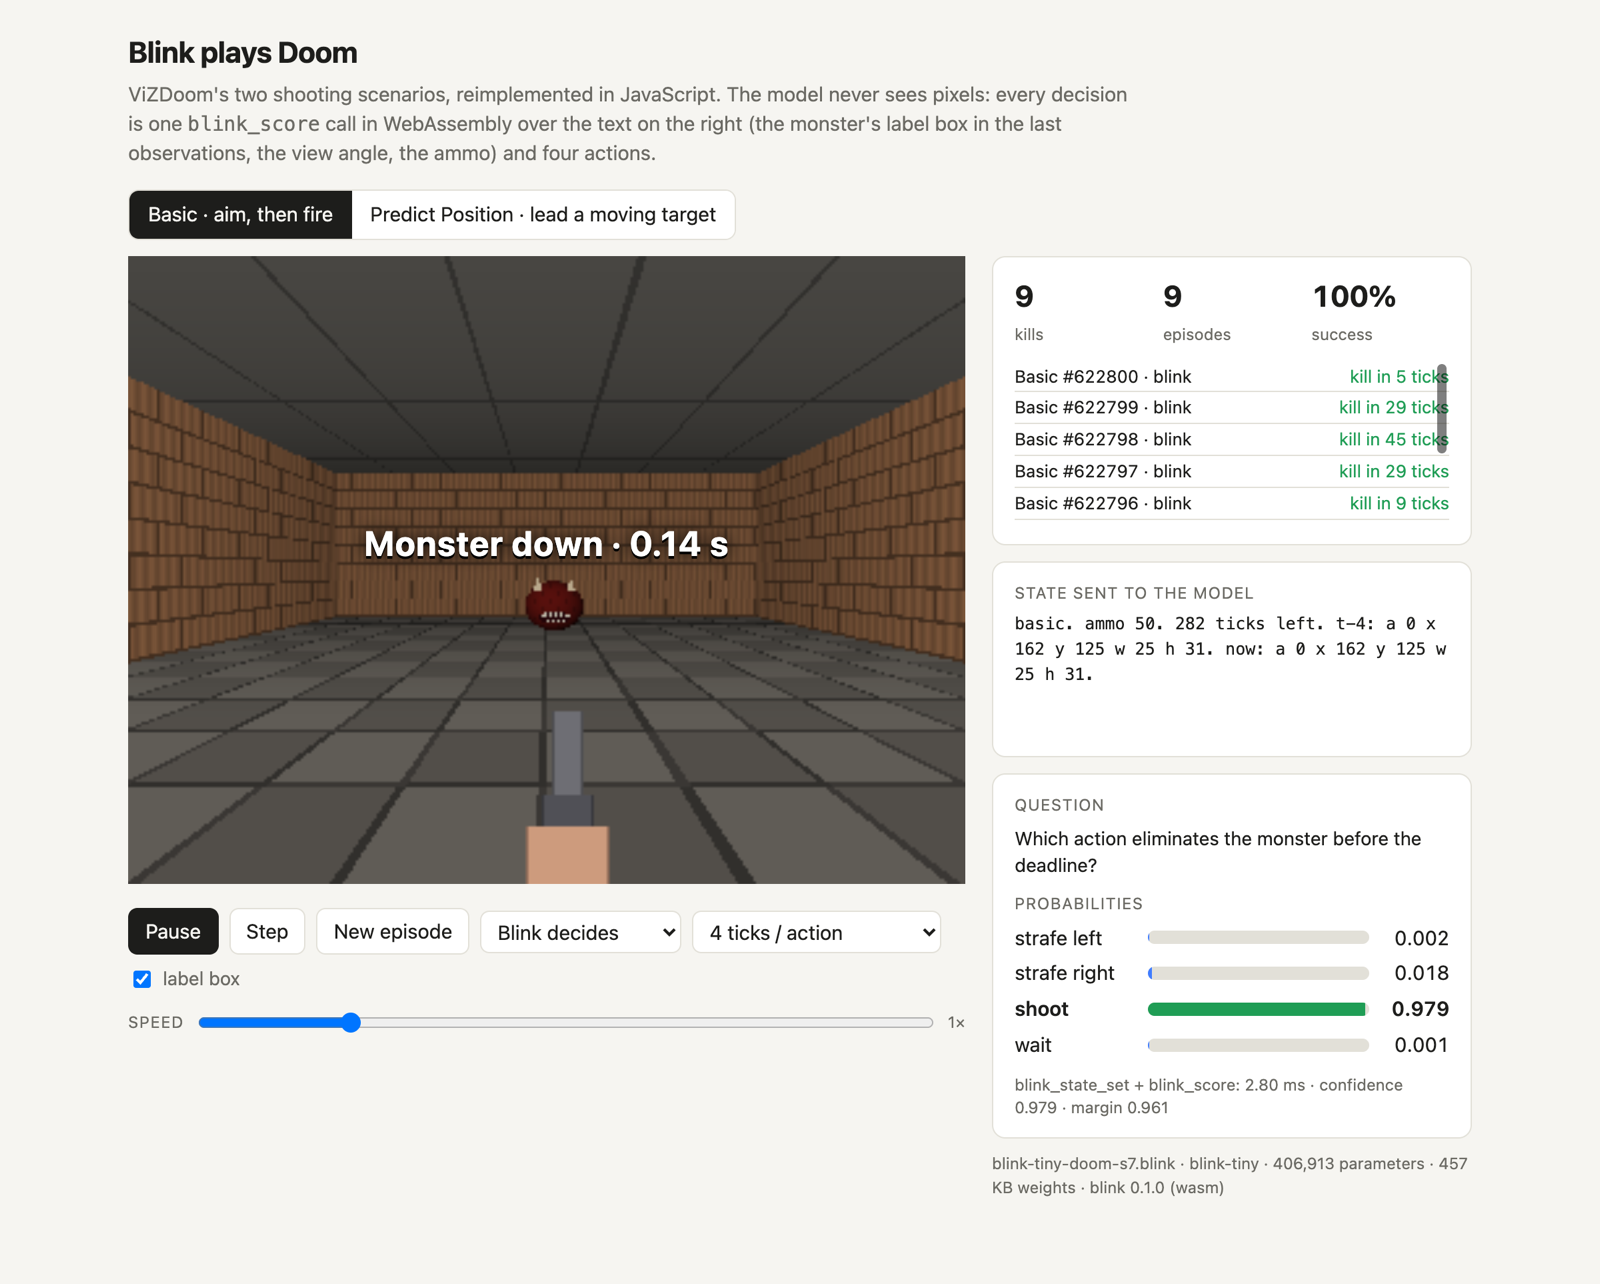
examples/doom/ runs a ViZDoom test with the whole game in JavaScript and Blink in WebAssembly. It covers two scenarios. In Basic you strafe until the monster is centred, then fire. In Predict Position you turn and lead a moving monster with a single rocket. There are four actions (left, right, shoot, wait), each held for 4 Doom ticks, with 75 decisions per episode. The model never sees pixels. It reads the monster's label box from the last four observations, the view angle and the ammo:
predict position. ammo 1. 268 ticks left. t-12: a 7 x 56 y 123 w 16 h 20.
t-8: a 18 x 89 y 122 w 15 h 18. t-4: a 32 x 126 y 122 w 13 h 16. now: a 46 x 163 y 122 w 12 h 16.
ViZDoom is a native engine, and these scenarios need ZDoom features (ACS
scripts, the label buffer), so they cannot run in a browser. doom.mjs
reimplements them with every constant measured on ViZDoom 1.3.1:
- strafe physics fitted exactly: v ← 0.90625·v + 0.75 per tick;
- turn rate: 1.758°/tick for 6 ticks, then 3.516°/tick;
- pistol: fires 4 ticks after the press, refires every 14 ticks, hits within the monster's 31-unit radius;
- rocket: leaves 8 ticks after the press and flies 20 units/tick;
- the projection onto the 320×240 screen;
- the monster's movement, a direction-transition matrix estimated from 400 real episodes.
It is a faithful model of the rules, not a bit-exact port. render.mjs draws
it with a raycaster and procedural sprites, with no WAD and no Doom art.
The teacher that labels the data works differently in each scenario:
- Basic: it uses only what is on screen.
- Predict Position: it reads the monster's world position, which Blink never sees, and solves for the rocket intercept.
node examples/doom/make_data.mjs data/doom            # 7,256 episodes, 75,752 rows, 0.2 s
PYTHONPATH=python .venv/bin/python -m blink_train.train data/doom/train.jsonl \
    --validation data/doom/validation.jsonl --preset tiny --epochs 10 \
    --output artifacts/blink-tiny-doom-s7.blink
node examples/doom/play.mjs artifacts/blink-tiny-doom-s7.blink
python3 -m http.server 8000   # then open http://localhost:8000/examples/doom/
Live at sqliteai.github.io/blink/examples/doom/.
Successes on held-out seeds: 128 test and 128 OOD episodes per scenario, with
OOD holding each action for 8 ticks. blink e=0.1 picks a random action 10%
of the time instead of the argmax (seed 17). The run used one MPS seed. Jev's
published numbers come from real ViZDoom, so they are context, not a
head-to-head:
| case | blink-tiny | blink e=0.1 | teacher | random | Jev |
|---|---|---|---|---|---|
| Basic, test | 128/128 | 128/128 | 128/128 | 69/128 | 56/128 |
| Basic, OOD | 124/128 | 126/128 | 120/128 | 64/128 | 59/128 |
| Predict Position, test | 39/128 | 44/128 | 68/128 | 6/128 | 11/128 |
| Predict Position, OOD | 17/128 | 11/128 | 64/128 | 6/128 | 8/128 |
On real ViZDoom the same teacher scores 81/128 on Predict Position test instead of 68, so the simulated monster is somewhat harder to lead than the real one.
Row-level results on the held-out rows (eval/evaluate.py, 1,191 rows):
- top-1 is 0.834: 0.994 on Basic and 0.730 on Predict Position;
- ECE is 0.031;
- the shuffled-state control scores 0.268, against a majority baseline of 0.286.
In wasm a decision costs about 0.81 ms: 0.59 ms for blink_state_set and 0.23
ms for blink_score. The weights are 457 KB.
Test: Blink drives (BlinkPilot)
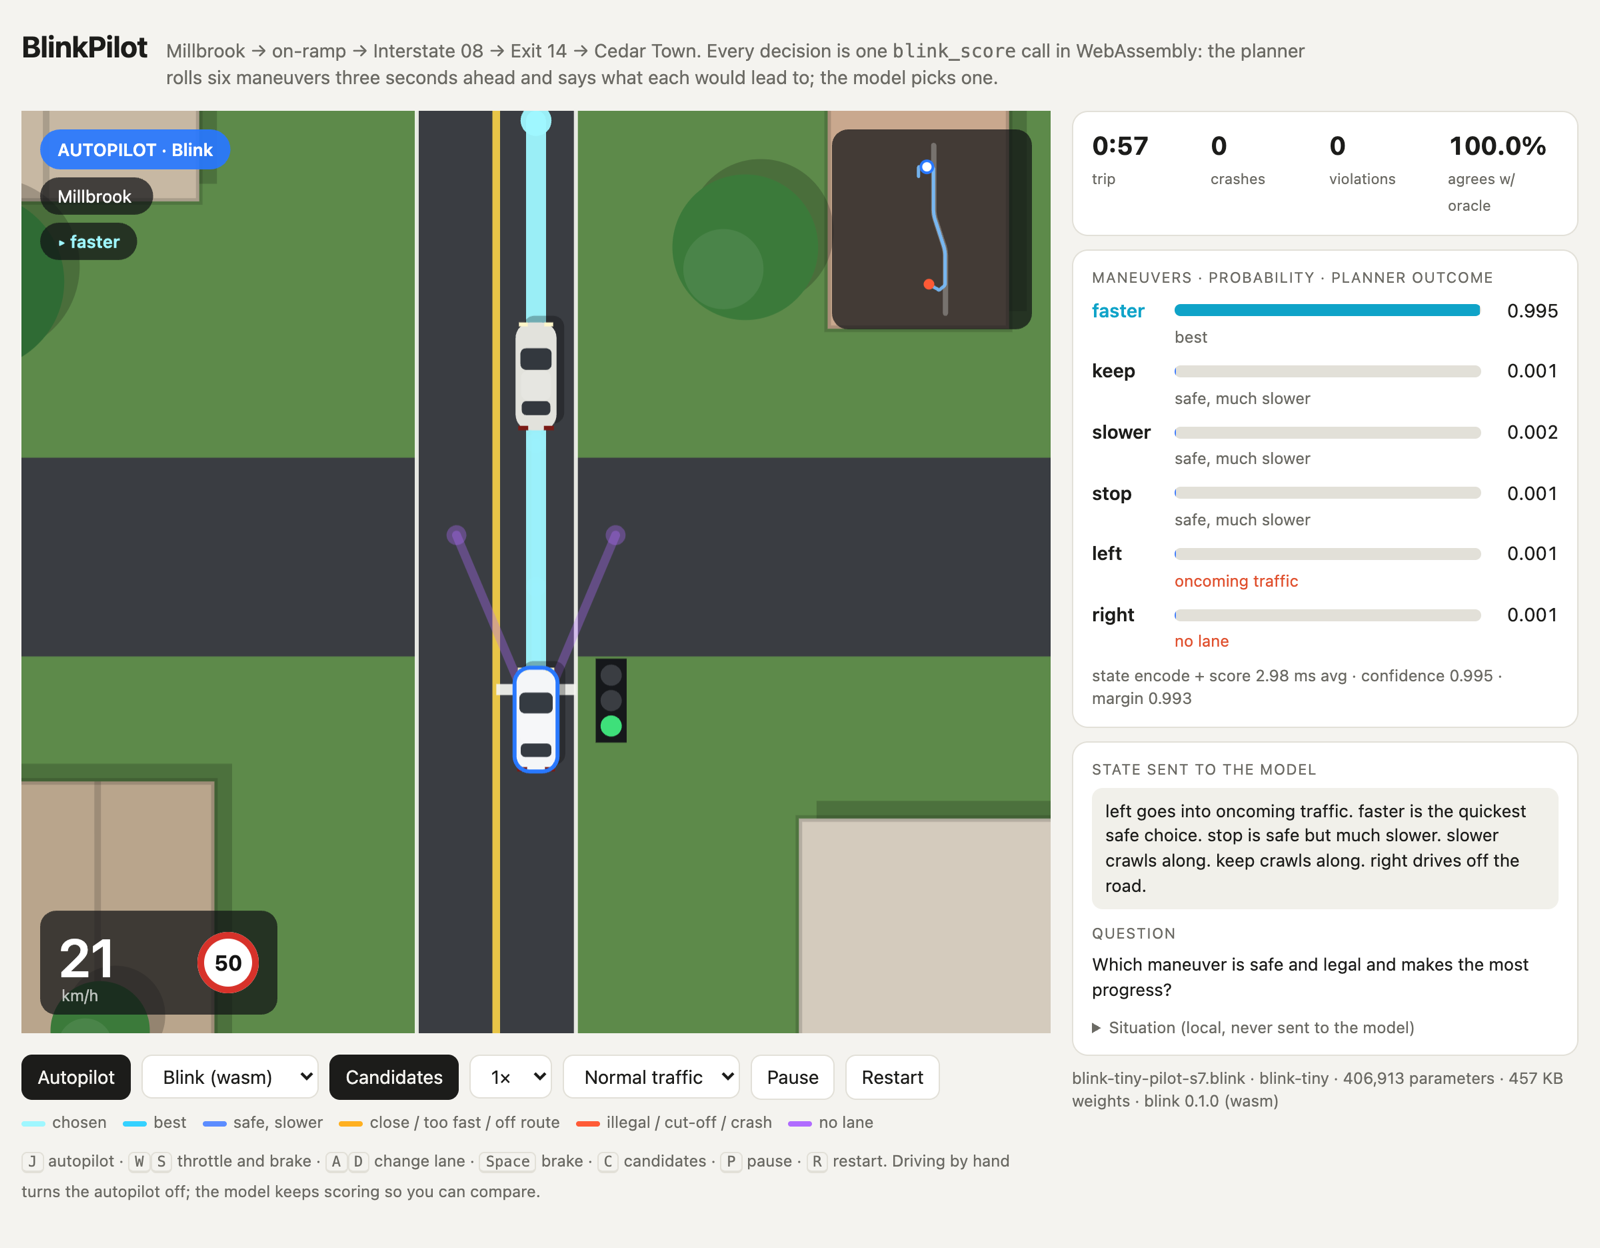
examples/pilot/ is a top-down driving demo on the wasm runtime. The trip: start in Millbrook, stop at a sign and a light, take the on-ramp, merge onto Interstate 08, move over for Exit 14 and park in Cedar Town.
Geometry, traffic prediction and control stay local. Every 0.25 s the planner rolls six maneuvers
(faster keep slower stop left right) three seconds ahead against predicted
traffic, signals and lane geometry, and writes one sentence per maneuver in
shuffled order ("left cuts off a car.", "keep runs the red light.",
"stop stops at the line."). The model scores the six maneuvers against that
text. The menu is encoded once per trip.
node examples/pilot/make_data.mjs data/pilot           # 80 trips, 63,479 rows
PYTHONPATH=python .venv/bin/python -m blink_train.train data/pilot/train.jsonl \
    --validation data/pilot/validation.jsonl --preset tiny --epochs 8 --seed 7 \
    --output artifacts/blink-tiny-pilot-s7.blink
node examples/pilot/drive.mjs artifacts/blink-tiny-pilot-s7.blink --trips 20
python3 -m http.server 8000   # then open http://localhost:8000/examples/pilot/
Live at sqliteai.github.io/blink.
make pilot packs the page, blink.wasm and the model into one 770 KB
build/blinkpilot.html that opens straight from disk, with no server.
.github/workflows/pages.yml publishes it to
GitHub Pages on every push to main, as the site's front page, with the Snake
and Doom demos under /examples/snake/ and /examples/doom/ and the unbundled
BlinkPilot under /examples/pilot/. bash scripts/build_site.sh assembles
the same site locally and checks that every file the pages load is in it.
Results from 20 seeded trips at normal traffic, with the same seeds for every policy. A trip that has not arrived after 600 s counts as not arrived. The run used one MPS seed, so it is not bit-reproducible:
| policy | arrived | median trip | crashes | violations | picks a best maneuver |
|---|---|---|---|---|---|
| blink-tiny (wasm) | 20/20 | 217.4 s | 0 | 0 | 100.00% |
| oracle that labelled the data | 20/20 | 217.1 s | 0 | 0 | 100% |
| random among safe, legal maneuvers | 0/20 | - | 0 | 0 | 26.3% |
| random | 0/20 | - | 6 | 3,346 | 20.1% |
At heavy traffic (--density 1.4) blink-tiny also arrives 20/20 with no
crash or violation.
Row-level results on the held-out test trips (eval/evaluate.py):
- top-1 is 0.820 against a ceiling of 0.823. When several maneuvers tie for best, the label is drawn at random between them.
- ECE is 0.029.
- The shuffled-state control scores 0.309, against a majority baseline of
0.175. The gap is the prior over maneuvers (
fasterandkeepare best most of the time), not information from the state.
As with Snake, this tests the runtime and the training pipeline, not driving.
The rollouts, the collision prediction and the traffic rules are computed by
the planner; the model reads and ranks their outcomes. In wasm a decision costs
about 0.88 ms: 0.62 ms for blink_state_set and 0.26 ms for blink_score.
Documentation
| docs/ARCHITECTURE.md | what Jev is, where Blink sits, and every design decision with its reason |
| docs/METHOD.md | metrics, controls, perturbations, and the boundaries of every claim |
| docs/RESULTS.md | accuracy, calibration, latency, memory, and what fails |
| docs/REPRODUCE.md | how to rerun each piece, and what is and is not bit-reproducible |
| include/blink.h | the public API, documented inline |
| docs/CLI.md | the blink command: options, output, exit codes (also man blink) |
| CHANGELOG.md | what each release contains |
Testing
| suite | what it covers |
|---|---|
tests/c/test_kernels.c |
every numeric kernel against hand-computed values, plus published CRC-32 vectors |
tests/c/test_container.c |
20 corrupted header fields and every truncation point must be rejected with a specific error |
tests/c/test_session.c |
arena sizing, placement, error paths, determinism, and bit-identical state reuse |
tests/c/test_inputs.c |
all 256 byte values, embedded NULs, invalid UTF-8, boundary lengths, 2-16 options, order equivariance |
tests/c/check_no_malloc.sh |
the scoring path references no allocator symbol |
tests/wasm/test_wasm.mjs |
the WebAssembly build against the native one: same argmax, probabilities within 2e-5, bit-identical state reuse, checksum refusal (make test-wasm) |
tests/python/test_parity.py |
C against a float64 reference; PyTorch against the same reference; the bigram hash across all 65,536 byte pairs; a C-written container read back in Python |
tests/python/test_harness.py |
the evaluation metrics against cases whose answers are known by hand, and that the corpus builder leaks nothing across a split |
eval/evaluate.py |
accuracy, calibration, shuffled controls, untrained control, perturbations, per-family strata |
CI additionally builds at -O0, under AddressSanitizer and
UndefinedBehaviorSanitizer, with gcc and clang, and with the SIMD kernel
compiled out - the scalar loop is the normative definition and must not stop
working because a faster path exists.
The SIMD paths are NEON on Arm and, on x86-64, SSE2 or AVX2 + FMA, chosen at
run time (BLINK_X86_SIMD=scalar|sse2|avx2 forces one; blink_backend()
reports it). The x86 paths are verified under emulation: every level passes
the C suite, sanitizers included, and agrees with the float64 reference to
6e-7 on a trained model. On a GitHub x86 runner AVX2 is 2.7× and SSE2 2.1×
the scalar loop (details). bash scripts/x86-docker-test.sh runs
all of that in a linux/amd64 container from any machine with Docker.
scripts/make_data.py
#!/usr/bin/env python3
"""Build the deterministic synthetic corpus.

Splits are made on scenario groups, never on rows: several questions can share
one state, and letting them straddle a split would leak the state into the test
set.
"""
from __future__ import annotations

import argparse
import hashlib
import json
import sys
from pathlib import Path

sys.path.insert(0, str(Path(__file__).resolve().parents[1] / "python"))

from blink_train.data import write_synthetic  # noqa: E402


def main() -> None:
    parser = argparse.ArgumentParser()
    parser.add_argument("--output", type=Path, default=Path("data/synthetic"))
    parser.add_argument("--train-groups", type=int, default=20000)
    parser.add_argument("--validation-groups", type=int, default=2000)
    parser.add_argument("--test-groups", type=int, default=2000)
    parser.add_argument("--seed", type=int, default=20260920)
    args = parser.parse_args()

    counts = write_synthetic(args.output, {
        "train": args.train_groups,
        "validation": args.validation_groups,
        "test": args.test_groups,
    }, args.seed)

    digests = {
        path.name: hashlib.sha256(path.read_bytes()).hexdigest()
        for path in sorted(args.output.glob("*.jsonl"))
    }
    manifest = {
        "generator": "blink_train.data.write_synthetic",
        "seed": args.seed,
        "groups": {"train": args.train_groups,
                   "validation": args.validation_groups,
                   "test": args.test_groups},
        "rows": counts,
        "sha256": digests,
    }
    (args.output / "manifest.json").write_text(json.dumps(manifest, indent=2) + "\n")
    print(json.dumps(manifest, indent=2))


if __name__ == "__main__":
    main()
scripts/run_all.sh
#!/usr/bin/env bash
# Reproduce everything docs/RESULTS.md reports, from a clean checkout.
#
#   bash scripts/run_all.sh                   the published protocol (~2 h, MPS)
#   bash scripts/run_all.sh --small           also blink-small (~5 h more)
#   bash scripts/run_all.sh --smoke           every stage on a tiny corpus, minutes
#   bash scripts/run_all.sh --skip-download   no network: no WANLI
#
#   BLINK_DEVICE=cpu   training device (default auto: MPS, then CUDA, then CPU)
#   BLINK_SEEDS="7"    fewer runs (default "7 17 27")
#   BLINK_PYTHON=...   interpreter (default .venv/bin/python)
#
# The published protocol is three independent runs of each model -- on MPS a
# seed does not pin a run, see docs/REPRODUCE.md -- named <preset>-<corpus>-s<seed>:
#
#   blink-tiny   synthetic  60 epochs, lr 3e-3
#   blink-tiny   WANLI      25 epochs, lr 3e-3, byte limits from the corpus
#   blink-small  synthetic 100 epochs, lr 2e-3          (--small)
#   blink-small  WANLI      60 epochs, lr 2e-3, limits from the corpus (--small)
#
# Each stage writes machine-readable output under results/, the measured
# sections of docs/RESULTS.md are regenerated from it, and results/MANIFEST.json
# records the checksum of every artefact, so a later run can be compared with a
# published one line by line.
#
# --smoke writes only under data/smoke, artifacts/smoke and results/smoke, and
# touches neither the published results nor the documents. It checks that the
# pipeline runs end to end, not that it reaches any accuracy.
#
# The comparisons against jevlike and on Wikispeedia need a jevlike checkout and
# are not part of this script; scripts/experiments/README.md lists them.

set -euo pipefail

cd "$(dirname "$0")/.."
ROOT="$PWD"

SMOKE=0 SMALL=0 SKIP_DOWNLOAD=0
for arg in "$@"; do
  case "$arg" in
    --smoke) SMOKE=1 ;;
    --small) SMALL=1 ;;
    --skip-download) SKIP_DOWNLOAD=1 ;;
    -h|--help) sed -n '2,31p' "$0"; exit 0 ;;
    *) echo "unknown argument: $arg" >&2; exit 2 ;;
  esac
done

PYTHON="${BLINK_PYTHON:-$ROOT/.venv/bin/python}"
DEVICE="${BLINK_DEVICE:-auto}"
SEEDS="${BLINK_SEEDS:-7 17 27}"
export PYTHONPATH="$ROOT/python${PYTHONPATH:+:$PYTHONPATH}"

if [ "$SMOKE" = 1 ]; then
  DATA=data/smoke ARTIFACTS=artifacts/smoke RESULTS=results/smoke
  SEEDS="${BLINK_SEEDS:-7}"
else
  DATA=data ARTIFACTS=artifacts RESULTS=results
fi
mkdir -p "$DATA" "$ARTIFACTS" "$RESULTS/predictions"

step() { printf '\n\033[1m== %s\033[0m\n' "$*"; }

if [ ! -x "$PYTHON" ]; then
  echo "No interpreter at $PYTHON." >&2
  echo "Create one with:  uv venv --python 3.12 .venv && uv pip install --python .venv/bin/python torch numpy pytest" >&2
  exit 1
fi

# epochs for one training job; --smoke shrinks every one of them to one or two
epochs() { if [ "$SMOKE" = 1 ]; then echo 2; else echo "$1"; fi; }

train() {  # label corpus preset epochs learning-rate [extra...]
  local label="$1" corpus="$2" preset="$3" n="$4" lr="$5"; shift 5
  step "train blink-$label"
  "$PYTHON" -m blink_train.train "$DATA/$corpus/train.jsonl" \
    --validation "$DATA/$corpus/validation.jsonl" \
    --preset "$preset" --epochs "$(epochs "$n")" --learning-rate "$lr" \
    --device "$DEVICE" --seed "${label##*-s}" \
    --output "$ARTIFACTS/blink-$label.blink" \
    --checkpoint "$ARTIFACTS/blink-$label.pt" \
    "$@" >"$RESULTS/train-$label.jsonl" 2>&1
  if grep -q temperature_pinned "$RESULTS/train-$label.jsonl"; then
    echo "  warning: the temperature fit hit its bound; read $RESULTS/train-$label.jsonl" >&2
    if [ "$SMOKE" = 1 ]; then
      echo "  (expected after two epochs on a small corpus)" >&2
    fi
  fi
  return 0
}

evaluate() {  # label model data [extra...]
  local label="$1" model="$2" data="$3"; shift 3
  [ -f "$model" ] && [ -f "$data" ] || { echo "-- skip $label"; return 0; }
  step "evaluate $label"
  "$PYTHON" eval/evaluate.py "$model" "$data" --quiet \
    --json "$RESULTS/eval-$label.json" \
    --predictions "$RESULTS/predictions/$label.jsonl" "$@"
}

# --------------------------------------------------------------- 1. build
step "build the C runtime and its tests"
make clean >/dev/null
make
make fixtures
make test

# ---------------------------------------------------------------- 2. data
step "synthetic corpus"
if [ "$SMOKE" = 1 ]; then
  "$PYTHON" scripts/make_data.py --output "$DATA/synthetic" \
    --train-groups 400 --validation-groups 100 --test-groups 100 \
    >"$RESULTS/data-synthetic.json"
else
  "$PYTHON" scripts/make_data.py --output "$DATA/synthetic" >"$RESULTS/data-synthetic.json"
fi

if [ -d ../SemIf ]; then
  step "external fixtures"
  "$PYTHON" eval/import_fixtures.py --source ../SemIf --output "$DATA/fixtures" \
    >"$RESULTS/data-fixtures.json" || echo "  (skipped)"
fi

WANLI=0
if [ "$SMOKE" = 0 ] && [ "$SKIP_DOWNLOAD" = 0 ]; then
  step "WANLI"
  if "$PYTHON" eval/build_wanli.py --output "$DATA/wanli" >"$RESULTS/data-wanli.json"; then
    WANLI=1
    if [ -d ../SemIf ]; then
      step "SemIf's 256 WANLI rows"
      "$PYTHON" eval/build_wanli256.py --source ../SemIf --output "$DATA/wanli256" \
        >"$RESULTS/data-wanli256.json" || echo "  (skipped)"
    fi
  else
    echo "  (skipped: no network?)"
  fi
fi

# ------------------------------------------------------- 3. train and export
for seed in $SEEDS; do
  train "tiny-synthetic-s$seed" synthetic tiny 60 3e-3
  if [ "$WANLI" = 1 ]; then
    train "tiny-wanli-s$seed" wanli tiny 25 3e-3 --limits-from-data
  fi
  if [ "$SMALL" = 1 ]; then
    train "small-synthetic-s$seed" synthetic small 100 2e-3
    if [ "$WANLI" = 1 ]; then
      train "small-wanli-s$seed" wanli small 60 2e-3 --limits-from-data
    fi
  fi
done

# ------------------------------------------------------------- 4. parity
step "Python tests: C against the float64 reference"
"$PYTHON" -m pytest tests/python -q

# ------------------------------------------------------------ 5. accuracy
presets=tiny
if [ "$SMALL" = 1 ]; then presets="tiny small"; fi
for seed in $SEEDS; do
  for preset in $presets; do
    evaluate "$preset-synthetic-s$seed" "$ARTIFACTS/blink-$preset-synthetic-s$seed.blink" \
      "$DATA/synthetic/test.jsonl"
    evaluate "$preset-wanli-s$seed" "$ARTIFACTS/blink-$preset-wanli-s$seed.blink" \
      "$DATA/wanli/test.jsonl"
    evaluate "$preset-wanli256-s$seed" "$ARTIFACTS/blink-$preset-wanli-s$seed.blink" \
      "$DATA/wanli256/test.jsonl" --bootstrap 2000
  done
  # Transfer: a model trained on the synthetic corpus, asked for something else.
  for fixture in authored144 perturbations108; do
    evaluate "tiny-synthetic-s$seed-$fixture" "$ARTIFACTS/blink-tiny-synthetic-s$seed.blink" \
      "$DATA/fixtures/$fixture.jsonl" --bootstrap 500
  done
done
# Untrained weights must land on chance; if they do not, the harness is
# measuring itself.
for preset in tiny small; do
  evaluate "$preset-untrained" "build/synth-$preset.blink" "$DATA/synthetic/test.jsonl" \
    --skip-controls --bootstrap 0
done

if [ "$SMOKE" = 1 ]; then
  step "benchmarks (not saved)"
  make bench >"$RESULTS/bench.jsonl"
  head -3 "$RESULTS/bench.jsonl"
  printf '\n\033[1msmoke run complete.\033[0m Everything it wrote is under %s, %s and %s.\n' \
    "$DATA" "$ARTIFACTS" "$RESULTS"
  exit 0
fi

# ----------------------------------------------------------- 6. benchmarks
# Latency, memory and the scalar build for the SIMD comparison. Run it on an
# idle machine: every other process shows up in the percentiles.
step "benchmarks"
make bench-save

# ------------------------------------------------------------ 7. document
step "regenerate the measured sections of docs/RESULTS.md"
"$PYTHON" scripts/report_results.py --write

step "manifest and summary"
"$PYTHON" scripts/manifest.py >results/MANIFEST.json
"$PYTHON" scripts/summarise.py >results/SUMMARY.md

printf '\n\033[1mdone.\033[0m results/ holds every report; results/MANIFEST.json holds every checksum.\n'
examples/snake/make_data.mjs
/* make_data.mjs -- write a Snake decision corpus in the Blink JSONL format.
 *
 *   node examples/snake/make_data.mjs data/snake
 *
 * Games are played by the oracle with a share of random non-lethal moves, so
 * the corpus also covers the states a weaker player reaches. Every turn is one
 * row. Splits are by game (`group`), never by row, and use disjoint seeds.
 *
 * Deterministic: the same command writes the same bytes.
 *
 * SPDX-License-Identifier: Apache-2.0 */

import { mkdirSync, writeFileSync } from "node:fs";
import { join } from "node:path";

import { MOVES, QUESTION, Snake, rng } from "./snake.mjs";

const EPSILON = 0.2;         /* share of random non-lethal moves */
const MAX_STEPS = 600;
const MAX_HUNGRY = 150;      /* end a game that circles without eating */

function playGames(games, seed, split) {
  const rows = [];
  const random = rng(seed);
  for (let g = 0; g < games; ++g) {
    const size = 8 + Math.floor(random() * 7);       /* 8x8 .. 14x14 */
    const game = new Snake({ width: size, height: size, seed: seed * 7919 + g });
    while (game.alive && game.steps < MAX_STEPS && game.sinceFood < MAX_HUNGRY) {
      const outcomes = game.outcomes();
      const best = game.best(outcomes);
      const options = [...MOVES];
      for (let i = options.length - 1; i > 0; --i) {
        const j = Math.floor(random() * (i + 1));
        [options[i], options[j]] = [options[j], options[i]];
      }
      const label = best[Math.floor(random() * best.length)];
      rows.push({
        state: game.describe(outcomes, random),
        question: QUESTION,
        options,
        label: options.indexOf(label),
        group: `snake-${split}-${g}`,
        family: "snake",
      });

      let move = label;
      if (random() < EPSILON) {
        const safe = MOVES.filter((m) => !["wall", "body"].includes(outcomes[m].kind));
        if (safe.length) move = safe[Math.floor(random() * safe.length)];
      }
      game.step(move);
    }
  }
  return rows;
}

const out = process.argv[2] ?? "data/snake";
mkdirSync(out, { recursive: true });
const splits = { train: [150, 11], validation: [20, 23], test: [20, 37] };
const manifest = { generator: "examples/snake/make_data.mjs", epsilon: EPSILON, splits: {} };
for (const [name, [games, seed]] of Object.entries(splits)) {
  const rows = playGames(games, seed, name);
  writeFileSync(join(out, `${name}.jsonl`), rows.map((r) => JSON.stringify(r)).join("\n") + "\n");
  manifest.splits[name] = { games, seed, rows: rows.length };
  console.log(`${name}: ${games} games, ${rows.length} rows`);
}
writeFileSync(join(out, "manifest.json"), JSON.stringify(manifest, null, 2) + "\n");
examples/snake/play.mjs
/* play.mjs -- Blink plays Snake through the WebAssembly runtime, headless.
 *
 *   node examples/snake/play.mjs MODEL.blink [--games 100] [--size 12] [--show]
 *
 * Plays the same seeded games with four policies and prints one table:
 *
 *   blink        argmax of blink_score over the four moves
 *   oracle       the rule that labelled the training data (upper bound)
 *   random-safe  uniform over moves that do not die immediately
 *   random       uniform over all four moves
 *
 * The menu is encoded once per game; each turn encodes a new state and scores
 * the fixed question against it.
 *
 * SPDX-License-Identifier: Apache-2.0 */

import { readFileSync } from "node:fs";
import { dirname, join } from "node:path";
import { fileURLToPath } from "node:url";

import { loadBlink } from "../../wasm/blink.mjs";
import { MOVES, QUESTION, Snake, rng } from "./snake.mjs";

const here = dirname(fileURLToPath(import.meta.url));
const args = process.argv.slice(2);
const flag = (name, fallback) => {
  const i = args.indexOf(name);
  return i >= 0 ? Number(args[i + 1]) : fallback;
};
const modelPath = args.find((a) => a.endsWith(".blink"));
if (!modelPath) {
  console.error("usage: play.mjs MODEL.blink [--games N] [--size N] [--show]");
  process.exit(2);
}
const GAMES = flag("--games", 100);
const SIZE = flag("--size", 12);
const SHOW = args.includes("--show");
const MAX_STEPS = 2000;
const MAX_HUNGRY = SIZE * SIZE * 2;

const blink = await loadBlink(readFileSync(join(here, "..", "..", "build", "wasm", "blink.wasm")));
const model = blink.openModel(readFileSync(modelPath));
const session = model.createSession({ maxOptions: 4 });
session.setMenu(MOVES);

let stateSeconds = 0, scoreSeconds = 0, decisions = 0;

const POLICIES = {
  blink(game, outcomes, random) {
    const text = game.describe(outcomes, random);
    const t0 = performance.now();
    session.setState(text);
    const t1 = performance.now();
    const r = session.score(QUESTION);
    stateSeconds += (t1 - t0) / 1e3;
    scoreSeconds += (performance.now() - t1) / 1e3;
    ++decisions;
    return MOVES[r.argmax];
  },
  oracle(game, outcomes, random) {
    const best = game.best(outcomes);
    return best[Math.floor(random() * best.length)];
  },
  "random-safe"(game, outcomes, random) {
    const safe = MOVES.filter((m) => !["wall", "body"].includes(outcomes[m].kind));
    const pool = safe.length ? safe : MOVES;
    return pool[Math.floor(random() * pool.length)];
  },
  random(game, outcomes, random) {
    return MOVES[Math.floor(random() * 4)];
  },
};

function draw(game) {
  const grid = Array.from({ length: game.height }, () => Array(game.width).fill("·"));
  if (game.food) grid[game.food[1]][game.food[0]] = "●";
  game.body.forEach(([x, y], i) => { grid[y][x] = i ? "▪" : "■"; });
  return grid.map((row) => row.join(" ")).join("\n");
}

const table = [];
for (const [name, policy] of Object.entries(POLICIES)) {
  const scores = [];
  const ends = {};
  let agree = 0, turns = 0;
  for (let g = 0; g < GAMES; ++g) {
    const game = new Snake({ width: SIZE, height: SIZE, seed: 100003 + g });
    const random = rng(7 + g);
    while (game.alive && game.steps < MAX_STEPS && game.sinceFood < MAX_HUNGRY) {
      const outcomes = game.outcomes();
      const move = policy(game, outcomes, random);
      agree += game.best(outcomes).includes(move) ? 1 : 0;
      ++turns;
      game.step(move);
    }
    const end = game.alive ? (game.steps >= MAX_STEPS ? "step cap" : "starved") : game.death;
    ends[end] = (ends[end] ?? 0) + 1;
    scores.push(game.score);
    if (SHOW && name === "blink" && g === 0) {
      console.log(`blink, game 0: score ${game.score}, ${game.steps} steps, ended by ${end}\n${draw(game)}\n`);
    }
  }
  scores.sort((a, b) => a - b);
  const mean = scores.reduce((s, v) => s + v, 0) / scores.length;
  table.push({
    policy: name,
    "mean food": mean.toFixed(2),
    median: scores[scores.length >> 1],
    best: scores[scores.length - 1],
    "oracle-agreement": (agree / turns).toFixed(4),
    endings: Object.entries(ends).map(([k, v]) => `${k} ${v}`).join(", "),
  });
}

const info = model.info();
console.log(`${modelPath}: ${info.name}, ${info.parameters} parameters, blink ${blink.version} (wasm)`);
console.log(`${GAMES} games on ${SIZE}x${SIZE}, same seeds for every policy\n`);
console.table(table);
const us = (s) => (s / decisions * 1e6).toFixed(1);
console.log(`\nwasm, ${decisions} decisions: blink_state_set ${us(stateSeconds)} µs, ` +
  `blink_score ${us(scoreSeconds)} µs, ${Math.round(decisions / (stateSeconds + scoreSeconds))} moves/s`);
examples/doom/make_data.mjs
/* make_data.mjs -- write a ViZDoom decision corpus in the Blink JSONL format.
 *
 *   node examples/doom/make_data.mjs data/doom
 *
 * Both scenarios go into one corpus, so one model plays both. Episodes are played by the teacher with a share of
 * random actions, so the corpus also covers states a weaker player reaches.
 * Every decision is one row; splits are by episode (`group`), never by row.
 *
 * Seeds: play.mjs evaluates on the held-out test and OOD seeds, so nothing
 * here touches them. Training seeds come from a separate range; validation
 * and test rows use the dev and calibration seed ranges.
 *
 * Predict Position has one rocket. Rows after it is fired are dropped --
 * nothing the policy does then changes the outcome -- and exploration never
 * fires at random, which would spend the episode on its first step.
 *
 * Deterministic: the same command writes the same bytes.
 *
 * SPDX-License-Identifier: Apache-2.0 */

import { mkdirSync, writeFileSync } from "node:fs";
import { join } from "node:path";

import { ACTIONS, Doom, OPTIONS, QUESTION, rng } from "./doom.mjs";

const EPSILON = 0.2;
const SPLITS = {
  train: { basic: [1_000_000, 3000], predict_position: [2_000_000, 4000] },
  validation: { basic: [9_010_000, 64], predict_position: [9_300_512, 64] },
  test: { basic: [9_020_000, 64], predict_position: [9_300_576, 64] },
};

function play(scenario, first, episodes, random) {
  const rows = [];
  let wins = 0;
  for (let seed = first; seed < first + episodes; ++seed) {
    const game = new Doom({ scenario, seed, frameSkip: 4, maxSteps: 75 });
    while (!game.done) {
      const label = game.teacher();
      if (game.ammo > 0) {
        rows.push({
          state: game.describe(),
          question: QUESTION,
          options: OPTIONS[scenario],
          label: ACTIONS.indexOf(label),
          group: `${scenario}-${seed}`,
          family: scenario,
        });
      }
      let move = label;
      if (random() < EPSILON) {
        const pool = scenario === "basic" ? ACTIONS : ["left", "right", "noop"];
        move = pool[Math.floor(random() * pool.length)];
      }
      game.step(move);
    }
    wins += game.success;
  }
  return { rows, wins };
}

const out = process.argv[2] ?? "data/doom";
mkdirSync(out, { recursive: true });
const manifest = { generator: "examples/doom/make_data.mjs", epsilon: EPSILON,
  frameSkip: 4, maxSteps: 75, splits: {} };
for (const [split, scenarios] of Object.entries(SPLITS)) {
  const random = rng(split.length * 7919);
  let rows = [];
  for (const [scenario, [first, episodes]] of Object.entries(scenarios)) {
    const played = play(scenario, first, episodes, random);
    rows = rows.concat(played.rows);
    manifest.splits[`${split}/${scenario}`] = { firstSeed: first, episodes,
      rows: played.rows.length, teacherWinsWithExploration: played.wins };
    console.log(`${split}/${scenario}: ${episodes} episodes, ${played.rows.length} rows, ` +
      `${played.wins} wins with exploration`);
  }
  /* Interleave the scenarios so a batch is never all one of them. */
  for (let i = rows.length - 1; i > 0; --i) {
    const j = Math.floor(random() * (i + 1));
    [rows[i], rows[j]] = [rows[j], rows[i]];
  }
  writeFileSync(join(out, `${split}.jsonl`), rows.map((r) => JSON.stringify(r)).join("\n") + "\n");
}
writeFileSync(join(out, "manifest.json"), JSON.stringify(manifest, null, 2) + "\n");
[Content truncated due to size limits]
Discussion
Questions & comments · 0
Sign In Sign in to leave a comment.