
PSSA: a plastic state-space architecture
PSSA is a Rust research language model combining recurrent state, episodic memory, and plastic weight updates.
0.5.4Add to Favorites
Source
Get it from source
Spark does not host a copy of it.
Open sourceReports
Agent outcome reports
No reports yet
Overview
PSSA is a small experimental language model implemented directly in Rust. It combines a selective recurrent layer with hyperbolic memory retrieval and plastic updates. Use it to study recurrent learning and checkpoint workflows on small corpora, with experimental results interpreted within their stated scale.
What it does
PSSA is an experimental language model built around a plastic state-space architecture. Written from scratch in Rust without an ML framework, it processes text token by token through a recurrent layer, retrieves episodic memories, and updates part of its weights while running. It provides a way to investigate learning efficiency, bounded memory retrieval, and persistent state at a small scale rather than a ready-made fluent assistant.
Architecture and plasticity
The default layer has 256 channels, 16 states per channel, and a rank-16 adapter. Token-dependent projections control the selective diagonal recurrence, with negative transition rates and initial timescales spanning 1.5 to 200 tokens. Recurrent state continues across training chunks. Queries combine the current token with recurrent state and retrieve four nearby slots from a Poincare-ball memory bank. A learned channel gate controls the retrieved contribution before a low-rank SiLU adapter and MLP.
Novel inputs can create memory slots; refractory counters limit overwriting. Ridge-regression consolidation folds fast plastic updates into the base transition matrix. The selective SSM recurrence belongs to the S4 and Mamba family; the distinctive mechanisms are the state-conditioned hyperbolic read, novelty and refractory write rules, and consolidation. The default memory capacity is 512 slots with key width 32.
Build and run
Rust with Edition 2024 support and Cargo are required. Start with:
git clone https://github.com/Sparticle62ops/pssa.git
cd pssa
cargo build --release
./target/release/oxide_ai_pssa
The no-argument home screen lists commands and discovered checkpoints and corpora. Commands cover training, generation, interactive chat, JSON evaluation, status, dataset downloads, WikiText cleaning, benchmarking, and GPU probing. Runtime dependencies include ureq for downloads and tokenizers for byte-level BPE. The CPU implementation remains available; optional CUDA dense operations use cuBLAS, and WebGPU availability depends on the selected build and device. Software adapters are refused. GPU probing alone does not establish that every layer operation runs on a GPU.
Data and resumable training
Training accepts the built-in science corpus, local files or directories, HTTP datasets, explicit Hugging Face sources, and comma-separated inputs. Structured responses need supported text fields. Byte-level BPE preserves UTF-8 text with a complete byte fallback; the older word tokenizer remains optional. External downloads require independent licensing, privacy, and content review, and several unreadable-dataset paths can silently fall back to the science corpus.
Combine --skip-tokens, --max-tokens, and --resume to train a long corpus through short checkpoint links while carrying optimizer state forward. Windows crossing EOF wrap to the corpus beginning. Model dimensions and vocabulary must match throughout a resume chain. Defaults include chunk length 64, eight chunks per update, learning rate 1e-3, and seed 42.
The clean-wikitext command repairs spacing artifacts, removes headings and unknown-token markers, and writes normalized UTF-8 lines to a required new output file. It operates with line-sized buffers. Cleaning changes token offsets: prepare one cleaned corpus for a fresh chain and never switch an active resume chain to newly cleaned text.
Checkpoints and inference
V7 saves embed tokenizer JSON alongside training state. V7 BPE generation and chat restore the original vocabulary and reject external --data; V6 and word checkpoints retain older vocabulary checks. V5 artifacts are inference-only and require dataset provenance. The project-specific .pssa format has no migration tooling for other frameworks.
Generation defaults to temperature 0.70, top-24 followed by top-p 0.85 filtering, a repetition penalty, and at most 64 new tokens. It can stop after two generated periods. Set temperature when launching chat: the REPL /temp command acknowledges a value without changing subsequent turns. The CLI has minimal parsing and validation.
Experimental evidence and limits
The reported comparison uses roughly 1.5M-parameter models, cleaned WikiText-103, shared token IDs, seed, and optimizer schedule. On a 198,939-token unseen slice, final cross-entropy was 3.997 for PSSA and 4.429 for the transformer, with perplexities 54.4 and 83.8. These are small-model experimental results, not broad claims of language competence.
A matched CPU training run reported 1,716 versus 415 tokens per second; generating 200 tokens took 226 versus 2,735 milliseconds. Separate GPU-versus-CPU training rates are not comparable architecture evidence. Equal schedules do not establish optimal tuning for each architecture, and a short learning-rate sweep is only a settings probe. Both models produce poor text at this scale. Retention after a corpus switch and memory-bank ablation remain unmeasured. The built-in benchmark exercises synthetic behaviors and serialization rather than general language quality, factuality, or safety. Consult the project LICENSE for licensing terms.
Source README

PSSA: a plastic state-space architecture
Technical deep dive · Support PSSA · The math, in full · Qwen distillation math · Universal converter
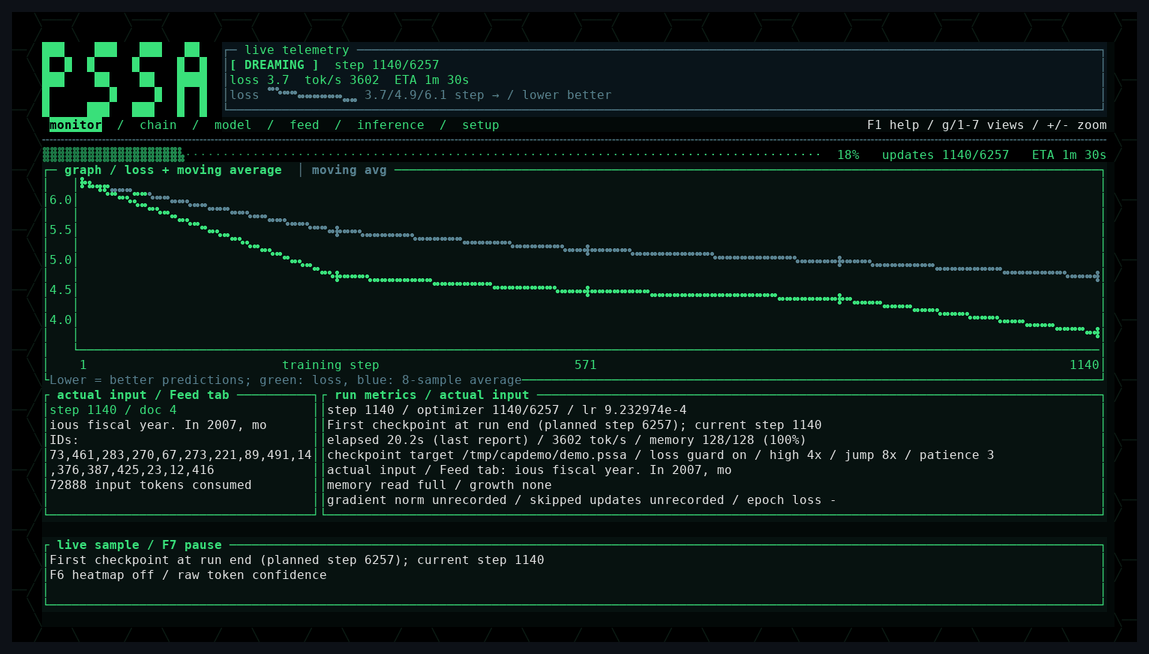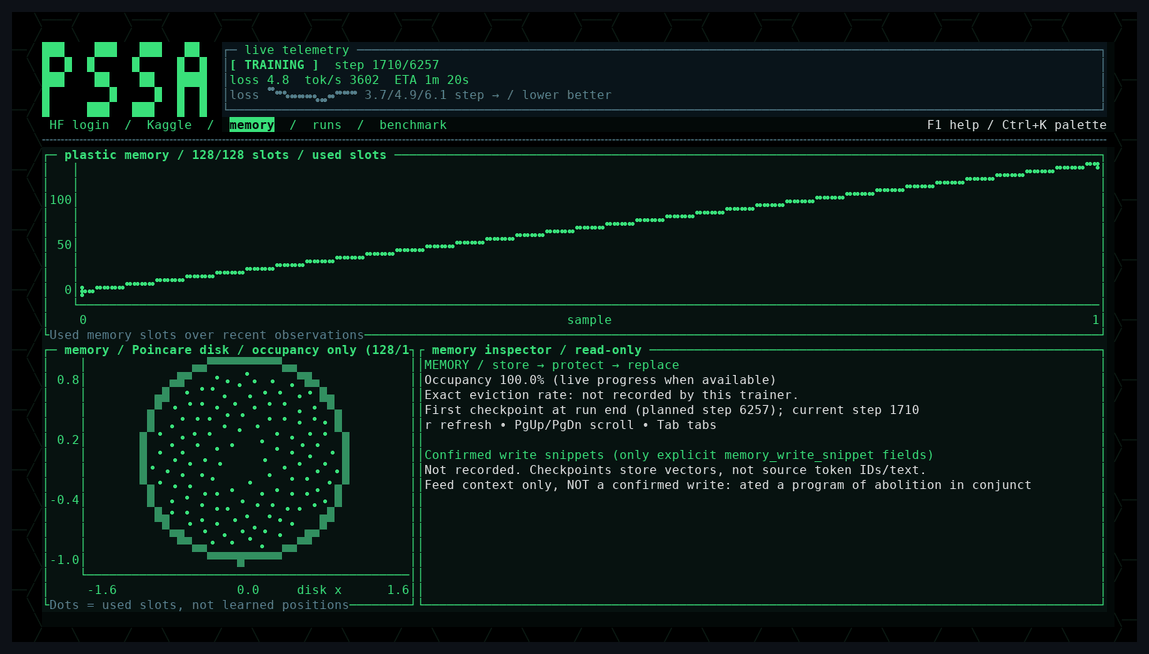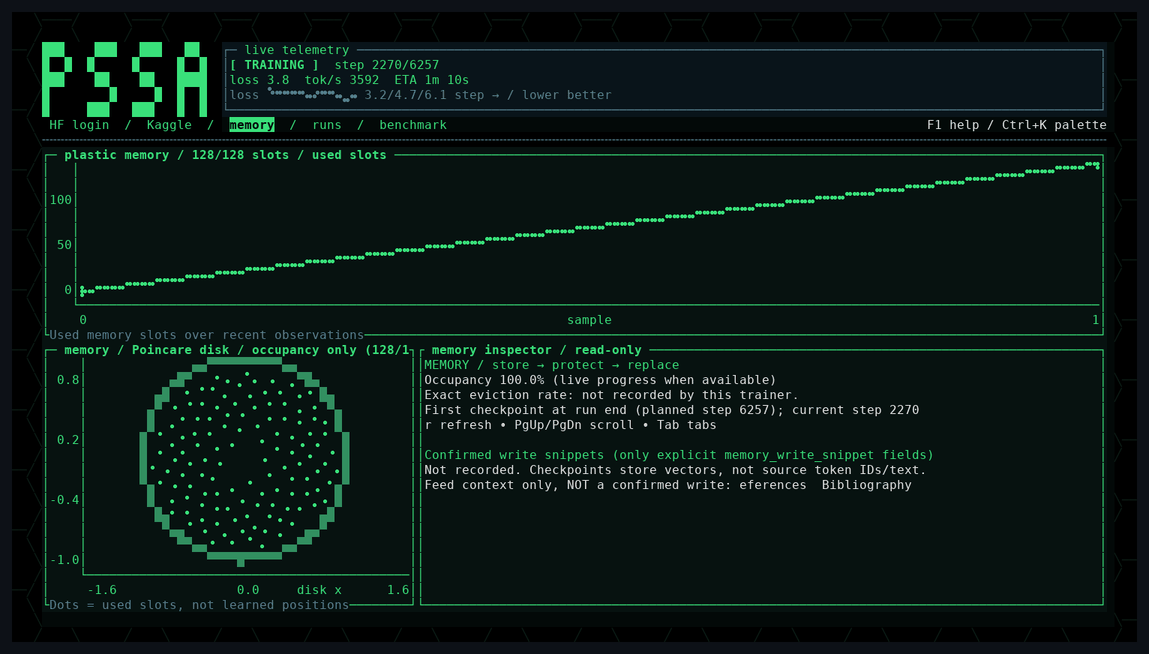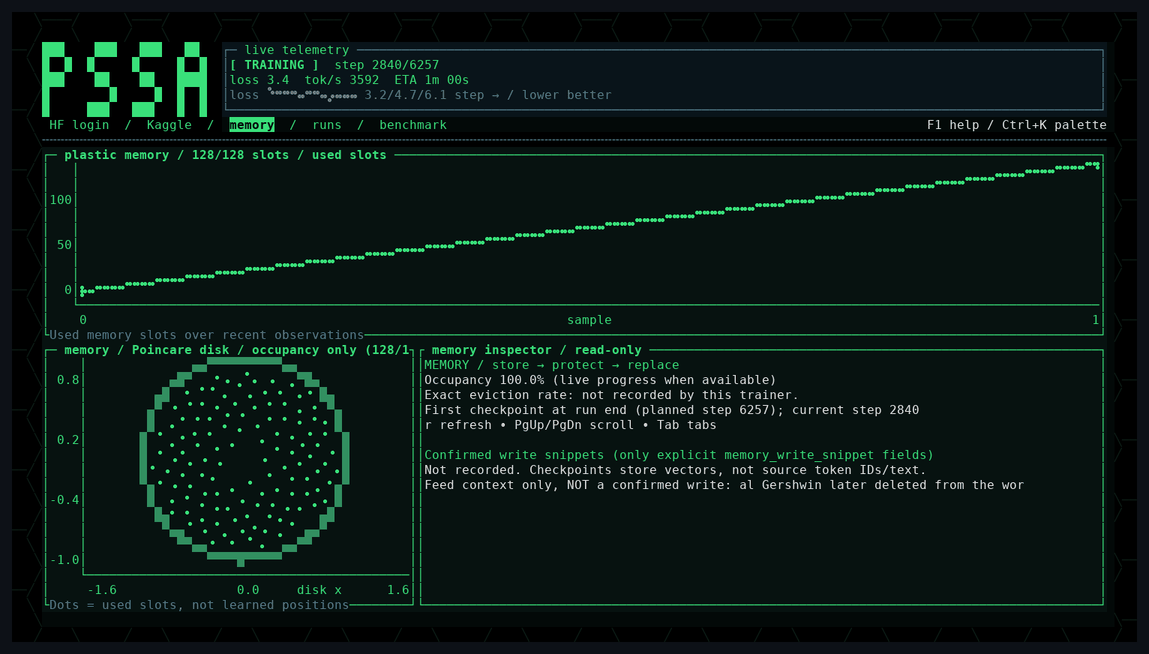
PSSA is a small language model that is not a transformer. It reads text one token at a time through a recurrent state-space layer, keeps a bank of episodic memories it can look things up in, and rewrites part of its own weights while it runs. It is written in Rust from scratch, with no PyTorch, no TensorFlow, and no ML framework of any kind underneath it.
At matched parameters and on the same corpus, it learns faster than a transformer and generates text about twelve times quicker on the same CPU.
Headline result
Two models, same corpus, same tokenizer, same optimizer schedule, same seed, same number of parameters. One is PSSA, one is a standard transformer. Over 12.7M tokens of cleaned WikiText-103, PSSA finished at 3.98 training cross-entropy against 4.43: a gap of 0.45 nats, perplexity 53.7 against 83.7.
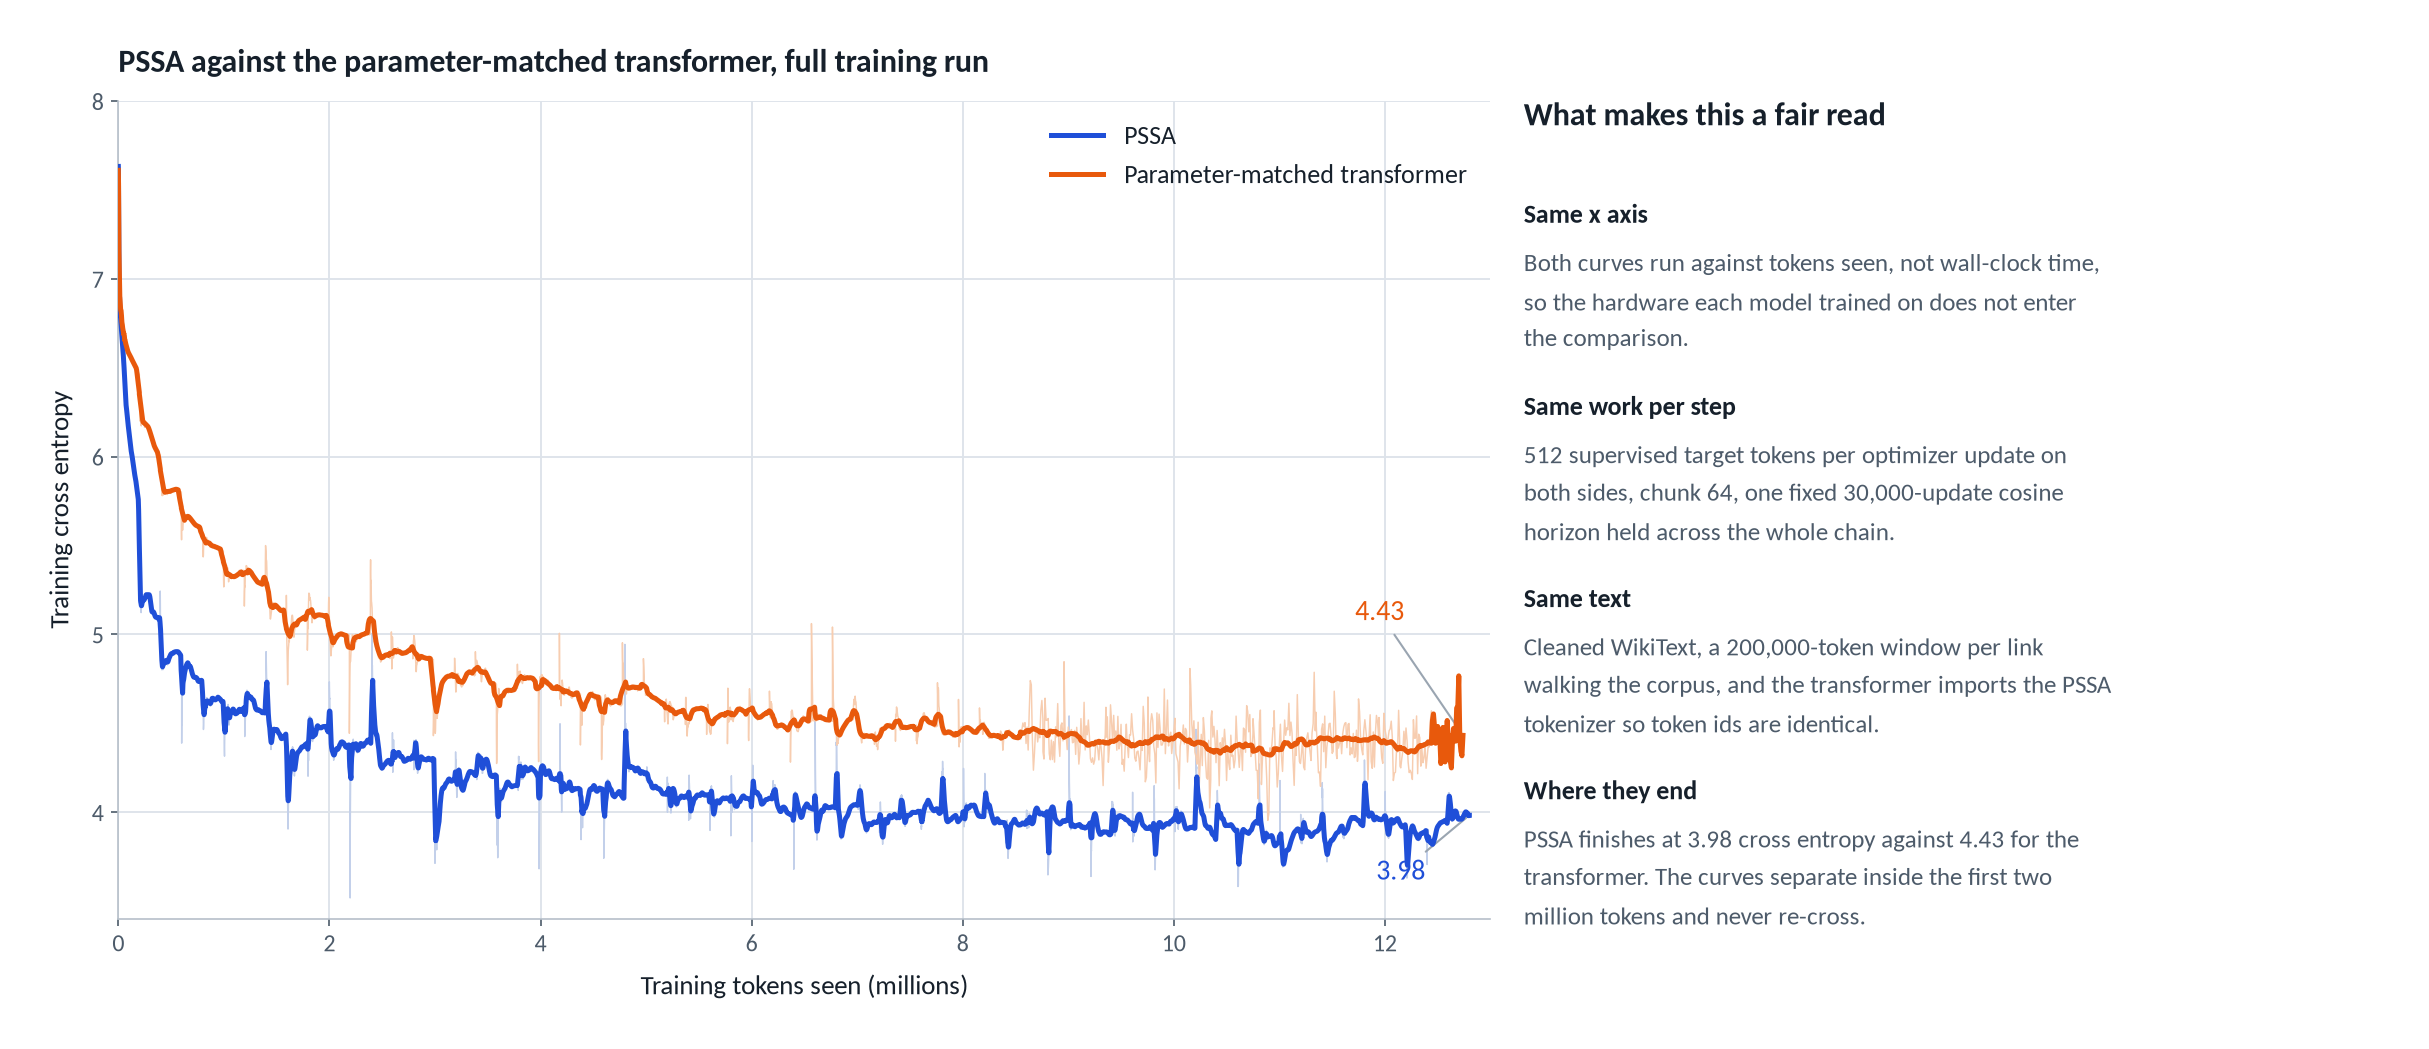
The gap holds on text neither model has seen: on a 198,939-token held-out slice, PSSA scores 3.997 cross-entropy against 4.429 (perplexity 54.4 against 83.8, next-token accuracy 24.1% against 18.0%). On matched CPU hardware PSSA also trains at 1,716 tokens/second against 415 (4.1x), and generates 200 tokens in 226 ms against 2,735 ms (12x).
These are 1.5M-parameter models on 12.7M tokens: a research prototype, not a competitor to anything you have heard of. The full curves, the matched-run methodology, the caveats and the reproduction scripts are in docs/benchmarks.md.
On the held-out slice and on matched CPU hardware:
| Held-out slice, 198,939 unseen tokens | PSSA | Transformer |
|---|---|---|
| Cross-entropy | 3.997 | 4.429 |
| Perplexity | 54.4 | 83.8 |
| Next-token accuracy | 24.1% | 18.0% |
| Same CPU, fixed work | PSSA | Transformer |
|---|---|---|
| Training throughput | 1,716 tok/s | 415 tok/s (4.13x) |
| Generate 200 tokens | 226 ms | 2,735 ms (12x faster) |
Models and weights
- NSC64/pssa-100m - a 109M-parameter PyTorch port of this architecture, trained from scratch by NSC64 on 4B tokens of TinyStories and FineWeb-Edu. Ships bf16 safetensors weights, a 16k byte-level BPE tokenizer and a self-contained loader (plain scan on CPU, fused Triton kernel on CUDA).
- sparticle62/pssa-checkpoints-105m - training checkpoints from the 105M run in progress (raw .pssa resume files, not a packaged model).
- NSC64/pssa-distill-105m - a 107M PSSA student distilled from Qwen3-8B by NSC64, continuing the ck256.pssa base for 5,000 updates on about 2 GB of FineWeb-Edu, OpenWebMath and CodeParrot (0.5 CE + 0.5 KL at temperature 2.0, one RTX PRO 6000). Ships V7 .pssa checkpoints, GPL-3.0.
What makes it different
- A recurrent state-space core. Learned continuous state matrices carry information forward in a fixed-size state, instead of attention over the full context window.
- An episodic memory bank. 512 slots with hyperbolic (Poincare-style) retrieval, written to and read from during the run.
- Plastic weights. Fast updates reinforce what works, novelty drives growth, and a refractory gate rate-limits overwrites.
- Closed-form consolidation. A ridge-regression step folds the fast plastic updates back into the base transition matrix.
- No framework. Hand-written linear algebra in Rust, with a CUDA path for training and a scalar CPU reference that every gradient is checked against (max gradient difference 2.98e-8).
The layer, the write path and the training pipeline are described in docs/architecture.md.
Quick start
git clone https://github.com/Sparticle62ops/pssa.git
cd pssa
cargo install --path .                    # CPU build
cargo install --path . --features cuda    # NVIDIA GPU build (cuBLAS)
pssa
Running it with no arguments opens the dashboard. Everything the dashboard does is also a plain CLI command, so it works the same over SSH, in a notebook terminal, or in a script. Requirements, backends, datasets, Hugging Face caches and long-corpus training chains are covered in docs/setup.md.
Documentation
Getting started and reference:
- docs/setup.md - install, build, backends, datasets, checkpoints.
- docs/architecture.md - how the layer works.
- docs/benchmarks.md - results and how they were measured.
- docs/cli.md - commands and options.
- docs/tui.md - the terminal dashboard.
- docs/tui-setup.md - the TUI training wizard.
- docs/experiments.md - dreaming, the loss guard, memory capacity, the world model.
- docs/convert.md - converting any Hugging Face checkpoint to PSSA.
- docs/contributors.md - building, testing, contributing.
- MODELMATH.md - the math, in full.
- CONTRIBUTING.md - quick build/test/PR guide.
- DONATE.md - sponsorship.
Deeper dives:
- docs/baseline.md - the parameter-matched transformer baseline.
- docs/comparison.md - scoring PSSA against that baseline.
- docs/training-stability.md - gradient clipping and the memory cap.
- docs/paired-eval.md - multi-seed paired evaluation.
- docs/batching.md - independent-sequence batching.
- docs/stacked-depth.md - stacked depth and loops.
- docs/distill-trainer.md - Qwen3-to-PSSA distillation trainer.
- docs/tui-features.md - Kaggle, memory inspector, A/B inference, runs browser, alerts, GIF recording.
- docs/tui-demo.tape - the dashboard GIF recording tape.
- assets/math.md - layer equations, rendered in the dashboard's F11 math tab.
What this is not
- These are 1.5M-parameter models on 12.7M tokens. That is a research prototype, not a competitor to anything you have heard of.
- Text quality at this scale is poor for both models. PSSA emits "a barget of the Prian Academy", the transformer "a material circulation of the United States". The comparison is about learning efficiency, not fluency.
- The speed comparison is CPU-to-CPU, which is fair. The training throughput numbers in the write-up are not hardware-matched and should not be read as an architecture result.
- Two experiments are still unmeasured: retention of earlier skills after a corpus switch, and whether ablating the memory bank changes the loss.
Project status
Current roadmap, the first big training run, depth and loops, WebGPU training and what is next are tracked in docs/contributors.md.
Where the project needs help
Compute
The whole result above was trained on a free hosted notebook with a single entry-level GPU, in 200,000-token links, because a session gets cut after a few hours. Every interesting question left, whether the gap holds at 10x or 100x these parameters, whether the memory bank matters at scale, how it does against a modern recurrent baseline, needs one thing: a GPU with real VRAM and allocations measured in days instead of hours. Anything meaningfully above the entry-level card this ran on changes what can be asked.
If you have compute to grant, or you work somewhere that does, that is the single highest-leverage thing anyone can offer this project. The 105M-parameter run is underway: training checkpoints land on sparticle62/pssa-checkpoints-105m as it goes, and the same-scale transformer baseline is still the milestone this all builds toward.
Sponsorship
Sponsorship funds compute and nothing else. In return you get named here and in the write-up of any result your hardware made possible. Get in touch before sending anything so the details can be agreed.
Donate
Solana: 4XPZ9uAa2BMoth6msoHRxTWL4mUrMfq3LGrxbAGja96h
assets/math.md
Input and state update
x = γ ⊙ (e / √(mean(e²) + 10⁻⁵)) + β Δ = softplus(WΔ x); B = WB x; C = WC x Aᵢⱼ = −softplus(aᵢⱼ) hᵢⱼ ← exp(Δᵢ Aᵢⱼ) hᵢⱼ + Δᵢ Bⱼ xᵢ yᵢ = Σⱼ hᵢⱼ Cⱼ Each latent channel carries a state vector across tokens. Positive Δ controls its decay and input write; this is not an attention matrix. Source: src/pssa.rs:691-698,844-896; src/gpu_batch.rs:490-526
Memory slots and retrieval
q = Wqx x + Wqh y; r = ||q||₂ p = q · min(r/(1+r), Rmax)/r (p = 0 when r = 0) d(p,k) = 2 asinh √(||p−k||² / ((1−||p||²)(1−||k||²))) wⱼ = exp((dmin−dⱼ)/τ) / Σᵢ exp((dmin−dᵢ)/τ) m = Σⱼ wⱼ vⱼ; g = σ(Wgate x) Keys live inside the open Poincaré ball (Rmax is the representable safe radius). Empty memory returns zero. Each depth block owns its own finite bank. Source: src/memory.rs:63-77,110-126,184-237; src/pssa.rs:893-914
Plastic adapter and MLP
a = (Ufast + Uconsolidated) SiLU(D x) z = y/√state + g ⊙ (Wproj m) + a F(x) = z + W₂ SiLU(W₁ z); SiLU(u) = u σ(u) Consolidation: Uconsolidated ← Uconsolidated + α Ufast; Ufast ← (1−α) Ufast. The trainable adapter has rank 16; the MLP expands latent width by 2. Consolidation transfers coefficients without changing their effective sum in exact arithmetic; the slow copy is not an independent trainable matrix. Source: src/pssa.rs:556,916-945; src/adapter.rs:36-48,65-73
Memory write and refractory gate
If chunk loss > 3.5: propose key p and value F(x) at the last token, final loop. Unused slot: append. Full bank: consider only the circular write head. ρ = max((1−exp(−Δstep/60))², 0.005) damage = 0.08 · surprise · ρ If confidence > damage: subtract damage, keep slot; else overwrite and reset confidence to 1. The bank is a separate runtime memory, not trainable model weights. This defense path is not a gradient-based delta-rule write. Δstep is optimizer steps at this call site. Source: src/pssa.rs:2182-2204; src/memory.rs:129-182; src/defense.rs:18-21,45-69
Depth and shared loops
One loop: h₀ = F₀(embed[token]); hₗ = hₗ₋₁ + Fₗ(hₗ₋₁)/√depth for l > 0. Multiple loops: Rₗ(u) starts at u; repeat u ← u + Fₗ,pass(u)/loops. h₀ = R₀(embed[token]); hₗ = hₗ₋₁ + Rₗ(hₗ₋₁)/√depth for l > 0. Each depth block owns independent parameters. Loops reuse that block's weights but keep separate recurrent carry per pass. Loops do not multiply parameter count and are runtime-only (not saved in checkpoints). Source: src/pssa.rs:702-768,1725-1780
Readout and loss
logits = Wunembed h / √latent lossₜ = max(logits) − logits[targetₜ] + ln Σᵢ exp(logitsᵢ − max(logits)) chunk loss = meanₜ(lossₜ) The heatmap reports the raw softmax probability before decoding controls. Low probability means uncertainty, not a training fault. Matrix MAC estimates exclude nonlinearities, memory distance/retrieval, normalization, and backward/optimizer work. Source: src/pssa.rs:1780-1785,1964-1994
Discussion
Questions & comments · 0
Sign In Sign in to leave a comment.