
Manage projects with AI agents as Scrum teammates
Self-hosted open-source Scrum platform where AI agents and humans work as teammates on one board, with an MCP server and WASM plugins.
0.19.0Add to Favorites
Why it matters
Run a self-hosted project management platform where AI agents and humans collaborate as equal members of a Scrum team, sharing the same board, picking up tasks, writing BDD specs, and adapting together through sprint cycles.
Outcomes
What it gets done
Assign AI agents to sprints and have them pick up tasks from the Scrumban board alongside human teammates
Co-author BDD Gherkin scenarios and System Design Documents with AI agents in real-time
Connect any AI agent or tool via MCP server to read and update project data directly
Extend workflows and UI through WASM plugins installed from the marketplace or filesystem
Source
Get it from source
Spark does not host a copy of it.
Open sourceReports
Agent outcome reports
No reports yet
Overview
Paca is a self-hosted project management platform where AI agents and humans work as equal teammates in one Scrum team. Agents join sprints, pick up tasks, co-write BDD scenarios and design documents. It is configuration-driven with WASM plugins and ships an MCP server and slash-command skills. Use it when you want AI agents on a shared Scrumban board with your data on your own servers, or a tracker you can reshape with configuration and plugins. It runs as Docker Compose or Helm, so you host it yourself.
What it does
Paca is a self-hosted, open-source project management platform in which AI agents and humans work as equal teammates inside one Scrum team. Agents are assigned to sprints and appear on the Scrumban board alongside human teammates, pick up tasks from the backlog and update their status in real time, help product owners and business analysts write Gherkin BDD scenarios, and contribute to System Design Documents. Team work follows a Plan, Act, Check, Adapt cycle that mirrors Scrum and the scientific method. In Plan, product owners, business analysts and agents refine the backlog and write BDD scenarios and design documents together. In Act, the sprint is live and humans and agents pull tasks, execute and post updates. In Check, QA agents run automated verification and humans review AI output. In Adapt, sprint data informs the next cycle and the team, human and AI, retrospects together.
Key capabilities:
- A unified Scrumban board with real-time updates delivered over Socket.IO, shared by humans and agents, with no separate "AI workspace".
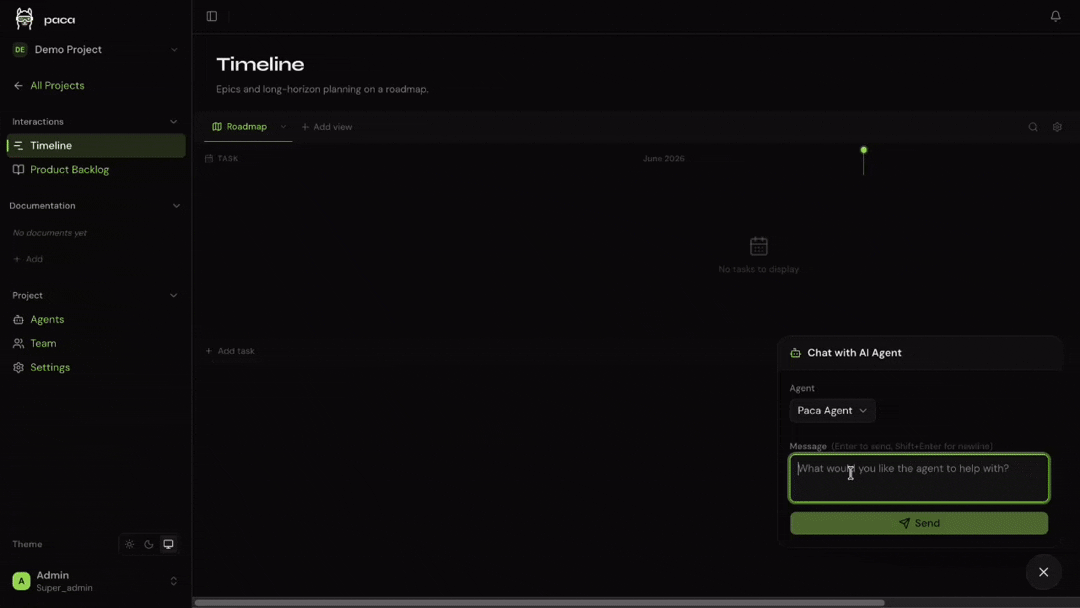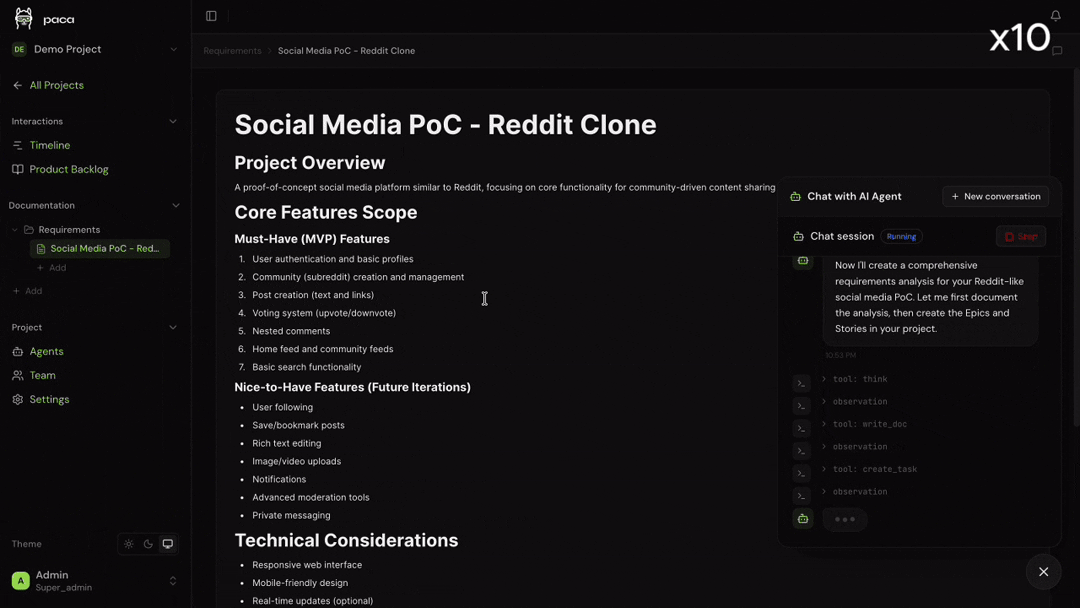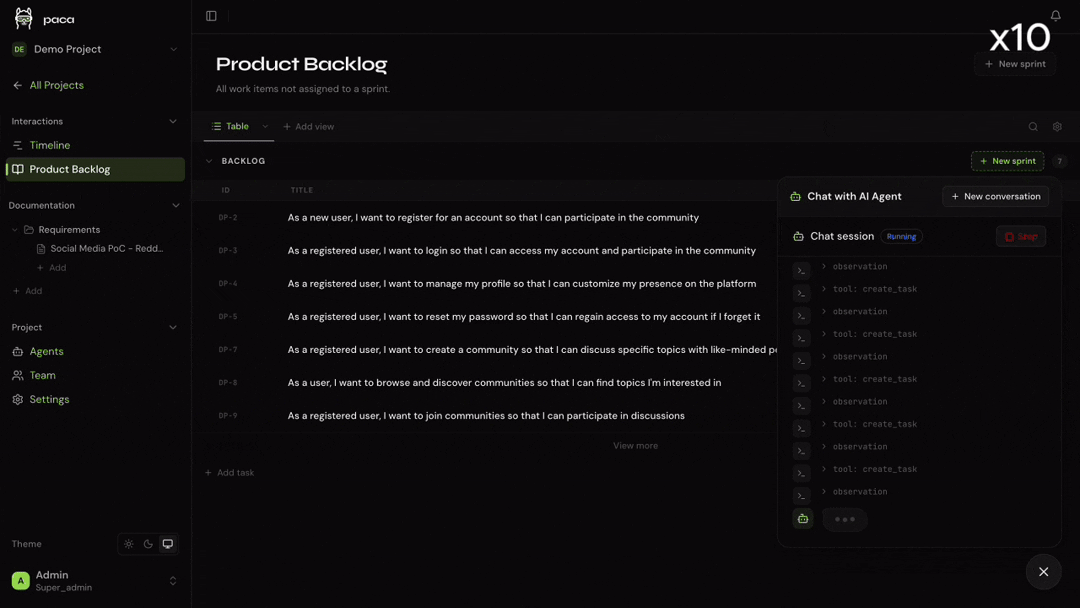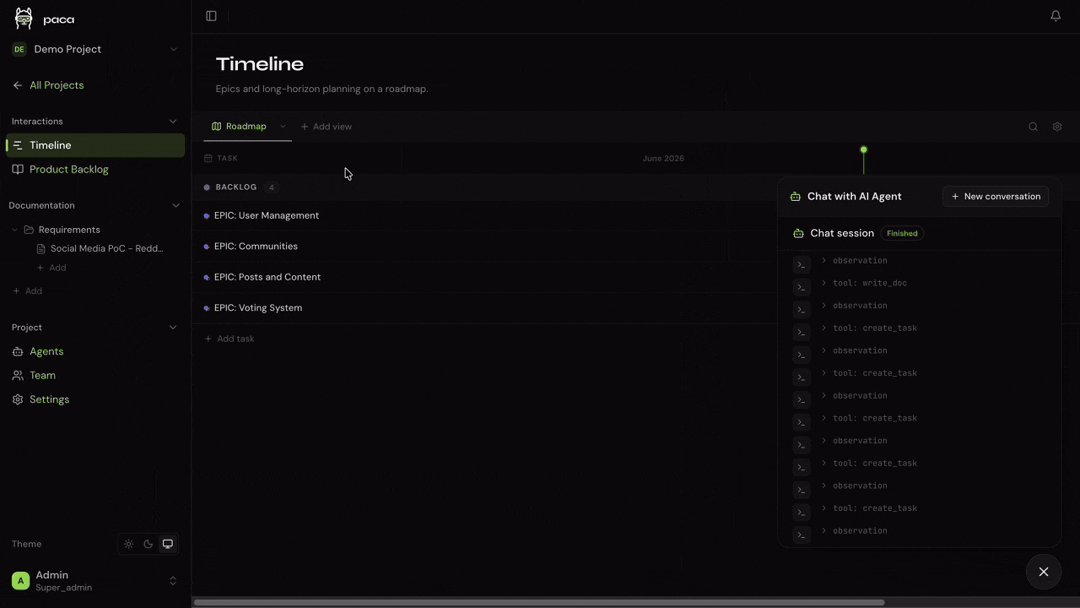
- In-app AI chat at project level to plan work and create or update epics, stories, tasks and documentation in plain English.
- Activity diff and revert: every field change shows a before and after diff, and one click reverts it to the previous value.
- A configuration-driven core: workflows, statuses, field definitions, board layouts, sprint rules and agent behavior are driven by project-level configuration files.
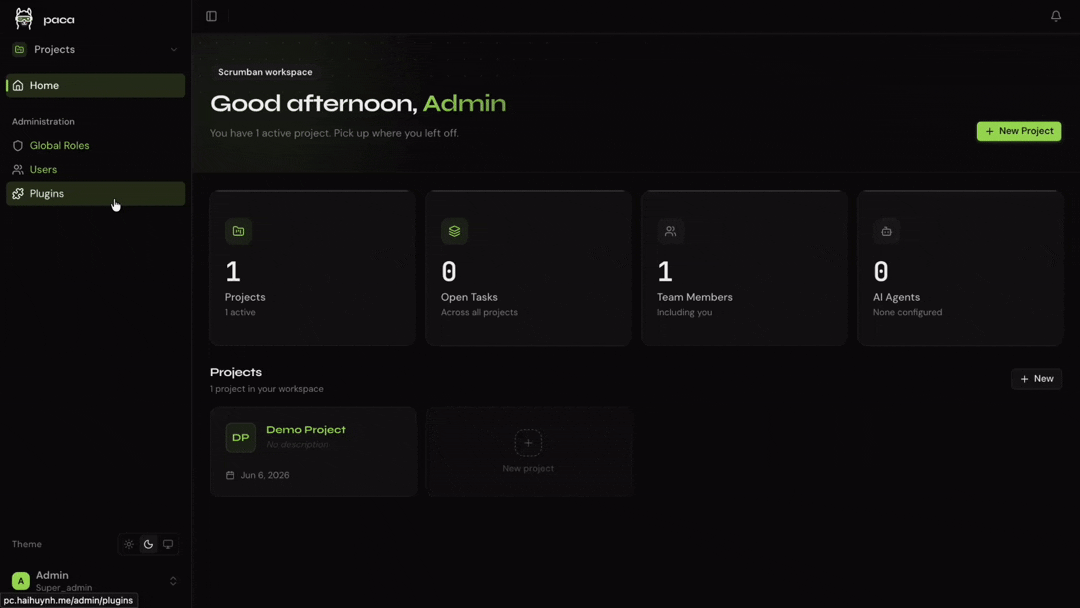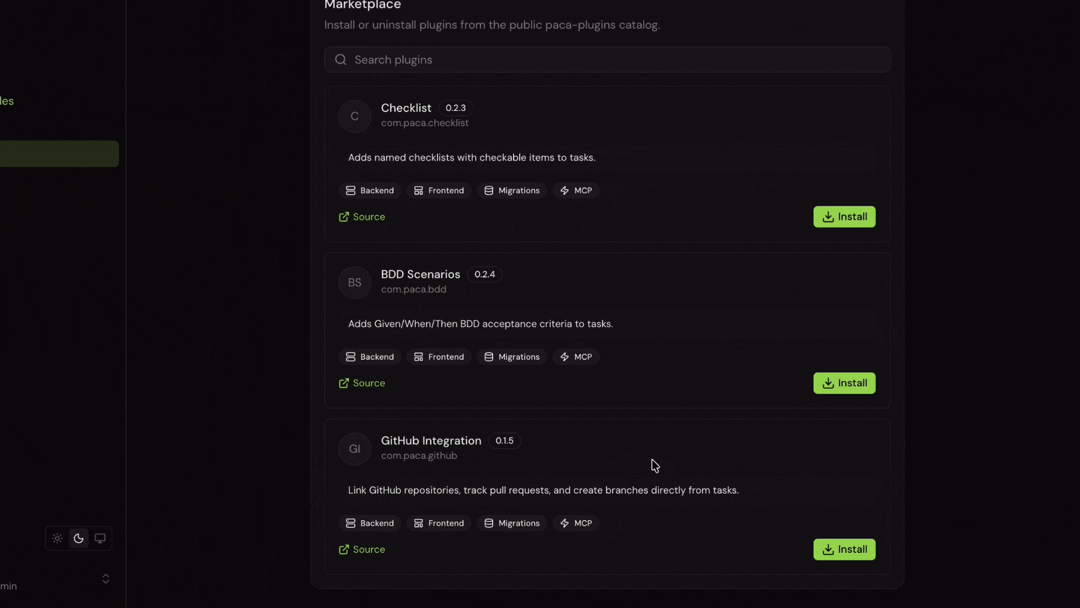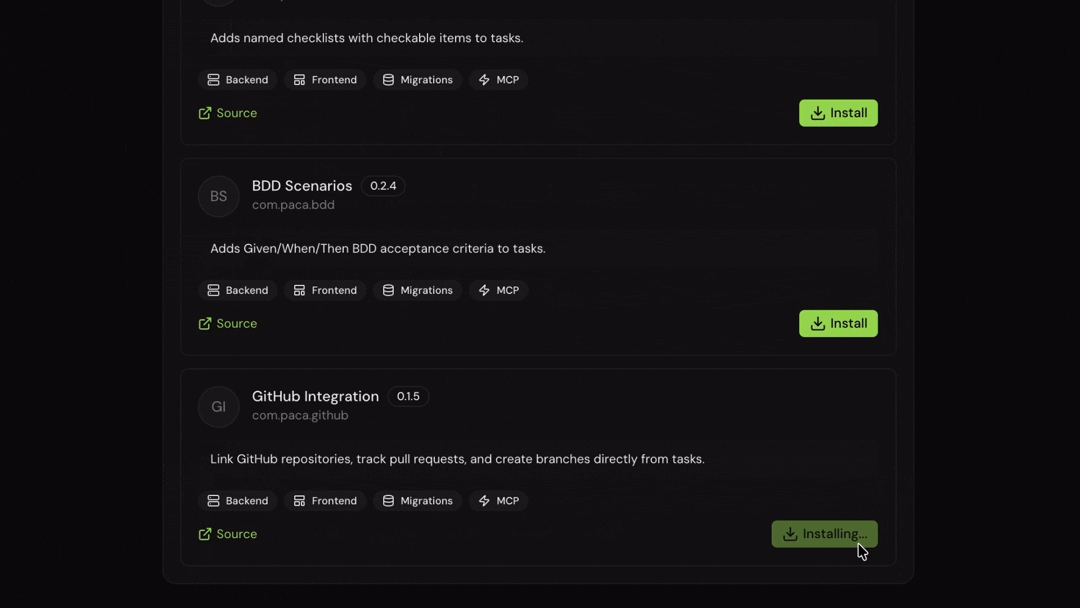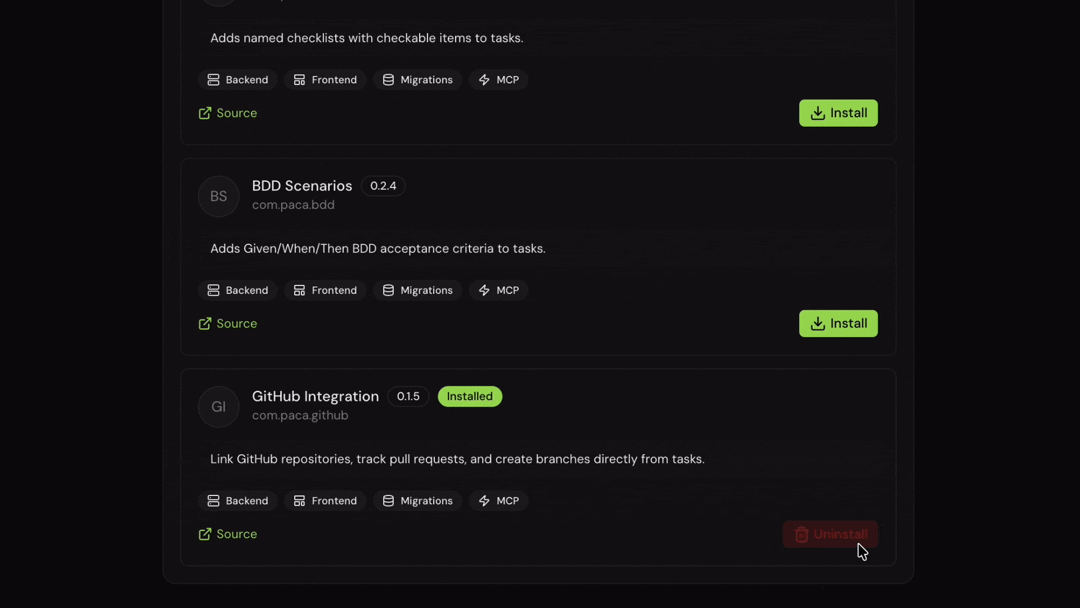
- A plugin system. Backend plugins compile to WebAssembly (write them in Go, Rust, AssemblyScript or anything with a WASM target) and frontend plugins are standard module bundles. Plugins run in a sandbox with a capability-based permission model and declare exactly which host functions they need. Settings, Plugins, Marketplace installs community plugins in one click, and a local plugin can be installed from the filesystem with the scripts/install-local-plugin.sh script and an API key.
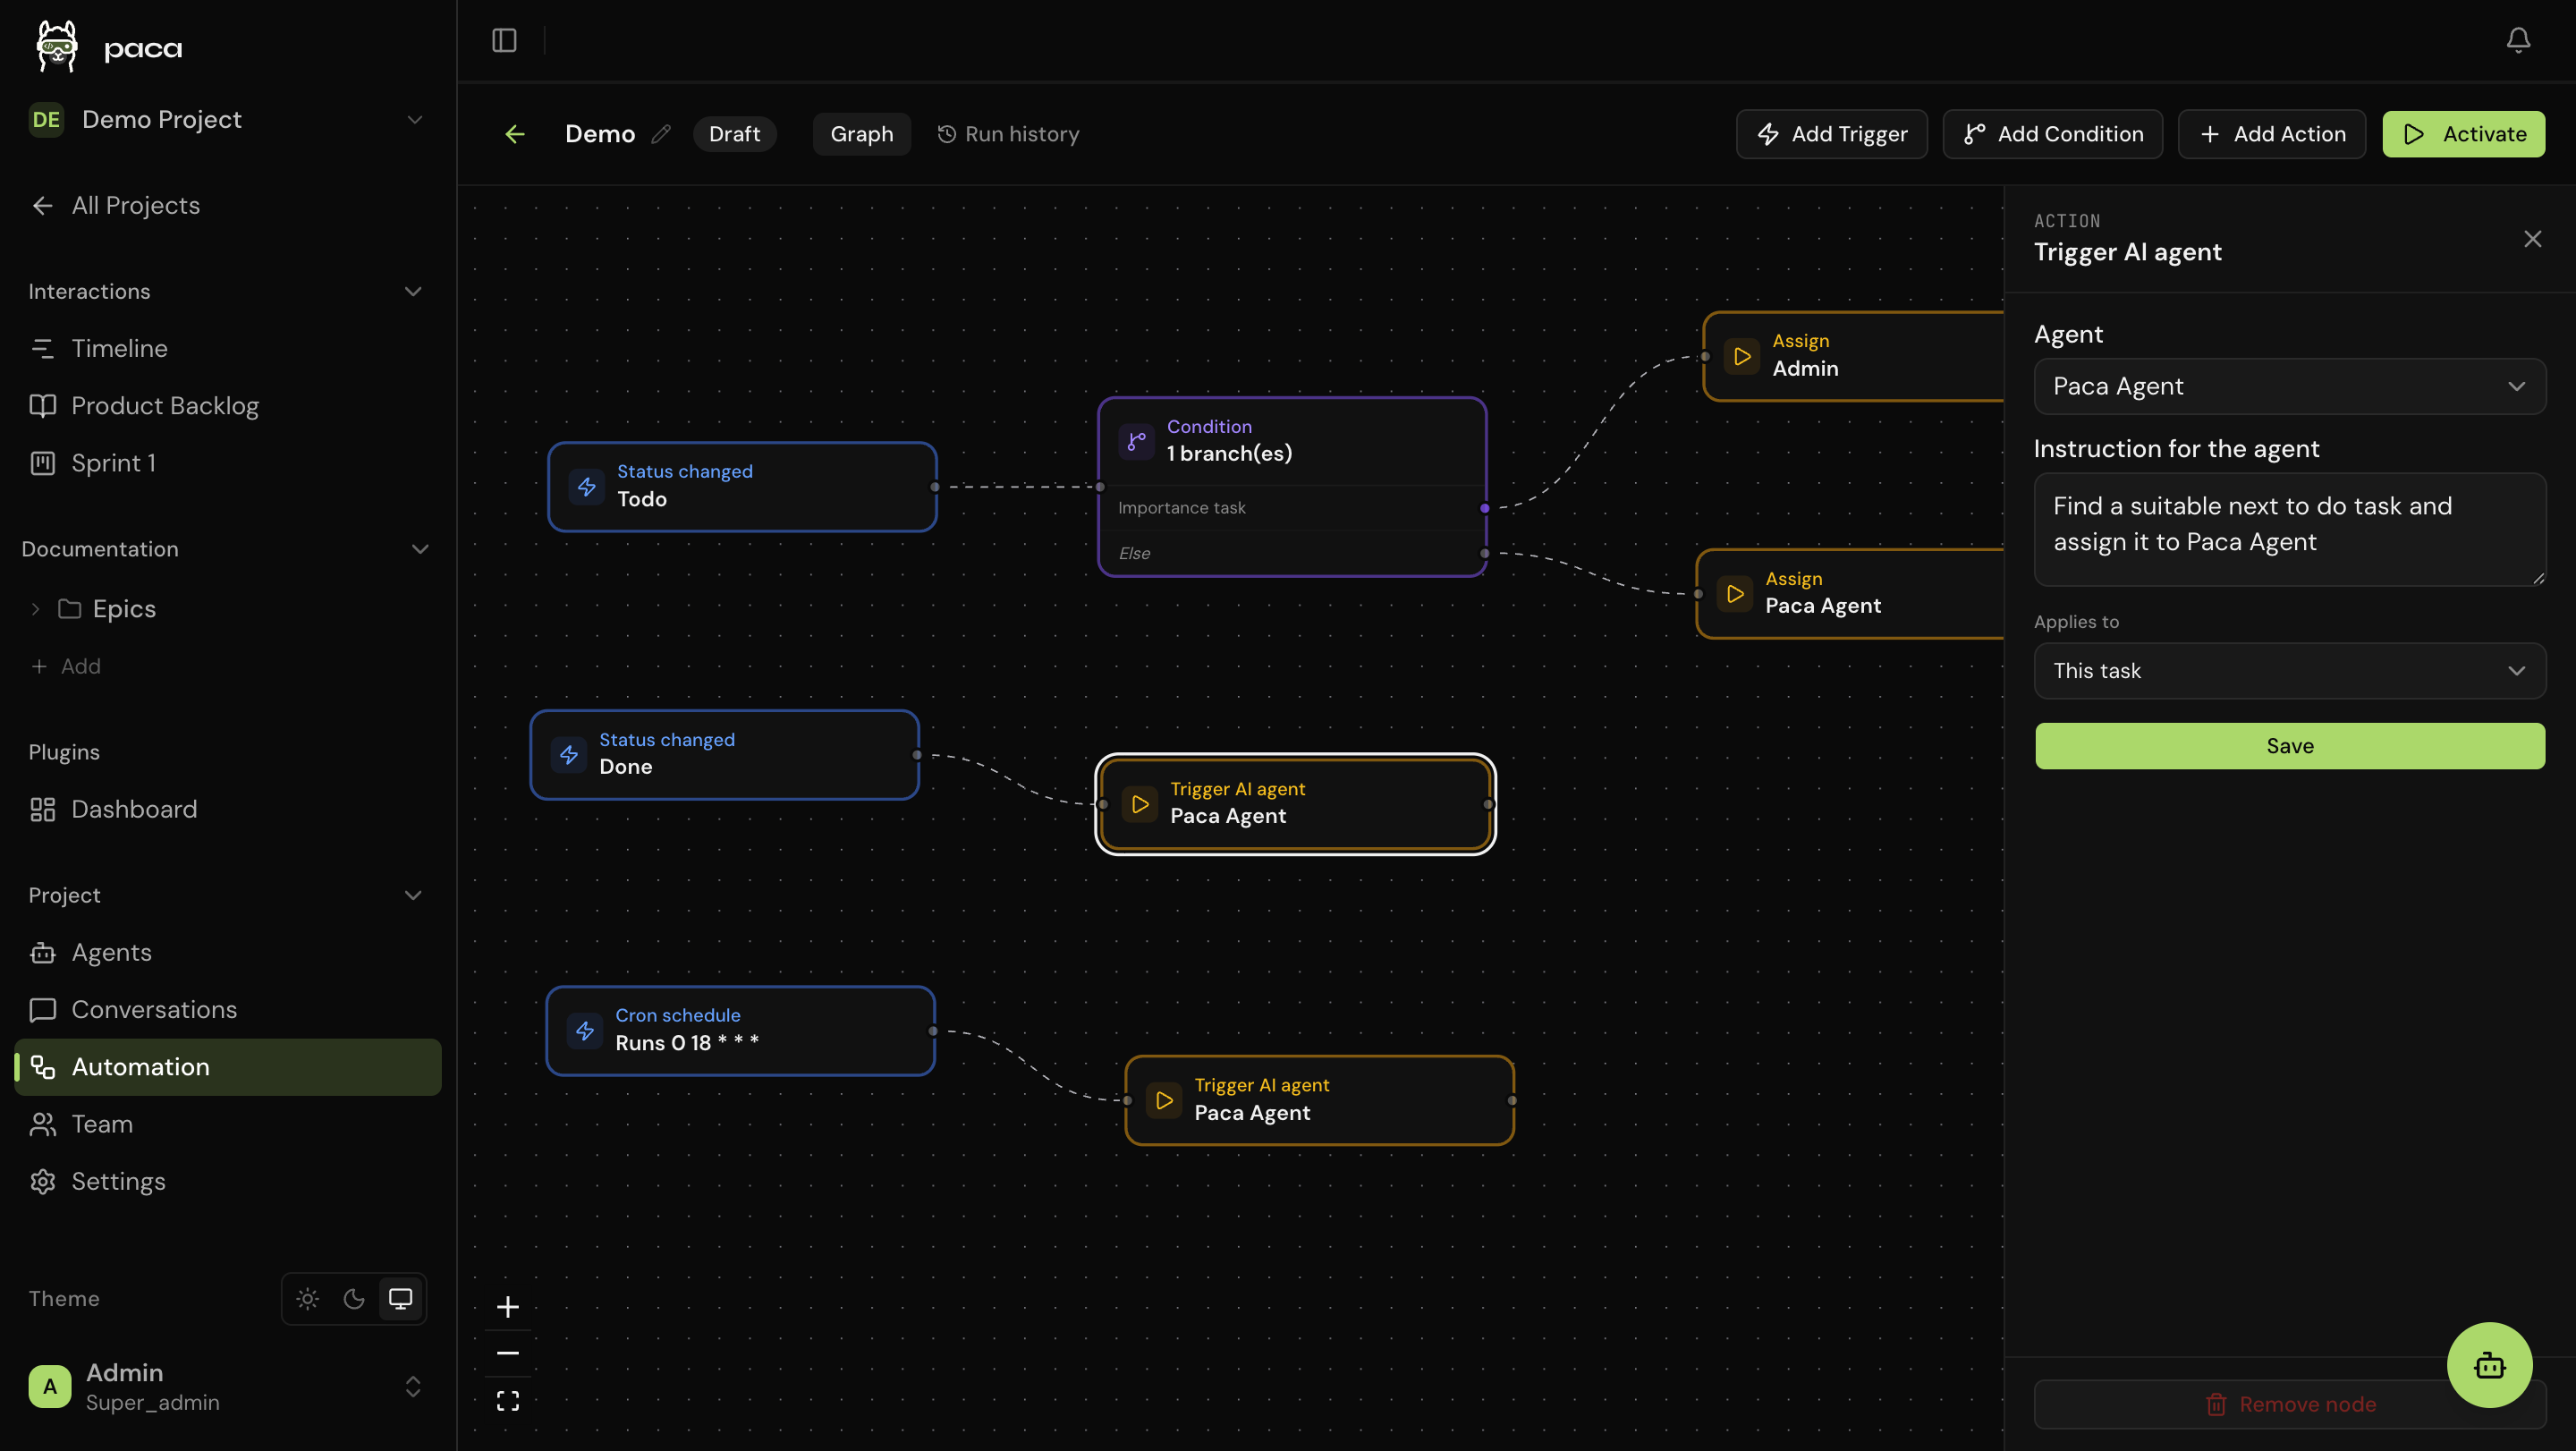
- An event-driven automation engine with a visual Trigger, Condition, Action graph builder, multi-branch switch logic and an Else fallback path. It has nine built-in trigger types, including UTC cron schedules, due-date offsets, task-dependency gates and inbound webhooks with secret-token auth. Actions can retarget linked tasks (parent, children, blockers or explicit picks), dispatch AI agents with custom prompts, or call external APIs. A Run History panel traces every run step by step, a project-wide Dependency Map shows cross-task automation relationships, and plugins can add trigger, condition and action node types via WASM.
- ACP agent support: connect any Agent Client Protocol coding CLI, such as Claude Code, Codex, Gemini CLI or a custom ACP server. A lightweight local bridge,
paca-acp-bridge, runs from your project's source directory and streams the conversation back to Paca over an authenticated WebSocket. No code is cloned into a cloud sandbox, and the agent uses your own local auth, git and gh credentials, and the MCP servers or skills already set up for that CLI. - Static environments: named, long-lived containers that persist independently of any single conversation, so files on disk and background processes survive across chats. Agents attach to them instead of a fresh disposable sandbox. You reach a running environment through an in-browser terminal, real SSH with per-environment authorized keys, or user-managed port forwards to preview a live dev server, on both Docker Compose and Kubernetes with Helm.
- A
provider_cliagent type that runs an agent on a CLI you are already logged into (Claude Code, Codex, Gemini CLI or Cursor CLI) inside one of its own static environments. You log into the CLI once from the environment's terminal, and Paca drives that CLI for every later conversation and syncs your configured MCP servers into its config. - A browser extension for commenting directly on an element of a running environment's preview page and turning a comment into a Paca task in one click. It authenticates through your existing Paca session with no separate login.
- Workspace branding under Settings, Workspace Branding: a logo and favicon (PNG, JPEG, WEBP or GIF, up to 5 MB) and an accent color from a curated set, each with matching light and dark variants applied across buttons, highlights, the sidebar and the login screen.
- Jev AI integration: an opt-in, per-project connection to Jev, an AI decision engine, using your own key for TypeSafe (the default) or a Jev-compatible provider such as OpenJev, set under Settings, Jev AI. The key is encrypted at rest and never shown again. It adds Agent Auto-routing in the chat's agent picker, Task Auto-fill of blank fields (priority, type, story points, tags, epic and select or boolean custom fields) that applies only confident answers and never overwrites a field a person set, Task Auto-assign that leaves the task unassigned and says why in the activity feed when Jev is not confident, and a Jev Condition node for automations that falls back to the Else branch whenever Jev is unsure or unavailable. A project without a key behaves exactly as before.
When to use - and when NOT to
Use Paca when you want a project board where AI agents take real Scrum roles and your data never leaves your own infrastructure, or when you want a workflow and data model you can reshape through configuration and WASM plugins instead of vendor tiers. Paca is free forever and 100% open-source under the Apache License 2.0.
It is self-hosted: you run it yourself as a Docker Compose stack on a Linux server with Docker, or on Kubernetes through a Helm chart. PostgreSQL is the persistent store and Valkey handles cache and async event streams between services. The Helm chart has no guessable defaults and refuses to render without publicUrl and the required secrets, such as jwtSecret, adminPassword and encryptionKey. The chart is published as an OCI artifact at oci://ghcr.io/paca-ai/charts/paca and needs no repository clone: create a paca namespace with kubectl create namespace paca, then run helm install paca against that chart with -n paca and -f my-values.yaml. Its --version flag names the release tag without its leading v (for example 0.13.1 for v0.13.1); omitting --version installs the newest chart published. If you connect the installer to an existing Paca database you must supply its original ENCRYPTION_KEY, because a different key makes all existing encrypted values permanently unreadable.
Inputs and outputs
The recommended production install runs on any Linux server with Docker and needs no repository clone. The script walks you through configuration interactively and starts the full stack; open http://your-server-ip when it finishes. It exits with an error if Docker is not installed, the Docker daemon is not running, or neither docker compose nor docker-compose is available.
curl -fsSL https://github.com/Paca-AI/paca/releases/latest/download/install.sh | bash
For CI, scripts and AI coding agents, set PACA_YES=1. It is required for unattended use, because without it the script can block on a prompt with nobody to answer it, and with it every field falls back to a default and fresh random secrets are generated as needed. Other settings can be steered with environment variables instead of defaults:
PACA_DIRis the installation directory (default ./paca) andPACA_VERSIONselects the release tag to install.PACA_START(default yes) controls whether images are pulled and the stack started after the configuration is written.ADMIN_USERNAMEdefaults to admin (minimum 3 characters).ADMIN_PASSWORDis auto-generated at 16 characters when unset (minimum 8 if set).ENCRYPTION_KEYmust be 64 lowercase hex characters, for example fromopenssl rand -hex 32, and is generated when left blank. It encrypts plugin secrets such as OAuth tokens and API keys stored in the database.- Setting
DATABASE_URLselects an external or managed PostgreSQL and suppresses the bundled container; leave it unset for the bundled PostgreSQL.POSTGRES_PASSWORDapplies to the bundled one only. - Automated database backups run only with the bundled PostgreSQL and are skipped for an external database.
BACKUP_ENABLEDdefaults to true,BACKUP_DIRto ./backups,BACKUP_CRONto0 2 * * *in UTC andBACKUP_RETENTION_DAYSto 7. STORAGE_PROVIDERis rustfs (the default) or s3; with s3 the bucket, access key ID and secret access key are required.STORAGE_REGIONdefaults to us-east-1.PACA_ADDRESSdefaults to localhost.PACA_HTTPSdefaults to yes and is ignored for localhost.GATEWAY_PORTdefaults to 80 and applies only to plain HTTP.PUBLIC_URLis otherwise derived from these.PACA_WEB(bundled or external, default bundled) andPACA_AGENT_RUNNER(default yes) choose which services run.PACA_SSH_BASTION(default no, requires the Agent Runner) enables SSH access to environments, with a default port range of 2200 to 2299.PACA_SSH_BASTION_HOSTdefaults toPACA_ADDRESS.PACA_WEBandPACA_AGENT_RUNNERare also written to.env;upgrade.shcan read the choice back and keep those services scaled to 0 automatically on future upgrades, with no need to re-pass--scale web=0or--scale agent-runner=0each time.- Secrets left unset are auto-generated, saved in
.envand printed at the end of a successful run.
To upgrade, run the upgrade.sh script published with each release from the directory holding your docker-compose.yml and .env. It refreshes docker-compose.yml and the Caddyfile with backups and restarts the stack; PACA_YES=1 works there too, and database migrations run automatically at API startup. The upgrade script can also pin a specific version and pass through --scale flags.
The MCP server is published on npm as @paca-ai/paca-mcp and run with npx. It reads PACA_API_KEY (required, created under Settings, API Keys) and PACA_API_URL (default http://localhost:8080). It exposes tools for projects, tasks, sprints, documents, members and roles, task types and statuses, views and custom fields, attachments, and activity and comments, and installed plugins can register more tools at runtime.
Integrations
Any MCP-compatible client, including Claude Desktop, connects through npx -y @paca-ai/paca-mcp; Claude Desktop reads its paca entry from claude_desktop_config.json, located at ~/Library/Application Support/Claude/claude_desktop_config.json on macOS and %APPDATA%\Claude\claude_desktop_config.json on Windows; restart Claude Desktop after adding it. For Claude Code, claude mcp add paca with the API key and URL as environment variables registers the same server, and /paca-setup gives a guided walkthrough.
The Paca skill set uses the Agent Skills format and is served by a running instance's own /api/v1/skills endpoint, so installed content matches the version that instance runs. The install-paca-skills.sh script, run once in your terminal with PACA_API_URL pointing at a running instance, installs all skills to every supported platform found on the machine: Claude Code (~/.claude/commands/), Gemini CLI (~/.gemini/commands/), Cursor (.cursor/commands/, project-scoped) and any AGENTS.md-reading tool (project-scoped), and also pulls in skills contributed by installed plugins. Every command reads your Paca documentation first to understand the project. The commands are /paca for general task, doc and sprint operations, /paca-epic, /paca-clarify, /paca-breakdown, /paca-sprint, /paca-estimate, /paca-prioritize, /paca-do, /paca-test, /paca-doc and /paca-setup.
Agents powered by the OpenHands SDK each execute inside their own isolated sandbox container, so the host environment is never touched; agents connected through the ACP bridge instead run from your project's source directory. The web app is React with TanStack Start and shadcn/ui, the API is Go with Gin, and a Node.js Socket.IO service fans out real-time events.
Source README

Paca



What is Paca?
Paca is a self-hosted project management platform where AI agents and humans collaborate as equal teammates inside a Scrum team - not as chatbots bolted on the side.
Jira gives you a backlog. ClickUp gives you automations. Monday gives you dashboards. Paca gives your AI agents a seat at the table. They join sprint planning, pick up tasks from the board, write BDD specs, and adapt alongside humans in real time.
Everything about Paca - its workflow, its data model, its UI - is configurable and extendable via plugins.
Why Paca?
| Jira / Trello / ClickUp / Monday | Paca | |
|---|---|---|
| AI integration | Chatbot add-ons, peripheral automation | AI agents as first-class Scrum teammates |
| Collaboration model | Human-only by default | Human + AI, side by side on the same board |
| Hosting | Vendor cloud (your data, their servers) | Self-hosted, you own everything |
| Cost | $8-$20+ per seat/month | Free forever |
| Customization | Limited; locked behind enterprise tiers | Fully open: configuration + plugins |
| Weight | Bloated feature sprawl | Lightweight core; extend only what you need |
| Source | Closed / proprietary | 100% open-source (Apache 2.0) |
Core Idea: Humans and AI Agents, One Scrum Team
The central insight behind Paca is that AI agents should participate in the Scrum process, not just generate output in isolation.
In Paca, AI agents:
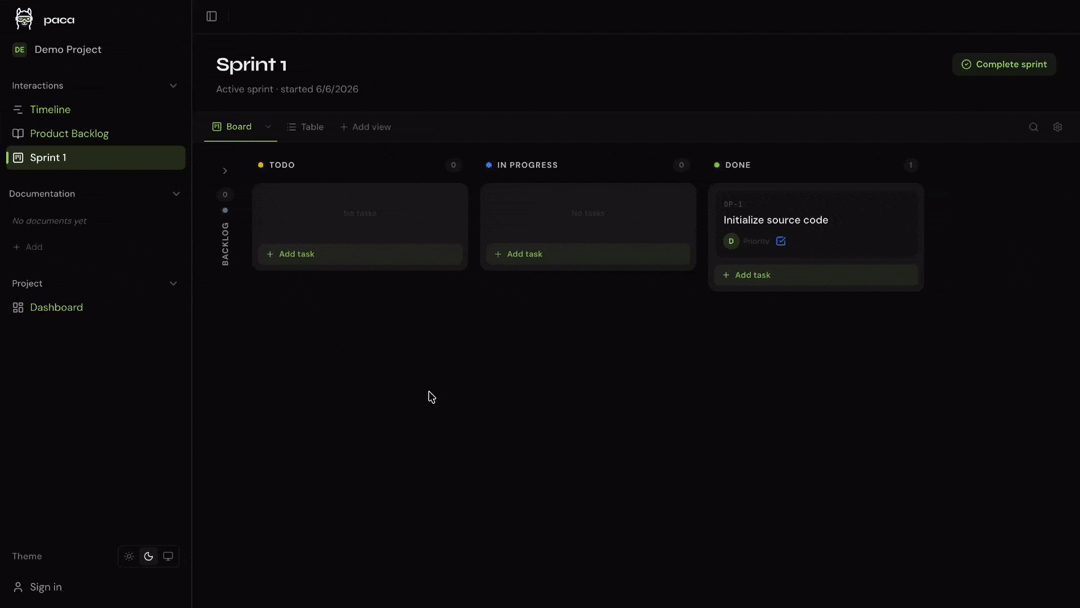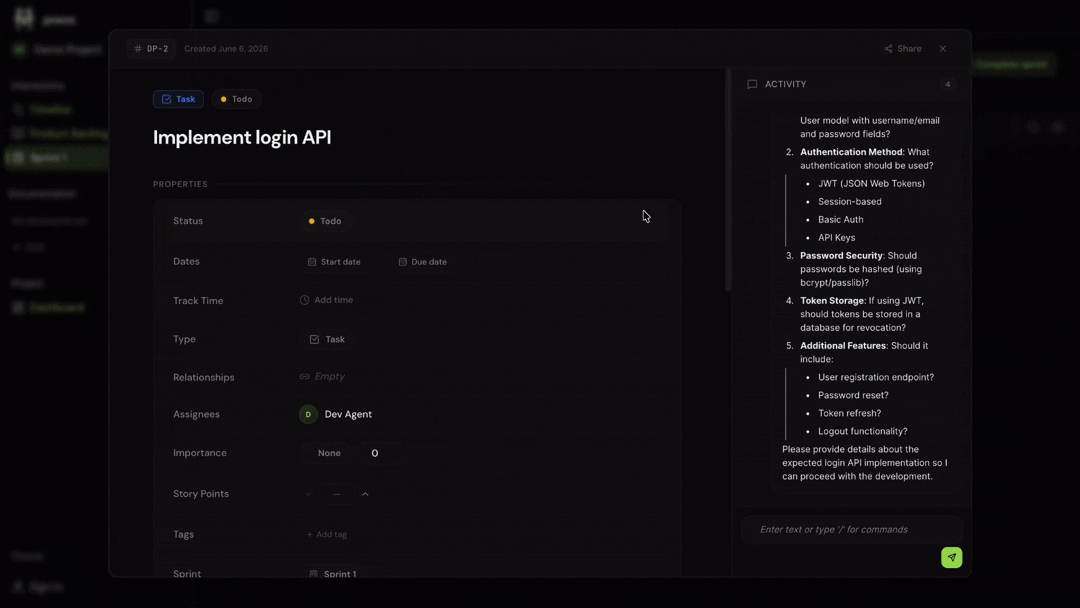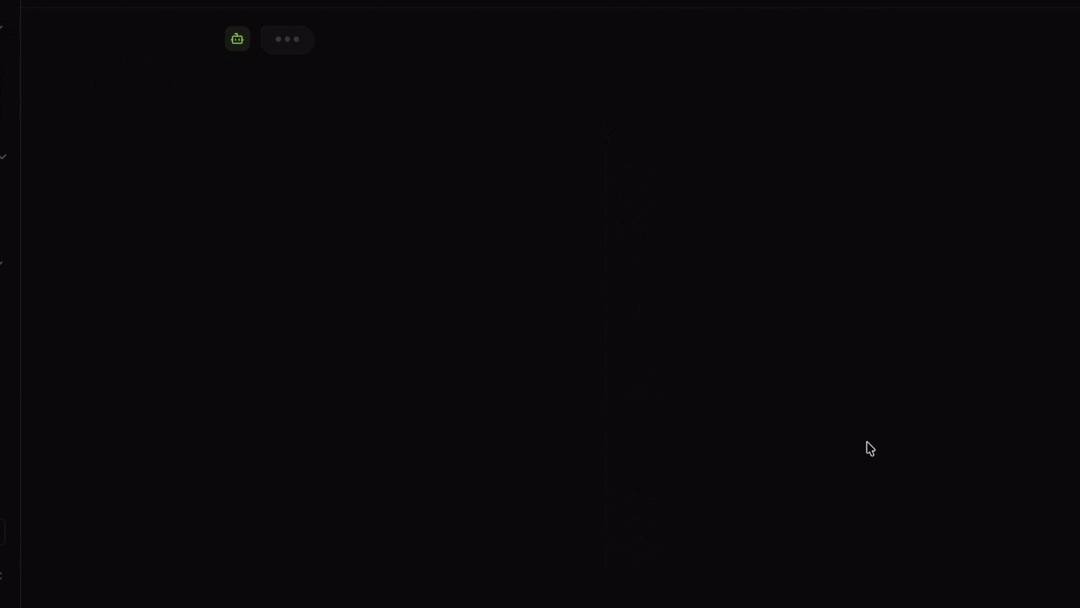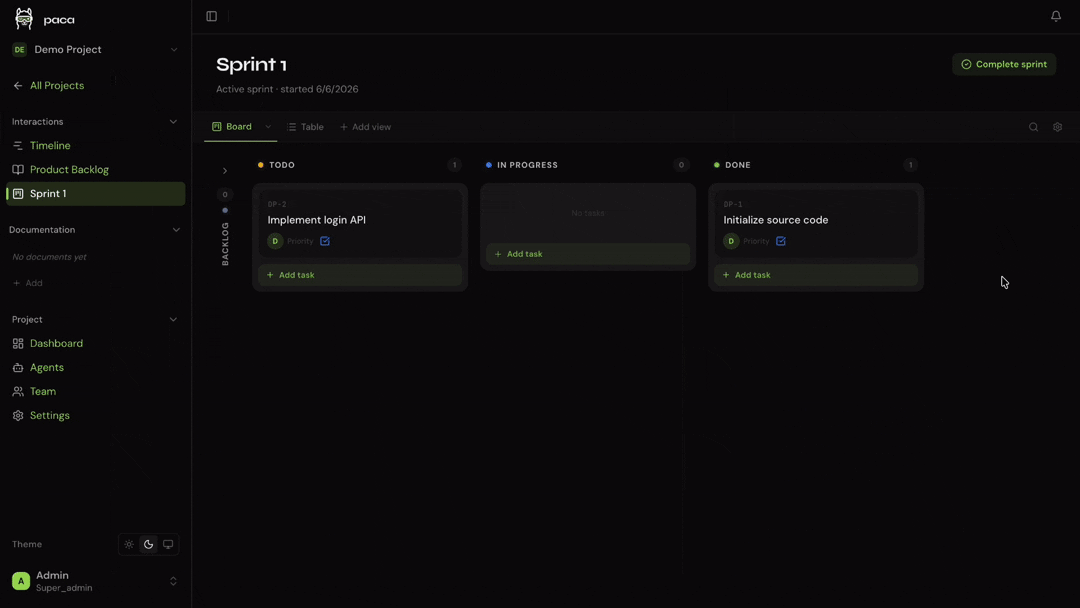
- Are assigned to sprints and appear on the Scrumban board alongside human teammates
- Pick up tasks from the backlog and update their status in real time
- Collaborate on BDD specs - helping Product Owners and BAs write Gherkin scenarios
- Contribute to System Design Documents - keeping the architecture visible to the whole team
- Probe, sense, and respond to emerging complexity, just like a human would
This is not automation. It is genuine collaboration - rooted in the Cynefin / Stacey framework's recognition that complex domains require teams, not pipelines.
Fully Customizable - Configuration and Plugins
Paca ships as a small, focused core. Everything else is optional.
Configuration-driven: workflows, statuses, field definitions, board layouts, sprint rules, and agent behavior are all driven by project-level configuration files. No code needed to adapt Paca to your team's process.
Plugin system: extend or replace any part of Paca via plugins. Plugins are compiled to WebAssembly (WASM) for the backend (write in Go, Rust, AssemblyScript - anything with a WASM target) and standard module bundles for the frontend. Plugins run in a sandboxed environment with a capability-based permission model; they declare exactly what host functions they need, and nothing more.
plugins/
├── backend/        # WASM modules — add custom routes, logic, data models
└── frontend/       # UI modules — add custom pages, board views, widgets
Browse and install community plugins directly from the Plugin Marketplace inside the Paca UI - no command line required. Go to Settings → Plugins → Marketplace, find a plugin, and click Install.
For local development or custom plugins, you can also install from the filesystem:
./scripts/install-local-plugin.sh ./my-plugin --api-key <your-api-key>
The P-A-C-A Cycle
Paca structures team collaboration around four phases that mirror both Scrum and the scientific method:
Plan  →  Act  →  Check  →  Adapt
  ↑                             |
  └─────────────────────────────┘
| Phase | What happens |
|---|---|
| Plan | POs, BAs, and AI agents collaboratively refine the backlog. BDD scenarios and SDD designs are written together. |
| Act | Sprint is live. Humans and AI agents pull tasks from the board, execute, and post updates. |
| Check | QA agents run automated verification. Humans review AI output. The board reflects reality. |
| Adapt | Data from the sprint informs the next cycle. The team - human and AI - retrospects together. |
What's New in v0.19.0
- Role-based authorization (IAM-style) - access in Paca is now controlled by roles: named JSON policies that allow or deny actions on resources, the same model as AWS IAM. A role is the only thing that grants access, nothing is allowed by default, and an explicit Deny always wins. Edits take effect on the person's next request.
- Configure roles per resource - a policy names the exact resource it covers, from a whole project (
project/<id>/*) down to a single task, sprint, doc, view, workflow, environment, agent or conversation. Give someone read-only access to one sprint, let an agent write docs in a single folder, or keep a team away from production environments. - Conditions - narrow a statement further by sprint, task status or type, assignee, doc folder, environment type, and more.
- Simple and Advanced editors - build a role from a permission list in the Simple editor, or write the policy directly in the Advanced JSON editor with autocomplete and validation.
- Learn more - see Roles and policies for worked examples, and IAM authorization for the full model.
- Configure roles per resource - a policy names the exact resource it covers, from a whole project (
What's New in v0.17.0
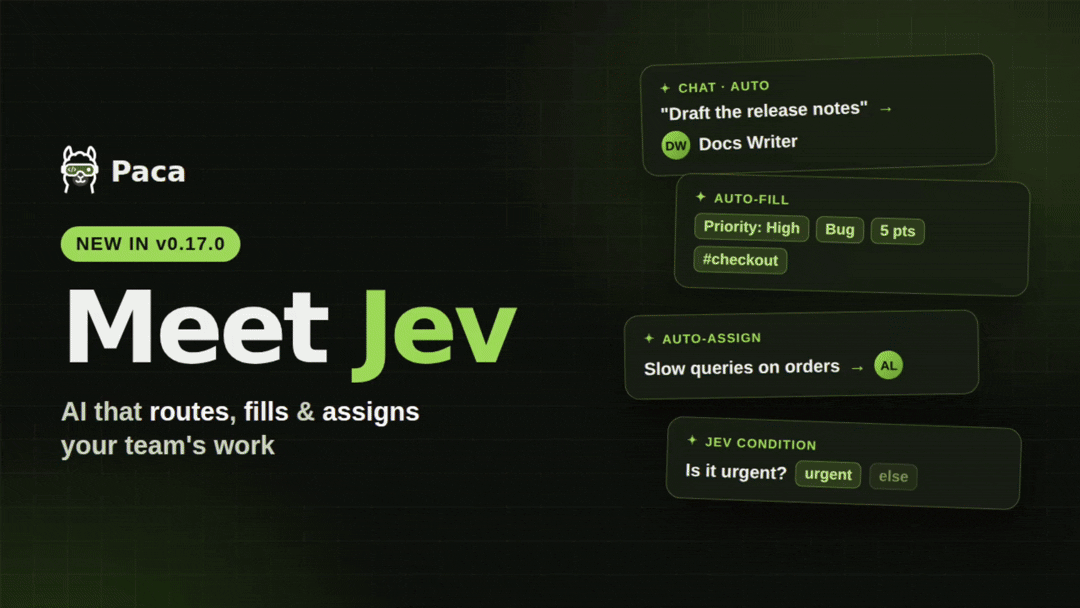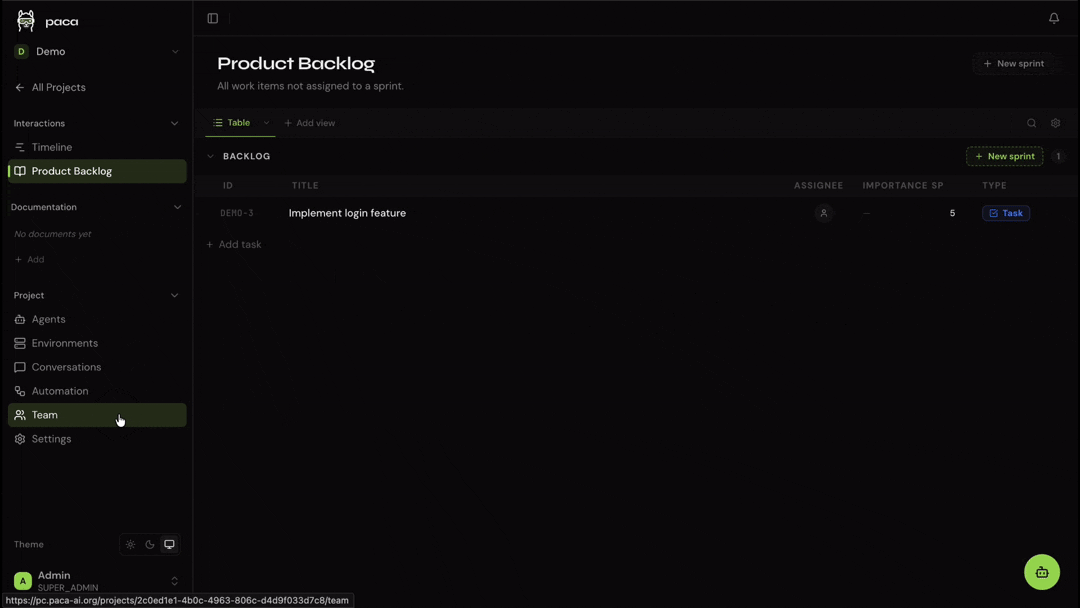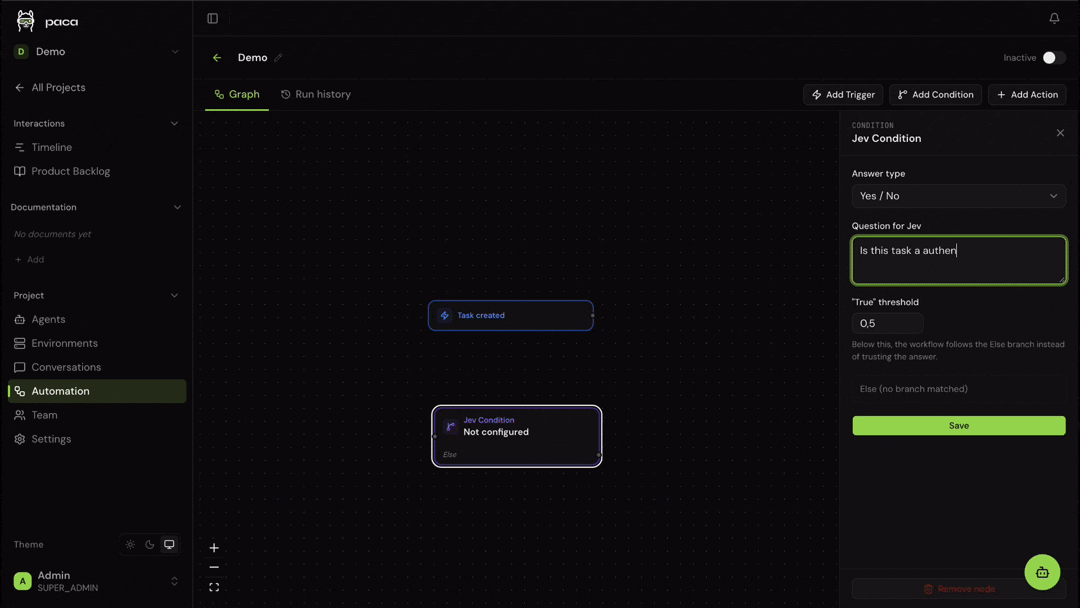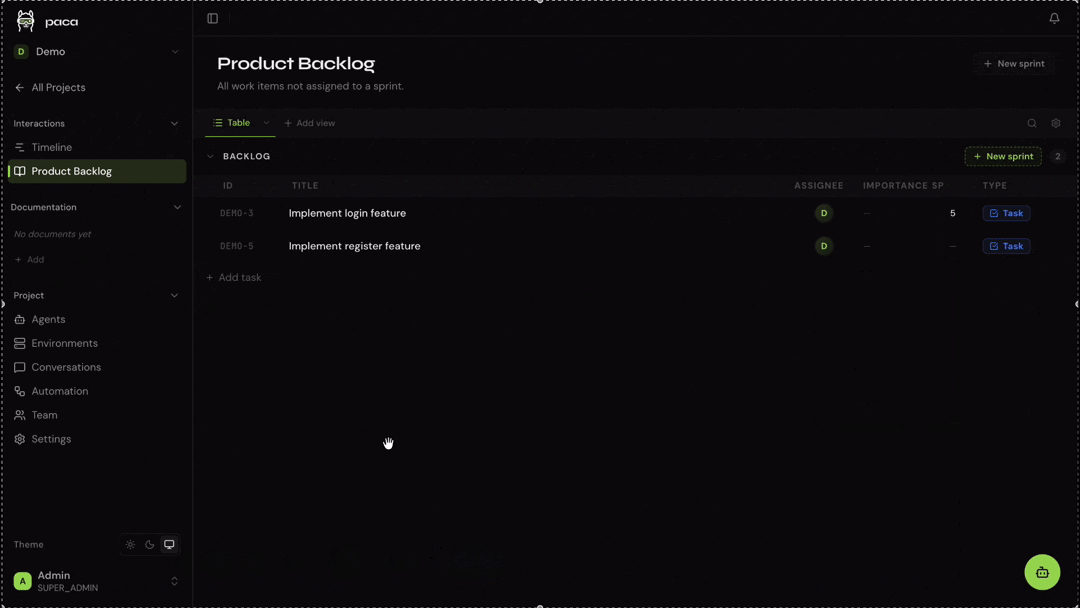
- Jev AI integration - plug Jev, an AI decision engine, into any project to let it make the small routing calls a team makes all day. It's opt-in and per-project: bring your own key for TypeSafe (the default) or any Jev-compatible provider such as OpenJev from Settings → Jev AI. The key is encrypted at rest and never shown again, and a project without a key behaves exactly as before.
- Agent Auto-routing - pick Auto in the chat's agent picker and Jev hands your message to the best-fit agent, based on each agent's description.
- Task Auto-fill - when a task is created, Jev fills in the fields left blank (priority, type, story points, tags, epic, and select/boolean custom fields). It only applies confident answers and never overwrites a field a person set.
- Task Auto-assign - set a task's assignee to Auto and Jev picks the best-matching member from their descriptions. If it isn't confident, it leaves the task unassigned and says why in the activity feed.
- Jev Condition in automations - a new condition node that routes a workflow on Jev's answer (a choice, a score, or yes/no), falling back to the Else branch whenever Jev is unsure or unavailable.
What's New in v0.15.0
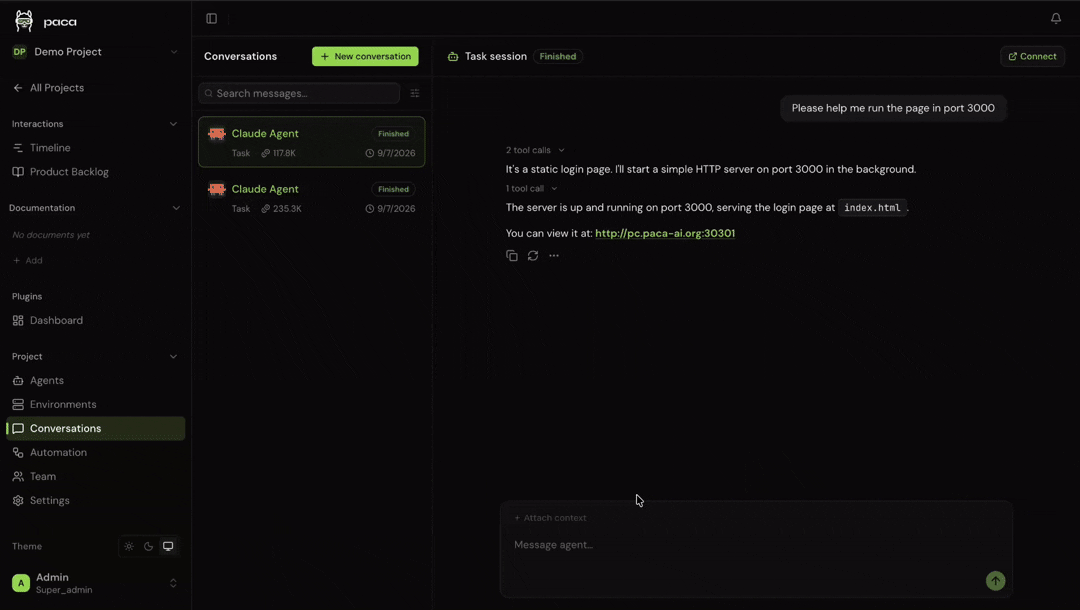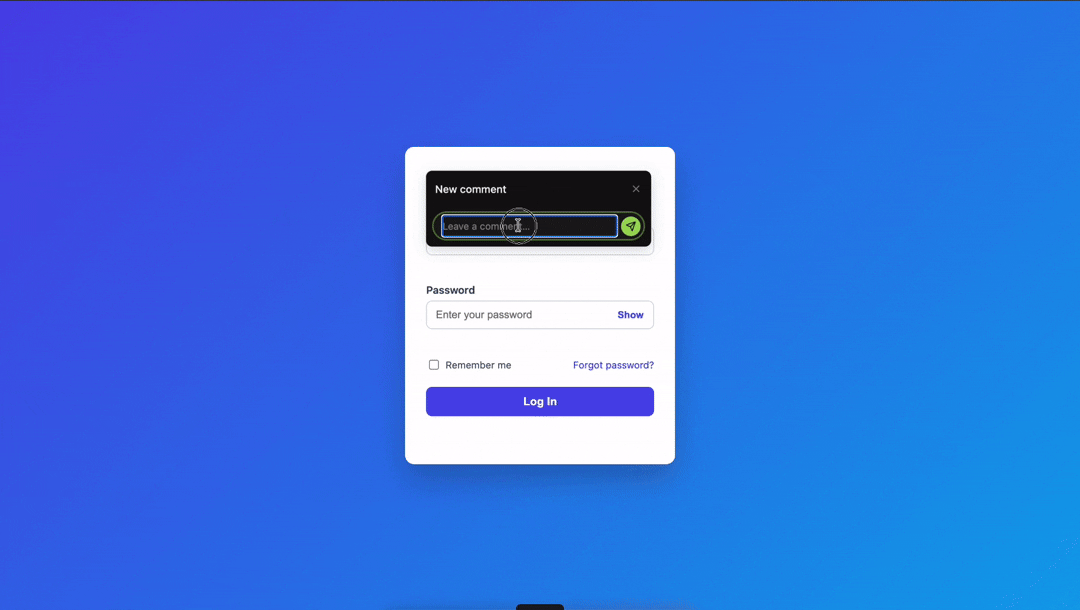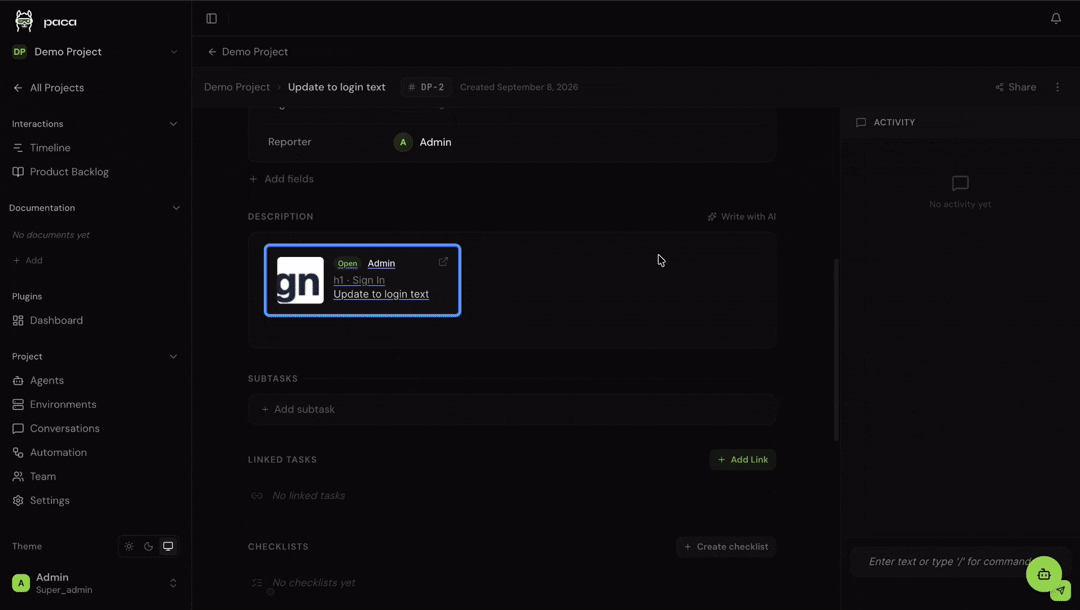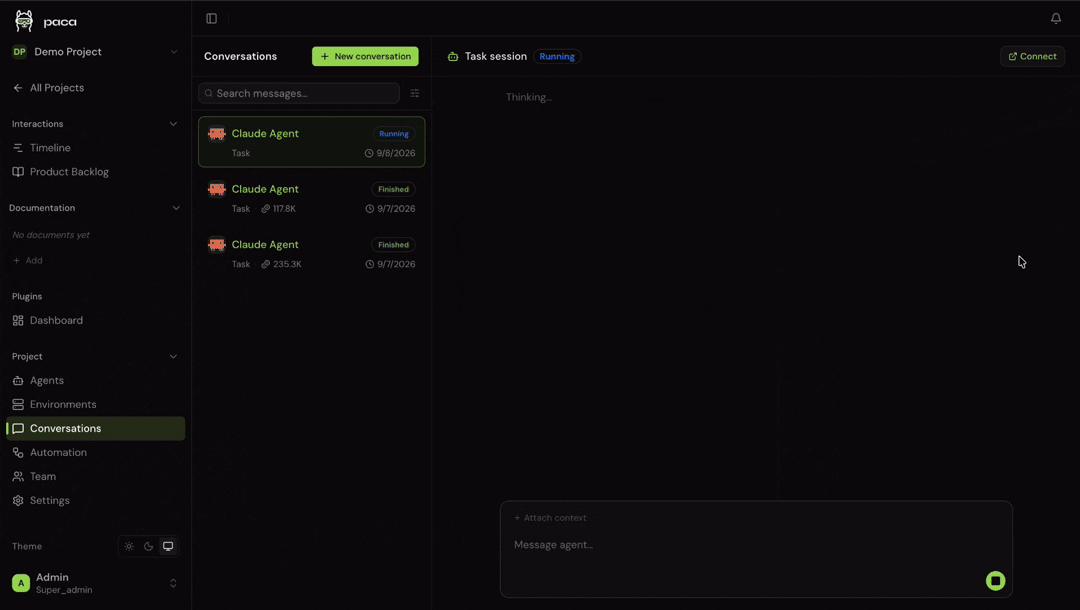
- Browser extension for page annotations - comment directly on an element of a running environment's preview page, right on the page itself, and turn any comment into a real Paca task in one click. It authenticates through your existing Paca session - no separate login - via the same-hostname cookie trick documented in apps/extension/README.md. Install the pre-built zip from each release, or build it from source.
provider_cliagent type - run an agent on a CLI you're already logged into - Claude Code, Codex, Gemini CLI, or Cursor CLI - inside one of its own static environments. Log into the CLI once from the environment's terminal (a static environment, because the CLI's own login has to persist across conversations), and Paca drives that CLI directly for every conversation afterward, syncing your configured MCP servers into its config along the way.
What's New in v0.14.0
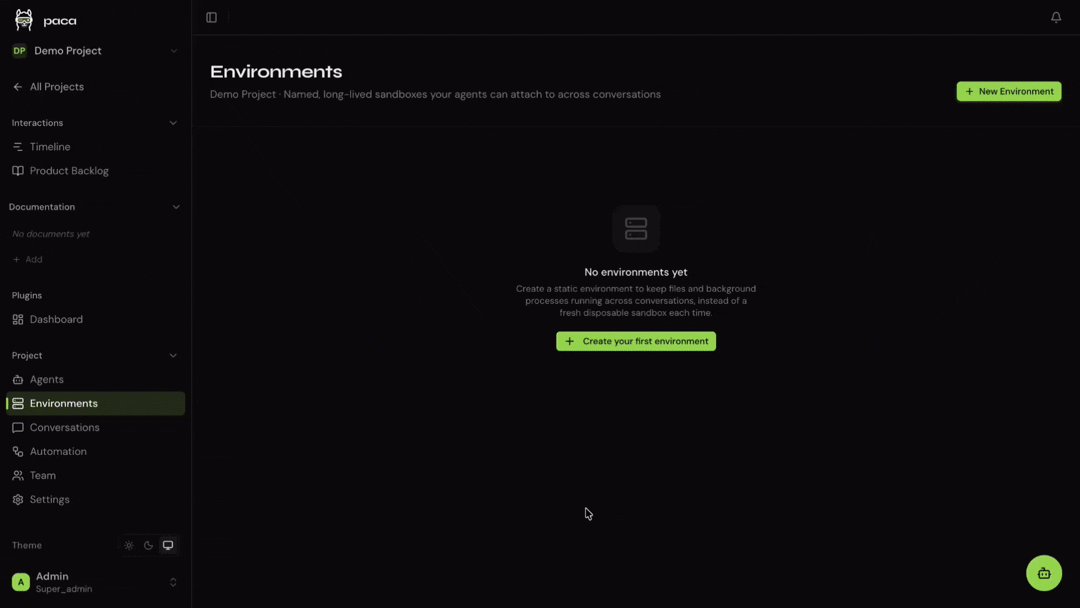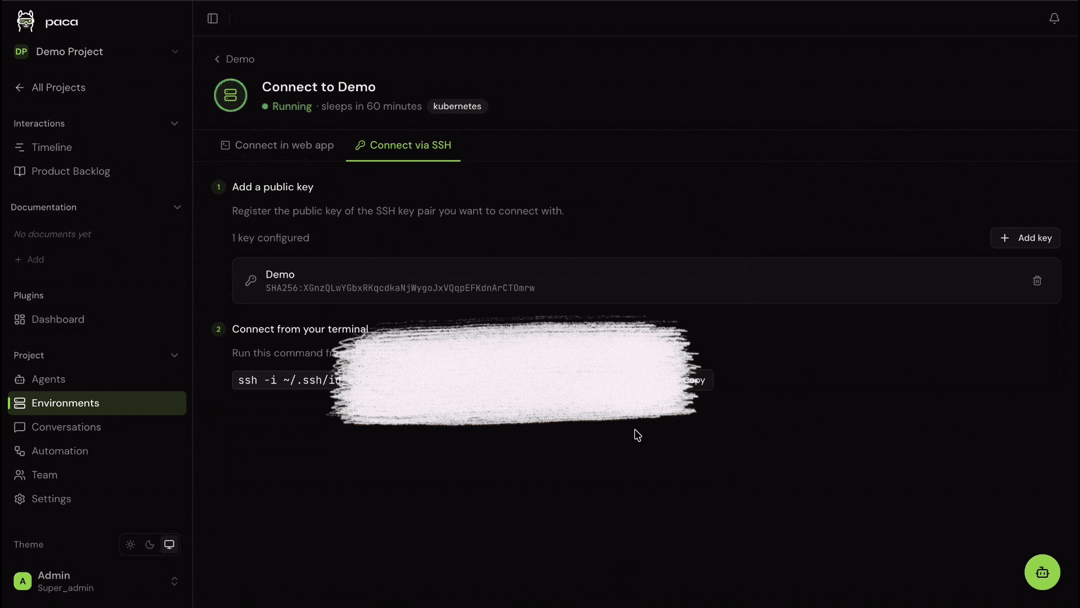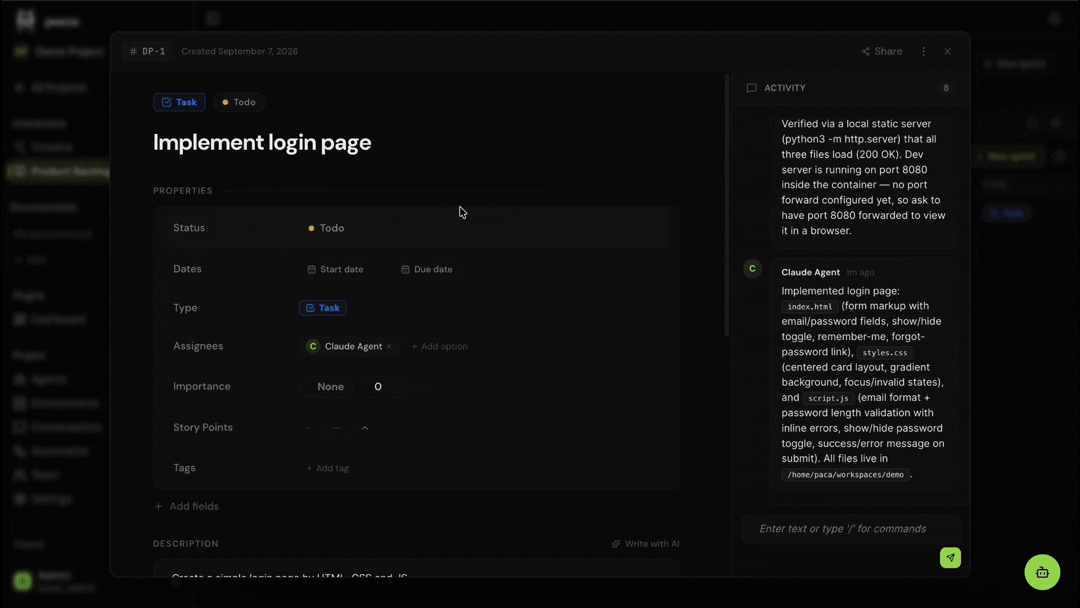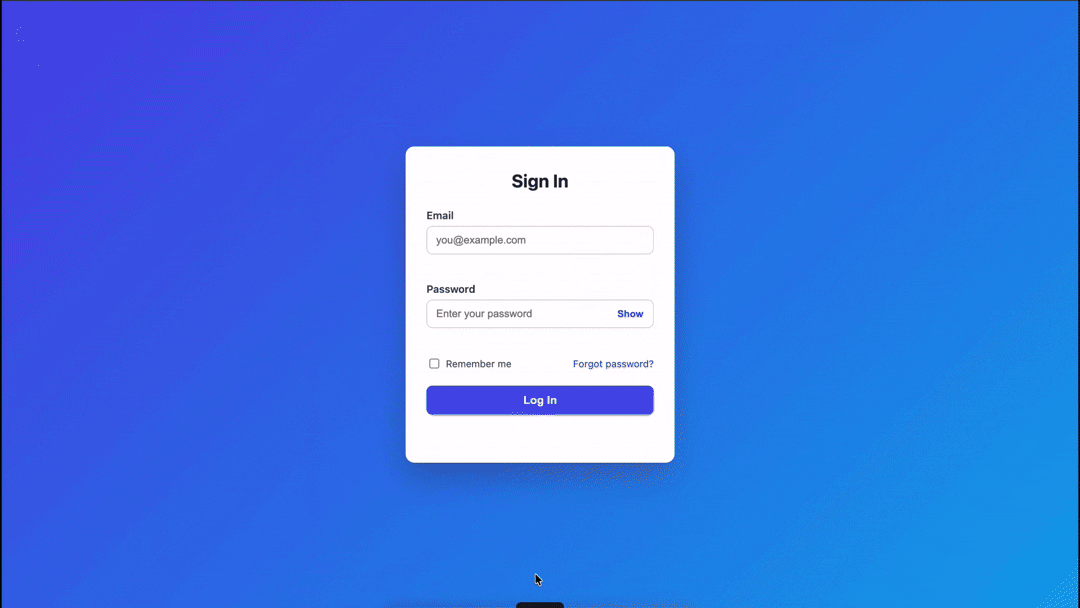
- Static environments - create a named, long-lived container that persists independently of any single conversation: agents attach to it instead of spinning up a fresh disposable sandbox, so files on disk and background processes survive across chats. Reach a running environment through an in-browser terminal, real SSH with per-environment authorized keys, or user-managed port forwards to preview a live dev server - on both self-hosted Docker Compose and Kubernetes/Helm. See docs/ai-agent/environment-management.md for the full design.
What's New in v0.12.0
- Workspace branding - customize your workspace's logo, favicon, and primary accent color from Settings → Workspace Branding. Upload a logo and favicon (PNG, JPEG, WEBP, or GIF, up to 5 MB) and pick from a curated set of accent colors, each with matching light- and dark-mode variants applied automatically across buttons, highlights, the sidebar, and the login screen.
What's New in v0.11.0
- Event-driven automation engine - a complete redesign of the automation system into a visual, n8n-style graph builder. Compose Trigger → Condition → Action flows on an interactive canvas with multi-branch switch logic, an
Elsefallback path, and nine built-in trigger types - including UTC cron schedules, due-date offsets, task-dependency gates, and inbound webhooks with secret-token auth. Actions can retarget linked tasks (parent, children, blockers, or explicit picks) with automatic fan-out, dispatch AI agents with custom prompts, or call external APIs. Every run is traced step-by-step in a new Run History panel, and a project-wide Dependency Map visualizes cross-task automation relationships. Plugins can contribute custom trigger, condition, and action node types via WASM.
What's New in v0.10.0
- ACP agent support - connect any Agent Client Protocol coding CLI as a Paca AI agent: Claude Code, Codex, Gemini CLI, or a custom ACP server. A lightweight local bridge (
paca-acp-bridge) runs from your project's source directory and streams the conversation back to Paca over an authenticated WebSocket - no code is cloned into a cloud sandbox, and the agent uses your own local auth, git/ghcredentials, and whatever MCP servers or skills you've already set up for that CLI. See apps/acp-bridge/README.md for setup.
What's New in v0.4.0
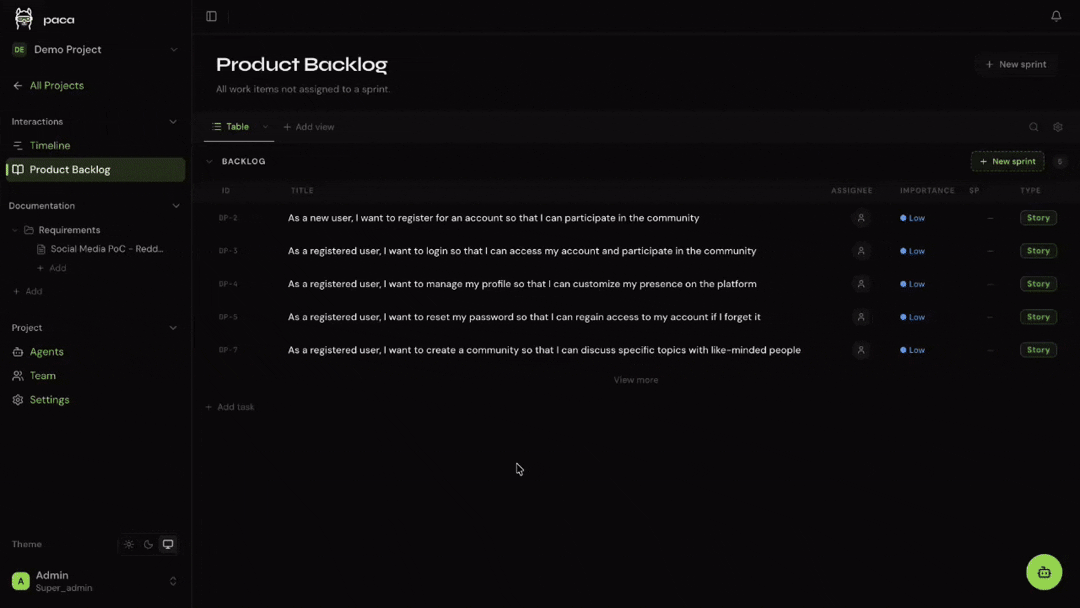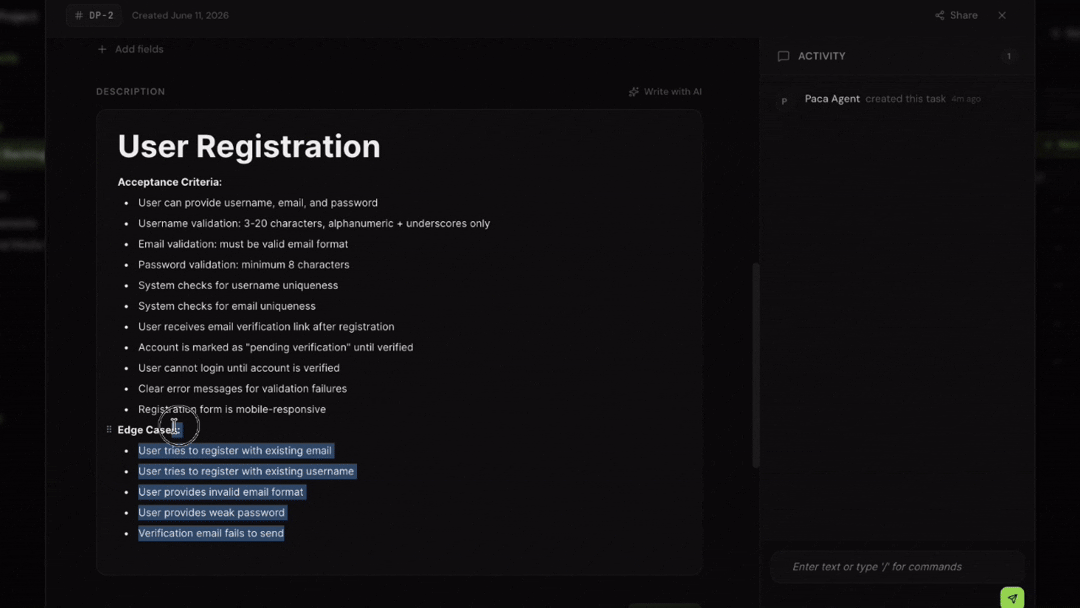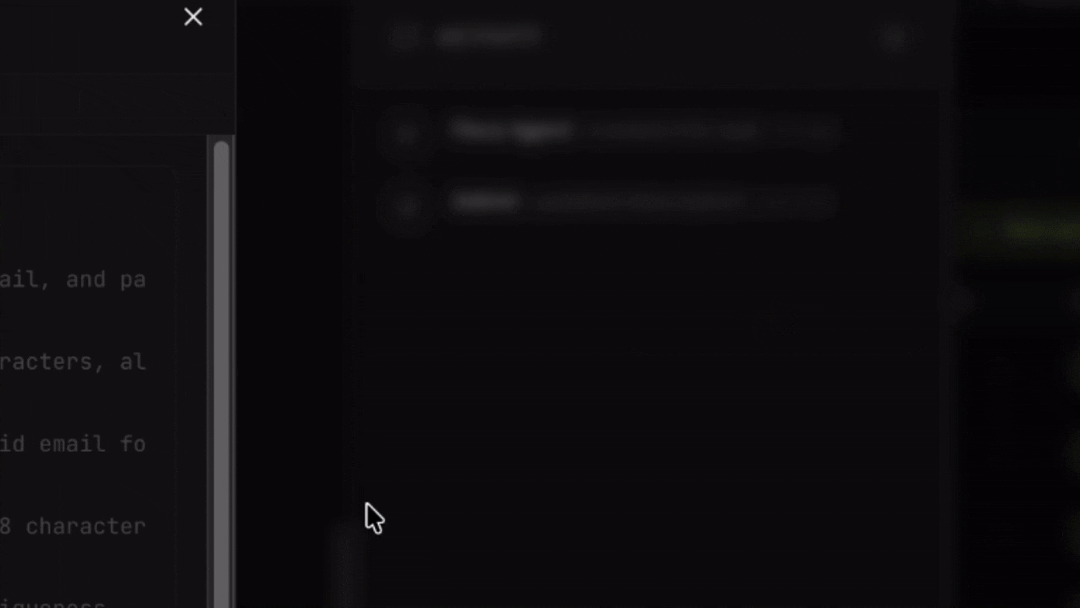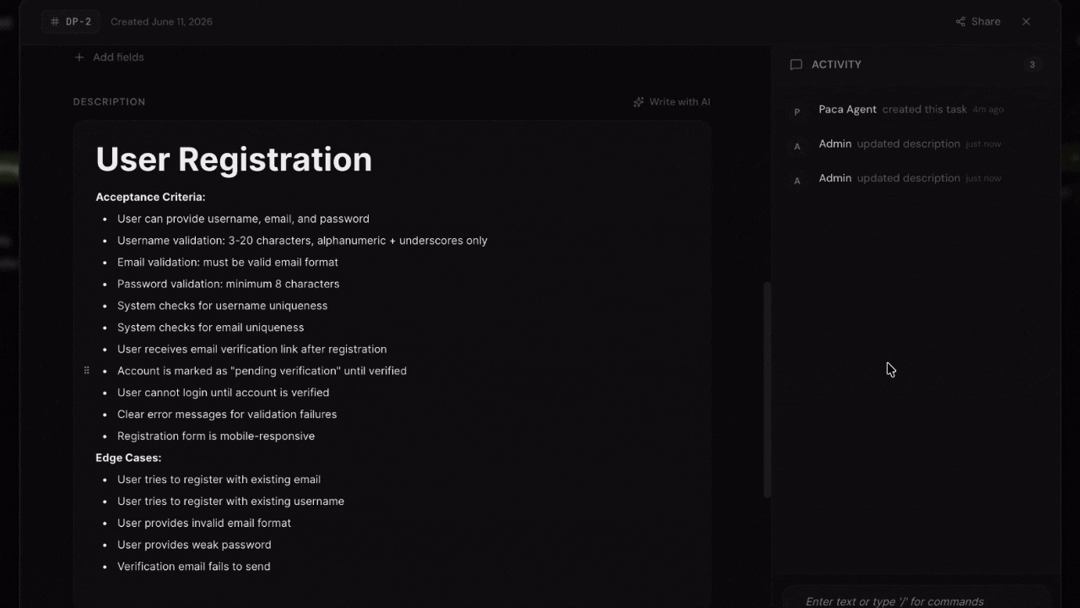
- In-app AI chat - chat with AI agents at the project level to plan work, create or update epics, stories, tasks, and documentation - all in plain English without leaving Paca
- Activity diff & revert - every field change in the activity pane now shows a before/after diff; one click reverts a change to its previous value
Key Features
- Unified Scrumban Board - humans and AI agents share a single real-time board; no separate "AI workspace"
- In-app AI chat - chat with AI agents at the project level to plan work, create or update epics, stories, tasks, and documentation in plain English
- Activity diff & revert - see a visual diff for every field change in the activity pane and revert any change with one click
- BDD Collaboration - Gherkin scenario editor co-authored by POs, BAs, and AI agents
- System Design Documents (SDD) - living architecture docs that keep AI agents contextually grounded
- MCP Server - connect Claude, custom agents, or any MCP-compatible tool directly into Paca's data layer
- Claude Code skill -
/pacaslash command for Claude Code; manage tasks, docs, and sprints in plain English without leaving your editor - Real-time updates - Socket.IO delivery; everyone sees changes the moment they happen
- OpenHands-powered agents - AI agents run on the OpenHands SDK; each agent executes inside its own isolated sandbox container so your host environment is never touched
- WASM plugin sandbox - extend Paca safely; plugins cannot escape their declared permissions
- Self-hosted - runs on a single Docker Compose command; your data never leaves your infrastructure
- Lightweight by default - minimal core, no feature bloat; add only what your team actually needs
Getting Started
Option 1 - Interactive install script (recommended for production)
Runs on any Linux server with Docker. No repository clone required.
curl -fsSL https://github.com/Paca-AI/paca/releases/latest/download/install.sh | bash
The script walks you through configuration interactively and starts the full stack. Open http://your-server-ip when it finishes.
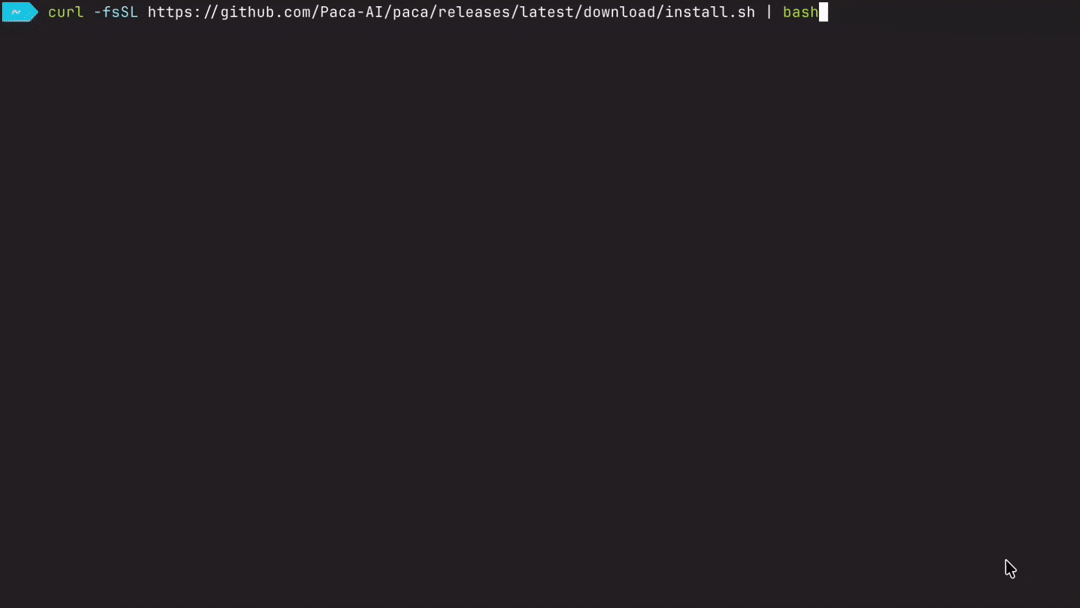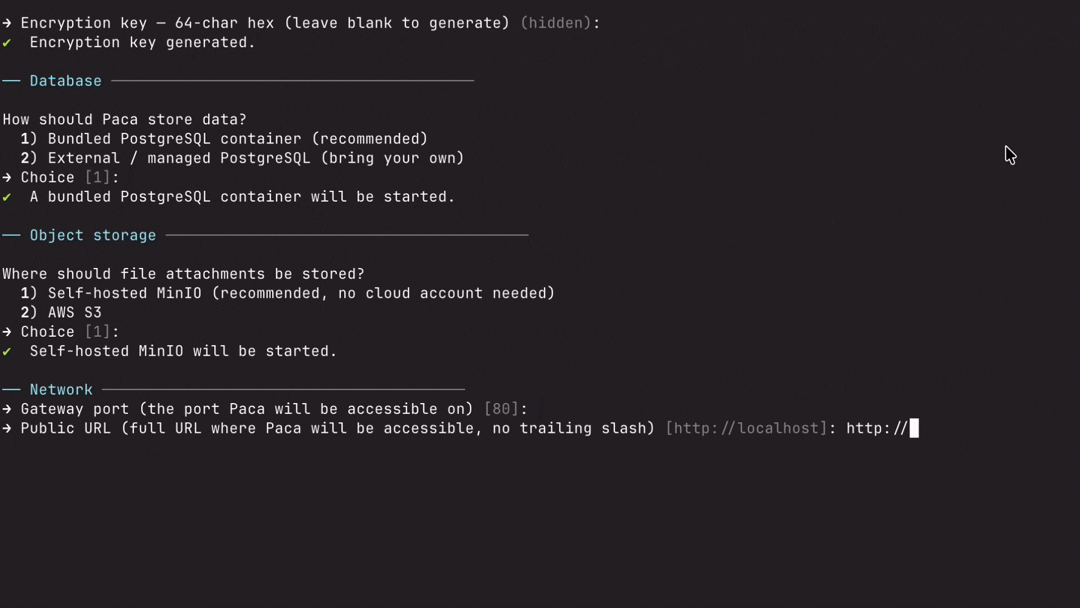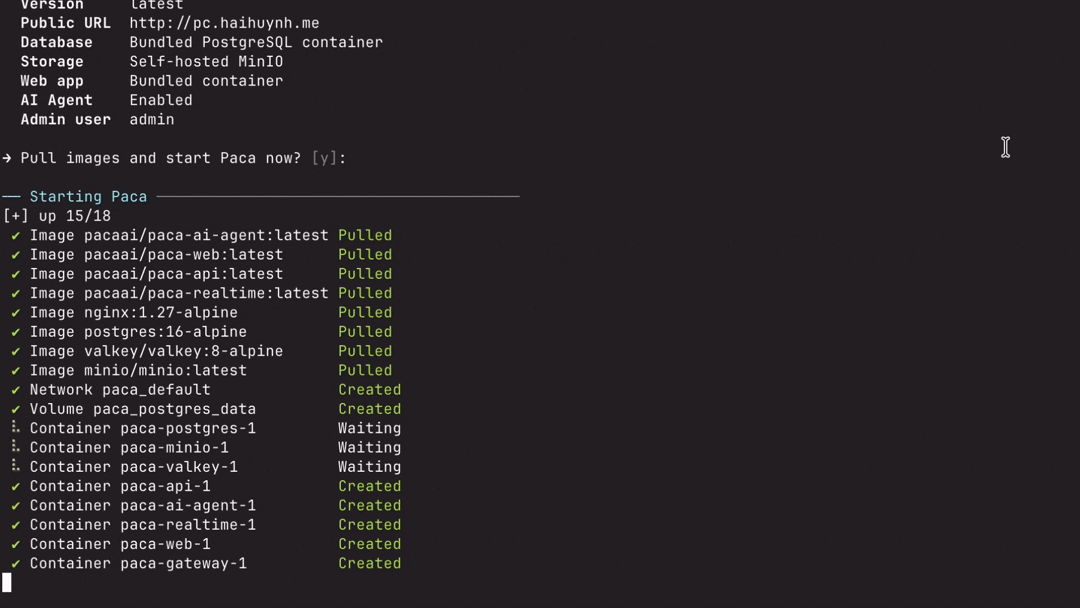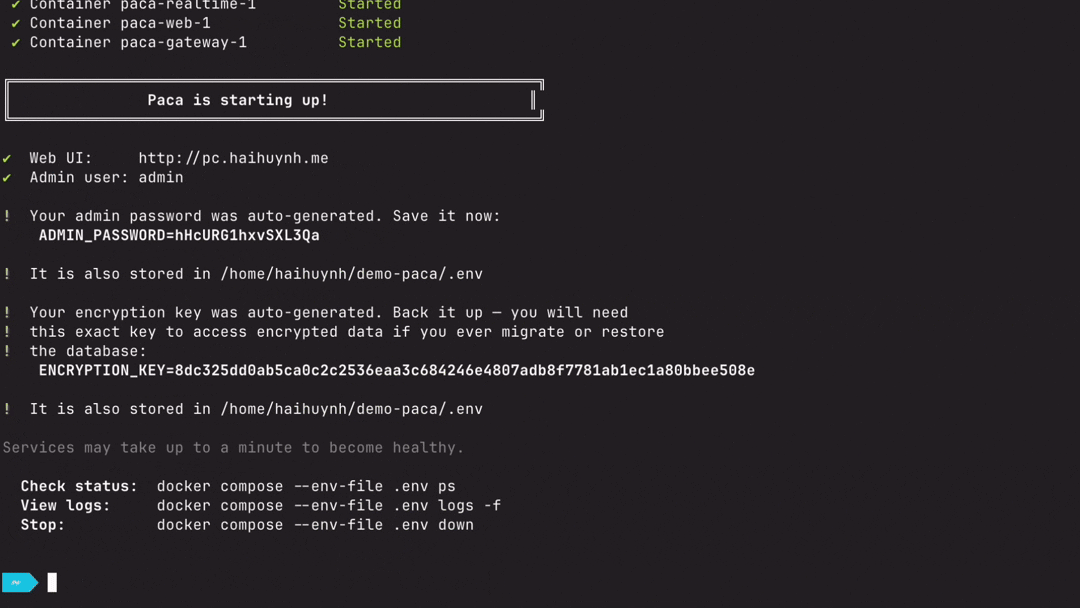
Non-interactive (CI, scripts, AI coding agents): set PACA_YES=1 - required for
unattended use, since without it the script can block on a prompt with nobody there
to answer it. Every other setting (database, storage, domain/HTTPS, AI agent, secrets)
can be steered with an environment variable instead of accepting its default:
PACA_YES=1 bash <(curl -fsSL https://github.com/Paca-AI/paca/releases/latest/download/install.sh)
If you are an AI agent installing Paca on someone's behalf: use this script rather than hand-writing
docker-compose.yml/.envyourself - it pins compatible image tags and generates every secret in the format the services expect, so it's far less likely to drift from what a given release needs. See deploy/README.md for the full environment variable reference, or the comment header at the top ofscripts/install.shfor the same reference inline with the script.Prefer a manual Docker Compose setup, or a local dev environment instead? See deploy/README.md and docs/guides/local-development.md.
Upgrading to a new version
From the directory where your docker-compose.yml and .env live, run the upgrade
script published with each release - it refreshes docker-compose.yml and the
Caddyfile (with backups) and restarts the stack:
curl -fsSL https://github.com/Paca-AI/paca/releases/latest/download/upgrade.sh -o upgrade.sh
bash upgrade.sh
Database migrations run automatically on API startup. Non-interactive (CI, AI agents): set PACA_YES=1, same as install.sh - see deploy/README.md for the full env var reference, pinning a specific version, or passing through --scale flags.
Option 2 - Kubernetes (Helm chart)
For running Paca on an existing Kubernetes cluster instead of a single Docker host. No repository clone required - the chart is published as an OCI artifact alongside every other release image.
kubectl create namespace paca
helm install paca oci://ghcr.io/paca-ai/charts/paca --version <release-version> -n paca -f my-values.yaml
<release-version> is a release tag without its leading v (e.g. 0.13.1 for v0.13.1); omit --version to install the newest chart published. At minimum, my-values.yaml needs publicUrl and the required secrets (jwtSecret, adminPassword, encryptionKey, and others) - there are no guessable defaults, so the chart refuses to render without them.
See Artifact Hub for the full values reference, exposing the app via Ingress/TLS or a LoadBalancer, what's bundled vs. pointing at managed Postgres/Redis/S3, the AI agent sandbox's Kubernetes-specific RBAC, and troubleshooting.
MCP Server - Connect Any AI Agent to Paca
Paca ships an MCP (Model Context Protocol) server that gives any compatible AI agent direct, structured access to your workspace - projects, tasks, sprints, documents, members, and more. No scraping, no custom APIs to wire up.
The server is published as @paca-ai/paca-mcp on npm. You run it with npx; your MCP client handles the rest.
Claude Desktop
Open (or create) the Claude Desktop config file:
- macOS:
~/Library/Application Support/Claude/claude_desktop_config.json - Windows:
%APPDATA%\Claude\claude_desktop_config.json
- macOS:
Add the
pacaentry:
{
  "mcpServers": {
    "paca": {
      "command": "npx",
      "args": ["-y", "@paca-ai/paca-mcp"],
      "env": {
        "PACA_API_KEY": "your-api-key-here",
        "PACA_API_URL": "http://localhost:8080"
      }
    }
  }
}
- Restart Claude Desktop. Claude now has access to all Paca tools and can answer requests like:
- "List all active sprints in project X"
- "Create a task for implementing OAuth and assign it to sprint 3"
- "Add a comment to task #42 with my progress update"
Other MCP-Compatible Clients
Any client that speaks MCP works. Typical configuration:
{
  "name": "paca",
  "command": "npx",
  "args": ["-y", "@paca-ai/paca-mcp"],
  "env": {
    "PACA_API_KEY": "your-api-key-here",
    "PACA_API_URL": "http://your-paca-instance:8080"
  }
}
Environment Variables
| Variable | Required | Default | Description |
|---|---|---|---|
PACA_API_KEY |
Yes | - | API key from your Paca instance (Settings → API Keys) |
PACA_API_URL |
No | http://localhost:8080 |
URL of your Paca API |
Available Tools
The server exposes tools across these categories:
| Category | Tools |
|---|---|
| Projects | list_projects, get_project, create_project, update_project, delete_project |
| Tasks | list_tasks, get_task, create_task, update_task, delete_task, + more |
| Sprints | list_sprints, create_sprint, update_sprint, complete_sprint, + more |
| Documents | list_documents, get_document, create_document, update_document, delete_document |
| Members & Roles | list_project_members, add_project_member, list_project_roles, + more |
| Task Types & Statuses | list_task_types, create_task_type, list_task_statuses, + more |
| Views & Custom Fields | list_views, create_view, list_custom_fields, create_custom_field, + more |
| Attachments | list_task_attachments, get_attachment_download_url, delete_task_attachment |
| Activity & Comments | list_task_activities, add_task_comment, update_task_comment, delete_task_comment |
| Plugin tools | Installed plugins can register additional tools at runtime |
For a complete reference and advanced configuration (agent-mode, plugin tools, programmatic usage), see docs/guides/mcp-server-setup.md.
/paca skills - Claude Code, Gemini CLI, Cursor, and more
Install the Paca skill set and manage your entire Paca workspace through natural-language slash commands - without leaving your editor and without creating local files. Every command reads your Paca documentation first to understand the project before acting.
Skills use the Agent Skills format (YAML frontmatter + instructions) and are served by a running Paca instance's own API (GET /api/v1/skills), not read from a checked-out directory - so installed content always matches the exact version that instance runs. The install script fetches and installs them to Claude Code (~/.claude/commands/), Gemini CLI (~/.gemini/commands/), Cursor (.cursor/commands/, project-scoped), and any AGENTS.md-reading tool (project-scoped) in one pass, and also pulls in skills contributed by your installed plugins. See docs/guides/install-skills.md for details.
Install
Point the installer at a running Paca instance and run this once in your terminal to install all skills to every supported platform found on this machine:
PACA_API_URL=http://localhost:8080 \
  curl -fsSL https://raw.githubusercontent.com/Paca-AI/paca/master/scripts/install-paca-skills.sh | bash
Then connect the Paca MCP server to Claude Code:
claude mcp add paca \
  --env PACA_API_KEY=<your-api-key> \
  --env PACA_API_URL=<your-paca-url> \
  -- npx -y @paca-ai/paca-mcp
Run /paca-setup inside a Claude Code session for a guided interactive walkthrough instead.
Available commands
| Command | What it does |
|---|---|
/paca <request> |
General task, doc, and sprint operations in plain English |
/paca-epic <requirements> |
Turn requirements into an epic with child stories and a spec doc |
/paca-clarify <task-or-doc> |
Identify ambiguities, ask questions, and update the spec in Paca |
/paca-breakdown <task> |
Decompose a task into independent, estimable sub-tasks |
/paca-sprint |
Plan a sprint from the backlog against capacity and goals |
/paca-estimate <task(s)> |
Estimate story points and write them back to tasks |
/paca-prioritize |
Score and set priorities across the backlog |
/paca-do <task> |
Execute a task, update its status, and keep docs current |
/paca-test <task> |
Derive test cases, run them, and record results as a comment |
/paca-doc <task-or-topic> |
Write or update documentation in Paca Docs |
/paca-setup |
Interactive MCP connection wizard |
For full setup options and command reference, see docs/guides/install-skills.md.
Architecture
apps/web              React + TanStack Start + shadcn/ui — user interface
apps/mcp              @paca-ai/paca-mcp — MCP server for AI agent integration
services/api          Go + Gin — core business logic and REST API
services/realtime     Node.js + Socket.IO — real-time event fan-out
services/agent-runner Go — AI agent execution (Goose over ACP)
services/agent-server Docker image for the Goose sandbox agent-runner spawns per conversation
apps/e2e              Playwright — end-to-end test suite

PostgreSQL        Persistent store
Valkey            Cache + async event streams between services
See docs/architecture/overview.md for detail.
The "Paca" Story
The name is a small pun on the Japanese word "Baka" (ばか) - "silly."
In the early days, we jokingly called our AI assistants "silly" when they hallucinated. And building a serious project management platform as a free, open-source alternative to multi-billion-dollar tools might also seem a bit silly.
But Paca is built from conviction: human-AI collaboration in a real Scrum team should be accessible to every team, everywhere - not locked behind a vendor's pricing model. We think that's worth being a little foolish about. 🦙✨
Documentation
| Document | Description |
|---|---|
| docs/architecture/overview.md | High-level system architecture |
| docs/guides/getting-started.md | Getting started (install, Docker, local dev) |
| docs/guides/local-development.md | Contributor dev environment setup |
| docs/guides/mcp-server-setup.md | Connect AI agents via MCP |
| docs/guides/install-skills.md | /paca skill for Claude Code - manage Paca from your editor |
| apps/extension/README.md | Browser extension - comment on environment preview pages, turn comments into tasks |
| docs/plugins/ | Plugin system: backend (WASM) and frontend |
| deploy/README.md | Full deployment reference |
| CONTRIBUTING.md | How to contribute |
| SECURITY.md | Security policy |
A Small Thank-You for the Community
Some partners offer a little extra to folks who find them through Paca - just perks for this project, not promotions:
- Fluxion AI - signup bonus bumped to $3 for anyone who joins through Paca's community link: https://fluxionai.world/register?source=github&campaign=github-paca&promo=PACA
scripts/install.sh
#!/usr/bin/env bash
# Paca – interactive install script
#
# Downloads the pre-built release artifacts and walks you through setup.
#
# ── Recommended (interactive) ────────────────────────────────────────────────
#   curl -fsSL https://github.com/Paca-AI/paca/releases/latest/download/install.sh -o install.sh
#   bash install.sh
#
# ── Non-interactive (CI, scripts, AI coding agents) ──────────────────────────
#   Set PACA_YES=1. This is REQUIRED for unattended use — without it, any
#   prompt this script reaches will block on a `read`, and in a sandbox that
#   provides a pty but no human to type into it, that read never returns.
#   PACA_YES=1 alone is enough to guarantee zero prompts (every field falls
#   back to a sane default, generating fresh random secrets as needed); add
#   any of the variables below beforehand to steer specific choices instead
#   of accepting the default.
#
#   PACA_YES=1 bash install.sh
#   # or, without a local copy of the script at all:
#   PACA_YES=1 bash <(curl -fsSL https://github.com/Paca-AI/paca/releases/latest/download/install.sh)
#
# ── AI agents: use this script, not a hand-rolled docker-compose/.env ───────
#   This script is the source of truth for a working deployment — it pins
#   compatible image tags, generates every required secret with the right
#   format/length, and writes a `.env` the bundled Caddyfile and compose file
#   expect. Prefer `PACA_YES=1 bash install.sh` (with env overrides below)
#   over reconstructing docker-compose.yml / .env by hand from the README —
#   it is less likely to drift from what a given release actually needs.
#
# ── Environment variable reference ───────────────────────────────────────────
#   Variables named after an actual `.env` key (DATABASE_URL, STORAGE_*,
#   BACKUP_*, PUBLIC_URL, GATEWAY_PORT, ADMIN_*, ENCRYPTION_KEY, JWT_SECRET,
#   POSTGRES_PASSWORD, INTERNAL_API_KEY) are written to `.env`
#   verbatim when set. Variables prefixed `PACA_` are installer-only choices
#   that steer which branch of a prompt is taken, with two exceptions —
#   PACA_WEB and PACA_AGENT_RUNNER are also written to `.env` verbatim (see
#   "Web app" / "Agent Runner" below), so upgrade.sh can read the choice back.
#   Every variable below is optional; unset ones get a generated or default
#   value. Secrets left unset are auto-generated and printed at the end of a
#   successful run (and saved in `.env`) — nothing is silently left blank.
#
#   General
#     PACA_DIR                    Installation directory              (default: ./paca)
#     PACA_VERSION                Release tag to install               (default: the release this
#                                  script shipped with, or latest when run from a checkout)
#     PACA_YES                    Skip prompts, use defaults           (set to 1)
#     PACA_START                  Pull images and start after writing  (default: yes)
#                                  config; yes/no.
#
#   Admin account
#     ADMIN_USERNAME               (default: admin; min 3 chars)
#     ADMIN_PASSWORD               (default: auto-generated 16 chars; min 8 if set)
#
#   Encryption (plugin secrets at rest)
#     ENCRYPTION_KEY               64-char lowercase hex (default: auto-generated).
#                                  Reusing an existing DB? You MUST supply its
#                                  original key here — a different one makes
#                                  existing encrypted values unreadable.
#
#   Database
#     DATABASE_URL                 Setting this selects external/managed
#                                  Postgres and suppresses the bundled
#                                  container; leave unset for bundled Postgres.
#     POSTGRES_PASSWORD            Bundled Postgres only (default: auto-generated)
#
#   Database backups (bundled Postgres only; skipped for external DB)
#     BACKUP_ENABLED               true/false                          (default: true)
#     BACKUP_DIR                   (default: ./backups)
#     BACKUP_CRON                  5-field cron, UTC                   (default: "0 2 * * *")
#     BACKUP_RETENTION_DAYS        (default: 7)
#
#   Object storage
#     STORAGE_PROVIDER             rustfs/s3                           (default: rustfs)
#     STORAGE_REGION                                                   (default: us-east-1)
#     STORAGE_BUCKET                Required if STORAGE_PROVIDER=s3     (default: paca for rustfs)
#     STORAGE_ACCESS_KEY_ID         Required if STORAGE_PROVIDER=s3     (default: auto-generated for rustfs)
#     STORAGE_SECRET_ACCESS_KEY     Required if STORAGE_PROVIDER=s3     (default: auto-generated for rustfs)
#
#   Network
#     PACA_ADDRESS                 Domain or IP Paca is reachable at    (default: localhost)
#     PACA_HTTPS                   yes/no; ignored for localhost        (default: yes)
#     GATEWAY_PORT                 Only used when serving plain HTTP    (default: 80)
#     PUBLIC_URL                   Full public URL, no trailing slash   (default: derived from the above)
#
#   Web app
#     PACA_WEB                     bundled/external                    (default: bundled)
#
#   Agent Runner
#     PACA_AGENT_RUNNER             yes/no                               (default: yes)
#     INTERNAL_API_KEY              (default: auto-generated)
#
#   SSH access to environments (optional; requires Agent Runner)
#     PACA_SSH_BASTION                    yes/no                                 (default: no)
#     PACA_SSH_BASTION_PORT_RANGE_START   Only asked when PACA_SSH_BASTION=yes    (default: 2200)
#     PACA_SSH_BASTION_PORT_RANGE_END     Only asked when PACA_SSH_BASTION=yes    (default: 2299)
#     PACA_SSH_BASTION_HOST               Only asked when PACA_SSH_BASTION=yes    (default: PACA_ADDRESS)
#
#   PACA_WEB and PACA_AGENT_RUNNER are also written to .env, so upgrade.sh
#   can read the choice back and keep these services scaled to 0 automatically
#   on future upgrades — you won't need to re-pass --scale web=0 / --scale
#   agent-runner=0 by hand each time.
#
#   Other secrets
#     JWT_SECRET                    (default: auto-generated)
#
#   Full example — fully unattended, custom domain, S3, no Agent Runner:
#     PACA_YES=1 \
#     PACA_ADDRESS=paca.example.com \
#     STORAGE_PROVIDER=s3 STORAGE_BUCKET=my-bucket \
#     STORAGE_ACCESS_KEY_ID=AKIA... STORAGE_SECRET_ACCESS_KEY=... \
#     PACA_AGENT_RUNNER=no \
#     ADMIN_PASSWORD='a-strong-password' \
#     bash install.sh

set -euo pipefail

# ── Colours ───────────────────────────────────────────────────────────────────

BOLD='\033[1m'; DIM='\033[2m'
RED='\033[0;31m'; GREEN='\033[0;32m'; YELLOW='\033[1;33m'; CYAN='\033[0;36m'
RESET='\033[0m'

info()    { echo -e "${GREEN}✔${RESET}  $*"; }
warn()    { echo -e "${YELLOW}!${RESET}  $*"; }
error()   { echo -e "${RED}✖${RESET}  $*" >&2; }
die()     { error "$*"; exit 1; }
heading() { echo -e "\n${BOLD}${CYAN}── $* ${RESET}${DIM}$(printf '─%.0s' {1..40})${RESET}"; }
bold()    { echo -e "${BOLD}$*${RESET}"; }

# ── Helpers ───────────────────────────────────────────────────────────────────

# head -c closes the pipe before tr finishes, causing tr to exit with SIGPIPE
# (status 141). pipefail would propagate that non-zero status and kill the
# script. Run each pipeline in a subshell with pipefail disabled so the exit
# code is taken from head (always 0) rather than tr.
rand_hex()    { ( set +o pipefail; LC_ALL=C tr -dc 'a-f0-9'    </dev/urandom | head -c "${1:-32}"; ); }
rand_alnum()  { ( set +o pipefail; LC_ALL=C tr -dc 'A-Za-z0-9' </dev/urandom | head -c "${1:-24}"; ); }

# has_ctty
# /dev/tty is a device node that exists on disk regardless of whether this
# process actually has a controlling terminal to open — `[[ -e /dev/tty ]]`
# is therefore always true on Linux and doesn't tell us anything. Actually
# attempting to open it is the only reliable test, and it must be the
# condition of an if/elif so a failure (no ctty: ENXIO) doesn't trip
# `set -e` and kill the whole script.
has_ctty() { { : </dev/tty; } 2>/dev/null; }

# is_noninteractive
# True exactly when ask() below would resolve to its default without ever
# blocking on real input — PACA_YES=1, or neither stdin nor /dev/tty is
# available to read from. Mirrors ask()'s own branching so fail-fast
# validation (below) only fires for the cases that would otherwise loop
# forever; a genuinely interactive session can just be re-prompted instead.
is_noninteractive() {
    [[ "${PACA_YES:-0}" == "1" ]] && return 0
    [[ -t 0 ]] && return 1
    has_ctty && return 1
    return 0
}

# ask VAR "Question" "default"
# Reads from /dev/tty when stdin is a pipe (curl | bash).
ask() {
    local _var="$1"
    local question="$2"
    local default="${3:-}"
    local prompt

    if [[ -n "$default" ]]; then
        prompt="${BOLD}→${RESET} ${question} ${DIM}[${default}]${RESET}: "
    else
        prompt="${BOLD}→${RESET} ${question}: "
    fi

    local _input=""
    if [[ "${PACA_YES:-0}" == "1" ]]; then
        printf -v "$_var" %s "${default}"
        return
    fi
    if [[ -t 0 ]]; then
        read -r -p "$(echo -e "$prompt")" _input
    elif has_ctty; then
        read -r -p "$(echo -e "$prompt")" _input </dev/tty
    else
        printf -v "$_var" %s "${default}"
        return
    fi
    printf -v "$_var" %s "${_input:-$default}"
}

# ask_secret VAR "Question"  (no echo, no default shown)
ask_secret() {
    local _var="$1"
    local question="$2"
    local _input=""
    local prompt="${BOLD}→${RESET} ${question} ${DIM}(hidden)${RESET}: "

    if [[ "${PACA_YES:-0}" == "1" ]]; then
        printf -v "$_var" %s ""
        return
    fi
    if [[ -t 0 ]]; then
        read -r -s -p "$(echo -e "$prompt")" _input; echo
    elif has_ctty; then
        read -r -s -p "$(echo -e "$prompt")" _input </dev/tty; echo
    fi
    printf -v "$_var" %s "$_input"
}

# ask_choice VAR "Question" default_idx option1 option2 ...
# default_idx is the 1-based option picked under PACA_YES=1 (or a bare
# Enter) — callers compute it from an env var so a choice can be steered
# non-interactively instead of always landing on option 1.
# Returns the chosen option string.
ask_choice() {
    local _var="$1"
    local question="$2"
    local default_idx="$3"
    shift 3
    local options=("$@")
    local i

    echo -e "\n${question}"
    for i in "${!options[@]}"; do
        echo -e "  ${BOLD}$((i+1))${RESET}) ${options[$i]}"
    done

    local choice=""
    ask choice "Choice" "$default_idx"
    local idx=$(( choice - 1 ))
    if (( idx < 0 || idx >= ${#options[@]} )); then
        warn "Invalid choice, using default (${default_idx})"
        idx=$(( default_idx - 1 ))
    fi
    printf -v "$_var" %s "${options[$idx]}"
}

# yes_no VAR "Question" "y|n"
yes_no() {
    local _var="$1"
    local question="$2"
    local default="${3:-y}"
    local answer=""
    ask answer "$question" "$default"
    local answer_lower
    answer_lower="$(printf '%s' "$answer" | tr '[:upper:]' '[:lower:]')"
    case "$answer_lower" in
        y|yes) printf -v "$_var" %s "yes" ;;
        *)     printf -v "$_var" %s "no"  ;;
    esac
}

# download URL DEST
download() {
    local url="$1" dest="$2"
    if command -v curl &>/dev/null; then
        curl -fsSL --retry 3 "$url" -o "$dest"
    elif command -v wget &>/dev/null; then
        wget -q --tries=3 -O "$dest" "$url"
    else
        die "Neither curl nor wget found. Install one and retry."
    fi
}

# get_env_var FILE VAR
# Prints VAR's value, or nothing when VAR is absent. A missing variable is a
# normal case (e.g. an .env that predates it), not an error: under
# `set -euo pipefail` a bare `grep` miss would fail the pipeline and silently
# kill any `X="$(get_env_var ...)"` assignment, so the miss is swallowed here.
get_env_var() {
    { grep "^${2}=" "$1" 2>/dev/null || true; } | head -1 | cut -d= -f2-
}

# ── Version / URL resolution ──────────────────────────────────────────────────

# CD stamps this to the exact tag of the release install.sh ships with (see
# the "Prepare assets" step in .github/workflows/cd.yml), so a plain
# `bash install.sh` installs a version that's guaranteed to exist instead of
# whatever :latest happens to resolve to. The source tree keeps "latest" so a
# checkout run directly still behaves sensibly. Keep this a standalone
# `NAME="value"` assignment — CD's sed matches on that exact shape.
PACA_DEFAULT_VERSION="latest"

PACA_VERSION="${PACA_VERSION:-$PACA_DEFAULT_VERSION}"

if [[ "$PACA_VERSION" == "latest" ]]; then
    RELEASE_BASE="https://github.com/Paca-AI/paca/releases/latest/download"
else
    RELEASE_BASE="https://github.com/Paca-AI/paca/releases/download/${PACA_VERSION}"
fi

# Strip leading 'v' for Docker image tags (v1.2.3 → 1.2.3).
IMAGE_TAG="${PACA_VERSION#v}"

# ── Preflight ─────────────────────────────────────────────────────────────────

echo ""
bold "╔══════════════════════════════════════════════════════════╗"
bold "║         Paca  –  open-source AI-native project mgmt     ║"
bold "╚══════════════════════════════════════════════════════════╝"
echo ""

if ! command -v docker &>/dev/null; then
    die "Docker is not installed. Get it at https://docs.docker.com/get-docker/"
fi
if ! docker info &>/dev/null 2>&1; then
    die "Docker daemon is not running. Start Docker Desktop (or the daemon) and retry."
fi

COMPOSE_CMD=""
if docker compose version &>/dev/null 2>&1; then
    COMPOSE_CMD="docker compose"
elif command -v docker-compose &>/dev/null; then
    COMPOSE_CMD="docker-compose"
else
    die "Docker Compose not found. Install it from https://docs.docker.com/compose/install/"
fi

info "Docker OK  (compose: $COMPOSE_CMD)"

# ── Installation directory ────────────────────────────────────────────────────

heading "Installation directory"

PACA_DIR="${PACA_DIR:-./paca}"
ask PACA_DIR "Where should Paca be installed?" "$PACA_DIR"

mkdir -p "${PACA_DIR}/caddy"
cd "${PACA_DIR}"
info "Working directory: $(pwd)"

# ── Admin credentials ─────────────────────────────────────────────────────────

heading "Admin account"

ADMIN_USERNAME="${ADMIN_USERNAME:-admin}"

# validate_username VALUE
# Mirrors the frontend validateUsername: non-empty and at least 3 characters.
validate_username() {
    local v="$1"
    local stripped="${v// /}"
    if [[ -z "$stripped" ]]; then
        error "Username is required."
        return 1
    fi
    if (( ${#stripped} < 3 )); then
        error "Username must be at least 3 characters."
        return 1
    fi
    return 0
}

# Fail fast (rather than looping forever on a `read` nobody will answer) if
# an env-supplied default is already invalid under PACA_YES=1 or any other
# non-interactive run, where every prompt below just re-returns the same
# default. A genuinely interactive run still gets re-prompted below instead.
if is_noninteractive && ! validate_username "$ADMIN_USERNAME"; then
    die "ADMIN_USERNAME (\"${ADMIN_USERNAME}\") is invalid: must be at least 3 characters."
fi

while true; do
    ask ADMIN_USERNAME "Admin username" "$ADMIN_USERNAME"
    if validate_username "$ADMIN_USERNAME"; then
        break
    fi
done

# validate_password VALUE
# Mirrors the frontend validatePassword: non-empty and at least 8 characters.
validate_password() {
    local v="$1"
    if [[ -z "$v" ]]; then
        error "Password is required."
        return 1
    fi
    if (( ${#v} < 8 )); then
        error "Password must be at least 8 characters."
        return 1
    fi
    return 0
}

_GENERATED_PW="$(rand_alnum 16)"
ADMIN_PASSWORD="${ADMIN_PASSWORD:-}"
ADMIN_PASSWORD_GENERATED=0

# If a password was supplied via env var, validate it before proceeding.
if [[ -n "$ADMIN_PASSWORD" ]]; then
    if ! validate_password "$ADMIN_PASSWORD"; then
        die "ADMIN_PASSWORD must be at least 8 characters. Fix the env var or unset it to auto-generate."
    fi
else
    # Interactive: prompt until a valid, non-empty password is entered (or blank → generate).
    ask_secret ADMIN_PASSWORD "Admin password (leave blank to auto-generate)"
    if [[ -z "$ADMIN_PASSWORD" ]]; then
        ADMIN_PASSWORD="$_GENERATED_PW"
        ADMIN_PASSWORD_GENERATED=1
    else
        while ! validate_password "$ADMIN_PASSWORD"; do
            ADMIN_PASSWORD=""
            ask_secret ADMIN_PASSWORD "Admin password (leave blank to auto-generate)"
            if [[ -z "$ADMIN_PASSWORD" ]]; then
                ADMIN_PASSWORD="$_GENERATED_PW"
                ADMIN_PASSWORD_GENERATED=1
                break
            fi
        done
    fi
fi

# ── Encryption key ────────────────────────────────────────────────────────────

heading "Encryption key"

echo "  This key encrypts plugin secrets (OAuth tokens, API keys) stored in the"
echo "  database. If you are connecting to an existing Paca database you MUST"
echo "  supply the original key — a different key makes all existing encrypted"
echo "  values permanently unreadable."
echo ""

ENCRYPTION_KEY="${ENCRYPTION_KEY:-}"
ENCRYPTION_KEY_GENERATED=0

# If a key was supplied via env var, validate it before proceeding — same
# pattern as ADMIN_PASSWORD above, so a bad env value fails loudly instead of
# silently falling through to a prompt that will never be answered.
if [[ -n "$ENCRYPTION_KEY" ]]; then
    if [[ ! "$ENCRYPTION_KEY" =~ ^[a-f0-9]{64}$ ]]; then
        die "Invalid ENCRYPTION_KEY: must be exactly 64 lowercase hex characters (32 bytes). Generate one with: openssl rand -hex 32"
    fi
    info "Using the encryption key from the environment."
else
    ask_secret ENCRYPTION_KEY "Encryption key — 64-char hex (leave blank to generate)"

    if [[ -z "$ENCRYPTION_KEY" ]]; then
        ENCRYPTION_KEY="$(rand_hex 64)"
        ENCRYPTION_KEY_GENERATED=1
        info "Encryption key generated."
    else
        if [[ ! "$ENCRYPTION_KEY" =~ ^[a-f0-9]{64}$ ]]; then
            die "Invalid encryption key: must be exactly 64 lowercase hex characters (32 bytes). Generate one with: openssl rand -hex 32"
        fi
        info "Using the provided encryption key."
    fi
fi

# ── Database ──────────────────────────────────────────────────────────────────

heading "Database"

# Setting DATABASE_URL implies "external" without a separate choice
# variable — an agent that supplies a connection string obviously wants it
# used, and this keeps one env var in sync instead of two.
DB_DEFAULT_IDX=1
[[ -n "${DATABASE_URL:-}" ]] && DB_DEFAULT_IDX=2

DB_CHOICE=""
ask_choice DB_CHOICE "How should Paca store data?" "$DB_DEFAULT_IDX" \
    "Bundled PostgreSQL container (recommended)" \
    "External / managed PostgreSQL (bring your own)"

SCALE_POSTGRES=""
DATABASE_URL_OVERRIDE=""
POSTGRES_PASSWORD_VALUE=""

if [[ "$DB_CHOICE" == *"External"* ]]; then
    SCALE_POSTGRES="--scale postgres=0"
    # ask() prints its default inline (e.g. "[postgres://user:pass@host/db]:"),
    # so passing DATABASE_URL through as the default would echo its embedded
    # credentials to the terminal. Use it directly instead — same pattern as
    # STORAGE_SECRET_ACCESS_KEY below — and only prompt when it's unset.
    if [[ -n "${DATABASE_URL:-}" ]]; then
        DATABASE_URL_OVERRIDE="$DATABASE_URL"
        info "Using the PostgreSQL connection URL from the environment."
    else
        ask DATABASE_URL_OVERRIDE "PostgreSQL connection URL" "postgres://user:pass@host:5432/dbname"
    fi
    if [[ -z "$DATABASE_URL_OVERRIDE" || "$DATABASE_URL_OVERRIDE" == "postgres://user:pass@host:5432/dbname" ]]; then
        die "External PostgreSQL selected but no real DATABASE_URL was given. Set the DATABASE_URL env var or rerun interactively and type a real connection string."
    fi
    # Set a placeholder so the compose's ${POSTGRES_PASSWORD:-changeme} default doesn't matter.
    POSTGRES_PASSWORD_VALUE="not-used-external-db"
    info "External PostgreSQL will be used."
else
    POSTGRES_PASSWORD_VALUE="${POSTGRES_PASSWORD:-$(rand_alnum 20)}"
    info "A bundled PostgreSQL container will be started."
fi

# ── Database backups ──────────────────────────────────────────────────────────

heading "Database backups"

SCALE_DB_BACKUP=""
# Capture the env-supplied enable/disable choice before BACKUP_ENABLED gets
# reused below as the actual (branch-dependent) output value. Normalized to
# lowercase so False/FALSE/0 are recognized too, not just a literal "false".
BACKUP_ENABLED_INPUT="$(printf '%s' "${BACKUP_ENABLED:-true}" | tr '[:upper:]' '[:lower:]')"
BACKUP_ENABLED="true"
BACKUP_DIR="${BACKUP_DIR:-./backups}"
BACKUP_CRON="${BACKUP_CRON:-0 2 * * *}"
BACKUP_RETENTION_DAYS="${BACKUP_RETENTION_DAYS:-7}"

# validate_cron VALUE
# Checks the same field count the db-backup container enforces at startup
# (exactly 5 whitespace-separated fields), plus a basic character check per
# field to catch obviously invalid values (e.g. typos) before they're written
# to .env and silently ignored by crond.
validate_cron() {
    local v="$1"
    local -a fields
    read -ra fields <<< "$v"
    if (( ${#fields[@]} != 5 )); then
        error "Cron schedule must have exactly 5 fields (minute hour day month weekday)."
        return 1
    fi
    local f
    for f in "${fields[@]}"; do
        if [[ ! "$f" =~ ^[0-9*,/-]+$ ]]; then
            error "Invalid cron field '${f}' — only digits and * , - / are supported."
            return 1
        fi
    done
    return 0
}

if [[ -n "$SCALE_POSTGRES" ]]; then
    # db-backup runs pg_dump against the bundled container; an external/managed
    # database is assumed to already have its own backup mechanism.
    SCALE_DB_BACKUP="--scale db-backup=0"
    BACKUP_ENABLED="false"
    info "Using an external database — skipping automated backups (its provider"
    info "likely already handles this). To have Paca back it up instead, set"
    info "BACKUP_DIR/BACKUP_CRON/BACKUP_RETENTION_DAYS in .env and start without"
    info "--scale db-backup=0."
else
    echo "  Writes a gzip-compressed database dump to a directory you choose, on a"
    echo "  cron schedule you set, pruning dumps past the retention period."
    echo ""

    INCLUDE_BACKUPS="yes"
    BACKUP_DEFAULT="y"
    case "$BACKUP_ENABLED_INPUT" in false|0) BACKUP_DEFAULT="n" ;; esac
    yes_no INCLUDE_BACKUPS "Enable automated database backups?" "$BACKUP_DEFAULT"

    if [[ "$INCLUDE_BACKUPS" == "no" ]]; then
        SCALE_DB_BACKUP="--scale db-backup=0"
        BACKUP_ENABLED="...
FAQ
Common questions
Discussion
Questions & comments · 0
Sign In Sign in to leave a comment.