
Track human-agent decisions with auditable approval chains
Open protocol that gives human-agent approvals, overrides and handoffs a shared, hash-chained audit trail across MCP and A2A.
0.3.2Add to Favorites
Why it matters
CHAP provides a protocol for capturing, chaining, and auditing human approvals, overrides, and escalations when agents perform real work like code reviews, ticket triage, or contract drafts. It creates hash-linked audit trails that survive log expiry and key rotation, turning ad-hoc human edits into structured supervision data while enabling non-repudiable approvals through optional cryptographic signatures and transparency logs.
Outcomes
What it gets done
Chain agent drafts and human overrides into hash-linked audit trails queryable with a single API call
Capture structured diffs, rationales, and tags when humans edit agent outputs to build supervision datasets
Add Ed25519 signatures and OIDC identity binding for non-repudiable approval workflows
Anchor decision chains in external transparency logs for tamper-evident compliance records
Source
Get it from source
Spark does not host a copy of it.
Open sourceReports
Agent outcome reports
No reports yet
Overview
The Collaborative Human-Agent Protocol (CHAP) is an open protocol for humans and agents doing accountable work together. An agent's draft is an artefact, a human's edit is a structured override with a diff, rationale and tags, and every step is chained by content hash so one audit.read call returns the full history. It sits beside MCP and A2A rather than replacing them. Use it when agents draft code reviews, triage tickets, suggest settlements or review contracts and a human approves, edits or rejects each one, and you want to reconstruct later what was drafted and why it was approved. CHAP 0.2 is a public draft, and profile surfaces move faster than Core.
What it does
CHAP, the Collaborative Human-Agent Protocol, is an open protocol for humans and agents doing accountable work together. It gives approvals, overrides, handoffs and escalations a shared, auditable shape across MCP and A2A.
The problem it addresses: agents draft code reviews, triage tickets, suggest settlements or review contracts, and a human approves, edits or rejects each one. That decision typically lives in application code, chat threads, ticket comments and someone's head. When something goes wrong six weeks later, reconstructing what happened costs about forty-five minutes and is half guesswork.
In CHAP the agent's draft is an artefact and the human's edit is a structured override with a diff, a rationale and tags you control. The envelopes chain together by content hash and are joined by prev_hash. You query one chain instead of grepping logs across several UIs. The chain survives key rotation, log expiry and people leaving, and one audit.read call returns the whole thing. The overrides reviewers were already making accumulate into supervision data you would otherwise have to commission.
The override envelope is the central shape, and every field has a job. task_id links to the review chain, from carries queryable identity, logical_id survives revision, diff is an RFC 6902 JSON Patch, rationale is the why alongside the what, and tags is structured supervision data. intent_preserved distinguishes a refining override, where the human agreed with the agent's decision but rewrote how it was expressed, from a substituting override, where the human reached a different decision. They are two different failure modes and want different fixes. A high refining rate around one policy clause means the agent's retrieval is off; a high substituting rate on the same clause means the policy itself is ambiguous, or the agent's task context is wrong. tags is the controlled vocabulary your team agrees on. Keep it small: whatever you put there is the dimension you will aggregate on months later, when asking which prompts need work or which paths the bot gets consistently wrong.
When to use - and when NOT to
Use it when agents do real work and a person approves, edits or rejects each result, and you want to reconstruct later what was drafted, who changed it and why.
When approvals must be non-repudiable, the optional security-signed/1.0 profile adds an Ed25519 signature to every envelope, identity-oidc/1.0 binds it to a real identity, and audit-scitt/1.0 anchors the chain in an external transparency log that can be verified without trusting your servers.
CHAP sits beside MCP and A2A rather than replacing them: MCP is for tools, A2A is for other agents, and CHAP is for the shared work with humans.
CHAP 0.2 is a public draft. Profile surfaces move faster than Core, and if you need strict stability you should wait for 1.0.
Inputs and outputs
Messages are JSON-RPC 2.0 envelopes carrying params such as workspace, from, to and ts. The specification is seven Core methods plus eleven optional profiles. The Core methods are participant.join, participant.leave, workspace.describe, task.create, task.update, task.complete and audit.read. Named profiles include review/1.0 for humans to approve or override agent output, whisper for mid-task disambiguation questions, deliberation for multi-party voting, modes for safely rolling out new agents from shadow to trial to production, handoff for shift handoffs and follow-the-sun, control for pause, supersede, snapshot and rollback, and identity-vc for verified human identity (identity-oidc/1.0 also binds an identity).
A review flow uses task.create (with kind, assignee and input; the response includes a task_id), task.complete (with output), review.request (with the artefact and to) and then decide.override, whose params are intent_preserved, a JSON Patch diff, rationale and tags. The output is the audit chain: the full ordered list of envelopes, every join, task transition and progress note, returned by audit.read with a range of from_seq and to_seq. The audit log is the source of truth.
A first run needs only the Core reference server and plain curl, with no SDK and no client library. Start it from reference/core with npm install and npm run start:demo; it listens on http://localhost:8080/chap. Then post JSON-RPC envelopes to it: participants join, workspace.describe returns the members and the workspace state, and audit.read returns the history. This shape needs no crypto, no identity provider and no external services, and is a useful deployment shape for an internal team chatbot, a solo-operator agent farm or a structured-task queue.
For analysis, chap-analytics (pip install chap-analytics) projects the whole chain into documented pandas tables, from a SQLite file, a JSON export, a live coordinator or a plain audit.read. Overrides, decisions, reviewers, whispers and handoffs can then be analysed as a supervision dataset.
Integrations
A coordinator can present itself as an MCP server or an A2A agent, and MCP tool calls can be cited inside artefacts. Five framework bridges put the human-in-the-loop decisions of LangGraph, Pydantic AI, AG2, LlamaIndex Workflows and Google ADK on the audit chain.
The TypeScript library exposes a typed facade (coord.api.*) with full autocomplete and compile-time checks, with SQLite persistence through SqliteStore from @brightbeamai/chap-coordinator/storage/sqlite. The Python library keeps the JSON-RPC envelope shape on its surface through coord.dispatch({...}), and consumers wrap it as suits the call site. Both emit the same params and the same envelope shape, and the audit chain reads the same whichever client made the call.
Install the TypeScript coordinator with npm or the Python coordinator with pip:
npm install @brightbeamai/chap-coordinator
pip install chap-coordinator
Either path gets you Core plus the review/1.0 profile and a runnable reference. For one real decision in about two minutes with Python and nothing else, clone the repository and run python3 start-here/start.py.
The specification is CC BY 4.0 and the code is Apache 2.0, royalty-free for any language and any deployment.
Source README
Collaborative Human-Agent Protocol (CHAP)



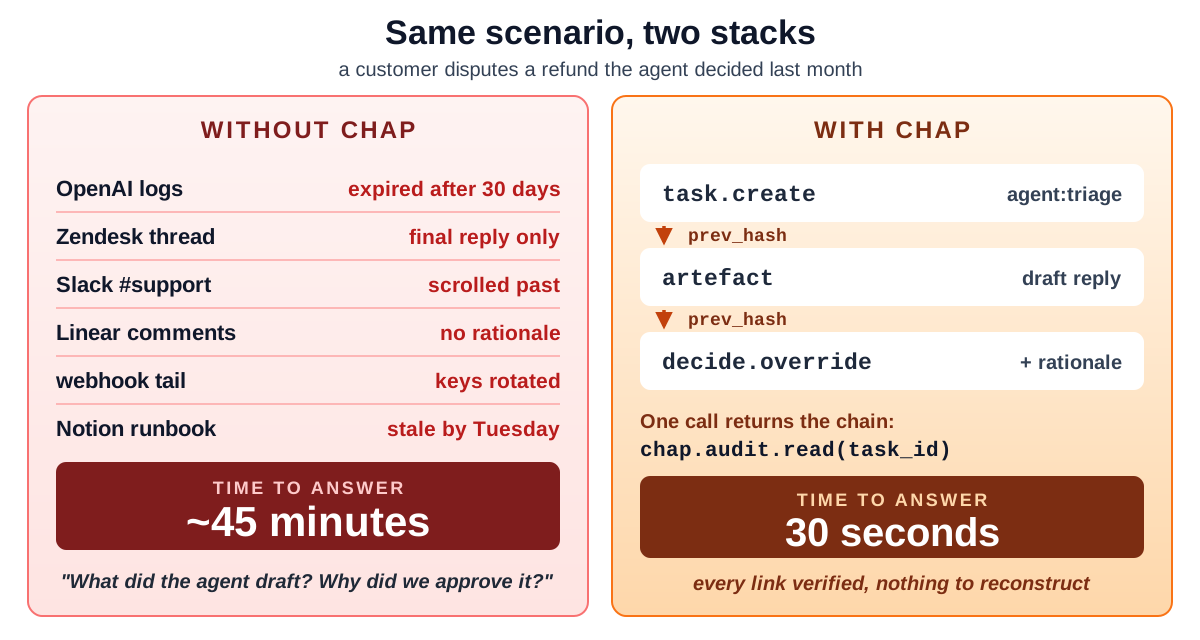
Work is moving towards teams in which hundreds of agents and hundreds of people take part. Agents draft, triage and recommend; people approve, correct, overrule and escalate. Those human decisions make the work accountable, yet they are usually recorded only in chat threads, ticket comments and memory.
CHAP gives those decisions a defined structure and an auditable record: what the agent produced, what the person decided and why, in one log that can be queried and verified.
- Structured overrides. When a person edits an agent's work, the edit is recorded with a diff, a rationale and tags your team defines, so corrections can be analysed later.
- A tamper-evident log. Every change is recorded in order. With the hash chain on, an altered entry is detected on verification, provided a recent chain head is kept out of the operator's reach (
SECURITY.md§5). The history survives key rotation, expired vendor logs and staff changes. - Signatures and identity. Optional extensions, called profiles, require every call to be signed, bind signing keys to verified identities, and submit entries to a transparency log.
- Alongside MCP and A2A. MCP connects agents to tools and A2A connects agents to each other; CHAP records the work agents share with people.
Concepts
CHAP is a protocol: a set of calls that agents, people and their tools send to a coordinator, the service that mediates a workspace. The coordinator checks each call against the workspace's rules, answers it, and records each accepted change in the workspace's audit log. The TypeScript and Python packages below are coordinators, to embed in your own process or run as a server.
| Term | What it is |
|---|---|
| Workspace | A named context for one body of work: its members, its tasks, and the profiles it uses |
| Participant | A member, named by a URI such as human:alice@example.org or agent:triage; group: names a set of members |
| Task | A unit of work, assigned to a participant |
| Artefact | What a participant produces in a task: a draft, a decision, an override |
| Envelope | One call, as a JSON-RPC 2.0 message; its method is the verb, such as task.create or decide.approve |
| Audit log | The ordered record of every change to the workspace; with the hash chain on, each entry carries the hash of the one before it |
The verbs read as their names. A task is created, completed and sent for review (task.create, task.complete, review.request). A reviewer approves, rejects or overrides it (decide.approve, decide.reject, decide.override). Work is handed off or escalated (handoff.propose, escalate.raise), and audit.read returns the record.
Core and profiles. Every coordinator implements Core (core/1.0): workspaces, participants, tasks and the audit log. Everything else is an optional profile, named with its version. review/1.0 adds review requests and decisions. Others add quick questions to a person (whisper/1.0), group votes (deliberation/1.0), handoffs (handoff/1.0), pausing and rollback (control/1.0), routing (routing/1.0), shadow and trial modes (modes/1.0), signed calls (security-signed/1.0), verified identities (identity-oidc/1.0, identity-vc/1.0) and a transparency log (audit-scitt/1.0). A workspace advertises the profiles it uses, and the coordinator refuses calls that belong to any other profile. core/SPEC.md fits Core on one page, profiles/PROFILES.md lists the profiles, and GLOSSARY.md defines every term.
Install
Libraries. Each package implements Core and every profile; a new workspace advertises core/1.0 and review/1.0 unless you name others.
npm install @brightbeamai/chap-coordinator
pip install chap-coordinator
A new project. create-chap-app generates one with a review desk, one profile setting and a diff-profiles command:
npx create-chap-app my-gate
cd my-gate && npm install && npm run demo
The default template is the code gate: each change a coding agent makes in a git repository is reviewed as a diff, approved with the reviewer's signature, and committed with the evidence beside it for CI to verify. The other templates are an MCP gate for Claude Desktop, Cursor and Claude Code, a support desk, an outbound approval gate and a production set. docs/profile-explorer.md shows what each profile changes.
From a clone of this repository. START_HERE.md runs a local review desk on the Python coordinator, with Python 3.10 or later and nothing else to install:
git clone https://github.com/BrightbeamAI/chap.git && cd chap
python3 start-here/start.py
examples/00-five-minute-start.md sends envelopes to the Core reference server with curl and reads back the audit log. The libraries are in packages/coordinator/ and packages/coordinator-py/, the reference implementations in reference/ and reference/python/.
The 90-second tour
A solo developer reviews pull requests with Cursor, and the bot flags a warning the developer disagrees with. The clip shows the exchange in six steps, in about 23 seconds.
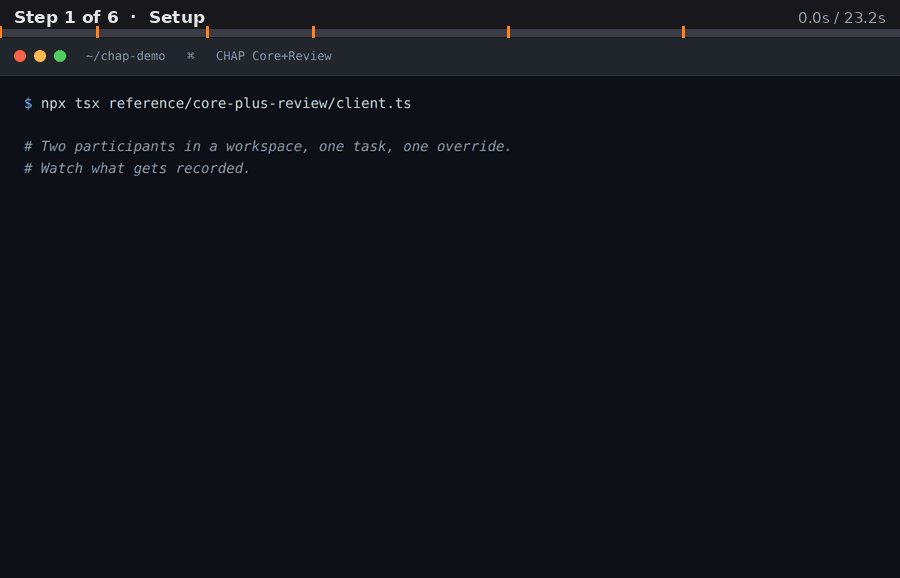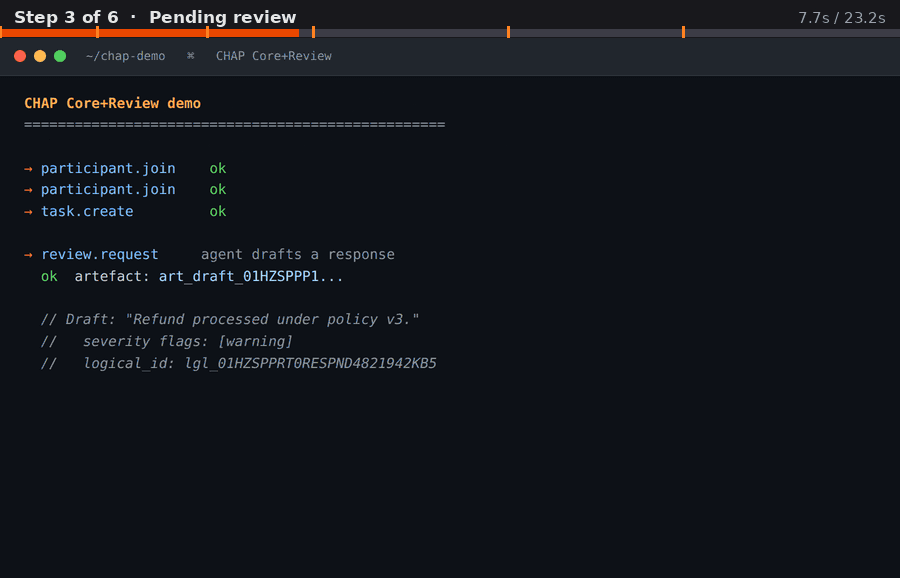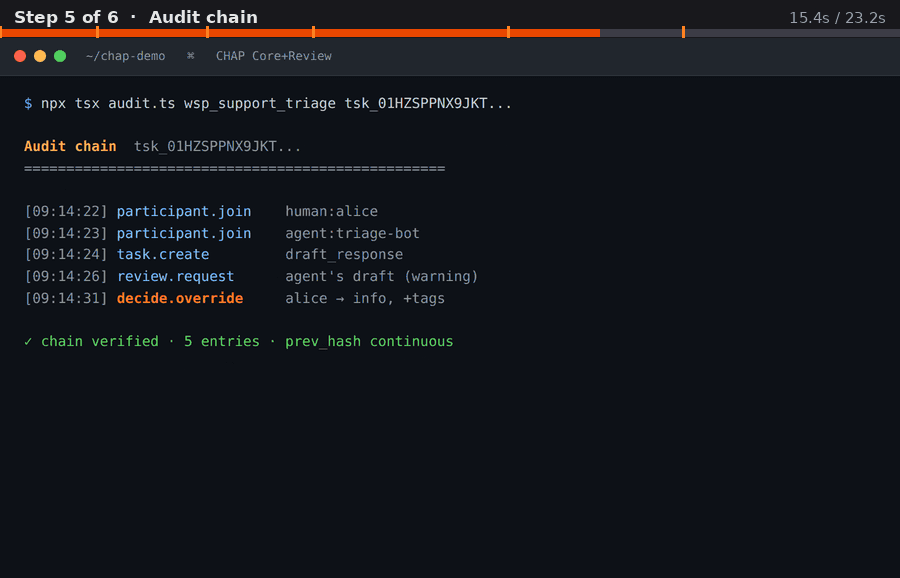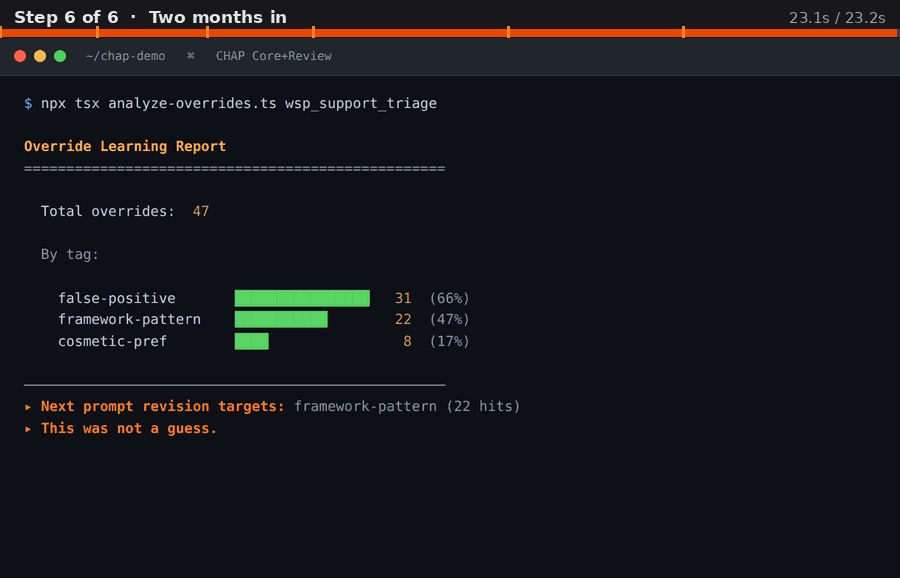
The code for each step follows, in TypeScript and Python.
import { Coordinator } from "@brightbeamai/chap-coordinator";
import { SqliteStore } from
  "@brightbeamai/chap-coordinator/storage/sqlite";

const coord = new Coordinator({
  store: new SqliteStore("./chap.db"),
  enableChain: true,
});

coord.api.workspace.create({
  workspace: "wsp_pr_reviews",
  profiles:  ["core/1.0", "review/1.0"],
});

coord.api.participant.join({
  workspace: "wsp_pr_reviews",
  from:      "human:me@local",
  type:      "human",
});

coord.api.participant.join({
  workspace: "wsp_pr_reviews",
  from:      "agent:cursor#v1",
  type:      "agent",
});
from chap_coordinator import Coordinator
from chap_coordinator.storage.sqlite \
    import SqliteStore

coord = Coordinator(
    store=SqliteStore("./chap.db"),
    enable_chain=True,
)

def send(method, params):
    return coord.dispatch({
        "jsonrpc": "2.0", "id": method,
        "method": method, "params": params,
    })

send("workspace.create", {
    "workspace": "wsp_pr_reviews",
    "profiles":  ["core/1.0", "review/1.0"],
})

send("participant.join", {
    "workspace": "wsp_pr_reviews",
    "from":      "human:me@local",
    "type":      "human",
})

send("participant.join", {
    "workspace": "wsp_pr_reviews",
    "from":      "agent:cursor#v1",
    "type":      "agent",
})
// The review Cursor returned.
const cursorReview = {
  comments: [{ severity: "warning",
               body: "Unused parameter." }],
};

// The bot's review is the output of a task.
const { task_id } = coord.api.task.create({
  workspace: "wsp_pr_reviews",
  from:      "agent:cursor#v1",
  assignee:  "agent:cursor#v1",
  kind:      "code_review",
  input:     { pr_id: "PR-482" },
});

coord.api.task.complete({
  workspace: "wsp_pr_reviews",
  from:      "agent:cursor#v1",
  task_id,
  output:    cursorReview,
});

coord.api.review.request({
  workspace: "wsp_pr_reviews",
  from:      "agent:cursor#v1",
  task_id,
  artefact:  cursorReview,
  to:        "human:me@local",
});

// You disagree with one comment. Override it.
coord.api.decide.override({
  workspace:        "wsp_pr_reviews",
  from:             "human:me@local",
  task_id,
  intent_preserved: true,
  diff: [{ op: "replace",
           path: "/comments/0/severity",
           value: "info" }],
  rationale: "False positive. Framework " +
             "convention, not a bug.",
  tags: ["false-positive",
         "framework-pattern-misread"],
});
# The review Cursor returned.
cursor_review = {
    "comments": [{"severity": "warning",
                  "body": "Unused parameter."}],
}

# The bot's review is the output of a task.
r = send("task.create", {
    "workspace": "wsp_pr_reviews",
    "from":      "agent:cursor#v1",
    "assignee":  "agent:cursor#v1",
    "kind":      "code_review",
    "input":     {"pr_id": "PR-482"},
})
task_id = r["result"]["task_id"]

send("task.complete", {
    "workspace": "wsp_pr_reviews",
    "from":      "agent:cursor#v1",
    "task_id":   task_id,
    "output":    cursor_review,
})

send("review.request", {
    "workspace": "wsp_pr_reviews",
    "from":      "agent:cursor#v1",
    "task_id":   task_id,
    "artefact":  cursor_review,
    "to":        "human:me@local",
})

# You disagree with one comment. Override it.
send("decide.override", {
    "workspace":        "wsp_pr_reviews",
    "from":             "human:me@local",
    "task_id":          task_id,
    "intent_preserved": True,
    "diff": [{"op":    "replace",
              "path":  "/comments/0/severity",
              "value": "info"}],
    "rationale": "False positive. Framework "
                 "convention, not a bug.",
    "tags": ["false-positive",
             "framework-pattern-misread"],
})
The two surfaces. TypeScript ships a typed facade,
coord.api.*, so every method has autocomplete and compile-time checks. Python keeps the JSON-RPC envelope on the surface,coord.dispatch({...}), wrapped here in asend()helper, the idiom the Python tests use. Both send the same parameters in the same envelope, so the audit chain reads the same whichever client made the call.
The repository ships the script in both languages. It reads the audit chain over HTTP or straight from your SQLite file:
# TypeScript reference, against the SqliteStore from step 1:
$ npx tsx reference/core-plus-review/analyze-overrides.ts --db ./chap.db wsp_pr_reviews

# Python reference, same idea:
$ python3 reference/python/analyze_overrides.py --db ./chap.db wsp_pr_reviews

Override Learning Report
========================================
Workspace:       wsp_pr_reviews
Total overrides: 47

By tag:
  false-positive                       ████████████████████   31  (66%)
  framework-pattern-misread            ██████████████          22  (47%)
  cosmetic-pref                        █████                    8  (17%)

Intent breakdown:
  refining (same decision, better wording)   41
  substituting (different decision)          6

Top reviewers:
  human:me@local                            47

Hint: the most common tags are your next prompt revision targets.
The most common tags name what the next prompt revision for Cursor should fix.
chap-analytics (pip install chap-analytics) loads the whole chain into documented pandas tables, from a SQLite file, a JSON export, a live coordinator or an audit.read: overrides, decisions, reviewers, whispers and handoffs. A notebook works through a week of review data, and ANALYTICS_ROADMAP.md describes the planned work.
The override envelope
The override envelope records a reviewer's change to an agent's output. Each field is annotated below:
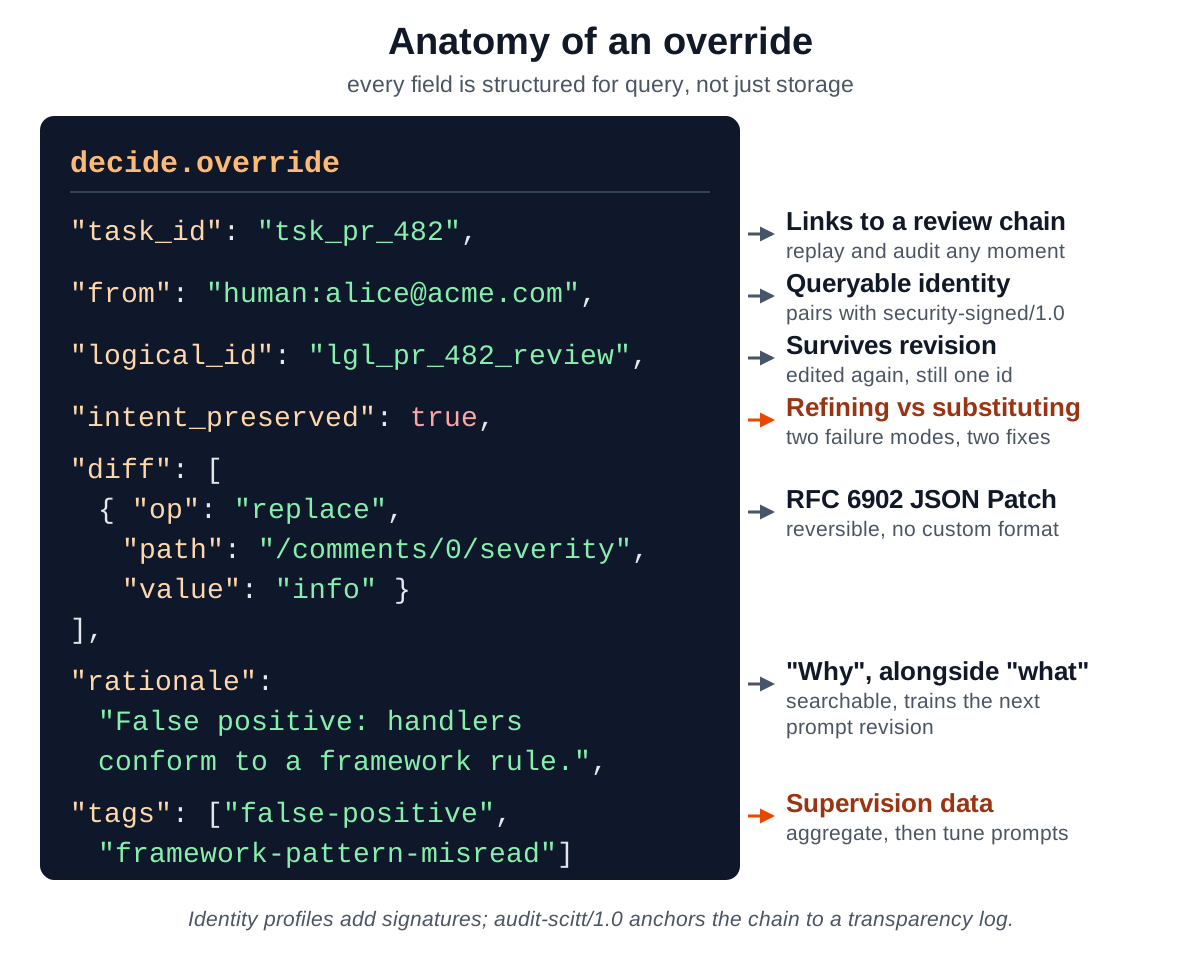
Two fields matter most for analysis:
intent_preservedtells a refining override, where the person kept the agent's decision and rewrote its wording, from a substituting one, where the person decided differently. Each points at a different fix: many refining overrides around one policy clause point at the agent's retrieval; many substituting ones point at an ambiguous policy, or at the agent's task context.tagsare the small, controlled vocabulary your team agrees on. They are what you will count by three months from now, to answer which prompts need work? and which paths does the bot keep getting wrong?
Status
CHAP 0.3 is a public draft: a small Core and optional profiles (SPECIFICATION.md).
- Two reference coordinators, in TypeScript and Python, implement the same methods, and a differential fuzzer checks that they answer and log alike.
- The conformance harness covers Core and
review/1.0, and runs against the Python coordinator and a standalone TypeScript server. - A coordinator can present itself as an MCP server or an A2A agent.
- Framework bridges put LangGraph, Pydantic AI, AG2, LlamaIndex Workflows and Google ADK human-in-the-loop decisions on the audit log.
Before 1.0, a minor release may break things, and its changelog lists each break with a migration; from 1.0 the specification follows Semantic Versioning. For strict stability, wait for 1.0: ROADMAP.md sets out what it will promise and the milestones on the way.
Read this next
| Read | For |
|---|---|
START_HERE.md |
A local review desk on the Python coordinator, with nothing to install beyond Python |
IN_PRACTICE.md |
Scenarios, from a solo developer with Cursor to GMP-regulated manufacturing |
ABOUT.md |
The repository's contents, how CHAP relates to MCP and A2A, the standards it reuses, and contributing |
core/SPEC.md |
Core, on one page |
| The technical report | The architecture, profile semantics and threat model, with the scenarios as JSON traces |
Cite
If you reference CHAP in academic or technical work, please cite the technical report.
@techreport{chap2026,
  author      = {Shahid, Arsalan and Suttie, Gordon and Black, Philip},
  title       = {Collaborative Human-Agent Protocol (CHAP): An open protocol for auditable, structured multi-human and multi-agent collaboration},
  institution = {Brightbeam AI},
  year        = {2026},
  type        = {Technical Report},
  number      = {arXiv:2606.09751},
  url         = {https://arxiv.org/abs/2606.09751}
}
CC BY 4.0 (specification text, see LICENSE-SPEC.md) · Apache 2.0 (everything else) · Any language, any deployment.
examples/00-five-minute-start.md
5-Minute Start
The shortest path from "I've heard of CHAP" to "I've sent CHAP
envelopes and read back the audit log", with the envelopes in plain
sight. It uses the Core reference server at
../reference/core/ and plain curl. No SDK,
no client library.
If you want a first decision rather than a first envelope, and would
rather not install anything, start at
../START_HERE.md.
If you'd rather watch the same flow run as a scripted client, see
../reference/core/client.ts.
Step 0: start the server
cd reference/core
npm install
npm run start:demo
You should see:
CHAP Core reference listening on http://localhost:8080/chap
Leave it running. In another terminal:
Step 1: alice joins
curl -s -X POST http://localhost:8080/chap \
  -H 'Content-Type: application/json' \
  -d '{
    "jsonrpc": "2.0",
    "id": "1",
    "method": "participant.join",
    "params": {
      "workspace":    "wsp_demo",
      "from":         "human:alice@example.org",
      "to":           "service:coordinator@example.org",
      "ts":           "2026-05-17T09:00:00Z",
      "type":         "human",
      "display_name": "Alice",
      "role":         "reviewer"
    }
  }' | jq
Response:
{
  "jsonrpc": "2.0",
  "id": "1",
  "result": { "joined": true, "as": "human:alice@example.org", "role": "reviewer" }
}
Step 2: the agent joins
curl -s -X POST http://localhost:8080/chap \
  -H 'Content-Type: application/json' \
  -d '{
    "jsonrpc": "2.0",
    "id": "2",
    "method": "participant.join",
    "params": {
      "workspace":    "wsp_demo",
      "from":         "agent:triage-bot",
      "to":           "service:coordinator@example.org",
      "ts":           "2026-05-17T09:00:00Z",
      "type":         "agent",
      "display_name": "Triage Bot v0.1",
      "role":         "drafter",
      "capabilities": { "kinds": ["draft_response"] }
    }
  }' | jq
Step 3: see who's in the room
curl -s -X POST http://localhost:8080/chap \
  -H 'Content-Type: application/json' \
  -d '{
    "jsonrpc": "2.0",
    "id": "3",
    "method": "workspace.describe",
    "params": {
      "workspace": "wsp_demo",
      "from":      "human:alice@example.org",
      "to":        "service:coordinator@example.org",
      "ts":        "2026-05-17T09:00:00Z"
    }
  }' | jq
You'll see both members, the workspace state, and profiles: ["core/0.2"].
Step 4: alice delegates a task to the bot
curl -s -X POST http://localhost:8080/chap \
  -H 'Content-Type: application/json' \
  -d '{
    "jsonrpc": "2.0",
    "id": "4",
    "method": "task.create",
    "params": {
      "workspace": "wsp_demo",
      "from":      "human:alice@example.org",
      "to":        "agent:triage-bot",
      "ts":        "2026-05-17T09:01:00Z",
      "kind":      "draft_response",
      "assignee":  "agent:triage-bot",
      "input":     { "ticket_id": "INC-48219", "customer_message": "Where is my order?" }
    }
  }' | jq
The response includes a task_id. Save it for the next steps:
TASK=$(curl -s -X POST http://localhost:8080/chap \
  -H 'Content-Type: application/json' \
  -d '{
    "jsonrpc": "2.0",
    "id": "4",
    "method": "task.create",
    "params": {
      "workspace": "wsp_demo",
      "from":      "human:alice@example.org",
      "to":        "agent:triage-bot",
      "ts":        "2026-05-17T09:01:00Z",
      "kind":      "draft_response",
      "assignee":  "agent:triage-bot",
      "input":     { "ticket_id": "INC-48219", "customer_message": "Where is my order?" }
    }
  }' | jq -r '.result.task_id')
echo $TASK
# tsk_…
Step 5: the bot starts work
curl -s -X POST http://localhost:8080/chap \
  -H 'Content-Type: application/json' \
  -d "{
    \"jsonrpc\": \"2.0\",
    \"id\": \"5\",
    \"method\": \"task.update\",
    \"params\": {
      \"workspace\":     \"wsp_demo\",
      \"from\":          \"agent:triage-bot\",
      \"to\":            \"human:alice@example.org\",
      \"ts\":            \"2026-05-17T09:01:05Z\",
      \"task_id\":       \"$TASK\",
      \"state\":         \"in_progress\",
      \"progress_note\": \"Looking up the order.\"
    }
  }" | jq
Step 6: the bot delivers
curl -s -X POST http://localhost:8080/chap \
  -H 'Content-Type: application/json' \
  -d "{
    \"jsonrpc\": \"2.0\",
    \"id\": \"6\",
    \"method\": \"task.complete\",
    \"params\": {
      \"workspace\": \"wsp_demo\",
      \"from\":      \"agent:triage-bot\",
      \"to\":        \"human:alice@example.org\",
      \"ts\":        \"2026-05-17T09:01:10Z\",
      \"task_id\":   \"$TASK\",
      \"output\": {
        \"subject\": \"Re: order status\",
        \"body\":    \"Order ORD-91204 is delayed by the carrier; new ETA Wed.\"
      },
      \"confidence\": \"0.91\"
    }
  }" | jq
Step 7: read the audit log
curl -s -X POST http://localhost:8080/chap \
  -H 'Content-Type: application/json' \
  -d '{
    "jsonrpc": "2.0",
    "id": "7",
    "method": "audit.read",
    "params": {
      "workspace": "wsp_demo",
      "from":      "human:alice@example.org",
      "to":        "service:coordinator@example.org",
      "ts":        "2026-05-17T09:02:00Z",
      "range":     { "from_seq": 0, "to_seq": 100 }
    }
  }' | jq '.result.entries | length, map((.envelope // .request).method)'
You get back the full ordered list of envelopes, every join, every
task transition, every progress note. A refused call the coordinator
recorded is held under request, with an outcome beside it. The
audit log is the source of truth.
What just happened
You exercised every one of CHAP Core's 7 methods:
| Method | What it did |
|---|---|
participant.join |
Two participants entered the workspace. |
workspace.describe |
The workspace returned its state. |
task.create |
A task was created and assigned. |
task.update |
The assignee reported progress. |
task.complete |
The assignee delivered output. |
audit.read |
The full history was readable as a log. |
participant.leave |
(Skipped here; called by the demo client.) |
That's it. No crypto. No identity provider. No external services. This is a real, useful deployment shape, internal team chatbot, solo-operator agent farm, structured-task queue.
Where to go next
| You want… | Read |
|---|---|
| Humans to approve / override agent output | ../profiles/review.md |
| Mid-task disambiguation questions | ../profiles/whisper.md |
| Multi-party voting | ../profiles/deliberation.md |
| Safely roll out new agents (shadow → trial → prod) | ../profiles/modes.md |
| Shift handoffs and follow-the-sun | ../profiles/handoff.md |
| Pause / supersede / snapshot / rollback | ../profiles/control.md |
| Non-repudiation and signed messages | ../profiles/security-signed.md |
| Cryptographic transparency log | ../profiles/audit-scitt.md |
| Verified human identity | ../profiles/identity-oidc.md · identity-vc.md |
| Cite MCP tool calls inside artefacts | ../integrations/CHAP-with-MCP.md |
| Cross-organisation peers (A2A bridge) | ../integrations/CHAP-with-A2A.md |
| Build Core in your favourite language | ../core/SPEC.md |
FAQ
Common questions
Discussion
Questions & comments · 0
Sign In Sign in to leave a comment.