
Detectorscope
Inspect AI-text detector predictions as named feature contributions with token locations, using DetectorScope research models.
1.0.0Add to Favorites
Source
Get it from source
Spark does not host a copy of it.
Open sourceReports
Agent outcome reports
No reports yet
Overview
A research workflow for examining text-detector predictions as named feature contributions and token highlights. It includes released detectors and a pipeline for building auditable versions. Use to study detector behavior and interpretability tradeoffs. Do not use these research detectors as the basis for decisions about individuals.
The workflow you build
DetectorScope supports a workflow for inspecting why a text detector assigns a prediction. It replaces an opaque decision with named, validated sparse-autoencoder features and their contributions. The language model's residual stream is encoded into features, their natural-language descriptions are checked against activations, and a head uses features that meet an interpretability threshold.
Load a released detector, provide a text or list of texts, and inspect the returned Detection objects. Each result includes label, p_ai, logit, bias, and active features with nonzero effects, ordered by contribution size. For the additive detector, logit equals bias plus the sum of feature importances. Importance measures how much the logit falls when a feature is silenced. Optional highlights associate features with token indices and activations, allowing examination of where the evidence appears.
The tau parameter selects the minimum auto-interpretation score. Its default is 0.85, with settings from 0.00 to 0.95 in steps of 0.05. Raising it restricts the head to fewer, better-described features at a potential accuracy cost. Lowering it admits more features, including less precise descriptions. Each branch includes heads at the available settings, so changing tau requires no additional download. Per-call settings allow comparison of the same text. A head selector switches between logistic regression and XGBoost at the chosen threshold.
When to use this bundle - and when NOT to
Use DetectorScope to study detector evidence, compare tendencies in generated text, or convert a black-box detector through its auditable pipeline. Open-domain models cover news, essays, reviews, and other COLING 2025 task data involving forty generators. Separate peer-review models distinguish human reviews from GPT-4o or Llama output.
These are research artifacts and can misclassify human writing. Accuracy outside their training domains and generators is unestablished. They must not determine academic-integrity, hiring, publication, or other decisions about individuals. DetectorScope is not an official Google product. Reported benchmark comparisons concern COLING and RAID; they do not establish reliability for every use case.
How to get started
A fresh Python environment can install the package from PyPI:
python -m venv .venv && source .venv/bin/activate
pip install detectorscope
Released detectors load through AuditableDetector.from_pretrained using a Hugging Face Hub identifier. Branches select three configurations: a fine-tuned Gemma-2-2b classifier with fine-tuned SAEs, an unchanged model with fine-tuned SAEs, or unchanged model and Gemma Scope SAEs. The open-domain default uses the second configuration; peer-review defaults use the first. Each branch bundles its language model without a separate license gate.
Building another detector involves classifier fine-tuning, SAE training, activation extraction and processing, feature auto-interpretation and validation, head training, and evaluation. Auto-interpretation uses Gemini and requires GEMINI_API_KEY. Stages zero through two require a GPU; later stages run on CPUs. The local and hosted demo uses Gradio, while experiment scripts cover hyperparameter search, counterfactual ablation, paraphrase ablation, and regex recall. A visualization notebook produces the paper's figures and tables.
Software is licensed under Apache License 2.0; other materials use CC-BY 4.0. Adapted third-party modules retain their own license headers.
Source README
🔬 DetectorScope 🔬



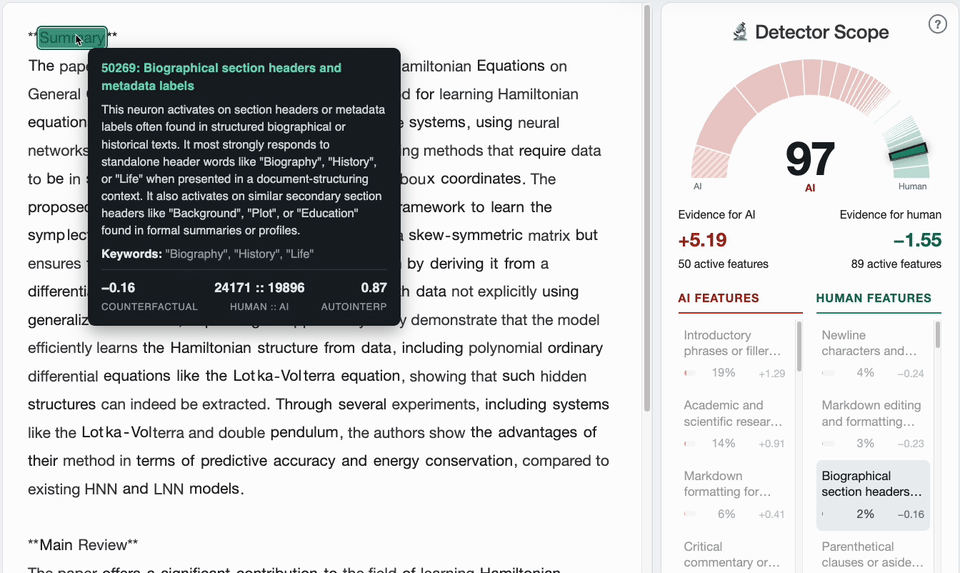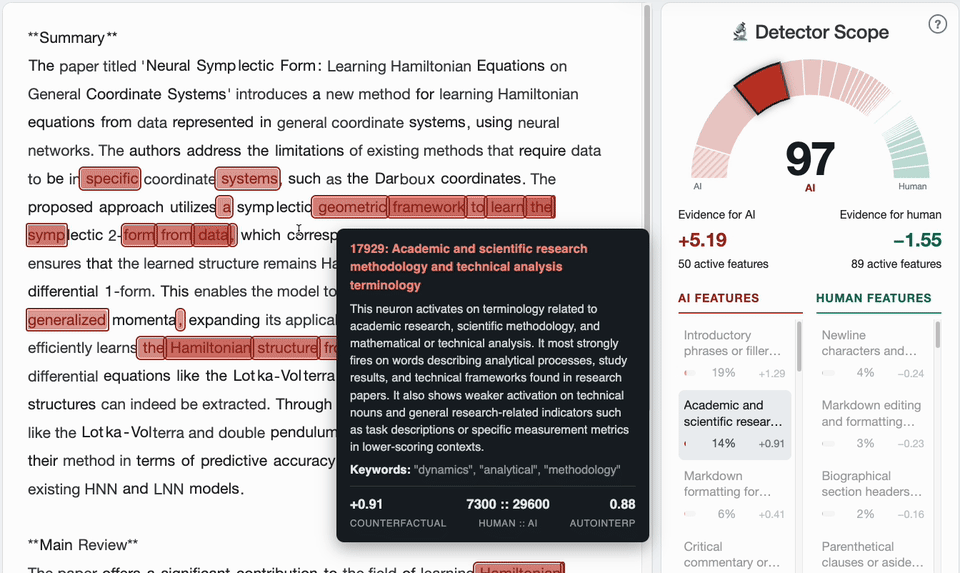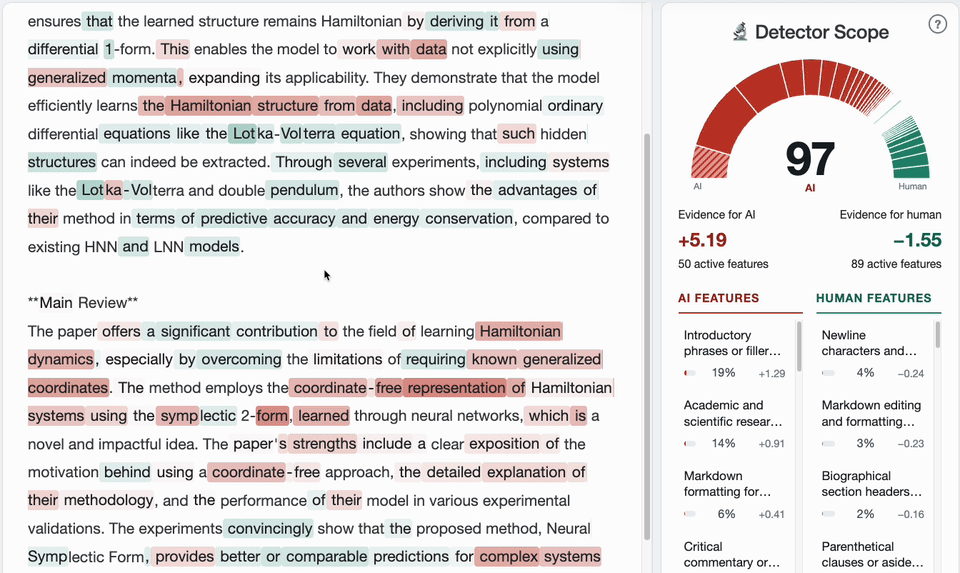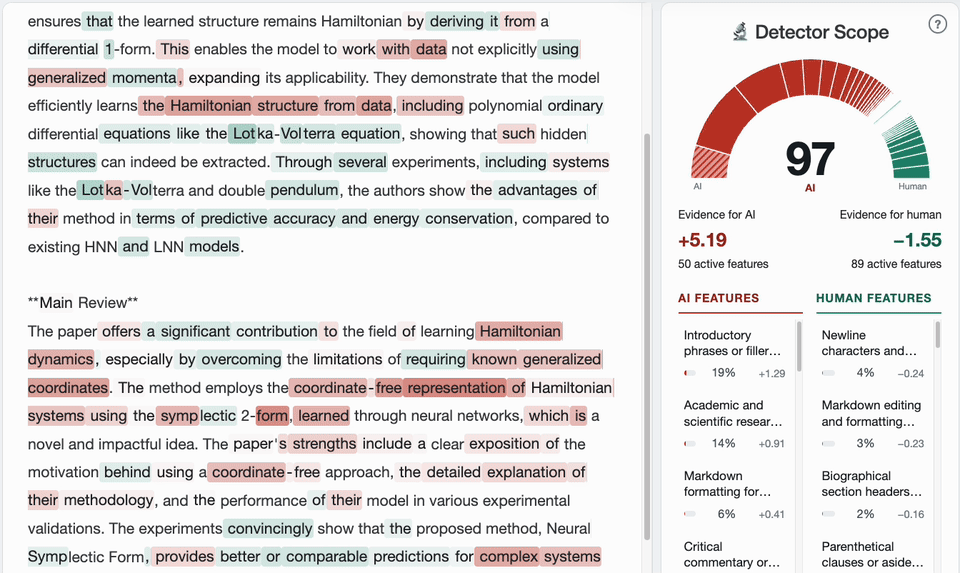
DetectorScope turns a black-box AI text detector into one whose every prediction is a sum of named, validated features. It can tell you which properties of a text made it predict "AI" and where in the text they are located.
from detectorscope import AuditableDetector

# Load the AI detector
detector = AuditableDetector.from_pretrained(
  "liamdugan/detector-scope"
)

# Run the AI detector on some input
output = detector(
  "Like I said, this is about accuracy, about speed, and about cost."
)

# Print the results
print(output)
Output
Detection(label='ai', p_ai=0.88, features=[
  Feature(importance=+0.23, description='the word about used as a preposition'),
  Feature(importance=+0.14, description='repeated phrases or sequences in text'),
  Feature(importance=-0.05, description='conversational filler phrase like i said'),
  ...])
Using DetectorScope you can:
- 🔍 Query a strong AI detector that is transparent about the features it uses
- 🖱️ Hover over the text to see the specific "AI Phrases" the detector is using
- 🔁 Convert your own black-box detector into an auditable one by using our pipeline
- 🎓 Analyze LLM Outputs so that you understand which models have which tendencies
News
- [25 Oct 2026] DetectorScope will appear at EMNLP 2026 in Budapest, Hungary!
Overview
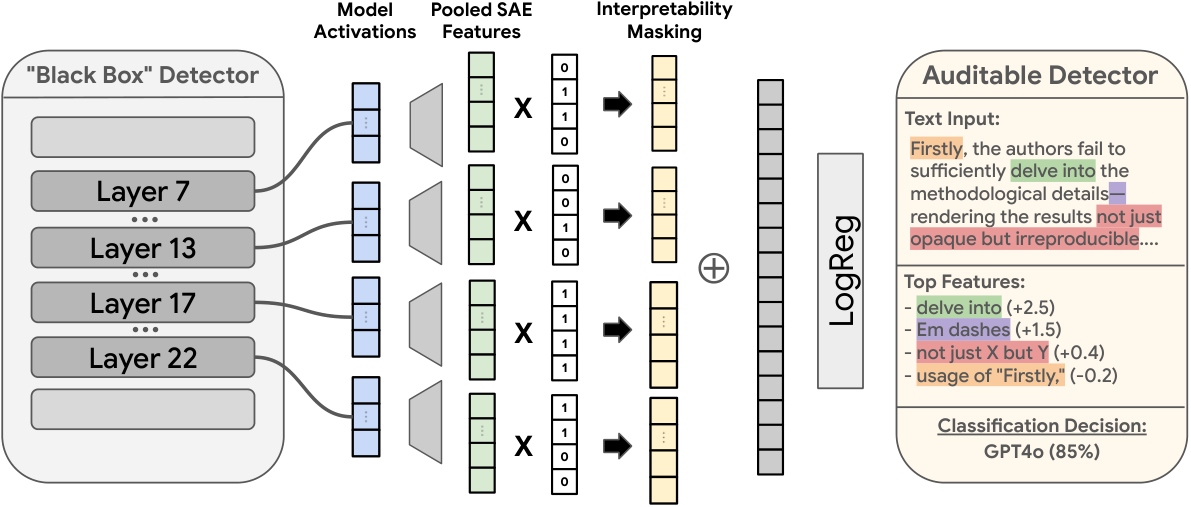
A DetectorScope detector is a concept bottleneck over interpretable sparse-autoencoder features: the language model's residual stream is encoded by SAEs, each feature gets a natural-language description that is validated against its own activations, and a sparse linear head over the validated features makes the decision. The prediction is therefore a sum of per-feature contributions, and every contribution has a description and a location in the text.
Results
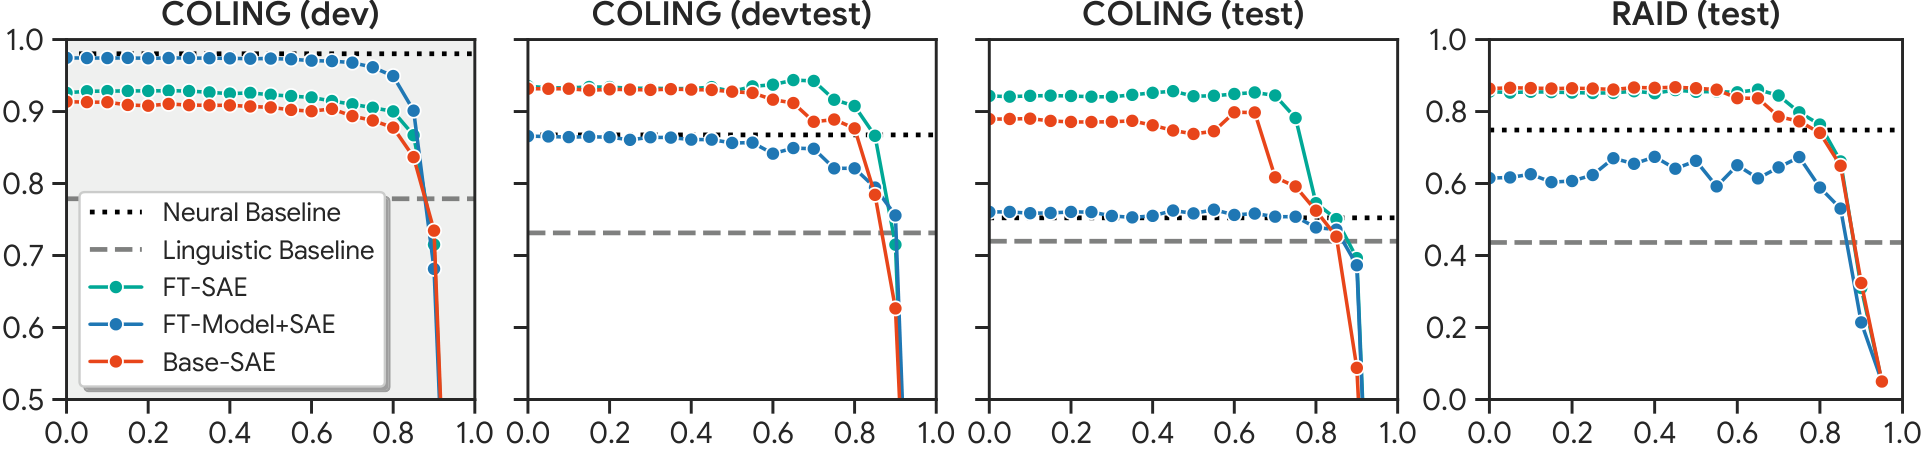
Across both benchmarks applying our auditable pipeline has minimal adverse effects on performance. The auditable detectors stay close to the fine-tuned black-box classifier they are built on. The full tables are in the paper.
Installation
From PyPI, in a fresh environment:
python -m venv .venv && source .venv/bin/activate
pip install detectorscope
From source, with the extras for the pipeline, the experiments and the demo:
git clone https://github.com/google-deepmind/detectorscope && cd detectorscope
pip install -e ".[all]"
Usage
Any released detector loads by its Hub id; the other settings of a repo are its branches.
from detectorscope import AuditableDetector

detector = AuditableDetector.from_pretrained("liamdugan/detector-scope-peer-review-gpt4o")
detector = AuditableDetector.from_pretrained("liamdugan/detector-scope", revision="base-sae")
detector(text) returns a Detection with label, p_ai, logit, bias and
features, every feature active in the text with a non-zero effect, largest
first. importance is how much the logit falls if the feature is silenced,
and logit == bias + sum(importances). A list of texts returns a list.
Set return_highlights=True to see where each feature is localized within the text:
output = detector(text, return_highlights=True)
output.tokens                   # the text as tokens
output.features[0].highlights   # [(token index, activation), ...]
You can use the tau parameter to control the tradeoff between
interpretability and accuracy. Every feature has an auto-interpretation score,
how well its description predicts where it fires, and tau is the score a
feature must reach before the head is allowed to use it. A higher tau gives
the head fewer, better-described features, so every item of evidence it reports
is one you can read and check, at some cost in accuracy. A lower tau admits
more features, including ones whose descriptions are loose, and the detector
gets more accurate and less legible. The default is 0.85.
detector = AuditableDetector.from_pretrained("liamdugan/detector-scope", tau=0.95)
tau runs from 0.00 (every feature) to 0.95 in steps of 0.05, and each branch
carries a head at every step, so changing it downloads nothing. It can also be
set per call, which is the easiest way to compare the same text at several
settings:
output = detector(text, tau=0.50)   # more features, higher accuracy
output = detector(text, tau=0.95)   # the few best-described features
detector.heads                      # every (head, tau) pair the repo holds
head="xgboost", on from_pretrained or on the call, selects the gradient-boosted
head at the same tau instead of the logistic-regression one.
Models
We provide the following model collections for download via Huggingface:
| Repo | Domain and data |
|---|---|
detector-scope |
open domain: the COLING 2025 GenAI Detection shared task (news, essays, reviews and more; 40 generators) |
detector-scope-peer-review-gpt4o |
closed domain: machine-learning peer reviews, human vs. GPT-4o (the AI Peer Review Detection Benchmark) |
detector-scope-peer-review-llama |
closed domain: the same reviews, human vs. Llama |
Each repo holds the paper's three settings as branches. ft-model-sae fine-tunes
Gemma-2-2b as a classifier and fine-tunes the SAEs on it; ft-sae keeps the
unmodified Gemma-2-2b and fine-tunes only the SAEs; base-sae keeps both the
unmodified Gemma-2-2b and the unmodified Gemma Scope SAEs. main is the setting
that performed best on each domain: ft-sae for the open domain, ft-model-sae
for peer reviews. Every branch bundles its language model, so nothing else is
downloaded and no licence gate is involved.
The defaults are set by hand: the logistic-regression head over features whose auto-interpretation score is at least 0.85, with the decision threshold fixed on the development split. Each branch also carries the XGBoost head and both heads at every other threshold.
Reproducing the paper
The pipeline that builds a detector is the package's stages, run as
python -m detectorscope.<stage>: finetune (the classifier), train_sae
(SAEs on its residual stream), data.extract and data.process (per-token
activations, per-document caches, log-odds ratios, feature statistics),
autointerpret (descriptions and their validation, through Gemini; set
GEMINI_API_KEY), model.detectors.heads.training.train_logreg /
train_xgboost (the heads) and evaluate. Stages 0 to 2 need a GPU; the rest
runs on CPUs.
The experiments are four scripts under scripts/: hparam_sweep.py (the SGD +
L1 grid search), counterfactual_ablation.py (zero-ablation vs. targeted
paraphrase of single features), paraphrase_ablation.py (the feature-guided
paraphrase attack) and regex_recall_ablation.py (regex recall of the
descriptions). Every figure and table of the paper comes from
scripts/visualization/analysis.ipynb, and --help on any script lists its
arguments.
demo/ is the Gradio app, which runs locally with python demo/app.py and as
the Hugging Face Space; scripts/huggingface_hub/ exports the detectors to the Hub and
publishes the Space.
Citation
@inproceedings{dugan-etal-2026-building,
    title = "Building Auditable {AI} Text Detectors with Sparse Autoencoders",
    author = "Dugan, Liam  and
      McDougall, Callum Stuart  and
      Denton, Matthew  and
      Pham, Philip  and
      Kaeser-Chen, Christine  and
      Callison-Burch, Chris",
    booktitle = "Proceedings of the 2026 Conference on Empirical Methods in Natural Language Processing",
    month = oct,
    year = "2026",
    address = "Budapest, Hungary",
    publisher = "Association for Computational Linguistics",
    url = "https://aclanthology.org/2026.emnlp-main.762/",
    pages = "17640--17689",
    ISBN = "979-8-89176-459-0",
}
Discussion
Questions & comments · 0
Sign In Sign in to leave a comment.