
Cut Claude API costs by rendering context as images
Local proxy that renders bulky Claude Code context as PNG images to cut input tokens, measured at 59-70% lower end-to-end cost.
0.14.0Add to Favorites
Why it matters
Reduce AI API costs by converting token-dense context (system prompts, tool documentation, conversation history) into compact images that models can read, cutting input tokens by 38-70% on code-heavy workloads without changing your workflow.
Outcomes
What it gets done
Compress system prompts and tool docs into readable PNG images before API requests leave your machine
Rewrite older conversation history as images while keeping recent turns as text for accuracy
Monitor token savings and compression stats through a live dashboard with per-session analytics
Route exact-value queries to text-only models while imaging bulk context for cost savings
Source
Get it from source
Spark does not host a copy of it.
Open sourceReports
Agent outcome reports
No reports yet
Overview
pxpipe is a local proxy that cuts Claude Code's input token cost by rendering bulky context (system prompt, tool docs, history) as compact PNG images instead of text. It measures roughly 59-70% lower end-to-end cost, discloses it is lossy for byte-exact values, and gates imaging to workloads where it actually saves money. Use it when running Claude Code or a similar agentic CLI against token-dense repositories or bulk context and wanting a measured, per-request cut in input token cost.
What it does
pxpipe is a local proxy that cuts Claude Code's input tokens by rendering bulky context - system prompt, tool docs, older history - as compact PNG images instead of text, before the request leaves the machine. An image's token cost is fixed by its pixel dimensions rather than the text inside it, and dense content (code, JSON, tool output) packs about 3.1 characters per image-token versus about 1 character per text-token on real Claude Code traffic. At current Fable list prices this measures as roughly a 59-70% lower end-to-end bill, tracked per-request against a free count_tokens counterfactual logged to ~/.pxpipe/events.jsonl.
Running it is one command: npx pxpipe-proxy starts the proxy on 127.0.0.1:47821, then ANTHROPIC_BASE_URL=http://127.0.0.1:47821 claude points Claude Code at it. A local dashboard shows tokens saved, every text-to-image conversion side by side, a kill switch, and live model chips. Responses stream normally - only the request is compressed, never the model's output - and recent turns stay as text while the system prompt, tool docs and older bulk history get imaged. pxpipe warp -- claude achieves the same thing without setting ANTHROPIC_BASE_URL, so /remote-control, claude.ai connectors and first-party gates keep working; a custom --route flag targets a non-default provider base URL. An offline export mode (pxpipe export) renders text, files or git diffs to PNG pages with no proxy running, for pasting into other image-upload clients.
It is explicitly disclosed as lossy: on a dense-hex exact-value test, Fable 5 scored 13/15 correct while Sol scored 0/15, and misses are silent confabulations rather than flagged errors - byte-exact values like IDs, hashes and secrets must stay as text, which recent turns already do, and a bounded factsheet selectively preserves up to 96 recognized precision-critical tokens rather than every identifier, and a dedicated verbatim-risk guard is not built yet. An escape hatch routes subagents on non-allowlisted models through as plain text for byte-exact work. Real-task evaluation: a SWE-bench Lite pilot scored 10/10 on both the pxpipe and text arms at -65% request size, and SWE-bench Pro scored 14/19 with pxpipe versus 15/19 with text at -60% request size, with verdicts agreeing on 18 of 19 tasks and the one disagreement re-resolving 3/3 identically on replication - read as run-to-run variance, not a compression-caused regression, though the sample size is small. Savings are workload-dependent: it wins on token-dense content (roughly 1 char/token) and loses money on sparse prose (roughly 3.5 chars/token), so a profitability gate calibrated on 391 production rows only images content where the math favors it. Savings are also client-dependent, since they track uncached bulk the client re-sends as text each turn; Claude Code re-sends system prompt, tools and history on every request and typically lands in the 60-70% range.
Default model scope is claude-fable-5 plus the gemini family (covering all Gemini IDs); Opus 5, Sol, GPT 5.5 and Grok are opt-in only via dashboard chips or PXPIPE_MODELS, and PXPIPE_MODELS=off disables imaging entirely with everything passing through byte-identical. Each model has its own measured rendering profile - Claude and Gemini use a 312-column, 1568x728, 5x8 Spleen bitmap font profile; opt-in Sol and Grok use a native 14px JetBrains Mono glyph profile at 84 columns - selected by exact model ID, since a sibling variant does not inherit another model's allowlist or render profile.
Benchmark receipts (measured on the shipped profiles, N sizes as tested): claude-fable-5 scores 100/100 arithmetic, 98/98 gist, 18/18 state, 0/16 never-stated confabulations, and 13/15 on dense hex recall; google/gemini-3.6-flash scores 100/100, 98/98, 18/18, 0/16 and 14/15 on the same tests; claude-opus-5 scores 100/100, 94/98, 17/18, 0/16 and 2/15. A capacity measurement rendering a dense fixture through each model's real pipeline found claude-fable-5[1m]'s 1M-token window holds about 18.9M characters through pxpipe images versus about 4.0M as plain text (roughly 4.7x), and google/gemini-3.6-flash holds about 20.1M characters (roughly 5.0x).
Architecturally, the proxy handles Anthropic Messages, OpenAI Responses/Chat Completions and Google generateContent requests: it rewrites eligible bulk content into image blocks and forwards the provider-native request (or bridges Anthropic Messages to a configured OpenAI-compatible provider), preserving the static prefix and prompt-cache boundary on Anthropic. It's also usable as a library with no proxy (renderTextToImages, transformAnthropicMessages from pxpipe-proxy, pure-JS runtime on Node or edge/Workers), and pxpipe stats summarizes the event log offline into a measured-savings report.
Two smaller disclosed limits: PNG encoding adds latency to large requests before they leave the machine, and while ASCII/Latin-1 text is well tested, CJK text renders correctly but is only conservatively tested.
When to use - and when NOT to
Use it to reduce Claude Code's (or another supported client's) input token cost when working with token-dense bulk context - code, JSON, tool output, long system prompts - that the client re-sends as text on every turn. It loses money on sparse prose workloads and is lossy for byte-exact values (IDs, hashes, secrets), which should stay routed as text via its escape hatch for subagents on non-allowlisted models.
Integrations
It runs as a local reverse proxy in front of Claude Code, Cursor Agent, Codex or any client via ANTHROPIC_BASE_URL or pxpipe warp, and exposes a JS/TS library API (pxpipe-proxy) for direct use with no proxy.
It is MIT licensed.
Who it's for
It suits developers running Claude Code or similar agentic CLIs against token-dense repositories who want a measured, per-request reduction in input token cost without changing their workflow.
Source README
pxpipe
Cut Claude Code's input tokens by rendering bulky context as images - the same system prompt, tool docs, and history, in a fraction of the tokens.
An image's token cost is fixed by its pixel dimensions, not by how much text
is inside it. Dense content (code, JSON, tool output) packs 3.1 chars per
image-token vs ~1 char per text-token on real Claude Code traffic. The
reader is the same vision channel that Anthropic's computer use already
relies on for screenshots. pxpipe is a local proxy that uses that channel
for context: it rewrites the bulky parts of each request into compact PNGs
before it leaves your machine. At current Fable
list prices that lands as a **59-70% lower end-to-end bill** - but prices
move and workloads differ, so the durable number is the token cut itself,
measured per-request against a free count_tokens counterfactual in
~/.pxpipe/events.jsonl.
This is what the model sees instead of text:
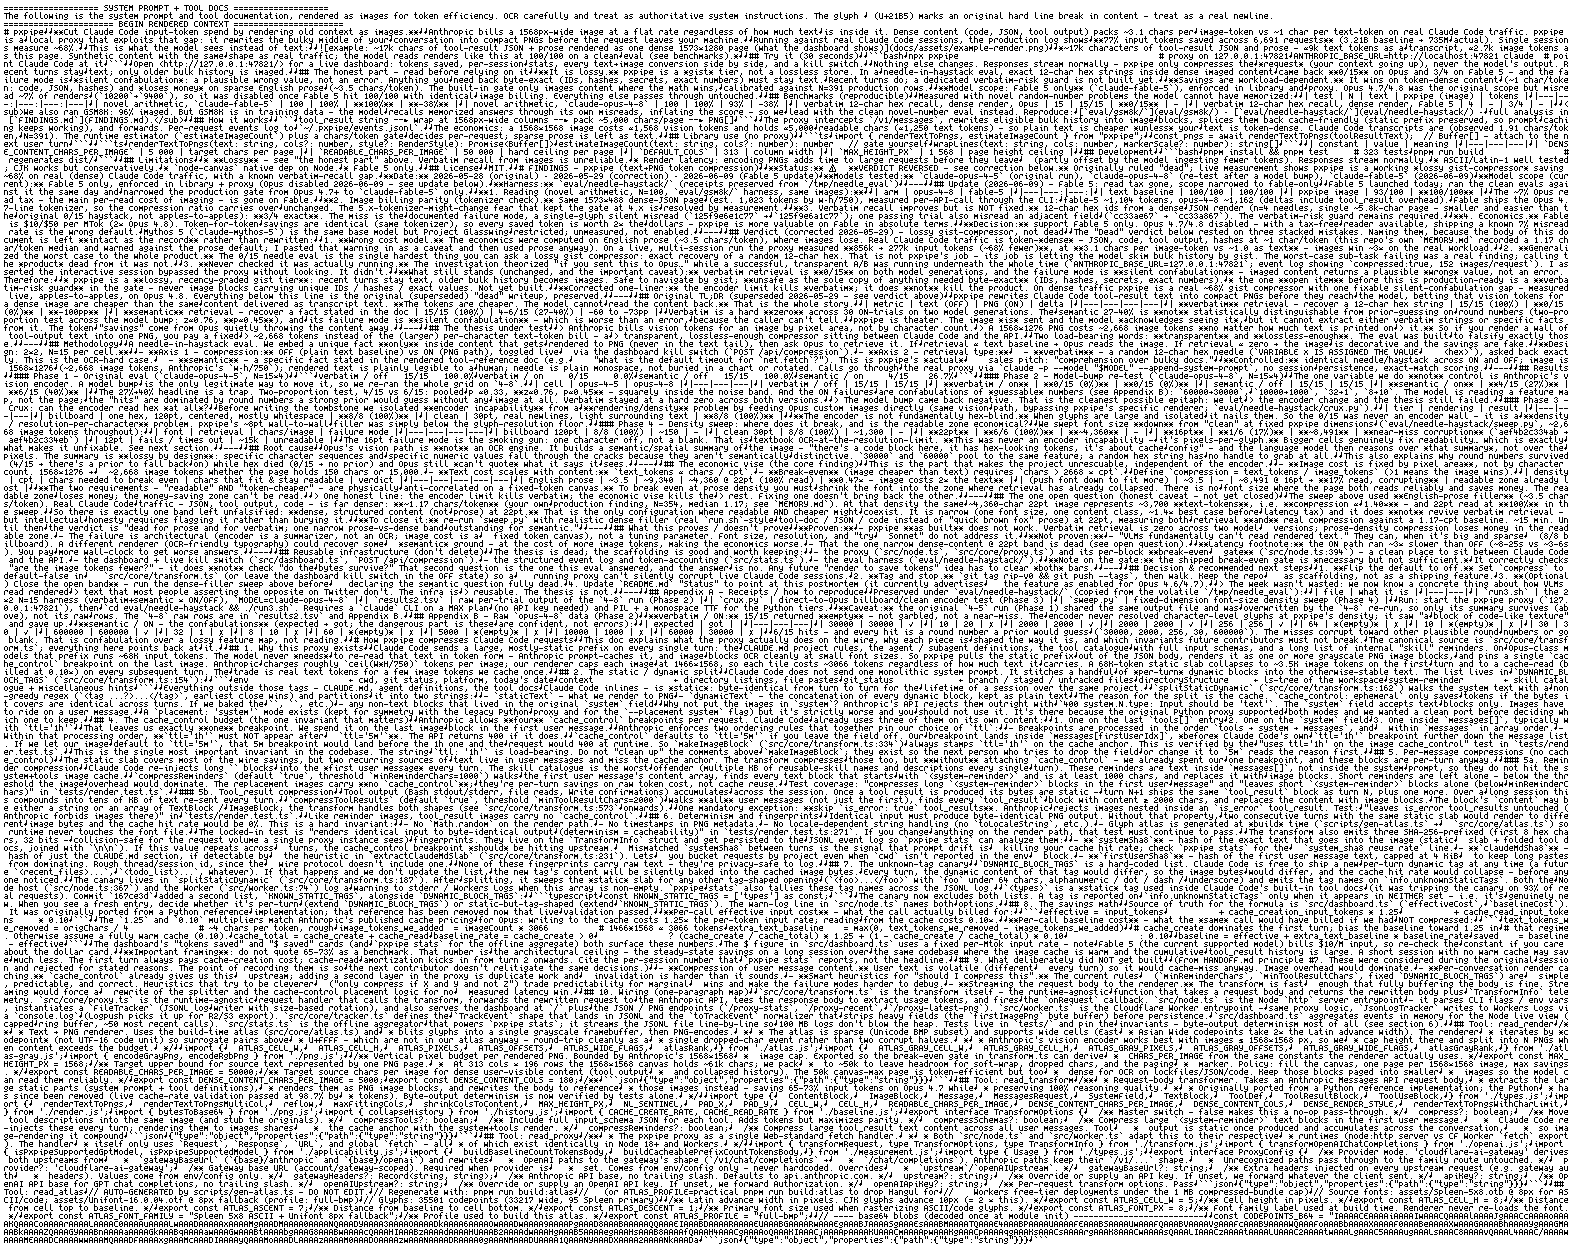
~48k chars of system prompt + tool docs: ≈25k tokens as text, ≈2.7k image tokens as this page. Real pipeline output; the model reads renders like this at 100/100 (see benchmarks).

*Eight years of context growth, in characters. Every text line tops out near
~4M chars (a 1M-token window at ~4 chars/token); Grok 4.5 is shown as a
text-window point only (500K). The orange overlays are the same 1M
windows read through pxpipe images - ~19.0M chars for Fable 5 (4.8×) and ~21.3M chars for Gemini 3.6 Flash (5.3× text capacity). Density is measured from a live render at
generation time, not hand-typed: regenerate with
npx tsx scripts/gen-context-chart.ts
(source).*
Demo
Fable 5 (the default, 100/100 reader) - plain left, pxpipe right:
https://github.com/user-attachments/assets/1c8ee63a-fcd7-4958-917b-da788d718349
pxpipe counts an exact token 10/10 across 39 imaged filler files
(matches grep line-for-line), gets the multi-step ledger arithmetic right,
and ends the session at $6.06 with context to spare (73.5k/1M) vs
$42.21 at 96% full. One caveat visible in the clip: the pxpipe arm
needed a nudge to match the requested one-line output format.
Try it (30 seconds)
npx pxpipe-proxy                                  # proxy on 127.0.0.1:47821
ANTHROPIC_BASE_URL=http://127.0.0.1:47821 claude  # point Claude Code at it
Dashboard at http://127.0.0.1:47821/: tokens saved, every text→image conversion side by side, kill switch, live model chips. Responses stream normally - pxpipe compresses the request only, never the model's output. Recent turns stay text; the system prompt, tool docs, and older bulk history are imaged.
pxpipe warp
pxpipe warp -- claude # also: cursor-agent, codex, or a shell alias
Same thing without ANTHROPIC_BASE_URL, so /remote-control, claude.ai
connectors, and first-party gates keep working. Full instructions in the
dashboard.
api.anthropic.com/v1/messages is routed by default. Agents that reach their
provider over some other base URL need a rule for it, and a rule that names a
port matches only that port:
pxpipe warp --route '127.0.0.1:9090/v1/*=http://127.0.0.1:47821' -- codex
Offline export (no proxy)
You can render text, files, or diffs to PNG pages without running the proxy or connecting Claude Code:
npx pxpipe-proxy export src/
cat prompt.txt | npx pxpipe-proxy export --stdin
npx pxpipe-proxy export --git
If the package is installed, use pxpipe export instead of
npx pxpipe-proxy export.
Each run writes a fresh pxpipe-export-XXXXXX/ output folder (the exact path
is printed when the command finishes) containing page-*.png, factsheet.txt,
manifest.json, and prompt.txt. Upload the PNG pages and paste the prompt
into image-upload clients such as Cursor when you want dense visual context
without running the proxy.
The honest part
It is lossy. Exact 12-char hex strings in dense imaged content: 13/15 on Fable 5 and 0/15 on Sol - misses are silent confabulations, not errors. Byte-exact values (IDs, hashes, secrets) must stay text; recent turns do. The factsheet selectively preserves up to 96 recognized precision-critical tokens, not every identifier. A dedicated verbatim-risk guard is not built yet.
Escape hatch: subagents on non-allowlisted models pass through as text - route byte-exact work there (
CLAUDE_CODE_SUBAGENT_MODEL=claude-sonnet-4-6, ormodel: sonnetin agent frontmatter).Real work: SWE-bench Lite pilot 10/10 both arms at −65% request size; SWE-bench Pro 14/19 ON vs 15/19 OFF at −60%, verdicts agree 18/19, and the single split re-resolved 3/3 on replication - run-to-run variance, not compression. Small n; receipts in
eval/.Workload-dependent. Wins on token-dense content (
1 char/token), loses money on sparse prose (3.5 chars/token); a profitability gate (calibrated on N=391 production rows) images only where the math wins.Client-dependent. Savings track uncached bulk the client still re-sends as text. Claude Code re-sends system + tools + history on
/anthropic/messagesand typically lands ~60-70%. Details and measured splits: docs/CACHING_AND_SAVINGS.md.claude-opus-5: weaker recall than Fable 5 (verbatim 2/15 vs 13/15), good enough otherwise (100/100 arithmetic, 0/16 never-stated), ~4.7× context before/compact. Suggested effort: medium. Details: FINDINGS.md.claude-opus-5-5: on by default. Uses 5×8 with 2px extra row height (~25% more image tokens than Fable's layout, still ~50%+ live savings). Exact hex recall is weak (3/15); re-fetch exact ids.Model scope: default
PXPIPE_MODELS=claude-fable-5,claude-opus-5-5,gemini. Thegeminibase covers every Gemini id (3.6/3.7/3.8 Flash, Pro, 4, 5, and future versions); to opt Gemini out, dropgeminifromPXPIPE_MODELSor click the chip off. Opus 5, Sol, GPT 5.5, and Grok are opt-in only (dashboard chips orPXPIPE_MODELS). The exact Sol id still matters. Sibling variants such asgpt-5.6-terrado not inherit Sol's allowlist or render profile.PXPIPE_MODELS=offdisables imaging. Everything else passes through byte-identical. On the GPT path, tool definitions stay native JSON and no Anthropiccache_controlmarkers are used. Responses history compression recognizes completedfunction_call/function_call_outputpairs, including OpenCode's parallel calls-then-outputs rounds: only old closed rounds are imaged atomically; every open call and malformed/orphan state remains native. The base profile keeps the newest six completed pairs and allows 32 images; Sol keeps one pair and allows 64 images, while Grok allows 24 images. Opt-in long-session coverage can be changed (defensive cap 100) withPXPIPE_GPT_HISTORY_MAX_IMAGES=48after validating the provider's request cap.Per-model rendering: opt-in
gpt-5.6-soland Grok use native 14px JetBrains Mono glyphs in a 9×16 cell, 84 columns, and a 764px full-width strip; Claude keeps its 312-column, 1568×728 5×8 Spleen profile. These are selected by exact model id, including history pages and profitability math. Recognized IDs can ride in the bounded factsheet, and recent/open tool state stays native. Sol receipts and profile evidence.Grok 4.5 / 4.6 (opt-in): native 14px / 84 cols / maxH 512 (100/100 arith, 97/98 gist). Off by default (dense hex still 0/15). History uses mixed collapse so Codex assistant messages between tool rounds still image. Enable with
PXPIPE_MODELS=claude-fable-5,grok-4.6or the dashboard chip. eval/grok-density/QUALITY_RESULTS.md.
Benchmark results and receipts
Model quality
This matrix shows coverage as well as scores. — means the model was not run
on that test; it does not mean zero. Arithmetic uses novel random-number
problems. Gist, state, and never-stated probes share one corpus. Never-stated
is confabulations, so lower is better. The numbers at column is the render
geometry the row's scores were measured at; a model's shipped profile can
differ (Sol and Qwen ship the measured 14px/84 geometry, but their broad-suite
numbers predate it).
| model | numbers at | arithmetic (N=100) | gist (N=98) | state (N=18) | never-stated (N=16) | dense hex (N=15) | profile provenance and receipts |
|---|---|---|---|---|---|---|---|
claude-fable-5 |
Spleen 5×8, 312 cols (shipped) | 100/100 | 98/98 | 18/18 | 0/16 | 13/15 | June 2026 production profiles: arithmetic + hex, gist/state/guards |
claude-fable-5-1 |
Spleen 5×8, 312 cols (Fable 5 profile) | 100/100 | 95/98 | 18/18 | 0/16 | 6/15 | Fable 5 profile, no geometry of its own; 3 gist misses are image-arm negation flags answered UNKNOWN (0 confabs). Same-day Fable 5 control on the identical harness/PNGs reproduced 100/100 arithmetic and 30/30 tier-2 gist, so the gist/hex gap is the model, not the harness (hex control not rerun): arithmetic, dense hex, gist/state/guards |
google/gemini-3.6-flash, 3.7-flash |
Spleen 5×8, 312 cols (shipped) | 100/100 | 98/98 | 18/18 | 0/16 | 14/15 | current shipped profile: quality results |
claude-opus-5 |
Spleen 5×8, 312 cols (shipped) | 100/100 | 94/98 | 17/18 | 0/16 | 2/15 | current profile: arithmetic, gist/state/guards, dense hex |
claude-opus-5-5 (default) |
Spleen 5×8, 312 cols, +2px rows | 100/100 | 94/98 | 17/18 | 0/16 | 3/15 | spaced profile (Opus 5.5+); hex measured at dense geometry: arithmetic, gist/state/guards, dense hex |
claude-sonnet-5-5 (opt-in) |
Spleen 5×8, 312 cols, +2px rows | 100/100 | 85/98 | 12/18 | 0/16 | 2/15 | spaced profile, opt-in via PXPIPE_MODELS; 6 state misses are wrong final values/counts, 7 gist misses answered UNKNOWN: arithmetic, gist/state/guards, dense hex |
gpt-5.6-sol |
Spleen 5×8, 152 cols; ships 14px/84 | 98/100 | 83/98 | 17/18 | 4/16 | 0/15 | broad suite predates the shipped 14px profile; 14px pilot: 7/8 exact, 0 inventions, gist/guard pass: pilot |
claude-opus-4-8 |
Spleen 5×8, 312 cols (historical) | 93/100 | 77/98 | 18/18 | 0/16 | 0/15 | historical profile: arithmetic, gist/state/guards, dense hex |
grok-4.5 |
JetBrains Mono 14px, 84 cols (shipped) | 100/100 | 97/98 | 17/18 | 0/16 | 0/15 | native 14px/84 quality suite (live profile); quality, native-sweep |
grok-4.6 high |
JetBrains Mono 14px, 84 cols (shipped) | 100/100 | 97/98 | 17/18 | 0/16 | 0/15 | native 14px/84, reasoning high; quality |
moonshotai/kimi-k3 |
Spleen 5×8, 152 cols (generic default) | 79/100 | 84/98 | 15/18 | 1/16 | 0/15 | generic GPT profile, no measured geometry of its own: quality results |
qwen-3.8 (@cf/qwen/qwen3.8-27b) |
Spleen 5×8, 152 cols; ships 14px/84 | 98/100 | 72/98 | 11/18 | 0/16 | 0/15 | broad suite predates the shipped 14px profile; 14px pilot: 8/8 exact, 0 inventions, 11/15 hex: pilot & quality |
glm-5.3-flash (@cf/zai-org/glm-5.3-flash) |
Spleen 5×8, 152 cols (default fallback, nothing shipped) | 36/100 | 57/98 | 6/18 | 0/16 | 0/15 | 5×8 is illegible to GLM (0/15 hex); 14px pilot: 10/15 hex, all misses single-glyph confabs, guards 0/16: pilot & quality |
Native-profile cost check
Offline export of the same deterministic 454,045-character dense record corpus through each complete profile produced:
| model profile | pages | text estimate | image tokens | savings |
|---|---|---|---|---|
| Claude, Spleen 5×8 | 17 | 122,715 | 23,856 | 80.6% |
| Sol, JetBrains Mono 14px | 45 | 122,715 | 65,424 | 46.7% |
The text estimate uses 3.7 characters/token; image tokens use each model's provider formula and actual rendered page dimensions. These figures establish profile cost on this corpus, not a universal workload savings rate. Sol's paid fixtures estimated 42% while reading 7/8 exact with no unsupported inventions.
The runs use different transports and profile generations, not one identical image geometry. Fable and Opus use Claude; Gemini uses Google AI Studio; Sol and Grok use Codex Responses; Kimi K3 uses Cloudflare's OpenAI-compatible transport. Current production profiles include the adjacent bounded factsheet; historical or pure-image exceptions are identified in the linked evaluation.
Model-specific evaluations
These are not cross-model comparisons. Every unlisted model is not run.
| test | model | result | evaluation and receipts |
|---|---|---|---|
| SWE-bench Lite | claude-fable-5 |
pxpipe 10/10; text 10/10; −65% request size | paired pilot |
| SWE-bench Pro | claude-fable-5 |
pxpipe 14/19; text 15/19; −60% request size | paired pilot |
| production-history row localization | google/gemini-3.6-flash |
text 17/30; pxpipe 18/30 | positional retrieval |
| production-history exact row | google/gemini-3.6-flash |
text 3/30; pxpipe 3/30 | positional retrieval |
The SWE-bench runner is Claude Code/Fable-specific; no other model has an ON/OFF run. Gemini's positional-retrieval sweep is directional evidence, not a general Lost-in-the-Middle result.
Capacity / density (how many chars per vision-token?)
Measured by rendering this repo’s dense fixture through the real pipeline and pricing pixels at each family’s vision rate. Multiplier = measured chars/vision-token ÷ 4 (prose text baseline). Not a model-quality score.
| family | window | as text (@4 c/tok) | as pxpipe images | density | multiplier |
|---|---|---|---|---|---|
claude-fable-5[1m] (default) |
1M | ~4.0M | ~18.9M | ~18.9 c/vt (exact 28px patches) | ~4.7× |
google/gemini-3.6-flash |
1M | ~4.0M | ~20.1M | ~20.1 c/vt (1,078 tok/page) | ~5.0× |
claude-opus-5 |
1M | ~4.0M | ~18.9M | ~18.9 c/vt (resolves to Fable 5’s geometry) | ~4.7× |
Regenerate: npx tsx scripts/gen-context-chart.ts · chart PNG
docs/assets/context-window-chars.png.

The older GSM8K result is omitted because its training-data contamination can hide image misreads; the linked arithmetic evaluations use novel numbers.
How it works
model id ──► render profile ──► wrap/reflow bulk context ──► PNG[] + bounded factsheet
The proxy handles Anthropic Messages, OpenAI Responses and Chat Completions,
and Google generateContent requests. It rewrites eligible bulk into image
blocks and forwards the provider-native request, or bridges Anthropic Messages
to a configured OpenAI-compatible provider. On Anthropic, the static prefix and
prompt-cache boundary are preserved. Model-specific profiles control geometry,
factsheets, history retention, and profitability, so sparse prose stays text.
Events log to ~/.pxpipe/events.jsonl.
Library use (no proxy)
import { renderTextToImages, transformAnthropicMessages } from "pxpipe-proxy";

const { pages } = await renderTextToImages(toolResultText);     // pages[i].png: Uint8Array
const { body, applied, info } = await transformAnthropicMessages({
  body: requestBytes,
  model: "claude-fable-5",
});
options.keepSharp(block) pins blocks as text; options.emitRecoverable
returns the originals of imaged blocks. Pure-JS runtime (Node and
edge/Workers); @napi-rs/canvas is build-time only. Full API:
src/core/index.ts.
The live dashboard shows savings while the proxy is running. To read the same event log after the fact - with no server up - summarize it straight from disk:
pxpipe stats                   # human report from ~/.pxpipe/events.jsonl
pxpipe stats --json            # same aggregate as machine-readable JSON
pxpipe stats --file /path/to/events.jsonl
Alongside request counts, compression ratios, latency percentiles, and
cache-hit rates, the report prints a measured savings headline -
count_tokens of the original body versus real usage, over probe-measured rows
only (unmeasured requests are excluded, never counted as zero). This is a
raw-token figure (cache reads at face value, not cost-weighted), so it is
deliberately a different quantity from the dashboard's cost-weighted saved %.
Point it at a non-default log with --file, or set PXPIPE_LOG.
Exit codes: 0 report printed, 1 events file not found, 2 file present but
no valid events. pxpipe stats --help prints usage.
Development
pnpm install && pnpm test
pnpm run build                # regenerates dist/
Windows is community-supported: primary development targets macOS/Linux, and Windows-specific fixes rely on contributor PRs (thanks @makoribrian).
FAQ
End-to-end, the whole bill. Most compression tools report savings only on
the input slice they touched, which flatters the number. The end-to-end
denominator is every production request: the small ones pxpipe correctly
left untouched, all cache writes and reads, and all output tokens (which the
proxy never compresses). On a 13,709-request snapshot that was 59% ($100 →
$41); a later 8,904-compressed-request trace measured ~70%. Compressed-only
runs higher (72-74%) and is quoted separately, never as the headline. The
exact figure is workload-dependent - reproduce it on your own log.
Both sides of the same request, at the same moment. For every /v1/messages
POST the proxy fires a free count_tokens probe on the original uncompressed
body (the counterfactual) in parallel with the real forward, and reads
Anthropic's actually-billed usage block off the response. Both land in the
same row of ~/.pxpipe/events.jsonl, so there is no turn-count or
run-to-run confound. Dollar conversion uses Fable 5 list ratios: input ×1.0,
cache write ×1.25, cache read ×0.1, output ×5. Cache pricing is applied
identically to both sides, so the caching discount cancels and cannot be
double-counted as "savings". Re-derive it yourself from the events log: the
formula and field names are documented in src/core/baseline.ts.
Three kinds of input blocks, each behind a profitability gate:
- large
tool_resultbodies (file reads, command output, logs) above ~6k chars of token-dense content - older collapsed history: turns behind the live tail get re-rendered as image pages, recent turns always stay text
- the static cacheable system prompt + tool docs slab; appended non-cacheable system blocks stay live text so host custom instructions keep system-level salience
Everything else passes through byte-identical: your messages, recent turns, the model's output (it is the response, the proxy never touches it), sparse prose, and anything too small to win. Model defaults and detailed results are listed under model support and benchmarks.
Yes, once in weeks of daily use: the model recalled a person's name from imaged chat history and got it confidently wrong. No error, just a plausible wrong name. That is the documented failure mode: exact strings in imaged content are not byte-safe. Coding sessions tolerate this because the agent re-reads files before editing; pure chat recall has no such check. This failure mode is measured, not anecdotal: the legibility audit quantifies exact-string recall off rendered pages (blind reads top out at 63% on dense identifiers, with every miss predicted by a glyph-confusability matrix) and documents the shipped mitigations - page geometry clamped to the API's resample cap so billed pixels actually reach the vision encoder, and selected identifiers (SHAs, numbers) riding alongside as text.
Because model vision is not OCR: the image becomes patch embeddings, never discrete characters, so there is no per-glyph confidence to fail loudly on. When pixels underdetermine a glyph, the language prior fills the gap with something plausible. Mechanism and receipts: docs/NOT-OCR.md.
No: it proved the channel works, using an encoder/decoder pair trained for the job. The skepticism dates from October 2025, when no stock production model could read dense renders; that changed with Fable 5 (0/15 verbatim hex on the prior Opus generation vs 13/15 on Fable 5, same pages). Timeline and per-model numbers: docs/NOT-OCR.md.
Because one did. Most of this repo's commits - the code and the docs - were authored by Opus/Fable agent sessions running behind pxpipe itself, reading their own collapsed history as image pages while they worked.
Additional limitations
- PNG encoding adds latency to large requests before they leave.
- ASCII/Latin-1 well tested; CJK works but conservatively.
Research status
Current as of 2026-07-22. The broad conclusion from the 2026-07-05 pass still
holds: exact recall is limited by pixels per glyph, so rendering changes do not
eliminate errors at profitable density. A later glyph-style A/B did find a
useful local improvement: repainting K reduced Fable's H/K error from 47.2%
to 18.7% without changing geometry or token cost. It shipped, but exact control
IDs did not improve. See FINDINGS.md, 2026-07-19 entry.
Runtime canary + text re-fetch and surrogate-reader pre-flight remain untested. The release tripwire remains a resolution sweep for each new model; a model that reads production cells near 100% would permit higher density.
Effective-context benefits remain unproven. The production-history results above are directional evidence, not a general context-window or long-task accuracy claim.
Community projects
Third-party projects listed here are not maintained or supported by pxpipe.
- pxpipe-windows - Windows support for
pxpipe mitm(node-forge CA in place of openssl, Task Scheduler autostart). - OmniGlyph - A community-maintained project derived from pxpipe and used by OmniRoute.
- pxpipe-go - A Go port of pxpipe's core with a CLI wrapper, standalone proxy, and embeddable library for Anthropic Messages and OpenAI Chat/Responses.
scripts/gen-context-chart.ts
/**
 * gen-context-chart.ts — README chart: how many *characters* a frontier context
 * window has held over time, GPT-1 (2018) → Fable 5 / Grok 4.5 (2026), as a
 * line chart on a real year axis. One pxpipe overlay is measured live for
 * Fable (the default reader); Grok appears as a plain text-window series only
 * (opt-in, not Fable-level pure-image quality).
 *
 *   npx tsx scripts/gen-context-chart.ts
 *
 * Writes docs/assets/context-window-chars.png and prints the data table.
 *
 * Method
 *  - Text points: window tokens × 4 chars/token (the standard English-prose
 *    rule of thumb; token-dense content like code/JSON tokenizes *worse*,
 *    ~2-2.5, so 4 is the generous assumption for the text series).
 *  - pxpipe points: window tokens × measured chars-per-vision-token using the
 *    shipped 312-column geometry and each provider's image-token accounting.
 *
 * Window sizes (announcement-era frontier defaults), with release dates used
 * for x-axis placement:
 *   GPT-1 512 (Jun 2018, Radford et al.) · GPT-2 1,024 (Feb 2019) · GPT-3
 *   2,048 (May 2020, Brown et al.) · GPT-3.5/ChatGPT 4,096 (Nov 2022) · GPT-4
 *   8,192 base (Mar 2023) · Claude 2 100K (Jul 2023) · GPT-4 Turbo 128K (Nov
 *   2023) · Claude 2.1 200K (Nov 2023) · Gemini 1.5 Pro 1M (Feb 2024) ·
 *   GPT-4.1 1,047,576 (Apr 2025) · Fable 5 200K standard, 1M as
 *   claude-fable-5[1m] (2026) · Grok 4.5 500K (2026, xAI maxPromptLength).
 */
import { readFileSync, writeFileSync, mkdirSync } from 'node:fs';
import { dirname, join } from 'node:path';
import { fileURLToPath } from 'node:url';
import { createCanvas } from '@napi-rs/canvas';
import { renderTextToImages } from '../src/core/library.js';
import type {
  RenderTextToImagesOptions,
  RenderTextToImagesResult,
} from '../src/core/library.js';
import { resolveGptProfile } from '../src/core/gpt-model-profiles.js';
import { patchTokens } from '../src/core/anthropic-vision.js';

const ROOT = join(dirname(fileURLToPath(import.meta.url)), '..');
const OUT = join(ROOT, 'docs/assets/context-window-chars.png');
const README_EXAMPLE = join(ROOT, 'docs/assets/example-render.png');

const TEXT_CPT = 4; // chars per text token, prose rule of thumb
const GEMINI_TOKENS_PER_FULL_PAGE = 1078; // measured at 1568x728

interface Density {
  /** chars per vision-token for this family's render+billing profile */
  cpt: number;
  pages: number;
  pixels: number;
  visionTokens: number;
}

// ---------------------------------------------------------------------------
// 1. Measure chars-per-vision-token through the real pipeline.
// ---------------------------------------------------------------------------
function loadFixture(): string {
  // Representative token-dense context — the kinds of content pxpipe actually
  // images (markdown docs, TS source, JSON), taken from this repo itself.
  // Literal ↵ sentinels are stripped: these files *document* the sentinel, and
  // reflow() deliberately bails on source that already contains it.
  return [
    readFileSync(join(ROOT, 'README.md'), 'utf8'),
    readFileSync(join(ROOT, 'docs/CACHING_AND_SAVINGS.md'), 'utf8'),
    readFileSync(join(ROOT, 'src/core/library.ts'), 'utf8'),
    readFileSync(join(ROOT, 'package.json'), 'utf8'),
  ]
    .join('\n\n')
    .replaceAll('↵', '');
}

/** Render the fixture under one model's geometry and report its density.
 *  `countTokens` differs by provider: Anthropic bills 28-px patches, Gemini a flat
 *  rate per full page. Default geometry is the library's Claude dense path
 *  (312-col Spleen, Anthropic height). */
async function measureDensity(
  label: string,
  fixture: string,
  countTokens: (pages: RenderTextToImagesResult['pages']) => number,
  geometry: RenderTextToImagesOptions = {},
): Promise<Density> {
  const r = await renderTextToImages(fixture, { reflow: true, ...geometry });
  if (r.droppedChars > 0) {
    throw new Error(
      `${label} fixture dropped ${r.droppedChars} chars — atlas gap, fix before charting`,
    );
  }
  const visionTokens = countTokens(r.pages);
  const cpt = fixture.length / visionTokens;
  console.log(
    `${label} density: ${fixture.length} chars → ${r.pages.length} pages, ` +
      `${r.pixels} px = ${visionTokens} vision tokens → ${cpt.toFixed(2)} chars/vision-token`,
  );
  return { cpt, pages: r.pages.length, pixels: r.pixels, visionTokens };
}

const patchTokenCount = (pages: RenderTextToImagesResult['pages']): number =>
  pages.reduce((total, page) => total + patchTokens(page.width, page.height), 0);


// ---------------------------------------------------------------------------
// 2. Data
// ---------------------------------------------------------------------------
type LabelSide = 'above' | 'below' | 'left' | 'right';

interface Point {
  name: string;
  /** Release date as fractional year — x position. */
  x: number;
  /** Model context window, in tokens. */
  tokens: number;
  chars: number;
  /** Vendor series — each gets its own line. 'pxpipe' is a measured overlay. */
  kind: 'openai' | 'gemini' | 'claude' | 'grok' | 'pxpipe';
  /** Where to hang the label so the cluttered 2023 cluster stays readable. */
  label: LabelSide;
  /** Extra vertical label offset (px) — staggers the linear-scale floor pileup. */
  dy?: number;
}

function points(fableCpt: number, geminiCpt: number, opusCpt: number): Point[] {
  const t = (
    kind: Point['kind'],
    name: string,
    x: number,
    tokens: number,
    label: LabelSide,
    dy?: number,
  ): Point => ({ name, x, tokens, chars: tokens * TEXT_CPT, kind, label, dy });
  return [
    t('openai', 'GPT-1', 2018.45, 512, 'above'),
    t('openai', 'GPT-2', 2019.12, 1_024, 'above', -36),
    t('openai', 'GPT-3', 2020.4, 2_048, 'above'),
    t('openai', 'GPT-3.5', 2022.91, 4_096, 'above', -36),
    t('openai', 'GPT-4', 2023.2, 8_192, 'right'),
    t('claude', 'Claude 2', 2023.53, 100_000, 'left', -14),
    t('openai', 'GPT-4 Turbo', 2023.85, 128_000, 'right', -26),
    t('claude', 'Claude 2.1', 2023.89, 200_000, 'above', -30),
    t('gemini', 'Gemini 1.0 Pro', 2023.93, 32_768, 'right', 4),
    // Feb '24: 128K standard / 1M limited preview; 1M GA May 23, 2024; 2M opened
    // to all developers June 27, 2024 — plotted at its 2M peak. The 2M window
    // retired with 1.5's deprecation (2.5 Pro shipped 1M), so the line dips.
    t('gemini', 'Gemini 1.5 Pro', 2024.49, 2_097_152, 'left'),
    t('openai', 'GPT-4.1', 2025.28, 1_047_576, 'below'),
    // Gemini 2.5 Pro: 1M window, GA at Google I/O May 20, 2025
    t('gemini', 'Gemini 2.5 Pro', 2025.38, 1_000_000, 'above'),
    // Sonnet 4: 1M public beta (Tier 4) Aug 12, 2025 — Anthropic's first 1M;
    // beta retired Apr 30, 2026 as 1M became standard on newer models
    t('claude', 'Sonnet 4 [1m]', 2025.61, 1_000_000, 'below', 36),
    // GPT-5.6 (Sol/Terra/Luna): GA July 9, 2026 — API docs list 1.05M ctx (1.5M was a pre-launch leak)
    t('openai', 'GPT-5.6', 2026.52, 1_050_000, 'right'),
    // the model powering this session: claude-fable-5[1m], 1M-token window
    t('claude', 'Fable 5 [1m]', 2026.05, 1_000_000, 'below'),
    // Gemini 3.6 Flash 1M window
    t('gemini', 'Gemini 3.6 Flash', 2026.50, 1_000_000, 'below'),
    // Grok 4.5: text-window only (opt-in; no pxpipe overlay on this chart).
    // Window = xAI docs maxPromptLength for grok-4.5 (500000).
    t('grok', 'Grok 4.5', 2026.42, 500_000, 'below', 10),
    // Claude Opus 5: released July 25, 2026. Window = 1M tokens per Anthropic
    // models overview (tooltip: ~555k words / ~2.5M unicode characters).
    // The ID is dateless (`claude-opus-5`) — the 4.6-generation convention drops
    // the YYYYMMDD snapshot — so the date comes from the release, not the ID.
    t('claude', 'Opus 5', 2026.56, 1_000_000, 'above', -18),
    {
      name: 'Fable 5 [1m] + pxpipe',
      x: 2026.05,
      tokens: 1_000_000,
      chars: Math.round(1_000_000 * fableCpt),
      kind: 'pxpipe',
      label: 'above',
    },
    {
      name: 'Gemini 3.6 Flash + pxpipe',
      x: 2026.50,
      tokens: 1_000_000,
      chars: Math.round(1_000_000 * geminiCpt),
      kind: 'pxpipe',
      label: 'above',
    },
    {
      // Measures identical to Fable 5 (same resolved profile geometry), so this
      // lands on the same horizontal line — that equality is the finding, not a
      // copy: opusCpt comes from its own render pass.
      name: 'Opus 5 + pxpipe',
      x: 2026.56,
      tokens: 1_000_000,
      chars: Math.round(1_000_000 * opusCpt),
      kind: 'pxpipe',
      label: 'above',
    },
  ];
}

const fmt = (v: number): string =>
  v >= 1e6
    ? `${+(v / 1e6).toFixed(v >= 1e7 ? 0 : 1)}M`
    : v >= 1e3
      ? `${+(v / 1e3).toFixed(v >= 1e4 ? 0 : 1)}K`
      : String(v);

/** Token windows read best in power-of-two units: 4,096 → "4K", 1,047,576 → "1M". */
const fmtTok = (t: number): string =>
  t >= 1e6
    ? `${Math.round(t / 1e6)}M`
    : t >= 1024
      ? t % 1024 === 0 && t < 10_000
        ? `${t / 1024}K`
        : `${Math.round(t / 1e3)}K`
      : String(t);

// ---------------------------------------------------------------------------
// 3. Draw
// ---------------------------------------------------------------------------
function pngWidth(path: string): number {
  const png = readFileSync(path);
  if (png.length < 24 || png.toString('ascii', 1, 4) !== 'PNG') {
    throw new Error(`${path} is not a PNG`);
  }
  return png.readUInt32BE(16);
}

function draw(data: Point[], fableCpt: number, geminiCpt: number): Buffer {
  const logicalWidth = 1180;
  const logicalHeight = 1000;
  const outputWidth = pngWidth(README_EXAMPLE);
  const scale = outputWidth / logicalWidth;
  const canvas = createCanvas(outputWidth, Math.round(logicalHeight * scale));
  const ctx = canvas.getContext('2d');
  ctx.scale(scale, scale);

  const bg = '#0d1117';
  const grid = '#21262d';
  const axis = '#8b949e';
  const ink = '#e6edf3';
  const dim = '#8b949e';
  const colors: Record<Point['kind'], string> = {
    openai: '#10a37f',
    gemini: '#a371f7',
    claude: '#58a6ff',
    grok: '#e3b341',
    pxpipe: '#f0883e',
  };

  ctx.fillStyle = bg;
  ctx.fillRect(0, 0, 1180, 1000);

  // Title block
  ctx.fillStyle = ink;
  ctx.font = '600 24px sans-serif';
  ctx.fillText('Characters a frontier context window holds', 36, 44);
  ctx.fillStyle = dim;
  ctx.font = '400 14px sans-serif';
  ctx.fillText(
    `each point: model · context window (tokens) → characters it holds · text at ~${TEXT_CPT} chars/token · ` +
      `pxpipe uses shipped 312-column pages · Fable ${fableCpt.toFixed(1)} · Gemini ${geminiCpt.toFixed(1)} chars/vision-token`,
    36,
    68,
  );

  // Plot area
  const left = 76;
  const right = 1180 - 36;
  const top = 100;
  const bottom = 1000 - 72;
  // Linear scale — log gave every decade equal height, which flattened the whole
  // point of the chart: 18M must physically tower ~4.5× over the 4M pack.
  const Y_MAX = 24_000_000;
  const X_MIN = 2018;
  const X_MAX = 2027.25;
  const y = (v: number) => bottom - (v / Y_MAX) * (bottom - top);
  const x = (v: number) => left + ((v - X_MIN) / (X_MAX - X_MIN)) * (right - left);

  // Horizontal gridlines + y labels (every 2M — 18M lands exactly on a line)
  ctx.font = '400 13px sans-serif';
  for (let v = 0; v <= Y_MAX; v += 2_000_000) {
    const gy = y(v);
    ctx.strokeStyle = grid;
    ctx.lineWidth = 1;
    ctx.beginPath();
    ctx.moveTo(left, gy);
    ctx.lineTo(right, gy);
    ctx.stroke();
    ctx.fillStyle = axis;
    ctx.textAlign = 'right';
    ctx.fillText(fmt(v), left - 10, gy + 4);
  }

  // Vertical year gridlines + x labels
  ctx.textAlign = 'center';
  for (let yr = 2018; yr <= 2026; yr++) {
    const gx = x(yr);
    ctx.strokeStyle = grid;
    ctx.beginPath();
    ctx.moveTo(gx, top);
    ctx.lineTo(gx, bottom);
    ctx.stroke();
    ctx.fillStyle = axis;
    ctx.fillText(String(yr), gx, bottom + 24);
  }

  // Axis titles
  ctx.save();
  ctx.translate(20, (top + bottom) / 2);
  ctx.rotate(-Math.PI / 2);
  ctx.fillStyle = axis;
  ctx.fillText('characters (linear scale)', 0, 0);
  ctx.restore();
  ctx.fillStyle = axis;
  ctx.fillText('release year', (left + right) / 2, 1000 - 40);

  // One line per vendor series (chronological within each series)
  for (const vendor of ['openai', 'gemini', 'claude', 'grok'] as const) {
    const pts = data.filter((p) => p.kind === vendor);
    ctx.strokeStyle = colors[vendor];
    ctx.lineWidth = 2;
    ctx.beginPath();
    pts.forEach((p, i) => {
      if (i === 0) ctx.moveTo(x(p.x), y(p.chars));
      else ctx.lineTo(x(p.x), y(p.chars));
    });
    ctx.stroke();
  }

  // Dashed vertical connector: Fable / Gemini text window → same window imaged (pxpipe).
  // Grok is plotted as a text series only (no pxpipe overlay).
  const overlays: Array<{ textName: string; pxName: string }> = [
    { textName: 'Fable 5 [1m]', pxName: 'Fable 5 [1m] + pxpipe' },
    { textName: 'Gemini 3.6 Flash', pxName: 'Gemini 3.6 Flash + pxpipe' },
  ];
  for (const o of overlays) {
    const base = data.find((p) => p.name === o.textName)!;
    const px = data.find((p) => p.name === o.pxName)!;
    const cx = x(base.x); // same as x(px.x) — both points share the year
    const y0 = y(base.chars) - 7;
    const y1 = y(px.chars) + 8;
    ctx.strokeStyle = colors.pxpipe;
    ctx.lineWidth = 1.5;
    ctx.setLineDash([5, 4]);
    ctx.beginPath();
    ctx.moveTo(cx, y0);
    ctx.lineTo(cx, y1);
    ctx.stroke();
    ctx.setLineDash([]);
    ctx.textAlign = 'left';
    const annLine1 = `${(px.chars / base.chars).toFixed(1)}×`;
    const annLine2 = 'same window, imaged';
    const annX = cx + 12;
    const annY = (y0 + y1) / 2 + 4;
    ctx.lineJoin = 'round';
    ctx.strokeStyle = bg;
    ctx.lineWidth = 5;
    ctx.font = '700 15px sans-serif';
    ctx.strokeText(annLine1, annX, annY - 9);
    ctx.fillStyle = colors.pxpipe;
    ctx.fillText(annLine1, annX, annY - 9);
    ctx.font = '600 12px sans-serif';
    ctx.strokeText(annLine2, annX, annY + 9);
    ctx.fillText(annLine2, annX, annY + 9);
  }

  const emphasize = (p: Point): boolean =>
    p.kind === 'pxpipe' || p.name === 'Fable 5 [1m]' || p.name === 'Grok 4.5';

  // Markers first, so no marker is drawn over a neighbouring label.
  for (const p of data) {
    const cx = x(p.x);
    const cy = y(p.chars);
    ctx.beginPath();
    ctx.arc(cx, cy, emphasize(p) ? 6.5 : 4.5, 0, Math.PI * 2);
    ctx.fillStyle = colors[p.kind];
    ctx.fill();
    // Outer ring on pxpipe overlays so they read as measured, not vendor text.
    if (p.kind === 'pxpipe') {
      ctx.beginPath();
      ctx.arc(cx, cy, 9, 0, Math.PI * 2);
      ctx.strokeStyle = colors.pxpipe;
      ctx.lineWidth = 2;
      ctx.stroke();
    }
  }

  // Label placement. Labels are centred on their markers, so points that
  // coincide in value overprint each other: Fable 5 and Opus 5 resolve to the
  // same render geometry (identical chars), and Fable 5 / Gemini 3.6 Flash both
  // sit at 4M. Those markers are ~80px apart while the labels are ~180px wide.
  // Measure every box and push overlaps apart vertically, rather than hand-
  // tuning `dy` again each time a model is added.
  const LABEL_H = 31; // two baselines 15px apart + leading
  const placed = data.map((p) => {
    const cx = x(p.x);
    const cy = y(p.chars);
    const emphasized = emphasize(p);
    const line1 = p.name;
    // no " tok" — the subtitle defines the pattern, and the ~4M band is crowded
    const line2 = `${fmtTok(p.tokens)} → ${fmt(p.chars)} chars`;
    let lx = cx;
    let ly1: number;
    let align: CanvasTextAlign = 'center';
    let push = -1; // direction a label flees a collision
    switch (p.label) {
      case 'above':
        ly1 = cy - 28;
        break;
      case 'below':
        ly1 = cy + 22;
        push = 1;
        break;
      case 'left':
        lx = cx - 12;
        ly1 = cy - 3;
        align = 'right';
        break;
      case 'right':
        lx = cx + 12;
        ly1 = cy - 3;
        align = 'left';
        break;
    }
    ly1 += p.dy ?? 0;
    ctx.font = emphasized ? '700 14px sans-serif' : '600 13px sans-serif';
    const w1 = ctx.measureText(line1).width;
    ctx.font = '400 12px sans-serif';
    const w = Math.max(w1, ctx.measureText(line2).width);
    const x0 = align === 'center' ? lx - w / 2 : align === 'right' ? lx - w : lx;
    return { p, emphasized, line1, line2, lx, ly1, align, push, x0, x1: x0 + w };
  });

  // Greedy separation, repeated so a label pushed clear of one neighbour is
  // re-checked against the rest. Bounded: stops when stable.
  for (let pass = 0; pass < 8; pass++) {
    let moved = false;
    for (const a of placed) {
      for (const b of placed) {
        if (a === b) continue;
        if (a.x1 <= b.x0 + 2 || b.x1 <= a.x0 + 2) continue; // no x overlap
        if (Math.abs(a.ly1 - b.ly1) >= LABEL_H) continue; // no y overlap
        a.ly1 = b.ly1 + (a.push < 0 ? -LABEL_H : LABEL_H);
        moved = true;
      }
    }
    if (!moved) break;
  }

  for (const q of placed) {
    ctx.textAlign = q.align;
    // bg-colored glyph halo so crossing series lines never strike through text,
    // without erasing whole rectangles out of neighboring lines/labels
    ctx.lineJoin = 'round';
    ctx.strokeStyle = bg;
    ctx.lineWidth = 5;
    ctx.font = q.emphasized ? '700 14px sans-serif' : '600 13px sans-serif';
    ctx.strokeText(q.line1, q.lx, q.ly1);
    ctx.fillStyle = colors[q.p.kind];
    ctx.fillText(q.line1, q.lx, q.ly1);
    ctx.font = '400 12px sans-serif';
    ctx.strokeText(q.line2, q.lx, q.ly1 + 15);
    ctx.fillStyle = dim;
    ctx.fillText(q.line2, q.lx, q.ly1 + 15);
  }
  ctx.textAlign = 'left';

  // Legend (upper-left of plot — the lines hug the bottom there)
  const legend: Array<[string, string]> = [
    [colors.openai, `OpenAI · GPT — plain text @ ~${TEXT_CPT} chars/token`],
    [colors.gemini, 'Google · Gemini'],
    [colors.claude, 'Anthropic · Claude → Fable'],
    [colors.grok, 'xAI · Grok 4.5'],
    [colors.pxpipe, 'pxpipe images (measured overlays)'],
  ];
  ctx.font = '400 13px sans-serif';
  let ly = top + 20;
  for (const [c, label] of legend) {
    ctx.fillStyle = c;
    ctx.beginPath();
    ctx.arc(left + 22, ly - 4, 5.5, 0, Math.PI * 2);
    ctx.fill();
    ctx.fillStyle = ink;
    ctx.fillText(label, left + 36, ly);
    ly += 22;
  }

  // Footnote
  ctx.fillStyle = '#484f58';
  ctx.font = '400 12px sans-serif';
  ctx.fillText(
    `same ratio at any size: a standard 200K Fable 5 window × pxpipe ≈ ${fmt(Math.round(200_000 * fableCpt))} chars (vs 800K as text). Regenerate: npx tsx scripts/gen-context-chart.ts`,
    36,
    1000 - 14,
  );

  return canvas.toBuffer('image/png');
}

// ---------------------------------------------------------------------------
const fixture = loadFixture();
const fable = await measureDensity('Fable', fixture, patchTokenCount);
// Opus 5 is measured, not derived from Fable. Both resolve to CLAUDE_PROFILE
// today, so this returns the same cpt — but hardcoding `fable.cpt` would go stale
// if resolveClaudeProfile ever splits them. Render under the resolved geometry.
const opusProfile = resolveGptProfile('claude-opus-5');
const opus = await measureDensity('Opus', fixture, patchTokenCount, {
  cols: opusProfile.stripCols,
  maxHeightPx: opusProfile.maxHeightPx,
  style: opusProfile.style,
});
const gemini = await measureDensity(
  'Gemini',
  fixture,
  (pages) => pages.length * GEMINI_TOKENS_PER_FULL_PAGE,
);
const data = points(fable.cpt, gemini.cpt, opus.cpt);

console.log('\n  model                released   window (tokens)   chars in window');
for (const p of data) {
  console.log(
    `  ${p.name.padEnd(20)} ${String(Math.floor(p.x)).padEnd(10)} ${fmtTok(p.tokens).padStart(6)}            ${fmt(p.chars).padStart(6)}`,
  );
}
const fableText = data.find((p) => p.name === 'Fable 5 [1m]')!;
const fablePx = data.find((p) => p.name === 'Fable 5 [1m] + pxpipe')!;
const geminiText = data.find((p) => p.name === 'Gemini 3.6 Flash')!;
const geminiPx = data.find((p) => p.name === 'Gemini 3.6 Flash + pxpipe')!;

console.log(
  `\n  Fable pxpipe multiplier on the same window: ${(fablePx.chars / fableText.chars).toFixed(2)}×`,
);
console.log(
  `  Gemini 3.6 Flash pxpipe multiplier on the same window: ${(geminiPx.chars / geminiText.chars).toFixed(2)}×`,
);

mkdirSync(dirname(OUT), { recursive: true });
writeFileSync(OUT, draw(data, fable.cpt, gemini.cpt));
console.log(`\nwrote ${OUT}`);
FAQ
Common questions
Discussion
Questions & comments · 0
Sign In Sign in to leave a comment.