
Fine-tune and post-train LLMs with one command
One-command LLM fine-tuning CLI that trains an 8B model on a 4 GB laptop GPU via layer streaming.
0.75.2Add to Favorites
Why it matters
Simplify the entire LLM fine-tuning workflow into a single command and configuration file, eliminating infrastructure complexity, SSH debugging, and manual GPU configuration while enabling training on resource-constrained hardware through layer streaming and automatic quantization.
Outcomes
What it gets done
Stream model layers to train 8B models on 4GB laptop GPUs with bit-exact accuracy
Auto-detect GPU capabilities and configure batch size, quantization, and LoRA settings
Initialize training configs from templates and execute fine-tuning with one command
Deploy trained models locally or to cloud without manual infrastructure setup
Source
Get it from source
Spark does not host a copy of it.
Open sourceReports
Agent outcome reports
No reports yet
Overview
Soup is a one-command LLM fine-tuning and post-training CLI with a beta layer-streaming feature that trains an 8B model on a 4 GB laptop GPU, plus a local web UI, model export, and serving. Use it to fine-tune or post-train an open LLM from the HuggingFace Hub without building custom training infrastructure, especially when VRAM is limited.
What it does
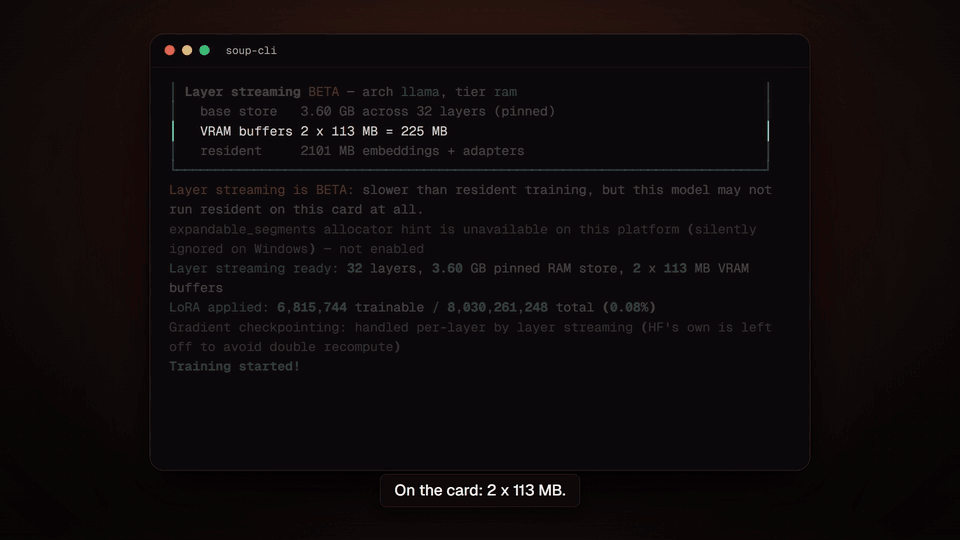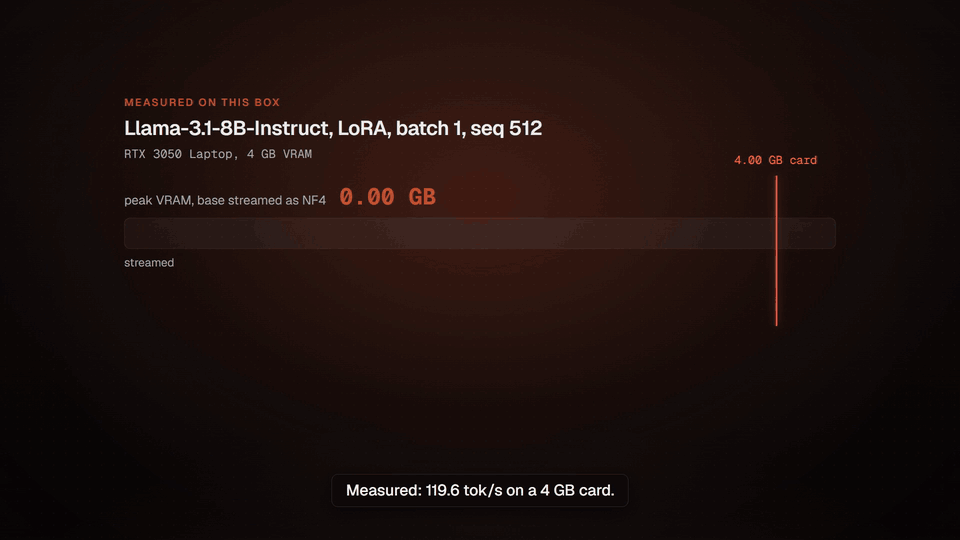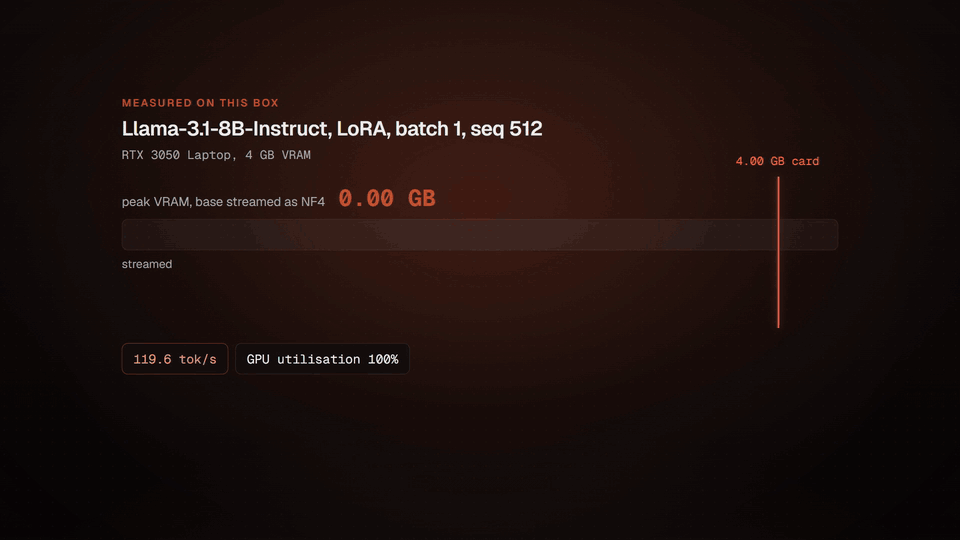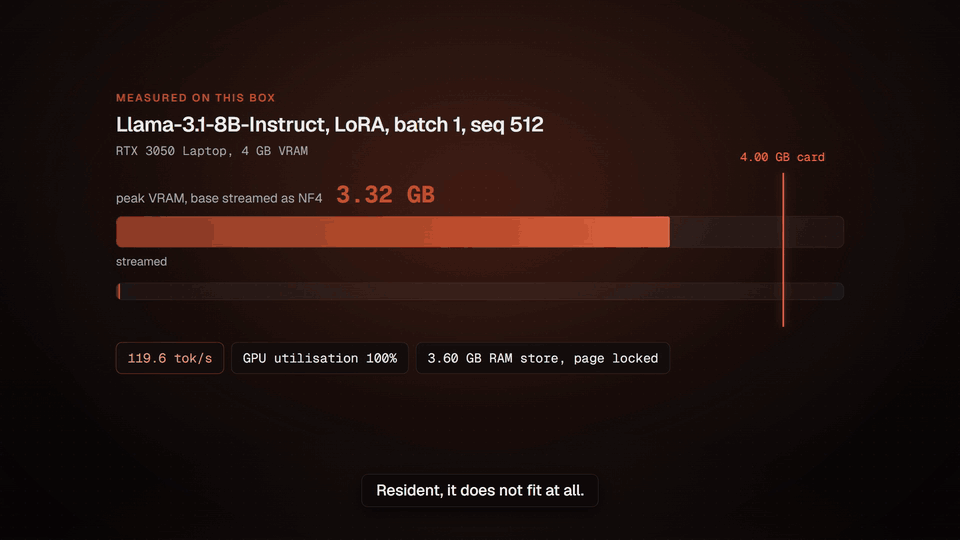
Soup turns LLM fine-tuning into one config, one command: soup init --template chat followed by soup train. Its headline feature is layer streaming (opt-in, still beta): it keeps the frozen base model out of VRAM and feeds it to the GPU one decoder layer at a time, so an 8B model can fine-tune on a 4 GB laptop GPU. Measured on an RTX 3050 Laptop 4 GB, Llama-3.1-8B-Instruct with NF4 quantization ran at 119.6 tok/s with a 3.32 GB peak, bit-exact against a normal resident run, and independently reproduced on an H100 at 113.00 tok/s in the same 3.32 GB. A later measurement found the largest streaming-specific cost is per-layer NF4 dequantization at 9.8% of step time, retracting an earlier claim that the technique was bound by host-to-device transfer rather than compute. Soup auto-handles batch size, GPU detection, and quantization, and works entirely locally with QLoRA, no cloud or SSH required.
When to use - and when NOT to
Use Soup when you want to fine-tune or post-train an LLM without hand-configuring infrastructure, especially on limited VRAM - it supports any text-generation model on the HuggingFace Hub that loads with AutoModelForCausalLM, with 100+ ready-made recipes (Llama 3.x/4, Qwen 2.5/3, Gemma 3, Mistral, Mixtral, DeepSeek R1/V3, Phi-4, and more). As a rough VRAM guide with QLoRA 4-bit: 8 GB fits about a 7B model, 16 GB about 14B, 24 GB about 34B, 48 GB about 70B, and 80 GB+ handles a 70B model in full or an MoE like Mixtral-8x22B. It requires Python 3.10-3.12 (3.13+ is not yet supported because the PyTorch stack is unvalidated there), and layer streaming specifically is still beta and opt-in via stream_layers: true - not the default training path.
Inputs and outputs
pip install "soup-cli[train]"
soup init --template chat
soup train
A complete config is a single soup.yaml specifying the base model, task (for example sft), data paths and format, training hyperparameters (epochs, learning rate, batch size, LoRA rank/alpha, quantization), and an output directory. Training data formats - Alpaca, ShareGPT, ChatML, preference pairs for DPO/ORPO/SimPO/IPO/KTO, vision, audio, ASR, plaintext, embedding, RAFT, and more - are auto-detected from JSONL, JSON, CSV, Parquet, or TXT. After training: soup chat --model ./output to talk to the model, soup push --model ./output --repo you/my-model to publish it, soup merge --adapter ./output to merge a LoRA adapter into the base, and soup export --model ./output --format gguf --quant q4_k_m for deployment formats including GGUF, ONNX, TensorRT, AWQ, and GPTQ.
Integrations
A local web UI (pip install "soup-cli[ui]" then soup ui, served at http://127.0.0.1:7860) covers training setup, live metrics, dataset exploration, and model chat for those who prefer a browser over the CLI. soup serve runs an OpenAI-compatible API server. A Docker image is published to GHCR on every release (docker pull ghcr.io/makazhanalpamys/soup:latest) for training without installing CUDA or PyTorch locally, and soup train --cloud lambda runs training on Lambda cloud GPUs, plan-only by default. soup doctor checks GPU, dependencies, and version in one place. It is licensed under Apache-2.0.
Who it's for
Developers and researchers fine-tuning or post-training open LLMs who want a single-command workflow instead of assembling their own training infrastructure, including those working on consumer GPUs with limited VRAM.
Source README
Soup







Soup turns the pain of LLM fine-tuning into a simple workflow. One config, one command, done.
pip install "soup-cli[train]"   # add [train] to fine-tune; bare `soup-cli` is the light CLI
soup init --template chat
soup train
Fine-tune an 8B model on a 4 GB laptop GPU. Layer streaming keeps the frozen base out of
VRAM and feeds it to the GPU one decoder layer at a time. Measured on an RTX 3050 Laptop 4 GB:
Llama-3.1-8B-Instruct + NF4 at 119.6 tok/s, 3.32 GB peak - bit-exact against a normal
resident run, and reproduced independently on an H100 at 113.00 tok/s in the same 3.32 GB.
(Both figures were measured on v0.72.2, before the v0.73.0 correctness repair that cost
−4.8% at 32B; neither has been re-run on a 4 GB card since - re-measurement pending in
issue #361.) Opt-in (stream_layers: true)
and still BETA -
how it works ·
all measurements · paper ·
check it yourself on a free Colab T4 (caps the process to
4 GB, then asserts a streamed model is bit-identical to a normal one)
Why Soup?
Training LLMs is still painful. Even experienced teams spend 30-50% of their time fighting infrastructure instead of improving models. Soup fixes that.
- Zero SSH. Never SSH into a broken GPU box again.
- One config. A simple YAML file is all you need.
- Auto everything. Batch size, GPU detection, quantization - handled.
- Works locally. Train on your own GPU with QLoRA. No cloud required.
What's New
v0.75.0 - the same soup.yaml trained a different recipe on MLX than on transformers,
silently. Six training options were validated, documented, accepted - and read by nothing
on that backend. All 60 pull requests in this release came from outside the maintainer,
by 22 people.
- Breaking: an unknown config key now refuses the load. v0.74 warned and named this
release as the deadline. A typo like
quantizaton, or a key that only exists on a newer Soup, used to be dropped while the run proceeded with the setting not applied; it now fails on the CLI (exit 1) and in the API (ValueError), naming the field you probably meant. The detector applies the root-levellora:remap the schema has honoured since v0.40.1, so that spelling is accepted, not refused; the twosoup fetch examplesfiles using it moved to the canonicaltraining.lora. Every recipe and template loads clean, key names are escaped before they reach the terminal, and the scan is bounded. - MLX honours the config it accepted.
train_on_responses_only,warmup_ratio/scheduler/weight_decay/optimizer,max_grad_norm,gradient_accumulation_stepsandgradient_checkpointingwere each validated and then dropped onbackend: mlx. Only 8 of the 32 optimizer names have an MLX equivalent; the other 24 are refused by name instead of silently becoming AdamW. MLX also drives the live dashboard, the tracker andsoup ui, andsoup doctor --configlists the settings a backend does not read. - Validation loss existed nowhere. It was computed on every backend and thrown away: no metrics column, no event field, nothing on the panel. It is now recorded, streamed and displayed.
- Breaking:
grpo_variant: gspois the published sequence-level objective (arXiv:2507.18071), replacing a column-centering heuristic in which a padding token also shifted the gradient of every row sharing its column. Existing gspo configs will not reproduce prior runs. - Web UI read endpoints and SSE require auth, with short-lived single-use tickets
instead of a token in a query string;
--publicno longer serves/docsand/openapi.jsonto the LAN; and a training subprocess no longer hangs when nothing reads its output. torch>=2.6.0closes v0.74.0's known limitation: at 2.5.1trl>=0.29could not import and every preference trainer was dead. Also fixed:training.loraplus_lr_ratiocrashed every run that set it, andpacking: trueraised on TRL 0.29.
Python 3.10-3.12 only. On 3.13+, pip used to resolve untested PyTorch wheels that crash in the native extension before Soup runs at all.
Older highlights live on the GitHub Releases page.
Quick Start
1. Install
Soup is a command-line application, so the cleanest install gives it its own
environment and puts soup on your PATH:
# Light core: CLI + config + data tools, no PyTorch
pipx install soup-cli
uv tool install soup-cli          # same idea, if you already use uv

# Add the training stack (torch, transformers, peft, trl, datasets, …)
pipx install "soup-cli[train]"

# Everything (train + serve + ui + data) in one shot
pipx install "soup-cli[all]"

# Or from GitHub (latest dev)
pipx install "git+https://github.com/MakazhanAlpamys/Soup.git"
Already inside a virtualenv, a Colab notebook, or a Docker image? Use pip
directly, with the same names and extras:
pip install soup-cli
pip install "soup-cli[train]"
pip install "soup-cli[all]"
pip install git+https://github.com/MakazhanAlpamys/Soup.git
Use pip rather than pipx if you also want to import soup_cli from your own
code, since pipx deliberately isolates the application from everything else.
The full extras table (fast, mlx, serve, eval, ui, vision, audio, …) lives in
docs/models.md.
error: externally-managed-environment? That is PEP 668, not a Soup problem. Debian 12, Ubuntu 23.04 and later stoppipfrom writing into the system Python, becauseaptmanages those files too.pipxanduv toolsidestep it by giving Soup its own environment, which is why they are listed first above.python3 -m venv .venv && source .venv/bin/activatethen plainpipworks just as well.
Double quotes, not single.
"soup-cli[train]"is the only spelling that works in every shell -cmd.exe, PowerShell, bash and zsh. If you copied'soup-cli[train]'from an older tutorial and pip rejected it, that is the reason: why, and the exact error.
soup init, soup data …, and the other data/inspection commands work on the light install.
Fine-tuning (soup train) needs the [train] extra.
2. Create a config
soup init                       # interactive wizard
soup init --template chat       # or start from a template
Templates: chat, code, tool-calling, medical, reasoning, vision, kto, orpo,
simpo, ipo, bco, rlhf, pretrain, moe, longcontext, embedding, audio.
3. Train, test, ship
soup train --config soup.yaml                 # LoRA, quantization, batching — all handled
soup chat  --model ./output                    # talk to your model
soup push  --model ./output --repo you/my-model

soup merge  --adapter ./output                              # merge LoRA into the base
soup export --model ./output --format gguf --quant q4_k_m   # GGUF for Ollama / llama.cpp
More export targets (ONNX, TensorRT, AWQ, GPTQ, BitNet) and deployment options live in
docs/serving-and-export.md.
Web UI
Prefer a browser? soup ui serves a local dashboard for experiments,
training setup, live metrics, dataset exploration and model chat.
pip install "soup-cli[ui]"
soup ui
# Opens http://127.0.0.1:7860
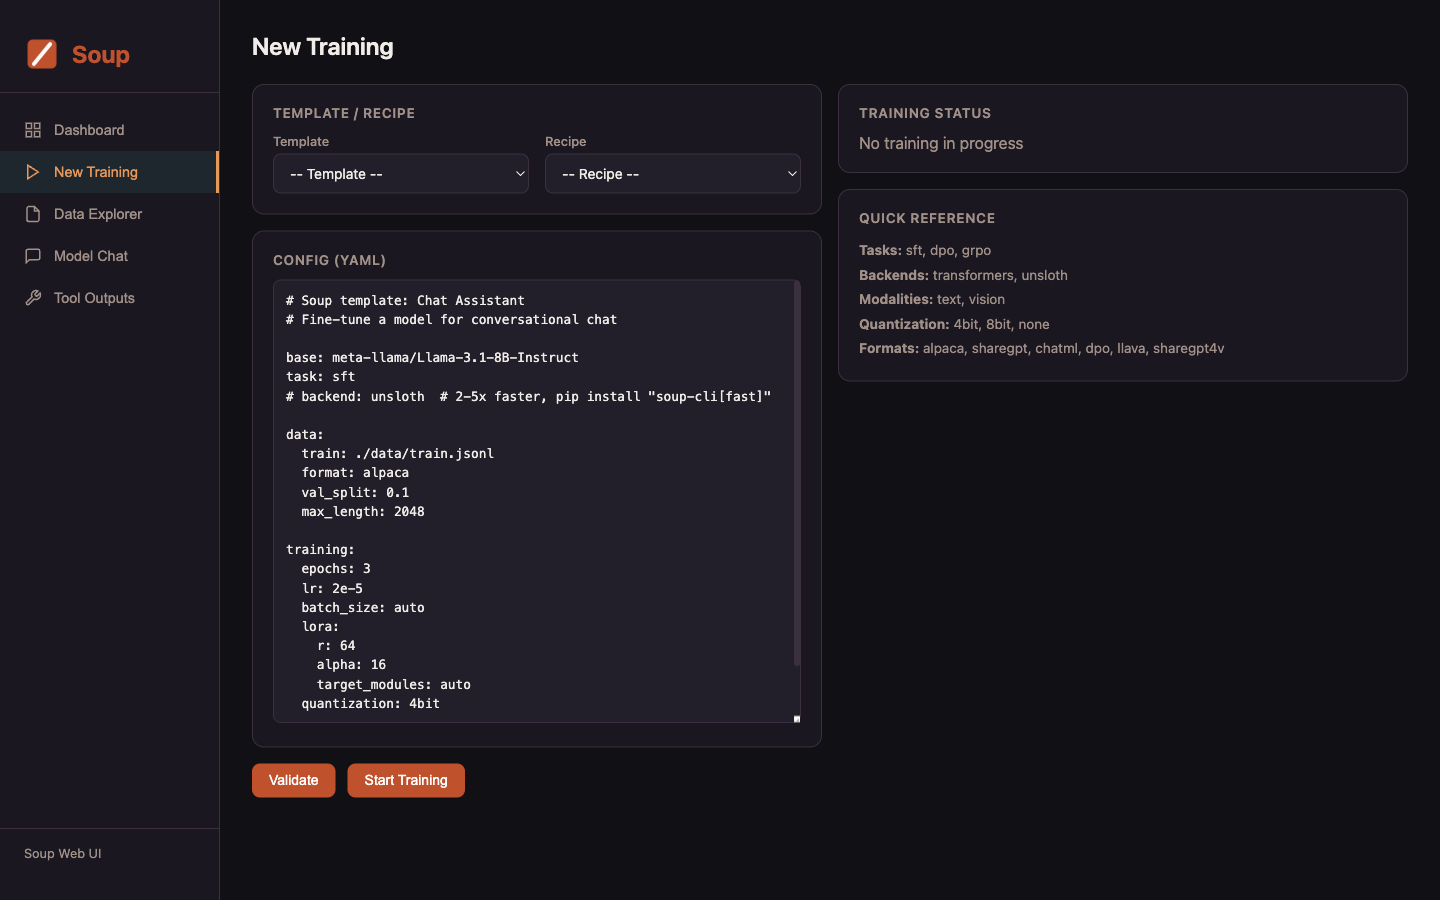
Configuration
A complete soup.yaml:
base: meta-llama/Llama-3.1-8B-Instruct
task: sft
# backend: unsloth  # 2-5x faster, pip install "soup-cli[fast]"

data:
  train: ./data/train.jsonl
  format: alpaca
  val_split: 0.1

training:
  epochs: 3
  lr: 2e-5
  batch_size: auto
  lora:
    r: 64
    alpha: 16
  quantization: 4bit

output: ./output
config/schema.py is the single source of truth for every field. Advanced data, training,
and PEFT options are documented under Documentation.
Unknown config keys are rejected since v0.75. A key no model declares - a typo like
quantizaton, or a field that only exists on a newer Soup - used to validate clean and be discarded, so the run proceeded with the setting simply not applied. v0.74 reported it at load with the field you probably meant; from v0.75 the same config fails to load, so fix or remove the key rather than relying on it being ignored. See Unknown config keys.
Documentation
The full feature reference lives in docs/. Start here:
| Guide | Covers |
|---|---|
| Training tasks & methods | SFT, DPO/GRPO/PPO/KTO/ORPO/SimPO/IPO/BCO, tool-calling, PRM, pre-training, distillation, classification, vision/audio/TTS, unlearning, RAFT/RA-DIT, loop-hardening detectors |
| PEFT, long context & efficiency | DoRA, LoRA+, rsLoRA, VeRA, OLoRA, NEFTune, PiSSA, ReLoRA, optimizer & PEFT zoo, LLaMA Pro, GaLore, YaRN/LongLoRA, packing, curriculum, auto-tuning |
| Performance & quantization | QAT, FP8, Quant Menu (I + II), KV-cache, NVFP4, save formats, Cut Cross-Entropy, gradient checkpointing, kernels, activation offloading, layer streaming, multi-GPU / DeepSpeed / FSDP |
| Data engineering | Formats, the Axolotl/LF-parity pipeline, data tools, synthetic generation & forge, quality scorecards, trace tooling, remote datasets, mixing, recipe DAGs |
| Evaluation & probes | Eval design/gate, eval-gated training, benchmarks, NLG metrics, calibration, Elo arena, diagnose, post-train X-ray probes, A/B, drift, tunability, soup advise |
| Serving & export | OpenAI-compatible server, batch inference, benchmarking, merge/export, Anthropic Messages endpoint, speculative decoding (train + measure your own draft), deploy autopilot, Web UI, Agent Forge |
| Adapters, registry & governance | Adapter lifecycle/management, model registry, Soup Cans, the data flywheel (soup loop), knowledge editing, steering, supply-chain controls (scan/sign/BOM/attest/audit/airgap) |
| Compliance & governance quickstart | HIPAA/SOC2/EU-AI-Act/SR-11-7 init templates, provenance (BOM/attest/repro-receipt), audit log, air-gap, model-card autogen (soup card), CI gate (soup ci init) |
| Backends, platform & ops | MLX/Unsloth backends, alternative hubs, HF Hub integration, autopilot, experiment tracking, plan/apply, env lockfiles, hardware-fit, completions, plugins, utility commands |
| Command reference | The full soup command list |
| Supported models & extras | Recommended model families, the VRAM size guide, the pip extras matrix |
Data Formats
Alpaca, ShareGPT, ChatML, preference pairs (DPO / ORPO / SimPO / IPO / KTO), vision, audio,
ASR, plaintext, embedding, RAFT and more - all auto-detected from JSONL, JSON, CSV, Parquet or
TXT, so in most cases you point data.train at a file and nothing else changes. Schemas with a
worked example per format, plus the data pipeline (remote URIs, streaming, sharding,
interleaving, vocab expansion, document ingestion), are in
docs/data.md.
Common Commands
soup train  --config soup.yaml        # train (SFT/DPO/GRPO/PPO/KTO/ORPO/SimPO/IPO/...)
soup infer  --model ./output --input prompts.jsonl   # batch inference
soup chat   --model ./output          # interactive chat
soup serve  --model ./output          # OpenAI-compatible API server
soup ui                               # local browser dashboard
soup merge  --adapter ./output        # merge LoRA into the base model
soup export --model ./output --format gguf           # export for deployment
soup eval   benchmark --model ./output               # evaluate
soup data   inspect ./data/train.jsonl               # dataset stats
soup recipes list                     # 100+ ready-made model recipes
soup autopilot --model <id> --data d.jsonl --goal chat  # zero-config
soup doctor                           # check GPU / deps / environment
The complete command list is in docs/commands.md.
Supported Models
Soup works with any text-generation model on the
HuggingFace Hub - if it loads with
AutoModelForCausalLM, it works, zero config changes. Llama 3.x/4, Qwen 2.5/3, Gemma 3, Mistral,
Mixtral, DeepSeek R1/V3, Phi-4, and 100+ others ship as ready-made recipes (soup recipes list).
| VRAM | Max model (QLoRA 4-bit) | Example |
|---|---|---|
| 8 GB | ~7B | Llama-3.1-8B, Mistral-7B |
| 16 GB | ~14B | Phi-4-14B, Qwen2.5-14B |
| 24 GB | ~34B | CodeLlama-34B, Yi-1.5-34B |
| 48 GB | ~70B | Llama-3.3-70B |
| 80 GB+ | 70B+ (full) or MoE | Mixtral-8x22B, DeepSeek-V3 |
Full model + vision tables and the optional-extras matrix are in docs/models.md.
Docker
Run Soup without installing CUDA or PyTorch locally (image published to GHCR on every release):
docker pull ghcr.io/makazhanalpamys/soup:latest
docker run --gpus all -v $(pwd):/workspace ghcr.io/makazhanalpamys/soup train --config soup.yaml
docker compose up   # or build locally
Requirements
- Python 3.10, 3.11 or 3.12 (those are the versions CI tests; 3.13+ is not supported yet because the PyTorch stack has not been validated there)
- GPU with CUDA (recommended), Apple Silicon (MPS), or CPU (experimental - very slow)
- 8 GB+ VRAM for 7B models with QLoRA
All training tasks run on CPU for testing (quantization auto-disabled). Optional extras
(train, all, fast, vision, qat, serve, serve-fast, ui, eval, deepspeed,
liger, mlx, onnx, tensorrt, …) are listed in
docs/models.md.
Troubleshooting
soup doctor # GPU, system resources, dependencies, and version in one place
CUDA wheels, version mismatches: docs/backends-and-ops.md.
Development
git clone https://github.com/MakazhanAlpamys/Soup.git
cd Soup
pip install -e ".[dev]"

ruff check src/soup_cli/ tests/    # lint
pytest tests/ -v                   # unit tests (fast, no GPU)
pytest tests/ -m smoke -v          # smoke tests (downloads a tiny model, trains)
pytest tests/ -m gpu --no-cov -v   # GPU tests (need a CUDA card; report results, see CONTRIBUTING.md)

pre-commit install                 # optional: ruff lint+format on commit
See CONTRIBUTING.md for the full workflow and SECURITY.md to
report a vulnerability. Telemetry is strictly opt-in (SOUP_TELEMETRY=1, default off; see Privacy Policy).
Citing Soup
Layer streaming - training an 8B model on a 4 GB laptop GPU by streaming the frozen base from host RAM one decoder layer at a time - is described in a preprint, together with the correctness protocol that verifies a streamed run against a resident one (forward and backward stated separately, because they are two claims and not one).
Makazhan, A. (2026). Exact Layer Streaming: LoRA Fine-Tuning of an 8B Model on a 4 GB Laptop GPU (v3). Zenodo. https://doi.org/10.5281/zenodo.21918325
Version 3 (13 August 2026) is current. The title and the claim are unchanged - 8B on 4 GB - and no measured number has changed since v1. What v3 does is withdraw an explanation we had published, which is also the shortest way to describe what the paper is for:
- Retracted in v3: "layer streaming is bound by host-to-device transfer, not by the GPU." That was an inference from the H100 replication below, and it had never been measured. We measured it on 11 August and it is false at the published configuration: deleting every host-to-device byte buys 1.4%, the compute stream waits on a copy for 0.20% of the step, and the step runs at 71.3% of that card's same-session GEMM ceiling. The largest streaming-specific cost is the per-layer NF4 dequantisation, at 9.8% (the record). Every measurement stands; the replication survives in a weaker form - the constraint is common to both machines and is not the GPU's compute.
- Replication on hardware nothing like the original (added in v2): 119.6 tok/s on the RTX 3050 against a median 113.00 on an H100, at the same 3.32 GB peak. Both pre-date the #331 repair; the 4 GB re-measurement is pending in issue #361.
- A silent wrong-gradient defect, found and repaired. On NF4 above ~165 MiB per layer the forward stayed bit-exact and the loss curve looked healthy while the gradients were wrong. The cause is named in the upstream library and reported there; the repair is gated against controls on real 32B and 72B.
- Bit-exactness at real model sizes instead of three-layer toys: forward from 0.5B to 72B, backward at 8B and 14B.
- Trained-model quality, measured for the first time, and indistinguishable from a resident run.
- A comparison against DeepSpeed - including the result that does not flatter us: eight cards of ZeRO-3 are slower than one card training resident.
- The limitations section rewritten: of v1's ten items, one closed and four more narrowed, and seven new ones added.
Cite the version you used. 10.5281/zenodo.21771064 is the concept DOI and always resolves to
the latest version (v3 today); v1 and v2 remain citable at their own version DOIs and are not
edited - the retraction above is a new version precisely so that the record of what we claimed,
and when, stays intact.
The measurement records behind every number in it are in benchmarks/, published
as written - including the failures, the assumptions that turned out wrong, and the numbers that
were measured and then discarded.
@misc{makazhan2026exact,
  title        = {Exact Layer Streaming: LoRA Fine-Tuning of an 8B Model on a 4 GB Laptop GPU},
  author       = {Makazhan, Alpamys},
  year         = {2026},
  publisher    = {Zenodo},
  version      = {v3},
  doi          = {10.5281/zenodo.21918325},
  url          = {https://doi.org/10.5281/zenodo.21918325}
}
FAQ
Common questions
Discussion
Questions & comments · 0
Sign In Sign in to leave a comment.