
Benchmark local LLMs with reproducible GPU diagnostics
Picchio is a single-file, stdlib-only tool that tells you whether your local LLM is actually running on the GPU or has fallen back to CPU.
1.0.0Add to Favorites
Why it matters
Verify that your local LLM deployment is actually using the GPU and performing at expected speeds by measuring prefill, decode, and wallclock times across multiple passes, then producing a reproducible verdict that explains whether the GPU did the work and why.
Outcomes
What it gets done
Detect silent CPU fallback by comparing engine logs against OS-level GPU telemetry
Measure quantization accuracy by reading actual bits-per-weight from GGUF files
Split prefill and decode performance to catch partial GPU offload issues
Monitor running LLM servers and flag performance degradation in real-time
Source
Get it from source
Spark does not host a copy of it.
Open sourceReports
Agent outcome reports
No reports yet
Overview
Picchio is a single-file, dependency-free Python tool that checks whether a local LLM is actually running on the GPU or has fallen back to the CPU. It reports per-layer GPU placement, prefill/decode/wall-clock speeds, and power or energy per token, across llama.cpp, Ollama, macOS, NVIDIA, and AMD. Use it when a local model feels too slow and you need to know if it's CPU fallback, partial offload, or a real bottleneck, or before downloading a model to check it fits your memory and context length. Not a model-quality benchmark - it only measures GPU placement and throughput.
What it does
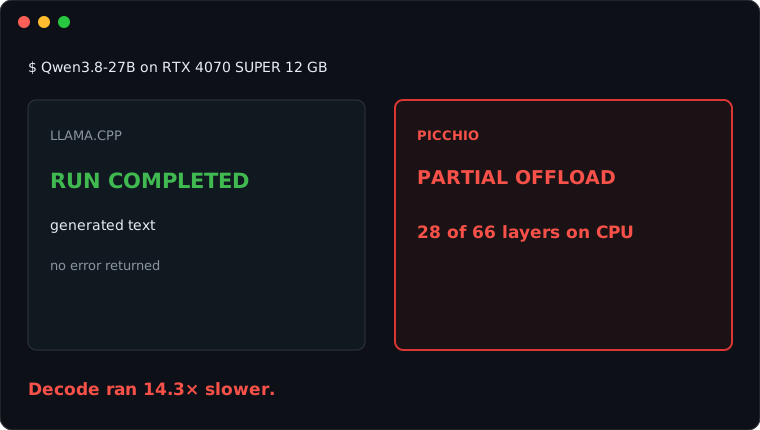
Picchio is a single-file, stdlib-only Python tool that tells you whether a local LLM is actually running on the GPU, or has silently fallen back to the CPU. Run with no arguments, it discovers Ollama tags, local GGUF files, and models cached by Hugging Face or LM Studio, picks one, and runs three measurement passes; you can also point it directly at a model file, an Ollama tag, or a running llama-server URL. In the project's own demo, it catches a 66-layer model with 28 layers stuck on the CPU and reports the resulting 14x decode slowdown.
When to use - and when NOT to
Use it when a local model feels slower than it should and you need to know whether that's CPU fallback, partial GPU offload, or just a genuinely slow setup - or before downloading a model at all, to check whether it fits in your machine's memory at your intended context length and KV cache type. picchio guard watches something already running - your own command, a loaded model, or a server - and tells you the moment it leaves the GPU; picchio compare diffs two runs and names the first setting that changed between them. It is not a benchmarking suite for comparing model quality or accuracy - it only measures GPU placement, throughput, and power or energy per token.
Inputs and outputs
./picchio MODEL                              # catch CPU fallback and measure the run
./picchio plan MODEL --ctx 262144 --kv q8_0  # check whether it fits at this context and KV type
Output includes the exact number of model layers placed on the GPU, separate prefill, decode, and wall-clock speeds, GPU activity, memory, power, and energy per generated token, and a HEALTHY, CPU FALLBACK, or PARTIAL OFFLOAD verdict. --share bug-report turns one run into a paste-ready GitHub Issue for the Ollama or llama.cpp trackers, and --json gives machine-readable output for scripting.
Integrations
It reads per-layer placement and timing from llama.cpp, the CPU/GPU weight split from Ollama, Apple GPU activity and power on macOS, NVIDIA GPU stats on Linux and Windows through NVML, and AMD GPU activity through amdgpu sysfs on Linux. Install is one line, with no package manager involved:
curl -fsSL https://raw.githubusercontent.com/logxio/picchio/main/public/picchio.pyz -o picchio
Results from any machine can be submitted to a public comparison page (--share row), which already lists measured prefill, decode, and wall-clock numbers across Apple M5, RTX 4090/5090/4070 SUPER, and CPU-forced runs. It requires Python 3.9+, runs on macOS, Linux, and Windows, and is MIT-licensed.
Who it's for
Anyone running local LLMs through llama.cpp, Ollama, or LM Studio who wants a fast, dependency-free way to confirm the model is actually using the GPU, size a model before downloading it, or get an accurate bug report when it isn't behaving.
Source README

Inference Placement Receipts for local LLMs


A separate Linux CUDA 27B receipt records all 66 layers on an RTX 5090, 92% GPU work and 81.5 tok/s warm decode. Its three captured passes and NVML samples are public alongside the Apple M5 GPU and forced-CPU runs.
An author-run Kaggle Linux T4 pair held the same Qwen3.5-9B file and exact per-pass prompts: the GPU receipt shows 33/33 layers and 40.1 tok/s warm decode, while the forced-CPU receipt shows 0/33 and 2.6 tok/s; recalculate these captured receipts without a GPU or model download:
python3 scripts/replay_receipts.py
The command checks each published receipt against its captured inputs. A mismatch points to the affected file or receipt line and exits nonzero.
Run it
curl -fsSL https://raw.githubusercontent.com/logxio/picchio/main/public/picchio.pyz -o picchio
chmod +x picchio
./picchio
On Windows, in PowerShell:
curl.exe -fsSL https://raw.githubusercontent.com/logxio/picchio/main/public/picchio.pyz -o picchio.pyz
python picchio.pyz
With no arguments, Picchio finds Ollama tags, local GGUF files and models in the Hugging Face and LM Studio caches. Pick one and it runs three passes.
You can also point it straight at a model or a running server:
./picchio model.gguf
./picchio qwen3.5:9b
./picchio http://127.0.0.1:8080
It runs on macOS, Linux and Windows with Python 3.9+. The download is one file and uses only the standard library.
Next
- Collect more Linux Radeon runs to check GPU activity and multi-card results against real engine output, building on the RX 7900 XTX report.
- Verify the complete Ollama path on Windows hardware, from finding a model to reporting where it ran.
Public work spans July through September 2026, with v1.0.0 released in August. In Issue #1, a Radeon user reported missing speed readings and an incorrect cold-run breakdown; the maintainer replied with a fix and requested a new verdict. The user has not posted that rerun, so the corrected result on that machine remains unverified.
Use the result
| I want to… | Run |
|---|---|
| catch CPU fallback and measure the run | ./picchio MODEL |
| know whether a model fits here before I download it | ./picchio plan https://huggingface.co/.../model-Q4_K_M.gguf · ./picchio plan qwen3.5:9b |
| check that fit at my own context and KV type | ./picchio plan MODEL --ctx 262144 --kv q8_0 |
| guard something already running and get told the moment it leaves the GPU: your own command, a loaded model, a server | ./picchio guard -- COMMAND · ./picchio guard ollama · ./picchio guard http://127.0.0.1:8080 |
| compare two runs and show the first changed setting | ./picchio compare before.txt after.txt |
| turn one run into a complete Ollama or llama.cpp Issue report | ./picchio MODEL --share bug-report |
Add --json when you want machine-readable output.
Add --ctx 262144 when the problem only appears at a larger context.
The fit check answers before the download, from the file header and the registry manifest, and it answers in one word and one move. In the browser: will it fit?
FITS. The whole model fits in this machine's memory.
  5.3 GiB to download
What it gives you
- the exact number of model layers on the GPU
- separate prefill, decode and wall-clock speeds
- GPU activity, memory, power and energy per generated token
- the first setting that changed when you compare two runs
- a clear
HEALTHY,CPU FALLBACKorPARTIAL OFFLOADresult - a paste-ready GitHub Issue with your machine, model, GPU placement and measured rates
Compare machines
I measured these with Picchio:
| machine | model and engine | placement | prefill | decode | wall-clock |
|---|---|---|---|---|---|
| Apple M5 | Qwen3.5-9B, llama.cpp Metal | 33/33 | 588.0 | 21.1 | 15.5 |
| Apple M5 | same file, forced CPU | 0/33 | 26.8 | 12.2 | 3.0 |
| RTX 4090 | same file, llama.cpp CUDA | 33/33 | 6763.3 | 138.0 | 25.2 |
| RTX 5090 | same file, llama.cpp CUDA | 33/33 | 9135.9 | 226.4 | 57.3 |
| RTX 5090 | same file, llama.cpp Vulkan | 33/33 | 6206.3 | 198.4 | 51.0 |
| RTX 5090 | qwen3.5:9b, Ollama | 100% GPU | 8614.7 | 193.5 | 153.9 |
| RTX 4070 SUPER | same file, llama.cpp CUDA | 33/33 | 4187.8 | 78.2 | 28.9 |
| your machine |
Open every result or compare the outputs in examples/.
What Picchio reads
- llama.cpp: per-layer placement, applied sampling settings and timing
- Ollama: CPU/GPU weight split and timing
- macOS: Apple GPU activity, memory, power and energy per token
- NVIDIA on Linux and Windows: GPU activity, memory, power and energy per token through NVML
- AMD on Linux: GPU activity and memory through amdgpu sysfs
Point Picchio at a GGUF path, an Ollama tag or a running llama-server URL. The result tells you where the model ran and which number is safe to compare.
One run, two sources of evidence
The llama-bench documentation shows backends, n_gpu_layers, and repeated-test avg_ts / stddev_ts output. Its n_gpu_layers is a test setting, not a measurement of GPU activity. The llama-cli documentation includes --show-timings. Picchio reads the engine's output and samples the OS during that same run:
| Input and source | Output in the public Apple M5 / Qwen3.5-9B receipts | What it can establish |
|---|---|---|
| llama.cpp stderr from each pass | offloaded 33/33 with prompt/eval timings in the GPU run; offloaded 0/33 in the forced CPU run |
Actual layer placement and engine timing as reported by llama.cpp; not independent proof that the GPU was busy. |
| Picchio's time-aligned macOS GPU samples from those same passes | GPU run: 99% work, +6.0 GiB, 11.0 W, 0.52 J/token; forced CPU run: 5% work, +0.3 GiB, 0.1 W, 0.01 J/token | OS-side activity, memory and energy alongside the engine report; these are whole-GPU readings, not per-process attribution or total-system energy. |
| Picchio's combined result | HEALTHY versus SILENT CPU FALLBACK, with --device none -ngl 0 identified in the CPU run |
A diagnosis for each recorded run. The different placement and rates come from the GPU settings, not from Picchio accelerating inference. |
The two M5 receipts report one Apple M5, the same model path, engine build, context and sampling settings; the forced-CPU run changes --device none -ngl 0. The raw files contain no independent machine or model-byte fingerprint, and the OS samples measure the whole GPU. No llama-bench throughput number is mixed into this comparison. The Linux 27B receipt replays from its three recorded CUDA passes and NVML samples; the OS samples measure the whole GPU, and the raw files have no independent machine or model-byte fingerprint. The 4070 SUPER 27B receipt can be checked for its own arithmetic (66 − 38 = 28 CPU layers); its raw layer and timing logs are not public, so the replay command does not independently reproduce its measurements. Speeds across the two 27B machines are not a controlled comparison or evidence that Picchio accelerates inference.
Send me your machine
./picchio MODEL --share row > result.md 2> picchio.txt
Add your result. If Picchio calls your run wrong, send me that one first.
examples/windows-4070s-27b.txt
model    Qwen3.8-27B Q4_K_M, 27.32 B, 15.32 GiB, llama.cpp b0.2.0-dev
gpu      PARTIAL: 38/66 layers on GPU (CUDA: GeForce RTX 4070 SUPER)
os       gpu idle 0%, work 30%, mem +9.7 GiB, 36.1 W, 6.18 J/tok
settings temp 1.0, top-k 20, top-p 0.95, min-p 0.05, seed 7
ctx 4096         prefill         decode      wallclock
  cold       425.3 tok/s      5.8 tok/s      1.7 tok/s
  warm mid   504.1 tok/s      5.7 tok/s      4.0 tok/s
  warm span      445~563        5.6~5.8        3.9~4.2
where the cold pass went (73.6 s, 8/16 threads)
  load weights   46.8 s  ##################..........   64%
  prefill         1.8 s  #...........................    2%
  decode         21.9 s  ########....................   30%
  engine misc     3.0 s  #...........................    4%
PARTIAL OFFLOAD. 28 layers sat on CPU.
WHY: memory fit: saw 11069 MiB free, gave 38/66 layers
-- picchio v0.1.0 mp1 on AMD Ryzen 7 7800X3D 8-Core Processor + GeForce RTX 4070 SUPER, 32 GB, Windows 10
examples/linux-5090-27b.txt
model    Qwen3.8-27B Q4_K_M, 27.32 B, 15.32 GiB, llama.cpp b0.2.0-dev
gpu      ENGAGED: 66/66 layers on GPU (CUDA: GeForce RTX 5090)
os       gpu idle 0%, work 92%, mem +15.8 GiB, 343 W, 4.61 J/tok
settings temp 1.0, top-k 20, top-p 0.95, min-p 0.05, seed 7
ctx 4096         prefill         decode      wallclock
  cold      2921.5 tok/s     79.7 tok/s      6.0 tok/s
  warm mid  3364.4 tok/s     81.5 tok/s     25.3 tok/s
  warm span    3355~3374      81.5~81.5      23.4~27.2
where the cold pass went (21.3 s, 8/16 threads)
  load weights   18.2 s  ########################....   86%
  prefill         0.3 s  ............................    1%
  decode          1.6 s  ##..........................    7%
  engine misc     1.2 s  ##..........................    6%
HEALTHY. The GPU did the work. Quote the warm median decode:
  81.5 tok/s. 3364 tok/s is prefill: reading speed, not writing.
-- picchio v0.1.0 mp1 on AMD Ryzen 7 7800X3D 8-Core Processor + GeForce RTX 5090, 30 GB, Linux 6.14.0-37-generic
examples/kaggle-t4-9b-gpu.txt
model    Qwen3.5-9B Q4_K_M, 8.95 B, 5.28 GiB, llama.cpp b0.5.0-dev
gpu      ENGAGED: 33/33 layers on GPU (CUDA: Tesla T4) [-ngl 99]
os       gpu idle 0%, work 53%, mem +5.9 GiB, 135 W, 3.45 J/tok
settings temp 0.8, top-k 40, top-p 0.95, min-p 0.05, seed 7
ctx 4096         prefill         decode      wallclock
  cold       846.8 tok/s     40.1 tok/s     15.0 tok/s
  warm mid   833.7 tok/s     40.1 tok/s     15.6 tok/s
  warm span      818~849      40.1~40.2      15.6~15.6
where the cold pass went (8.5 s, 2/4 threads, weights cached)
  load weights    2.2 s  #######.....................   26%
  prefill         0.9 s  ###.........................   11%
  decode          3.2 s  ##########..................   37%
  engine misc     2.2 s  #######.....................   26%
HEALTHY. The GPU did the work. Quote the warm median decode:
  40.1 tok/s. 834 tok/s is prefill: reading speed, not writing.
-- picchio v1.0.0 mp1 on Intel(R) Xeon(R) CPU @ 2.00GHz + Tesla T4 x2, 31 GB, Linux 6.12.90+
examples/kaggle-t4-9b-cpu.txt
model    Qwen3.5-9B Q4_K_M, 8.95 B, 5.28 GiB, llama.cpp b0.5.0-dev
gpu      NOT ENGAGED: 0/33 layers on GPU (CUDA: Tesla T4) [--de..]
os       gpu idle 0%, work 0%, mem +0.0 GiB, 20.2 W, 7.89 J/tok
settings temp 0.8, top-k 40, top-p 0.95, min-p 0.05, seed 7
ctx 4096         prefill         decode      wallclock
  cold         9.5 tok/s      2.6 tok/s      0.9 tok/s
  warm mid     9.5 tok/s      2.6 tok/s      0.9 tok/s
  warm span         9~10        2.5~2.6        0.9~0.9
where the cold pass went (138.9 s, 2/4 threads, weights cached)
  load weights    5.5 s  #...........................    4%
  prefill        81.7 s  ################............   59%
  decode         49.8 s  ##########..................   36%
  engine misc     1.9 s  ............................    1%
SILENT CPU FALLBACK. Prefill: 263 s per 2500 tokens.
WHY: forced by flag: --device none -ngl 0
-- picchio v1.0.0 mp1 on Intel(R) Xeon(R) CPU @ 2.00GHz + Tesla T4 x2, 31 GB, Linux 6.12.90+
scripts/replay_receipts.py
#!/usr/bin/env python3
"""Recalculate public M5, Linux 27B and T4 receipts from captured inputs."""

import argparse
import hashlib
import json
import re
import sys
from pathlib import Path

ROOT = Path(__file__).resolve().parents[1]
sys.path.insert(0, str(ROOT))
import picchio  # noqa: E402


class ReplayError(Exception):
    pass


def require(ok, message):
    if not ok:
        raise ReplayError(message)


def source_line(path, needle):
    lines = path.read_text(encoding="utf-8").splitlines()
    found = [i for i, line in enumerate(lines, 1) if needle in line]
    require(found, "{}: missing {!r}".format(path, needle))
    return "{}:{}".format(path.relative_to(ROOT), found[-1])


def replay(name, raw_name=None):
    raw_dir = ROOT / "examples" / "raw" / (raw_name or name)
    receipt_path = ROOT / "examples" / (name + ".txt")
    require(receipt_path.is_file(), "missing {}".format(receipt_path))
    passes, metas, model_paths = [], [], []
    for number in range(1, 4):
        stem = raw_dir / "pass{}".format(number)
        meta_path = Path(str(stem) + ".meta.json")
        stderr_path = Path(str(stem) + ".stderr.txt")
        require(meta_path.is_file() and stderr_path.is_file(),
                "missing pass {} inputs in {}".format(number, raw_dir))
        meta = json.loads(meta_path.read_text(encoding="utf-8"))
        stderr = stderr_path.read_text(encoding="utf-8")
        parsed = picchio.parse_stderr(stderr, meta["wall_s"])
        paths = re.findall(r"loaded meta data .*? from (.+?) \(version GGUF",
                           stderr)
        require(paths and len(set(paths)) == 1,
                "{}: model path is missing or inconsistent".format(
                    stderr_path))
        model_paths.append(paths[0])
        for field in ("offload_n", "offload_total", "prompt_tokens",
                      "prompt_ms", "eval_tokens", "eval_ms", "load_ms",
                      "prefill_toks", "decode_toks", "wallclock_toks"):
            require(parsed[field] is not None,
                    "{}: missing {}".format(stderr_path, field))
        parsed["nonce"] = meta.get("prompt_nonce")
        passes.append(parsed)
        metas.append(meta)
    require(len({(m["model_name"], m["engine"],
                  tuple(m.get("extra_args", []))) for m in metas}) == 1,
            "{}: pass metadata disagree".format(raw_dir))
    require(len({(p["offload_n"], p["offload_total"])
                 for p in passes}) == 1,
            "{}: placement differs across passes".format(raw_dir))
    require(len(set(model_paths)) == 1,
            "{}: model path differs across passes".format(raw_dir))
    tele_path = raw_dir / "telemetry.json"
    require(tele_path.is_file(), "missing {}".format(tele_path))
    raw = json.loads(tele_path.read_text(encoding="utf-8"))
    require(raw.get("samples") and len(raw.get("marks", [])) == 3,
            "{}: expected samples and three pass marks".format(tele_path))
    saved = raw.get("summary", {})
    tele = picchio.telemetry_summary(
        raw["samples"], raw["marks"], saved.get("throttled", False),
        saved.get("src"))
    for field in ("idle_med", "work_med", "mem_step", "work_w", "dec_w"):
        require(tele[field] is not None,
                "{}: cannot derive {}".format(tele_path, field))
    rep = picchio.build_rep(passes)
    state, para = picchio.diagnose(passes[0], rep, "llama.cpp", tele)
    extra = metas[0].get("extra_args", [])
    why = picchio.attribute_why(state, rep, "llama.cpp", extra)
    l1, l2 = passes[0]["load_ms"], passes[1]["load_ms"]
    cold_note = l1 < 2 * l2 + 500
    got = picchio.render_verdict(
        picchio.machine_info(), metas[0]["engine"],
        metas[0]["model_name"], passes, state, para, "llama.cpp",
        None, cold_note, why,
        metas[0].get("ctx", picchio.effective_ctx(extra)), extra, tele)
    want = receipt_path.read_text(encoding="utf-8").rstrip()
    got_lines, want_lines = got.splitlines(), want.splitlines()
    # machine_info() describes the reader's computer. The recorded footer
    # belongs to the capture machine and is checked across the paired runs.
    for number, (actual, published) in enumerate(
            zip(got_lines[:-1], want_lines[:-1]), 1):
        require(actual == published,
                "{}:{} differs\n  published: {}\n  replayed:  {}".format(
                    receipt_path.relative_to(ROOT), number,
                    published, actual))
    require(len(got_lines) == len(want_lines),
            "{}: line count differs".format(receipt_path))
    block = picchio.parse_block(want)
    require(block and block["verdict"] == state,
            "{}: verdict cannot be read back".format(receipt_path))
    require(block["model"] == metas[0]["model_name"]
            and block["engine"] == metas[0]["engine"],
            "{}: model or engine footer disagrees with metadata".format(
                receipt_path))
    return {"name": name, "block": block, "passes": passes,
            "metas": metas, "tele": tele, "state": state,
            "model_path": model_paths[0],
            "marks": raw["marks"],
            "sources": [str((raw_dir / "pass2.meta.json").relative_to(ROOT)),
                        source_line(raw_dir / "pass2.stderr.txt",
                                    "offloaded "),
                        source_line(raw_dir / "pass2.stderr.txt",
                                    "prompt eval time ="),
                        source_line(raw_dir / "pass2.stderr.txt",
                                    "eval time ="),
                        str(tele_path.relative_to(ROOT)) + " (marks, samples)"],
            "receipt": str(receipt_path.relative_to(ROOT))}


def check_pair(gpu, cpu):
    a, b = gpu["block"], cpu["block"]
    require((a["chip"], a["ram"], a["os"], a["model"], a["engine"],
             a["ctx"], a["quant"], a["settings"]) ==
            (b["chip"], b["ram"], b["os"], b["model"], b["engine"],
             b["ctx"], b["quant"], b["settings"]),
            "M5 receipts disagree on machine, model or settings")
    require(a["chip"] == "Apple M5" and a["ram"] == "32"
            and a["ctx"] == 4096,
            "M5 comparison identity does not match the public claim")
    require(gpu["metas"][0].get("extra_args", []) == []
            and cpu["metas"][0]["extra_args"] ==
            ["--device", "none", "-ngl", "0"],
            "M5 placement intervention differs from recorded flags")
    require(gpu["model_path"] == cpu["model_path"]
            and gpu["passes"][0]["gpu_device"] == "Apple M5",
            "M5 logs disagree on model path or Metal device")
    for number, (gpu_pass, cpu_pass) in enumerate(
            zip(gpu["passes"], cpu["passes"]), 1):
        for field in ("prompt_tokens", "eval_tokens", "threads", "cores",
                      "model_params", "model_size", "sampling"):
            require(gpu_pass[field] == cpu_pass[field],
                    "M5 pass {} differs on {}".format(number, field))
    require(gpu["passes"][0]["offload_n"] == 33
            and cpu["passes"][0]["offload_n"] == 0
            and gpu["passes"][0]["offload_total"] == 33
            and cpu["passes"][0]["offload_total"] == 33,
            "M5 layer contrast is not 33/33 versus 0/33")


def check_kaggle_pair(gpu, cpu):
    raw_dir = ROOT / "examples" / "raw" / "kaggle-t4-9b"
    fingerprints = json.loads(
        (raw_dir / "fingerprints.json").read_text(encoding="utf-8"))
    model_sha = "03b74727a860a56338e042c4420bb3f04b2fec5734175f4cb9fa853daf52b7e8"
    require(fingerprints["model"] == "Qwen3.5-9B-Q4_K_M.gguf"
            and fingerprints["model_bytes"] == 5680522464
            and fingerprints["model_sha256"] ==
            fingerprints["expected_model_sha256"] == model_sha,
            "examples/raw/kaggle-t4-9b/fingerprints.json: "
            "captured model identity, size or SHA-256 differs")
    require(fingerprints["picchio_zipapp_sha256"] ==
            "87632c11bce5afb97d012e8920e0f7b28bedfced635c5c3bd0ec744b5336da94"
            and fingerprints["engine_archive_sha256"] ==
            "c10e4c58b2ff953e69564fb5e37fddc5a105ec00e8e278e1ebeab3de374e6787",
            "examples/raw/kaggle-t4-9b/fingerprints.json: "
            "captured tool or engine archive SHA-256 differs")
    nonce = json.loads(
        (raw_dir / "nonce-control.json").read_text(encoding="utf-8"))
    site_path = raw_dir / "sitecustomize.py"
    require(hashlib.sha256(site_path.read_bytes()).hexdigest() ==
            nonce["sitecustomize_sha256"] and nonce["run_id"] == "44332211",
            "examples/raw/kaggle-t4-9b/sitecustomize.py: "
            "controlled prompt source or run id differs")
    query = (raw_dir / "nvidia-query.stdout.txt").read_text(
        encoding="utf-8").splitlines()
    require(len(query) == 2 and all(", Tesla T4, GPU-" in line
                                    and ", 580.159.04, 15360 MiB, 7.5" in line
                                    for line in query),
            "examples/raw/kaggle-t4-9b/nvidia-query.stdout.txt: "
            "captured two-card T4 machine differs")
    require("22.04.5 LTS" in (raw_dir / "os-release.stdout.txt").read_text(
        encoding="utf-8"),
            "examples/raw/kaggle-t4-9b/os-release.stdout.txt: OS differs")
    require("build 11228" in (raw_dir / "llama-version.stderr.txt").read_text(
        encoding="utf-8"),
            "examples/raw/kaggle-t4-9b/llama-version.stderr.txt: "
            "engine build differs")
    require("CUDA0: Tesla T4" in (raw_dir / "llama-devices.stdout.txt").read_text(
        encoding="utf-8"),
            "examples/raw/kaggle-t4-9b/llama-devices.stdout.txt: "
            "engine did not list a T4")
    done = json.loads((raw_dir / "capture-end.json").read_text(
        encoding="utf-8"))
    require(done["success"] is True and (raw_dir / "SUCCESS.json").is_file(),
            "examples/raw/kaggle-t4-9b/capture-end.json: capture did not finish")

    a, b = gpu["block"], cpu["block"]
    for field in ("chip", "ram", "os", "model", "engine", "ctx",
                  "quant", "settings", "threads", "protocol"):
        require(a[field] == b[field],
                "Kaggle pair differs on receipt {}".format(field))
    require(a["chip"] == "Intel(R) Xeon(R) CPU @ 2.00GHz + Tesla T4 x2"
            and a["os"].startswith("Linux ")
            and a["model"] == "Qwen3.5-9B Q4_K_M"
            and a["engine"] == "llama.cpp b0.5.0-dev"
            and a["ctx"] == 4096,
            "Kaggle receipt identity differs from recorded machine/model")
    require(gpu["model_path"] == cpu["model_path"]
            and gpu["model_path"].endswith("/Qwen3.5-9B-Q4_K_M.gguf"),
            "examples/raw/kaggle-t4-9b/*/pass*.stderr.txt: "
            "model paths do not match")
    for leg, run, args, offload in (
            ("gpu", gpu, ["-ngl", "99"], 33),
            ("cpu", cpu, ["--device", "none", "-ngl", "0"], 0)):
        command = json.loads((raw_dir / (leg + ".command.json")).read_text(
            encoding="utf-8"))
        require(command["returncode"] == (0 if leg == "gpu" else 4)
                and command["argv"][-len(args):] == args
                and command["argv"][0:2] ==
                ["env", "PYTHONPATH=/tmp/picchio-fresh-linux/fixed-nonce"],
                "examples/raw/kaggle-t4-9b/{}.command.json: "
                "capture command or exit differs".format(leg))
        for number, (p, meta, mark) in enumerate(
                zip(run["passes"], run["metas"], run["marks"]), 1):
            stem = "examples/raw/kaggle-t4-9b/{}/pass{}".format(
                leg, number)
            require(p["offload_n"] == offload
                    and p["offload_total"] == 33
                    and p["gpu_device"] == "Tesla T4",
                    stem + ".stderr.txt: CUDA layer placement differs")
            require(meta["ctx"] == 4096
                    and meta["prompt_nonce"] ==
                    "Run 44332211 pass {:02d}. ".format(number)
                    and p["prompt_tokens"] == 776
                    and p["eval_tokens"] == 127,
                    stem + ": prompt, context or token counts differ")
            stderr = (ROOT / (stem + ".stderr.txt")).read_text(
                encoding="utf-8")
            require(re.search(r"I llama_context: n_ctx\s+=\s+4096\b", stderr),
                    stem + ".stderr.txt: engine context differs")
            for mark_field, expected in (
                    ("wall_s", meta["wall_s"]),
                    ("load_s", p["load_ms"] / 1000),
                    ("prompt_s", p["prompt_ms"] / 1000),
                    ("eval_s", p["eval_ms"] / 1000)):
                require(abs(mark[mark_field] - expected) < 0.00001,
                        "examples/raw/kaggle-t4-9b/{}/telemetry.json: "
                        "pass {} {} disagrees with meta/stderr".format(
                            leg, number, mark_field))
    gpu_cmd = json.loads((raw_dir / "gpu.command.json").read_text(
        encoding="utf-8"))
    cpu_cmd = json.loads((raw_dir / "cpu.command.json").read_text(
        encoding="utf-8"))
    prefix_end = gpu_cmd["argv"].index("--keep-logs")
    require(gpu_cmd["argv"][:prefix_end] ==
            cpu_cmd["argv"][:cpu_cmd["argv"].index("--keep-logs")]
            and gpu_cmd["end_utc"] <= cpu_cmd["start_utc"]
            and gpu_cmd["argv"][4] == gpu["model_path"],
            "examples/raw/kaggle-t4-9b/{gpu,cpu}.command.json: "
            "legs were not sequential on one model and engine")
    for number, (p, q) in enumerate(zip(gpu["passes"], cpu["passes"]), 1):
        for field in ("prompt_tokens", "eval_tokens", "threads", "cores",
                      "model_params", "model_size", "sampling", "nonce"):
            require(p[field] == q[field],
                    "Kaggle paired pass {} differs on {}".format(
                        number, field))
    require(gpu["tele"]["src"] == cpu["tele"]["src"] == "nvml"
            and gpu["tele"]["work_med"] >= 30
            and cpu["tele"]["work_med"] <= 5
            and gpu["tele"]["mem_step"] >= 5 * 1024 ** 3
            and cpu["tele"]["mem_step"] < 100 * 1024 ** 2,
            "examples/raw/kaggle-t4-9b/*/telemetry.json: "
            "whole-GPU activity or memory contrast is missing")


def check_linux_27b(run):
    block, passes, metas, marks = (run["block"], run["passes"],
                                   run["metas"], run["marks"])
    require(block["chip"].endswith("GeForce RTX 5090")
            and block["os"].startswith("Linux ")
            and block["model"] == "Qwen3.8-27B Q4_K_M"
            and block["engine"] == "llama.cpp b0.2.0-dev"
            and block["ctx"] == 4096,
            "{}: published Linux 27B identity or context differs".format(
                run["receipt"]))
    require(run["model_path"] == "Qwen3.8-27B-UD-Q4_K_M.gguf"
            and all(p["offload_n"] == p["offload_total"] == 66
                    and p["gpu_device"] == "GeForce RTX 5090"
                    for p in passes),
            "examples/raw/linux-5090-27b/pass*.stderr.txt: CUDA model or "
            "layer placement differs")
    for number, (parsed, meta, mark) in enumerate(
            zip(passes, metas, marks), 1):
        stderr_path = ROOT / "examples" / "raw" / "linux-5090-27b" / \
            "pass{}.stderr.txt".format(number)
        stderr = stderr_path.read_text(encoding="utf-8")
        require(re.search(r"I llama_context: n_ctx\s+=\s+4096\b", stderr),
                "{}: context differs from 4096".format(stderr_path))
        for field in ("prompt_tokens", "eval_tokens", "threads", "cores",
                      "model_params", "model_size", "sampling"):
            require(parsed[field] == passes[0][field],
                    "examples/raw/linux-5090-27b/pass{}.stderr.txt: "
                    "{} differs across passes".format(number, field))
        for mark_field, expected in (("wall_s", meta["wall_s"]),
                                     ("load_s", parsed["load_ms"] / 1000),
                                     ("prompt_s", parsed["prompt_ms"] / 1000),
                                     ("eval_s", parsed["eval_ms"] / 1000)):
            require(abs(mark[mark_field] - expected) < 0.00001,
                    "examples/raw/linux-5090-27b/telemetry.json: pass {} "
                    "{} disagrees with meta/stderr".format(
                        number, mark_field))
    require(block["threads"] == "8/16"
            and block["settings"] ==
            "temp 1.0, top-k 20, top-p 0.95, min-p 0.05, seed 7"
            and block["rates"][1] == 81.5
            and run["tele"]["work_med"] == 92,
            "{}: 27B settings, decode or GPU work differ".format(
                run["receipt"]))


def check_27b():
    path = ROOT / "examples" / "windows-4070s-27b.txt"
    text = path.read_text(encoding="utf-8")
    block = picchio.parse_block(text)
    require(block and block["verdict"] == "PARTIAL OFFLOAD",
            "{}: expected a partial-offload receipt".format(path))
    placement = re.search(r"(\d+)/(\d+) layers on GPU", block["place"])
    remaining = re.search(r"PARTIAL OFFLOAD\. (\d+) layers sat on CPU\.",
                          text)
    require(placement and remaining
            and int(placement[2]) - int(placement[1]) == int(remaining[1]),
            "{}: GPU and CPU layers do not sum to total".format(path))
    require(block["rates"][1] == 5.7,
            "{}: warm decode differs from 5.7 tok/s".format(path))
    return path.relative_to(ROOT), int(placement[2]), int(placement[1]), \
        int(remaining[1]), block["rates"][1]


def main():
    argparse.ArgumentParser(
        description="Recalculate bundled M5, Linux 27B and T4 receipts without GPU or model"
    ).parse_args()
    try:
        gpu = replay("healthy-metal")
        cpu = replay("cpu-fallback")
        check_pair(gpu, cpu)
        for run in (gpu, cpu):
            block, tele = run["block"], run["tele"]
            print("PASS {}: {} ({})".format(
                run["receipt"], run["state"], block["place"]))
            print("  warm prefill / decode / wall: {} / {} / {} tok/s".format(
                *["{:.1f}".format(n) for n in block["rates"]]))
            print("  GPU idle / work: {:.0f}% / {:.0f}%; memory +{:.1f} GiB; "
                  "decode {:.1f} W".format(
                      tele["idle_med"], tele["work_med"],
                      tele["mem_step"] / 1024 ** 3, tele["dec_w"]))
            print("  sources: " + "; ".join(run["sources"]))
        print("PASS recorded pair: Apple M5, 32 GB, same Qwen3.5-9B "
              "model path, llama.cpp b9430, ctx 4096, sampling and "
              "token counts; placement 33/33 vs 0/33 via "
              "--device none -ngl 0")
        print("  boundary: shared machine and file bytes have no "
              "independent fingerprint; OS GPU samples cover the whole "
              "GPU, and the runs differ in placement flags")
        t4_gpu = replay("kaggle-t4-9b-gpu", "kaggle-t4-9b/gpu")
        t4_cpu = replay("kaggle-t4-9b-cpu", "kaggle-t4-9b/cpu")
        check_kaggle_pair(t4_gpu, t4_cpu)
        for run in (t4_gpu, t4_cpu):
            block = run["block"]
            print("PASS {}: {} ({}); warm prefill / decode / wall "
                  "{:.1f} / {:.1f} / {:.1f} tok/s; NVML work {:.0f}%".format(
                      run["receipt"], run["state"], block["place"],
                      *block["rates"], run["tele"]["work_med"]))
            print("  sources: " + "; ".join(run["sources"]))
        print("PASS fresh Linux pair: one author-run Kaggle VM with two "
              "Tesla T4 cards, same Qwen3.5-9B file and engine, ctx 4096, "
              "sampling, and exact per-pass prompt (776 tokens); "
              "placement 33/33 vs 0/33 via --device none -ngl 0")
        print("  captured model SHA-256: "
              "examples/raw/kaggle-t4-9b/fingerprints.json; "
              "prompt control: examples/raw/kaggle-t4-9b/sitecustomize.py")
        print("  boundary: self-run, not an independent user; NVML work is "
              "the busiest card and memory/power sum both whole cards; "
              "the forced-CPU GPU watts are idle draw, not model energy")
        linux = replay("linux-5090-27b")
        check_linux_27b(linux)
        print("PASS {}: {} ({}); warm prefill / decode / wall "
              "{:.1f} / {:.1f} / {:.1f} tok/s; GPU work {:.0f}%".format(
                  linux["receipt"], linux["state"],
                  linux["block"]["place"], *linux["block"]["rates"],
                  linux["tele"]["work_med"]))
        print("  NVML idle / work: {:.0f}% / {:.0f}%; memory +{:.1f} GiB; "
              "work {:.0f} W; decode {:.2f} J/token".format(
                  linux["tele"]["idle_med"],
                  linux["tele"]["work_med"],
                  linux["tele"]["mem_step"] / 1024 ** 3,
                  linux["tele"]["work_w"],
                  linux["tele"]["dec_w"] / linux["block"]["rates"][1]))
        linux_dir = ROOT / "examples" / "raw" / "linux-5090-27b"
        print("  sources: " + "; ".join(
            str((linux_dir / "pass{}.meta.json".format(n)).relative_to(ROOT))
            for n in (1, 2, 3)))
        print("  placement: " + "; ".join(
            source_line(linux_dir / "pass{}.stderr.txt".format(n),
                        "offloaded ") for n in (1, 2, 3)))
        print("  timing: " + "; ".join(
            source_line(linux_dir / "pass{}.stderr.txt".format(n), needle)
            for n in (2, 3)
            for needle in ("prompt eval time =", "eval time =")))
        print("  GPU samples: " + linux["sources"][-1])
        print("  boundary: one recorded Linux CUDA machine; OS GPU samples "
              "cover the whole GPU, not just the model process")
        path, total, on_gpu, on_cpu, decode = check_27b()
        print("PASS {}: {} - {} = {} CPU layers; warm decode "
              "{:.1f} tok/s (receipt arithmetic only; no public "
              "4070 SUPER 27B raw logs to replay)".format(
                  path, total, on_gpu, on_cpu, decode))
        return 0
    except (ReplayError, OSError, KeyError, ValueError, TypeError) as exc:
        print("FAIL receipt replay: {}".format(exc), file=sys.stderr)
        return 1


if __name__ == "__main__":
    sys.exit(main())
examples/healthy-metal.txt
model    Qwen3.5-9B-Q4_K_M.gguf, 8.95 B, 5.28 GiB, llama.cpp b9430
gpu      ENGAGED: 33/33 layers on GPU (Metal: Apple M5)
os       gpu idle 0%, work 99%, mem +6.0 GiB, 11.0 W, 0.52 J/tok
settings temp 0.8, top-k 40, top-p 0.95, min-p 0.05, seed 7
ctx 4096         prefill         decode      wallclock
  cold       584.9 tok/s     21.0 tok/s     13.1 tok/s
  warm mid   588.0 tok/s     21.1 tok/s     15.5 tok/s
  warm span      585~591      21.0~21.2      15.4~15.5
where the cold pass went (9.7 s, 4/10 threads)
  load weights    1.8 s  #####.......................   18%
  prefill         1.3 s  ####........................   13%
  decode          6.1 s  #################...........   62%
  engine misc     0.6 s  ##..........................    6%
HEALTHY. The GPU did the work. Quote the warm median decode:
  21.1 tok/s. 588 tok/s is prefill: reading speed, not writing.
-- picchio v0.1.0 mp1 on Apple M5, 32 GB, macOS 26.5.1
examples/cpu-fallback.txt
model    Qwen3.5-9B-Q4_K_M.gguf, 8.95 B, 5.28 GiB, llama.cpp b9430
gpu      NOT ENGAGED: 0/33 layers on GPU [--device none -ngl 0]
os       gpu idle 8%, work 5%, mem +0.3 GiB, 0.1 W, 0.01 J/tok
settings temp 0.8, top-k 40, top-p 0.95, min-p 0.05, seed 7
ctx 4096         prefill         decode      wallclock
  cold        22.8 tok/s      9.3 tok/s      2.5 tok/s
  warm mid    26.8 tok/s     12.2 tok/s      3.0 tok/s
  warm span        27~27      12.0~12.4        3.0~3.0
where the cold pass went (49.9 s, 4/10 threads, weights cached)
  load weights    2.1 s  #...........................    4%
  prefill        33.4 s  ###################.........   67%
  decode         13.7 s  ########....................   27%
  engine misc     0.8 s  ............................    2%
SILENT CPU FALLBACK. Prefill: 93 s per 2500 tokens.
WHY: forced by flag: --device none -ngl 0
-- picchio v0.1.0 mp1 on Apple M5, 32 GB, macOS 26.5.1
FAQ
Common questions
Discussion
Questions & comments · 0
Sign In Sign in to leave a comment.