
Train domain-specific language models from scratch with full pipeline transparency
Trains a 113M-parameter GPT for earthquake science end to end, from crawling and tokenizing to two-GPU DDP training and streaming inference.
1.0.0Add to Favorites
Why it matters
Build and train a small GPT language model specialized for earthquake science by walking through every stage of the LLM lifecycle-from crawling open-access research papers and general text, through tokenization and model architecture, to distributed training and inference-with every design decision explained and measured.
Outcomes
What it gets done
Crawl and deduplicate 533K documents from six free sources including research papers, arXiv preprints, Wikipedia, and educational web content
Train a custom 16K BPE tokenizer and encode 822.7M tokens optimized for seismology vocabulary mixed with general text
Configure and train a 113M-parameter decoder with GQA, RoPE, and 4096-token context across 2 GPUs using DDP
Deploy streaming inference with KV-cache and measure fluency improvements from domain-general text mixing
Source
Get it from source
Spark does not host a copy of it.
Open sourceReports
Agent outcome reports
No reports yet
Overview
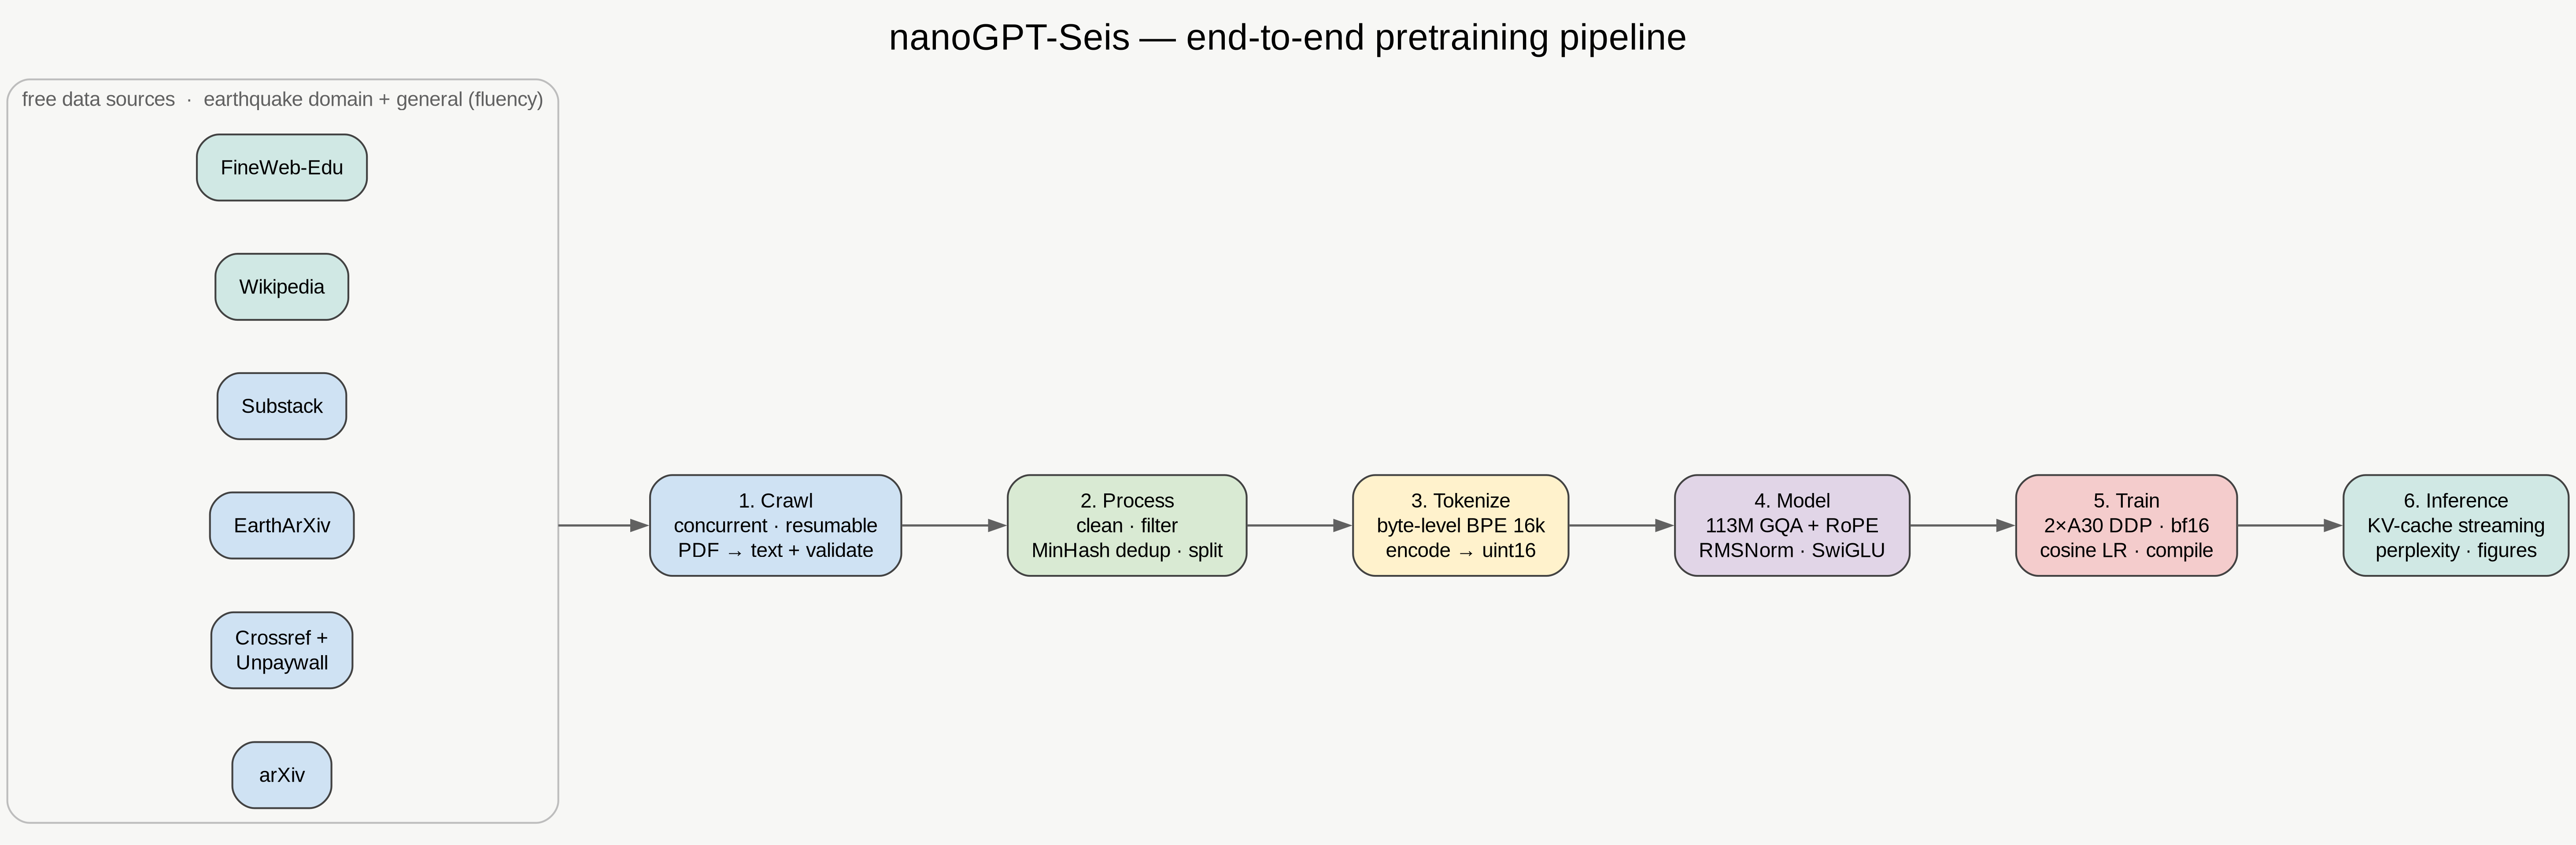
nanoGPT-Seis trains a small GPT for earthquake science and walks through the entire LLM lifecycle, from a blank folder to a talking model, block by block. The stages are crawl, clean, tokenize, model, train and infer, run on two NVIDIA A30 GPUs. Use it to learn how pretraining works end to end, or to run a small model on one node. Base pretraining alone never yields chat.
What it does
nanoGPT-Seis trains a small GPT for earthquake science and covers the entire LLM lifecycle, from a blank folder to a talking model, block by block: crawl, clean, tokenize, model, train, infer. Six free data sources feed a crawl and clean/dedup stage, a 16k byte-level BPE tokenizer, a 113M-parameter decoder-only model with grouped-query attention, rotary position embeddings, RMSNorm and SwiGLU, two-GPU DDP training and streaming inference.
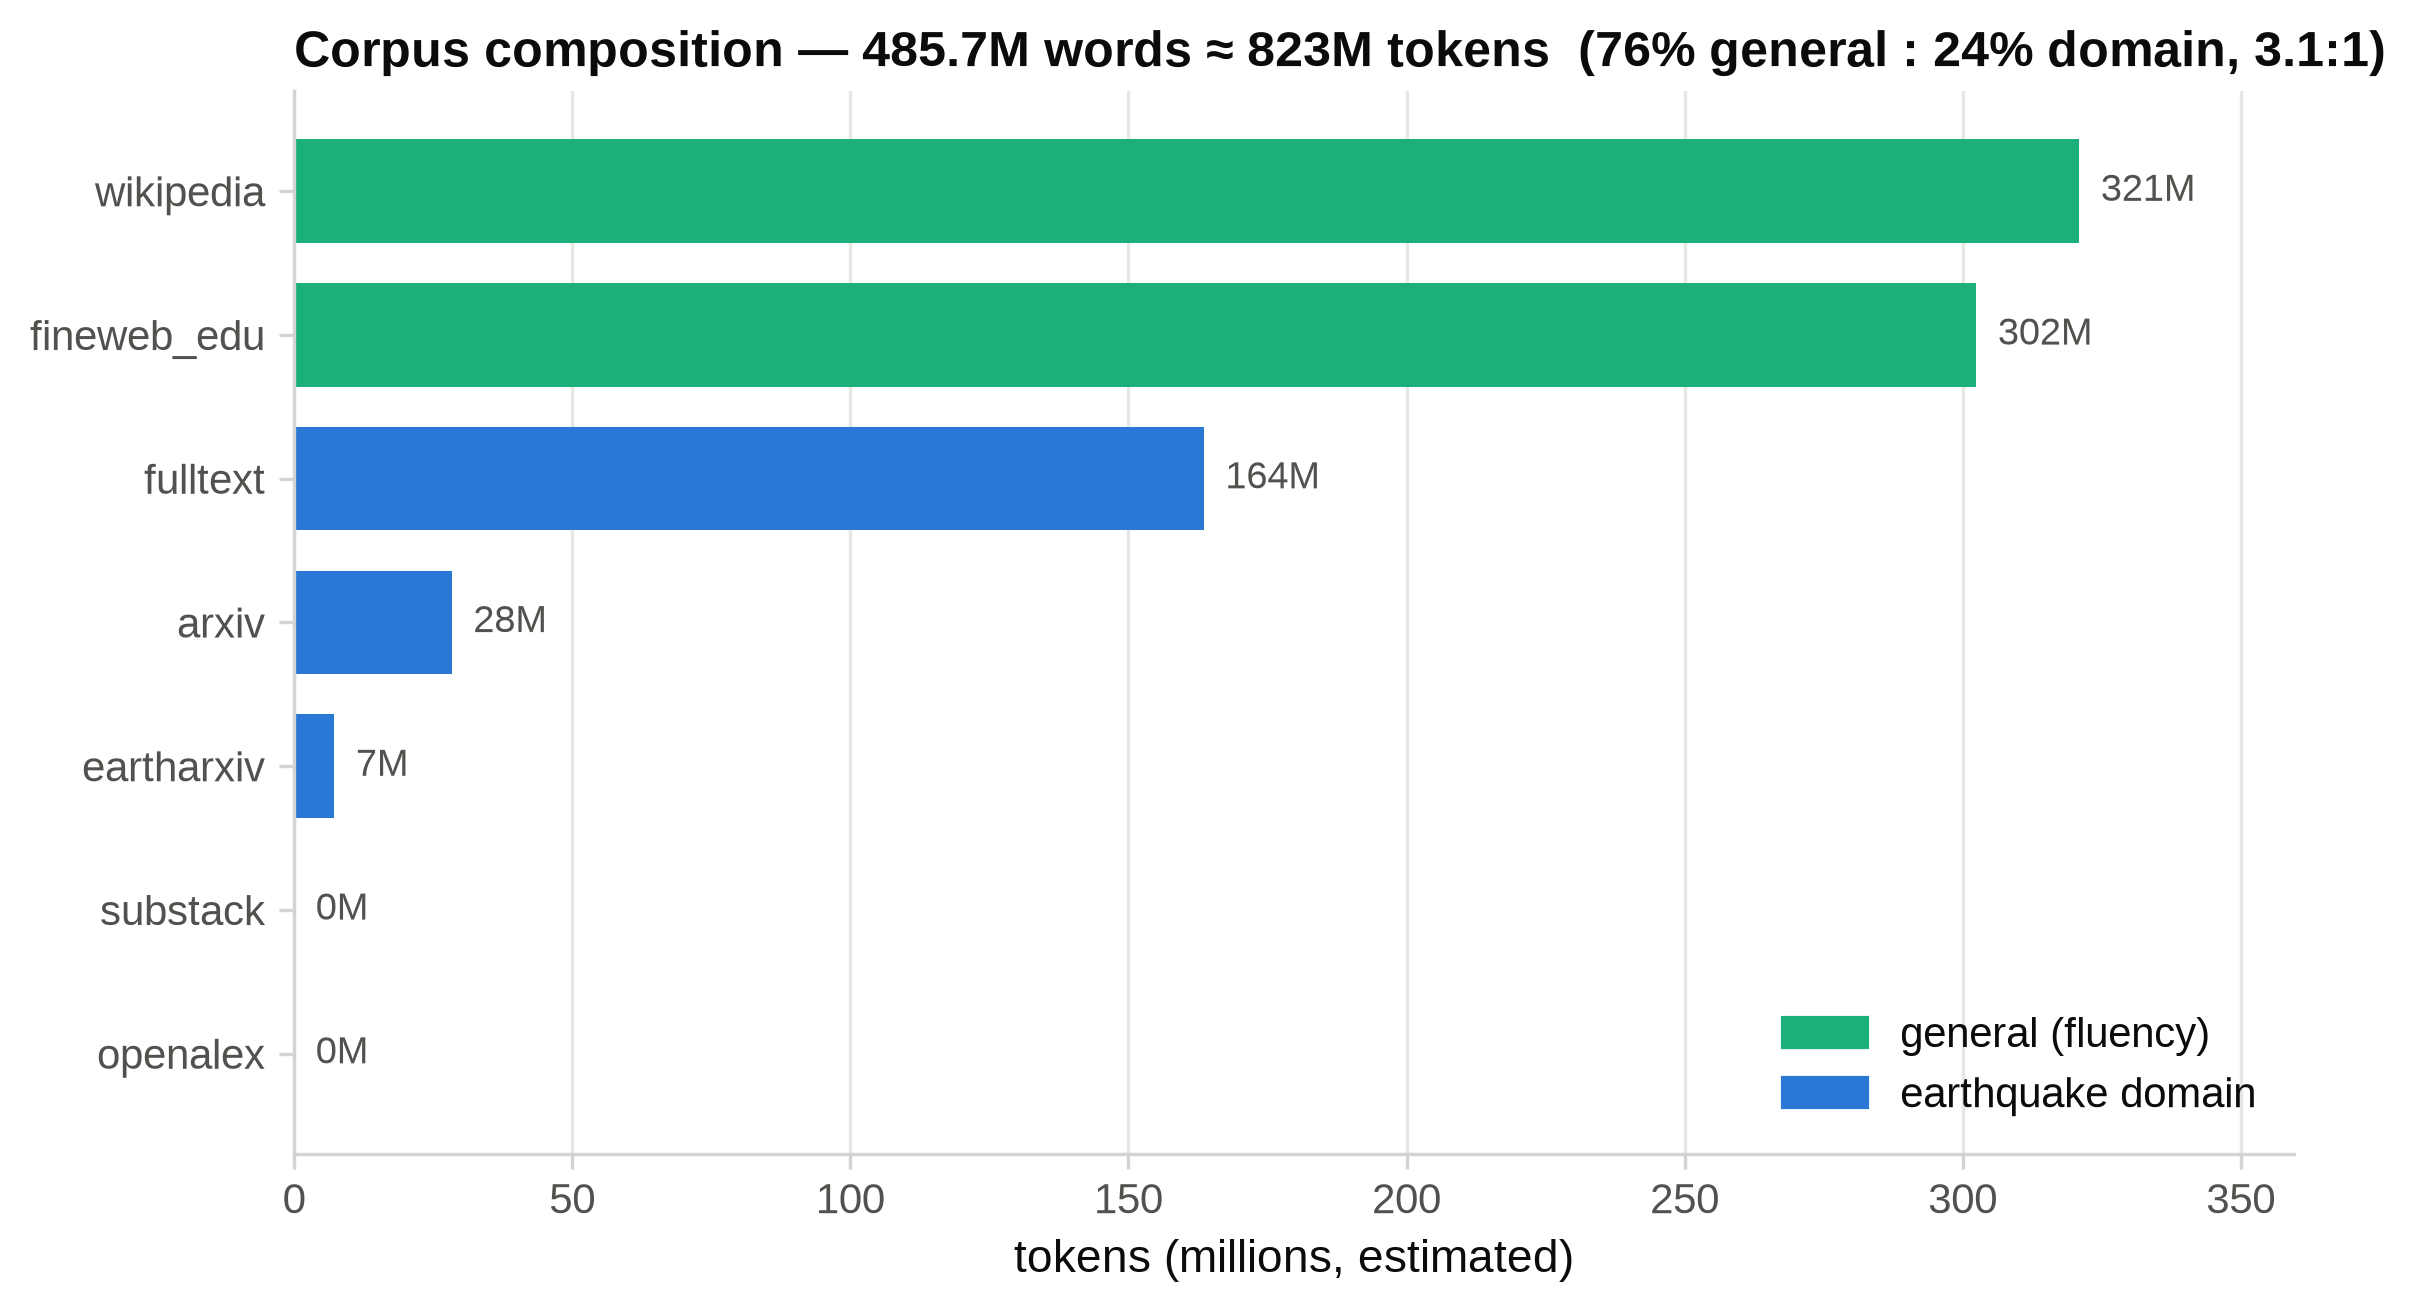
Data. The corpus mixes earthquake and seismology text with general text for plain-language fluency. The domain side is open-access research papers (Crossref DOIs, then Unpaywall for the open-access PDF), arXiv and EarthArXiv preprints (arXiv API plus OSF/DOI), Wikipedia pages titled earthquake (MediaWiki API plaintext extracts) and the Earthquake Insights Substack (archive API plus HTML body parse). The general side is Wikipedia and FineWeb-Edu, streamed through Hugging Face datasets to a token budget. A model trained only on research papers becomes fluent in paper register but repetitive and incoherent in plain prose. The result is 533,248 documents, 485.7M words and 822.7M training tokens, at about 2.4 to 1 general to domain. Every document is normalized to one schema with source, id, title, text, url, date and an extra dict.
Crawling. Crossref pages through earthquake journal articles with a deep cursor (no offset limit), filtered by journal ISSN; each request carries a mailto contact email parameter. Unpaywall (free, about 100k per day) maps each DOI to its legal open-access copies; repository (green OA) locations are tried first because publisher links are frequently bot-blocked stubs. Downloads run in a thread pool with a per-host throttle, so different servers download concurrently while any single server stays rate-limited. A download is accepted only if it starts with the PDF magic bytes, has at least two pages and yields enough extracted text, since many open-access PDFs are 5 KB anti-bot landing pages. A low-yield abort gate skips a journal once its hit rate stays under a threshold, so mostly paywalled journals such as Science and Nature do not burn the Unpaywall budget. Output is appended line by line and already-fetched ids are skipped on restart, so a multi-hour crawl survives interruption. Full-text yield is about 99 percent for arXiv, about 15 percent for the broad open-access pool and about 0 percent for paywalled journals (abstract fallback), for roughly 20k full-text papers plus 26k abstracts.
Cleaning and filtering. Cleaning is source-aware: HTML unescape, NFKC normalization, control byte removal and whitespace collapse, plus PDF line-break de-hyphenation and reference-section stripping (truncating at the last References or Bibliography heading). Three filters follow: drop documents under 200 characters; an English ratio, the fraction of tokens that are common English stopwords, which drops the Spanish-translated Substack posts without a language-ID dependency; and an alpha ratio, the fraction of letters and spaces, which drops garbled PDF tables and math dumps.
Deduplication. Deduplication runs the cheapest test first. The exact pass lowercases and collapses whitespace, then keys each document on one SHA-1. The near-duplicate pass turns each document into word 5-gram shingles, estimates similarity with 128-permutation MinHash signatures and buckets them with LSH so only likely-similar documents are compared; a document is dropped when a document at least 70 percent similar is already kept, and documents are processed longest first so the fullest version survives. Signatures are computed across a process pool while the LSH insert and query stay serial. On the real corpus this removed 1,126 exact and 304 near duplicates. The documents are then shuffled with a fixed seed and split into train and validation sets.
Tokenizer. The tokenizer is a byte-level BPE trained from scratch, with the 256 raw bytes as its base alphabet, so there are no unknown tokens. The vocabulary is 16,384 tokens against GPT-2's 50,257, which keeps the embedding matrix small, and compression on the corpus is about 3.9 characters per token. The single special end-of-text token marks document boundaries. Token ids are stored as uint16 shards, 822.7M tokens taking about 1.6 GB, memory-mapped by the training loader. The file does not depend on context length, which is why moving from 1024 to 4096 needed no re-tokenization.
Model. The model follows Llama-style choices: RMSNorm over LayerNorm (no mean subtraction, no bias), RoPE over learned positions, GQA with 12 query heads sharing 4 KV heads for a 3 times smaller KV cache at nearly no quality cost, SwiGLU over a GELU MLP, weight tying that saves 12.6M parameters, and no biases. Blocks are pre-norm, where the residual path is an unbroken identity highway for gradients; the cost is that the residual stream's variance grows with depth, which the initialization offsets. RoPE rotates each query and key channel pair by an angle proportional to position, with no learned parameters, so the query-key score depends only on relative distance; the model uses the real-valued rotate_half form. Attention divides scores by the square root of the head width to keep softmax from saturating, uses a causal mask, and costs O(T squared) in time and in score-matrix memory. FlashAttention removes the memory term: it tiles Q, K and V into blocks that fit in on-chip SRAM and uses an online softmax with a running max, normalizer and output, so the score matrix never reaches main GPU memory. That is what makes a 4096-token context affordable on a 24 GB card. Weights start at Normal(0, 0.02); the attention output and SwiGLU down projections that write into the residual stream are scaled by 1/sqrt(2 x n_layer); RMSNorm gains start at 1. A correctly wired model should start at a loss near ln(16384), about 9.70, and this one starts at 9.85.
Training. torchrun starts one process per GPU; DistributedDataParallel keeps a model replica on each and all-reduces gradients before the optimizer step, with torch.compile and the nccl backend. Gradient accumulation syncs gradients only on the last micro-batch, so the in-between backward passes skip the all-reduce, and gradient norm is clipped at 1.0. Global batch is batch 4 x grad_accum 12 x 2 GPUs x 4096 context, 393,216 tokens per iteration. bf16 autocast halves memory and doubles throughput versus fp32 with no loss scaling needed.
When to use - and when NOT to
Use it to learn the whole pretraining loop, from crawling through DDP training and inference. A focused corpus lets a roughly 100M-parameter model become fluent on a single node, so the whole loop closes in a day, not a month.
Model and data mix. The model has 113M parameters, a 4096-token context and trains for 8,000 iterations (about 3.8 epochs). A domain-only (v1) base is repetitive and incoherent in plain prose. Adding about 540M tokens of Wikipedia and FineWeb-Edu brings training to about 823M tokens, roughly 3.8 epochs, within the roughly 4-epoch repeat budget shown to be near-lossless. That mix (v2) generates coherent non-earthquake text where v1 emits gibberish, at the cost of some domain sharpness. The domain-only weights are kept as checkpoints/ckpt_v1_domain.pt. Inference is KV-cached and streaming with an anti-repeat sampler. Base pretraining alone never yields a chat model.
Inputs and outputs
Hardware is two NVIDIA A30 GPUs (24 GB each, bf16, DDP), though it also runs on a single RTX 3090 or 4090, or on 12 to 16 GB with a smaller batch. The model config in configs/gpt120m_ctx4k.yaml uses 16 layers, d_model 768, 12 heads with 4 KV heads (GQA 12 to 4), a block size of 4096, vocabulary 16384 and a SwiGLU hidden size of 2048, about the GPT-2-small shape and roughly 113M parameters. The head dimension is 64, the size FlashAttention is tuned for, and the SwiGLU hidden size follows the Llama 8/3 times d rule rounded to a multiple of 256.
The pipeline runs as modules. Crawlers are src.crawl.wikipedia (--max-pages 500), fulltext (--per-journal 3000 --broad 30000 --workers 64), preprints (--arxiv 3000 --eartharxiv 2000), substack (--max 500) and general (--wiki-tokens 300000000 --fineweb-tokens 240000000, about 540M tokens). src.process.build_corpus --val-frac 0.005 cleans, dedups and splits; src.tokenizer.train_bpe --vocab-size 16384 trains the tokenizer; src.tokenizer.encode writes uint16 shards; torchrun --standalone --nproc_per_node=2 -m src.train --config configs/gpt120m_ctx4k.yaml trains on two GPUs; src.inference --prompt streams generation.
A common pitfall: a PyTorch built for a newer CUDA than your driver silently reports cuda.is_available() == False and falls back to CPU, so verify that python -c "import torch; print(torch.cuda.is_available())" prints True. This setup uses torch 2.6.0+cu124 to match a CUDA 12.5 driver.
Integrations
The pretrained 113M checkpoint is hosted on the Hugging Face Hub as jiazhe868/nanogpt_seis. Use a working CUDA 12.4 PyTorch environment, download the checkpoint, tokenizer, metadata and config into the paths src/inference.py expects, then generate:
conda activate nanogpt_seis
pip install -r requirements.txt
huggingface-cli download jiazhe868/nanogpt_seis \
    checkpoints/ckpt.pt \
    data/tokenized/tokenizer.json \
    data/tokenized/meta.json \
    configs/gpt120m_ctx4k.yaml \
    --local-dir .
python -m src.inference --prompt "The 2011 Tohoku earthquake"
Data is fetched through the Crossref and Unpaywall APIs, arXiv and OSF, the MediaWiki API, the Substack archive API and Hugging Face datasets streaming.
Source README
🌍 nanoGPT-Seis
English | 中文 | 🎯 Post-Training (SFT & GRPO RL) | 🤗 Hugging Face Base Model
Train a small GPT for earthquake science - the entire LLM lifecycle, from a blank folder to a talking model, explained block by block.
Crawl → Clean → Tokenize → Model → Train → Infer, on 2× NVIDIA A30 (48 GB).
🚀 Phase II & Phase III Post-Training Available: Looking for Supervised Fine-Tuning (SFT) and Verifier Reinforcement Learning (GRPO RLVR)? Check out the post-training code repository: nanoGPT-Seis-Posttrain and fine-tuned model weights on Hugging Face.
nanoGPT-Seis is a teaching repository. It is not trying to be a great earthquake model - it is trying to make every stage of pretraining a language model legible: where the data comes from, how it is cleaned and deduplicated, how a tokenizer is built, why the Transformer looks the way it does, how it is trained across two GPUs, and how it is served. Every design decision is explained, and every number (perplexity, VRAM, tokens) is one we actually measured on this hardware.
The corpus mixes earthquake / seismology text (open-access papers via Crossref+Unpaywall, arXiv/EarthArXiv preprints, the "Earthquake Insights" Substack) with general text (Wikipedia + FineWeb-Edu) for plain-language fluency - about 24% domain / 76% general. A focused corpus lets a ~100M-param model become genuinely fluent on a single node, so you can see the whole loop close in a day, not a month. (Why the general mix? See §1.)
Status: the pretraining lifecycle is complete - crawl through inference.
Table of contents
- Results at a glance
- Quick start
- Stage 1 - Data crawling
- Stage 2 - Processing & dedup
- Stage 3 - The BPE tokenizer
- Stage 4 - The model (RoPE, GQA, …)
- Stage 5 - Training (DDP, VRAM, LR)
- Stage 6 - Inference
- Repository layout
- Scaling-law experiments
1. Results at a glance
| value | |
|---|---|
| Corpus | 533,248 docs · 485.7M words · 822.7M training tokens (≈2.4:1 general:domain) |
| Model | 113M params - decoder-only, GQA + RoPE + RMSNorm + SwiGLU |
| Hardware | 2× NVIDIA A30 (24 GB each), bf16, DDP - also runs on a single RTX 3090/4090, or 12-16 GB with a smaller batch (§7.5) |
| Context length | 4096 tokens |
| Training | 8,000 iters (~3.8 epochs), ~6.5 h, ~2.9 s/iter |
| Fluency (bits/byte, general text) | 0.997 - vs 1.527 for a domain-only base (−35%) |
| Inference | KV-cached streaming, ~176 ms to first token, anti-repeat sampler |
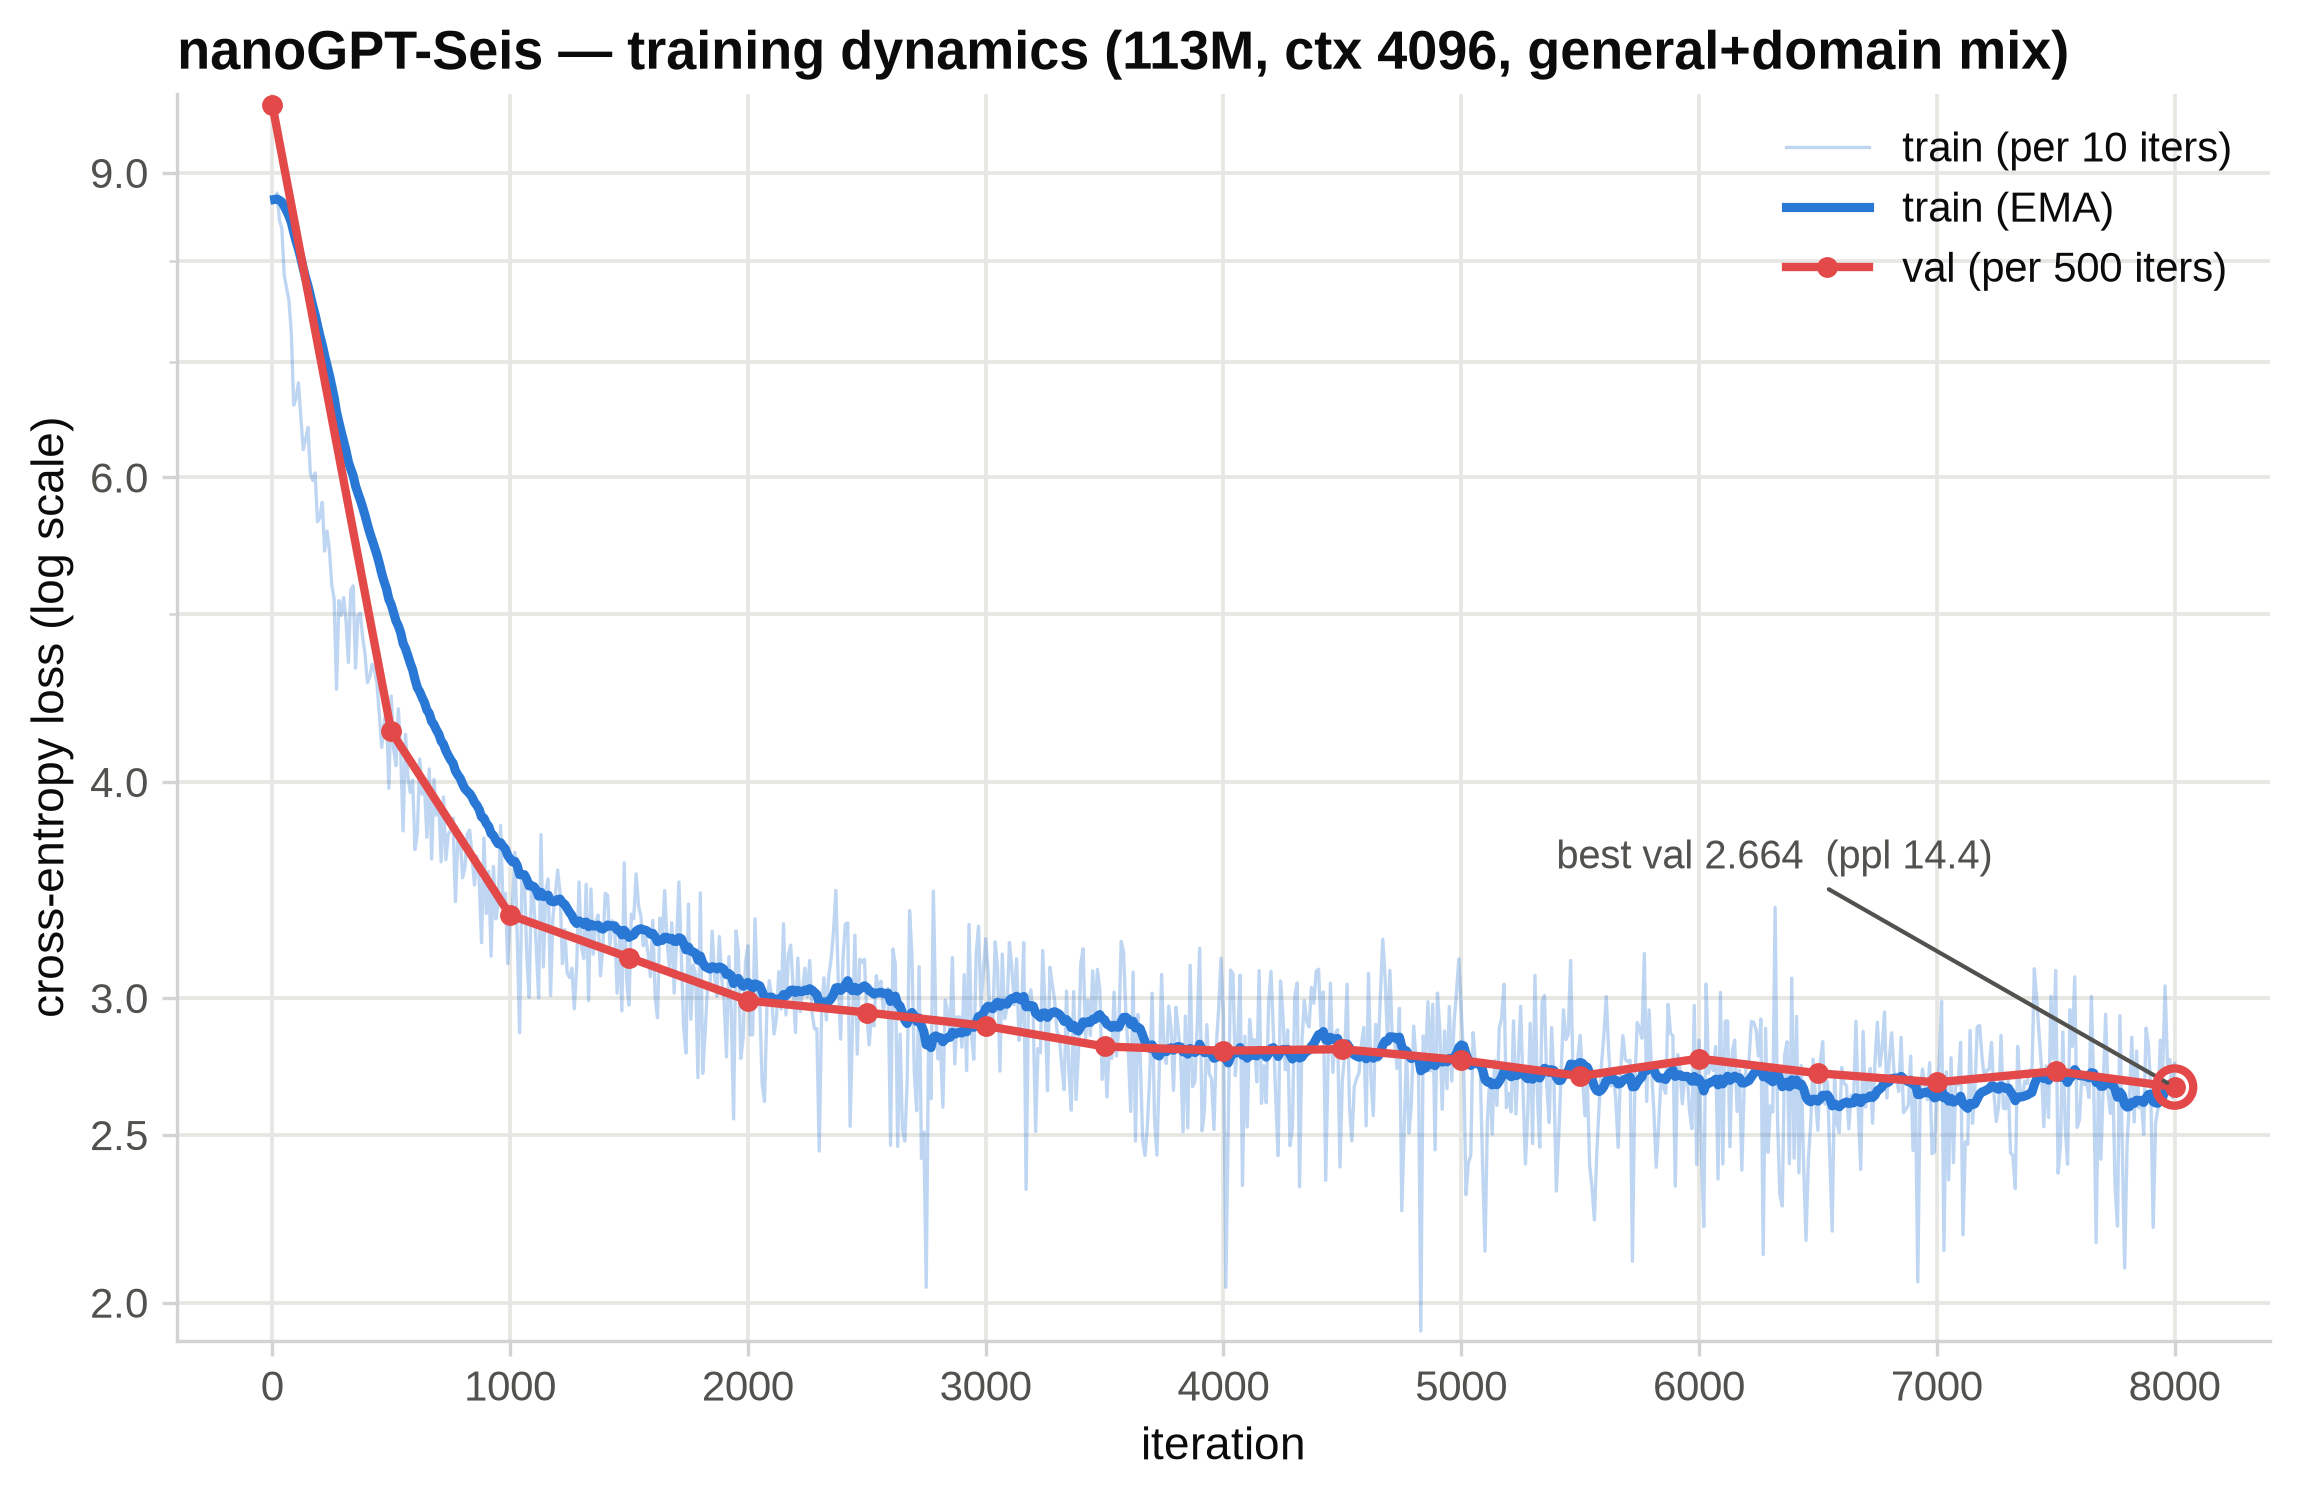
Three findings worth pausing on:
- Longer context helped. A controlled A/B (data held fixed) - retraining at 4096 vs 1024 dropped perplexity ~11% (9.74 → 10.93 domain-only) for only ~26% more compute per step - papers have long-range structure a 1024-token window can't see across.
- The model uses that context. In a 4096-token window, loss on tokens at positions 2048-4096 is 25% lower than at 0-64 - it conditions on thousands of preceding tokens (see §8).
- A general-text mix restores fluency. Adding Wikipedia + FineWeb-Edu (~2.4:1 general:domain) cut bits/byte on general prose by 35% vs a paper-only base - see the data-mix comparison below.
Data mix: domain-only (v1) → general + domain (v2)
A paper-only base is fluent in paper-register but repetitive/incoherent in plain prose. Adding ~540M tokens of Wikipedia + FineWeb-Edu (→ ~823M train tokens, ~2.4:1 general:domain, ~3.8 epochs - within the ~4-epoch repeat budget shown to be near-lossless by Muennighoff et al., 2023) gives v2.
Measured with bits-per-byte (tokenizer-independent, so v1↔v2 is fair;
src/compare_models.py):
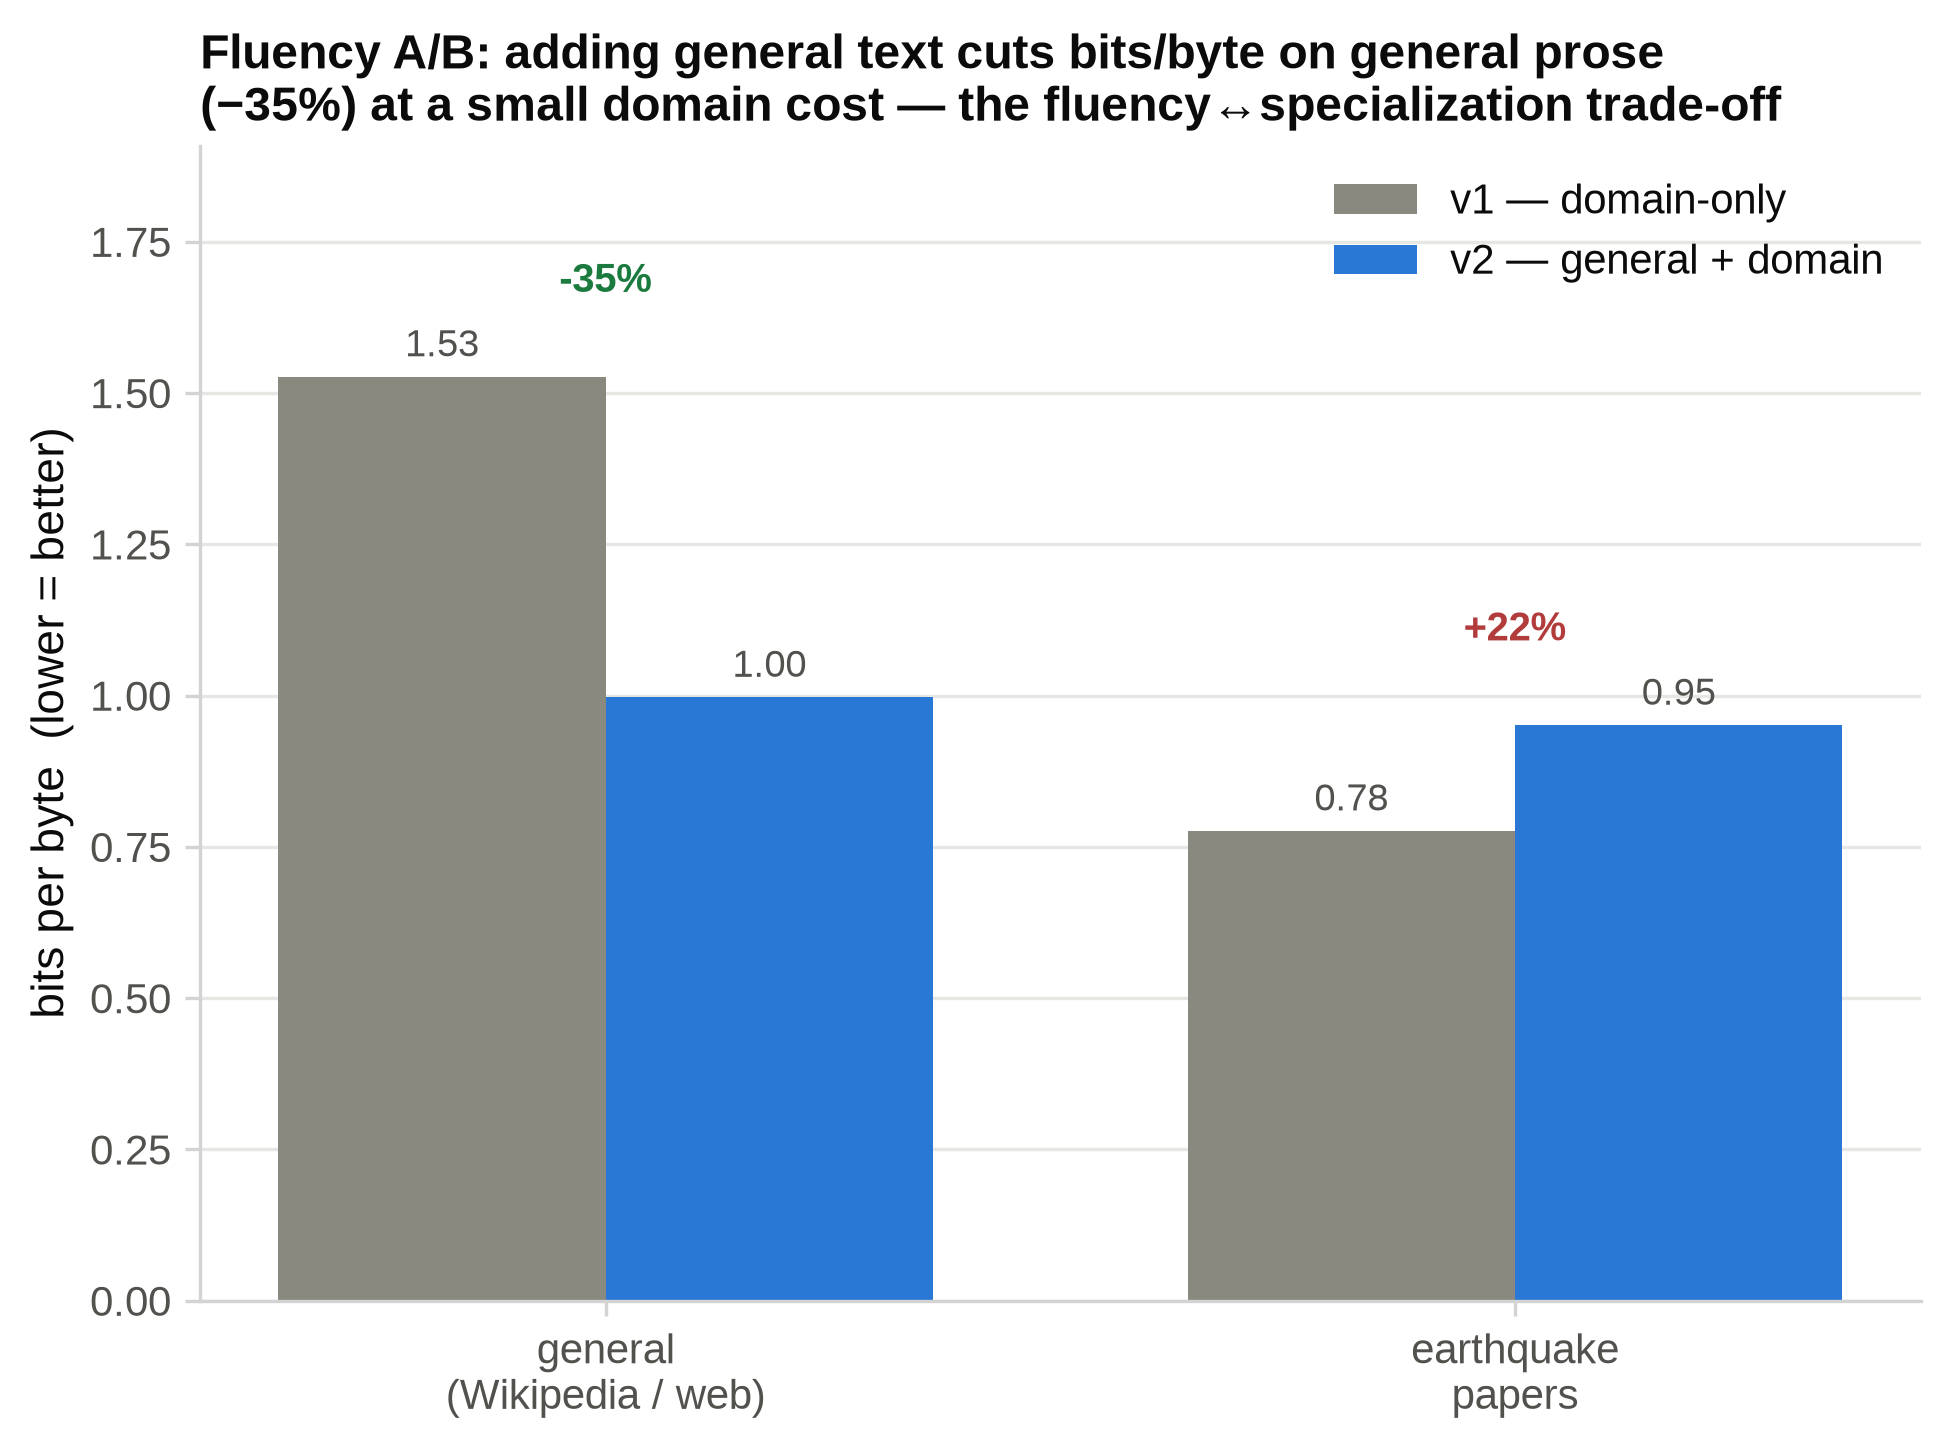
v2 is far more fluent on general prose (−35% bits/byte) and generates coherent
non-earthquake text where v1 emits gibberish, at the cost of some domain sharpness
(+22%) - the classic fluency↔specialization trade-off. This fluent base is the
right starting point for SFT; base pretraining alone never yields chat. Domain-only
weights are kept as checkpoints/ckpt_v1_domain.pt.
2. Quick start
2.1 Try the pretrained model
The pretrained 113M checkpoint is hosted on the Hugging Face Hub:
jiazhe868/nanogpt_seis.
# environment (a working CUDA-12.4 PyTorch; see the note below)
conda activate nanogpt_seis
pip install -r requirements.txt

# download the checkpoint, tokenizer, and model config into the paths expected by
# src/inference.py
huggingface-cli download jiazhe868/nanogpt_seis \
    checkpoints/ckpt.pt \
    data/tokenized/tokenizer.json \
    data/tokenized/meta.json \
    configs/gpt120m_ctx4k.yaml \
    --local-dir .

python -m src.inference --prompt "The 2011 Tohoku earthquake"
2.2 Reproduce pretraining from scratch
# environment (a working CUDA-12.4 PyTorch; see the note below)
conda activate nanogpt_seis
pip install -r requirements.txt

# --- run the whole pipeline ---
# earthquake-domain sources
python -m src.crawl.wikipedia        --max-pages 500                              # earthquake-titled pages
python -m src.crawl.fulltext         --per-journal 3000 --broad 30000 --workers 64
python -m src.crawl.preprints        --arxiv 3000 --eartharxiv 2000
python -m src.crawl.substack         --max 500
# general-text mix for fluency (~540M tokens: Wikipedia + FineWeb-Edu)
python -m src.crawl.general          --wiki-tokens 300000000 --fineweb-tokens 240000000

python -m src.process.build_corpus   --val-frac 0.005      # clean · dedup · split
python -m src.tokenizer.train_bpe    --vocab-size 16384    # train the tokenizer
python -m src.tokenizer.encode                             # → uint16 shards

torchrun --standalone --nproc_per_node=2 \
    -m src.train --config configs/gpt120m_ctx4k.yaml       # train on 2 GPUs

python -m src.inference --prompt "The 2011 Tohoku earthquake"   # streams live
⚠️ Environment gotcha. A PyTorch built for a newer CUDA than your driver will silently report
cuda.is_available() == Falseand fall back to CPU. Verify withpython -c "import torch; print(torch.cuda.is_available())"- it must printTrue. This project usestorch 2.6.0+cu124to match a CUDA-12.5 driver.
3. Stage 1 - Data crawling
Goal: assemble a large, legal, full-text earthquake corpus from free sources.
Code: src/crawl/.
3.1 The sources and how each is fetched
| source | module | what we pull | mechanism |
|---|---|---|---|
| Research papers | fulltext.py |
OA full-text PDFs of earthquake papers | Crossref (DOIs) → Unpaywall (OA PDF) → download → extract |
| Preprints | preprints.py |
arXiv + EarthArXiv full text | arXiv API + OSF/DOI → PDF |
| Wikipedia | wikipedia.py |
pages titled "earthquake" | MediaWiki API plaintext extracts |
| Substack | substack.py |
"Earthquake Insights" articles | archive API + HTML body parse |
| General text | general.py |
Wikipedia + FineWeb-Edu (fluency mix) | HF datasets streaming to a token budget |
Why a general-text mix? A ~113M model trained only on research papers becomes fluent in paper-register but repetitive and incoherent in plain prose, and 240M tokens is far below compute-optimal (Hoffmann et al., 2022). So we add ~240M tokens of Wikipedia (encyclopedic) + FineWeb-Edu (Penedo et al., 2024; quality-filtered educational web) for a ~1:1 general:domain mix - a fluent base that the planned SFT stage can then make conversational. (Base pretraining alone never yields chat; that's SFT.)
Every document is normalized to one schema (src/crawl/common.py):
@dataclass
class Doc:
    source: str          # "fulltext" | "arxiv" | "wikipedia" | ...
    id: str              # stable per-source id (used for dedup)
    title: str
    text: str            # the cleaned body we will tokenize
    url: str = ""
    date: str = ""
    extra: dict = field(default_factory=dict)   # venue, cited_by, full_text, ...
3.2 How the web crawling actually works
Finding the papers (Crossref). Crossref indexes ~150M scholarly works with a free, generous API. We page through earthquake journal-articles with a deep cursor (no offset limit), filtered by journal ISSN:
# src/crawl/fulltext.py — iter_crossref()
params = {"rows": 1000, "cursor": cursor,
          "filter": "type:journal-article,issn:0094-8276",   # e.g. GRL
          "query.bibliographic": "earthquake", "mailto": EMAIL}
Finding the open PDF (Unpaywall). A DOI is not a PDF. Unpaywall (free, ~100k/day) maps a DOI to its legal open-access copies. We try repository (green OA) locations first - publisher links are frequently bot-blocked stubs:
# repository copies download far more reliably than publisher links
prio = 0 if loc.get("host_type") == "repository" else 1
Downloading in parallel, politely. PDFs come from many hosts, so we use a thread pool but throttle per host - different servers download concurrently while any single server stays rate-limited:
class HostThrottle:                 # src/crawl/fulltext.py
    def wait(self, host):
        with self._guard:                                  # get/create this host's lock
            host_lock = self._locks.setdefault(host, threading.Lock())
            self._last.setdefault(host, 0.0)
        with host_lock:                                    # serialize only this host
            delta = self.min - (time.monotonic() - self._last[host])
            if delta > 0: time.sleep(delta)
            self._last[host] = time.monotonic()
Validating every download. Not every "OA PDF" is real - many are 5 KB anti-bot landing pages. We accept a download only if it is a real PDF with enough text:
if not pdf_bytes.startswith(b"%PDF"): return None   # HTML / stub
if doc.page_count < 2:                return None    # cover page
if len(text) < min_chars:             return None    # too little extracted
Not wasting the budget. Some journals (Science, Nature) are almost entirely paywalled - scanning thousands of their DOIs would burn the Unpaywall budget for zero full text. A low-yield abort gate skips a journal once its hit-rate stays under a threshold:
if scanned >= abort_after and got_ft / max(1, scanned) < min_hit:
    break        # this venue isn't worth more API calls
Resumable. Output is appended line-by-line and already-fetched ids are skipped on restart, so a multi-hour crawl survives interruption:
done = _load_done_ids(out)          # ids already in the JSONL
...
if iid in done: continue            # skip work we already have
War story (why Crossref + Unpaywall). This project originally enumerated papers via OpenAlex, which changed to a paid credit model mid-build - the free daily budget ran out after ~100 requests. Crossref + Unpaywall is the free, robust replacement, and it is what the code ships with. The lesson - pin your data source assumptions and make the crawler resumable - is baked into the design.
Full-text yield varies a lot by source: arXiv ~99% (open by design), the broad OA pool ~15%, paywalled journals ~0% (abstract fallback). Net corpus: ~20k full-text papers + ~26k abstracts.
3.3 The general pattern - a thread-safe BFS crawler
The crawler above is API-driven, but the shape underneath is the classic one: a breadth-first traversal of a link graph, run across many threads. It is worth writing that general pattern out in full, because getting the concurrency right is the hard part. The crux is shared state that every worker touches at once - a frontier of URLs still to visit, and a set of URLs already seen.
Three rules make it correct:
- The frontier is a
queue.Queue, which is internally synchronised:get()andput()are atomic, andget()blocks until work exists, so workers never busy-wait. - The seen-set gets its own lock. "Is this URL new? if so, add it" is a read-modify-write; without the lock two threads can both judge the same URL new and enqueue it twice.
- Termination uses
Queue.join()/task_done(). The hard question in a concurrent BFS is knowing when you are done: a worker finding the frontier momentarily empty does not mean the crawl is finished, because another worker may be one instruction away from enqueuing more links.join()counts outstanding tasks and only releases once every enqueued URL has been fully processed.
import re, threading, queue, requests
from urllib.parse import urljoin, urldefrag, urlparse

class BFSCrawler:
    """Breadth-first web crawler: one shared frontier, N worker threads."""

    def __init__(self, seeds, max_pages=5000, n_workers=16, min_interval=1.0):
        self.frontier   = queue.Queue()          # thread-safe BFS queue of (url, depth)
        self.seen       = set(seeds)             # every URL ever enqueued
        self.seen_lock  = threading.Lock()       # guards `seen` (check-then-add races)
        self.pages      = []                     # kept (url, html) pairs
        self.pages_lock = threading.Lock()       # guards `pages` + the page counter
        self.max_pages  = max_pages
        self.n_workers  = n_workers
        self.throttle   = HostThrottle(min_interval)   # §3.2 — politeness, per host
        for s in seeds:
            self.frontier.put((s, 0))            # seed the frontier at depth 0

    def _links(self, base, html):                # extract absolute, de-fragmented links
        for m in re.finditer(r'href=["\'](.*?)["\']', html):
            url, _ = urldefrag(urljoin(base, m.group(1)))   # relative → absolute, drop #frag
            if url.startswith(("http://", "https://")):
                yield url

    def _enqueue(self, url, depth):
        with self.seen_lock:              # the check AND the add are ONE critical section,
            if url in self.seen:          # else two threads both see `url` as new and
                return                    # enqueue it twice
            self.seen.add(url)
        self.frontier.put((url, depth))

    def _worker(self):
        while True:
            url, depth = self.frontier.get()      # blocks; (None, _) is the stop sentinel
            if url is None:
                self.frontier.task_done()
                return
            try:
                with self.pages_lock:
                    if len(self.pages) >= self.max_pages:
                        continue                  # budget spent — drain the rest quietly
                self.throttle.wait(urlparse(url).netloc)      # rate-limit this host
                html = requests.get(url, timeout=10).text
                with self.pages_lock:
                    if len(self.pages) >= self.max_pages:
                        continue
                    self.pages.append((url, html))
                for link in self._links(url, html):           # BFS: expand the frontier
                    self._enqueue(link, depth + 1)
            except Exception:
                pass                              # one dead link must not kill a worker
            finally:
                self.frontier.task_done()         # pairs with the get() above

    def run(self):
        workers = [threading.Thread(target=self._worker, daemon=True)
                   for _ in range(self.n_workers)]
        for t in workers:
            t.start()
        self.frontier.join()                      # wait until the frontier is truly drained
        for _ in workers:                         # then release the idle, blocked workers
            self.frontier.put((None, 0))
        for t in workers:
            t.join()
        return self.pages
ThreadPoolExecutor reaches the same result with less bookkeeping - submit _worker
n_workers times and let the pool own the threads - but spelling out the
Queue.join() handshake is what makes the termination logic visible.
This repo's fulltext.py is a one-hop specialisation of exactly this skeleton: the
frontier is the list of DOIs Crossref returns, each is "expanded" not into page
out-links but into its Unpaywall PDF locations, and the shared guarded state is the
resume-set of already-fetched ids rather than a seen set of URLs. The thread pool and
the per-host throttle are identical. A full multi-hop BFS would instead follow
<a href> links, which is the version above.
4. Stage 2 - Processing & dedup
Code: src/process/. Turns messy data/raw/*.jsonl into clean train/val splits.
4.1 Cleaning (source-aware) - clean.py
def normalize(text):
    text = html.unescape(text)                 #
 & → real chars
    text = unicodedata.normalize("NFKC", text) # fi ligatures, full-width, …
    text = _CTRL_RE.sub("", text)              # strip control bytes
    text = _MULTISPACE_RE.sub(" ", text)       # collapse whitespace
    ...
PDFs get extra care: line-break de-hyphenation (earth-\nquake → earthquake) and
reference-section stripping (truncate at the last "References"/"Bibliography"
heading - the bibliography is noise for a language model).
4.2 Quality filtering
Three cheap, effective filters (passes_filters):
- length - drop < 200 chars;
- English ratio - fraction of tokens that are common English stopwords; drops the Spanish-translated Substack posts without a language-ID dependency;
- alpha ratio - fraction of letters/spaces; drops garbled PDF tables and math dumps.
4.3 Deduplication - dedup.py
Duplicate training data measurably hurts language models (Lee et al., 2021) - repeated documents get over-memorised and waste the token budget. But comparing every document against every other is O(N²) and reads every byte, so good dedup is an exercise in doing the cheap test first: eliminate non-candidates with progressively more expensive checks, and pay the expensive one only on what survives.
The cascade, in its classic form. The same idea drives the textbook "find duplicate files on disk" problem. Two files can only be identical if they have the same size; of the same-size files, only those whose first kilobyte also matches can be identical; and only those earn a full-content hash. Each tier is strictly more expensive than the last and runs on strictly fewer inputs:
import os, hashlib
from collections import defaultdict

def find_duplicate_files(root: str) -> list[list[str]]:
    def file_hash(path: str, first_chunk_only=False, chunk=8192) -> str:
        h = hashlib.md5()
        try:
            with open(path, "rb") as f:
                if first_chunk_only:
                    h.update(f.read(1024))                    # cheap: one small read
                else:
                    for block in iter(lambda: f.read(chunk), b""):
                        h.update(block)                       # full read of the file
        except OSError:
            return ""
        return h.hexdigest()

    # Tier 1 — group by size. Just a stat() per file; no bytes are read.
    by_size: dict[int, list[str]] = defaultdict(list)
    for dirpath, _, names in os.walk(root):
        for name in names:
            path = os.path.join(dirpath, name)
            if os.path.islink(path):
                continue
            try:
                size = os.path.getsize(path)
            except OSError:
                continue
            if size > 0:
                by_size[size].append(path)

    # Tier 2 — within each size group, group by a partial (first-1KB) hash.
    by_partial: dict[str, list[str]] = defaultdict(list)
    for paths in by_size.values():
        if len(paths) > 1:                                    # a lone file can't be a dup
            for p in paths:
                if (ph := file_hash(p, first_chunk_only=True)):
                    by_partial[ph].append(p)

    # Tier 3 — only now pay for a full-content hash, on the few real candidates.
    by_full: dict[str, list[str]] = defaultdict(list)
    for paths in by_partial.values():
        if len(paths) > 1:
            for p in paths:
                if (fh := file_hash(p, first_chunk_only=False)):
                    by_full[fh].append(p)

    return [paths for paths in by_full.values() if len(paths) > 1]
Why it is fast: N files cost N cheap stat() calls; a partial read happens only for
files that share a size; a full read happens only for files that also share a first
kilobyte. Almost everything is filtered out before Tier 3, so the expensive
full-content pass touches a tiny fraction of the data - the O(N²)-looking problem
collapses to roughly O(N). The design rule generalises: cheapest discriminator first,
narrow to candidates, confirm last.
Exact pass, applied to documents. Text documents are small enough that a single hash is the whole cascade - the trick is what you hash. We normalise first (lowercase, collapse whitespace) so copies that differ only in formatting collide, then key on one SHA-1. Normalisation is the moral equivalent of the size/partial tiers: it forces "same content, different wrapping" into the same bucket before the hash even runs.
def exact_key(text: str) -> str:                 # src/process/dedup.py
    normalized = " ".join(text.lower().split())  # canonicalise whitespace + case
    return hashlib.sha1(normalized.encode("utf-8")).hexdigest()

seen, unique = set(), []
for d in docs:
    k = exact_key(d["text"])
    if k in seen:            # O(1) set membership — the whole exact pass is O(N)
        continue
    seen.add(k); unique.append(d)
Near-duplicate pass (MinHash + LSH). Exact hashing misses documents that are almost identical - e.g. an abstract that also appears verbatim inside its full-text PDF, plus one extra sentence: one byte differs, so the SHA-1s diverge completely. For those we need a similarity measure, and LSH is the same cascade idea applied to fuzzy matching. Each document becomes a set of word 5-grams (shingles); a MinHash (Broder, 1997) signature (128 permutations) estimates the Jaccard similarity of two shingle sets in constant space; and an LSH index buckets signatures so only likely-similar documents are ever compared - the cheap candidate filter that replaces the O(N²) all-pairs comparison, exactly like Tier 1 above. Documents are processed longest-first, so when a near-dup is found we keep the fullest version:
m = MinHash(num_perm=128)
for shingle in word_5grams(text): m.update(shingle.encode())
if lsh.query(m):          # LSH returns only bucket-mates — the candidate set
    near_dups += 1        # a ≥70%-similar doc is already kept → drop this one
else:
    lsh.insert(id, m); kept.append(doc)
The MinHash step is the expensive tier (it reads every surviving document), so
dedup.py computes signatures across a process pool - worker processes inherit the
document list by copy-on-write and return just the signatures - while the stateful LSH
insert/query stays serial but cheap (dict ops on precomputed signatures). On the real
corpus this removed 1,126 exact + 304 near duplicates. Finally the docs are shuffled
with a fixed seed and split into train / val, preserving each doc's metadata.
5. Stage 3 - The BPE tokenizer
Code: src/tokenizer/. We train our own tokenizer rather than reuse GPT-2's -
owning this stage is the point, and a domain vocabulary encodes seismology text more
efficiently.
5.1 Why byte-level BPE
BPE (Byte-Pair Encoding - Sennrich et al., 2015,
adapting a 1994 compression scheme) starts from single characters and greedily merges the most
frequent adjacent pair, over and over, until it reaches the target vocab size. Frequent
sequences (earthquake, sub, duction) become single tokens; rare ones stay in
pieces. Byte-level (Wang et al., 2019) means the
base alphabet is the 256 raw bytes, so any input
is representable - there are no <unk> tokens, ever.
# src/tokenizer/train_bpe.py
tokenizer = Tokenizer(BPE(unk_token=None))
tokenizer.pre_tokenizer = ByteLevel(add_prefix_space=False)
trainer = BpeTrainer(vocab_size=16384, special_tokens=["<|endoftext|>"],
                     initial_alphabet=ByteLevel.alphabet())   # all 256 bytes
tokenizer.train_from_iterator(_iter_texts(train_jsonl), trainer)
We use 16,384 tokens (vs GPT-2's 50,257): smaller vocab → smaller embedding matrix
(a big fraction of a small model's params) and the domain is narrow. Measured
compression on our corpus is ~3.9 chars/token - healthy. The single special token
<|endoftext|> marks document boundaries.
5.2 How BPE works (from scratch)
tokenizers does this for us in fast Rust, but the algorithm is small enough to
write by hand - and understanding it is the point. A BPE tokenizer is just a base
alphabet plus an ordered list of merge rules, learned in two phases.
The whole thing fits in one small class - training learns the merges, encoding replays them, decoding concatenates the bytes back:
from collections import defaultdict

class BPETokenizer:
    def __init__(self, vocab_size: int):
        assert vocab_size >= 256
        self.vocab_size = vocab_size
        self.vocab = {}      # token id -> merged bytes
        self.merges = {}     # (id1, id2) -> new id

    def _get_stats(self, ids: list) -> dict:            # count adjacent id pairs
        count = defaultdict(int)
        for i in range(len(ids) - 1):
            count[(ids[i], ids[i + 1])] += 1
        return count

    def _merge(self, ids: list, pair: tuple, newidx: int) -> list:
        output, i = [], 0
        while i < len(ids):
            if i < len(ids) - 1 and pair == (ids[i], ids[i + 1]):
                output.append(newidx); i += 2
            else:
                output.append(ids[i]); i += 1
        return output

    def train(self, text: str):
        for i in range(256):                            # base vocab = the 256 bytes
            self.vocab[i] = bytes([i])
        ids = list(text.encode("utf-8"))
        for i in range(self.vocab_size - 256):          # each merge adds one token
            stats = self._get_stats(ids)
            if not stats:
                break
            top_pair = max(stats, key=stats.get)        # most frequent adjacent pair...
            newidx = 256 + i
            ids = self._merge(ids, top_pair, newidx)    # ...becomes one new token
            self.merges[top_pair] = newidx
            self.vocab[newidx] = self.vocab[top_pair[0]] + self.vocab[top_pair[1]]

    def encode(self, text: str) -> list:                # text -> BPE token ids
        ids = list(text.encode("utf-8"))
        while len(ids) >= 2:
            stats = self._get_stats(ids)
            # apply the pair whose merge was learned earliest (smallest new id)
            pair = min(stats, key=lambda p: self.merges.get(p, float("inf")))
            if pair not in self.merges:
                break
            ids = self._merge(ids, pair, self.merges[pair])
        return ids

    def decode(self, ids: list) -> str:                 # token ids -> text
        raw = b"".join(self.vocab[i] for i in ids)
        return raw.decode("utf-8", errors="replace")
train starts from the 256 byte values, then repeatedly counts adjacent id pairs,
merges the most frequent pair into a fresh id (256 + i), and records both the merge
rule and its byte expansion - one new token per iteration, so it stops after
vocab_size − 256 merges. encode replays those merges greedily, always applying
the one learned earliest (min by new id = highest priority) until no learned pair
is left. decode concatenates each id's bytes and UTF-8-decodes. Because the base
alphabet is all 256 bytes, nothing is ever out-of-vocabulary. (For a longer
from-scratch treatment of this exact algorithm, see Karpathy's
minbpe and the
"Let's build the GPT Tokenizer" video.)
On our real 16k tokenizer (verified) the same mechanism gives earthquake and
subduction one token each (they're common in the corpus), newest → [new, est],
seismogram → [seism, ogram], and a genuinely rare word splits far more -
antidisestablishmentarianism → [ant, id, is, establish, ment, arian, ism].
This minimal version merges over the raw byte stream; production tokenizers - including
our tokenizers-based train_bpe.py - add a byte-level pre-tokenizer that first
splits text into word-ish chunks so merges never cross word boundaries. But the core
loop is exactly the above, just in fast Rust so it handles the 3 GB corpus.
5.3 Encoding to uint16 shards
encode.py streams the corpus through the tokenizer and writes one flat array of token
ids per split, documents separated by the eot id:
for enc in tok.encode_batch(batch):
    buf.extend(enc.ids); buf.append(eot_id)       # eot between docs
    if len(buf) >= FLUSH_EVERY:
        np.asarray(buf, dtype=np.uint16).tofile(fout)   # 2 bytes/token
uint16 (0-65535) fits our 16k vocab in 2 bytes/token → 822.7M tokens ≈ 1.6 GB, and the
training loader np.memmaps it (no RAM blow-up). Crucially, this file is
context-length-agnostic - the window width is chosen at training time, which is why
switching 1024→4096 needed no re-tokenization.
6. Stage 4 - The model
Code: src/model/gqa_gpt.py. A modern, Llama-style decoder-only Transformer.
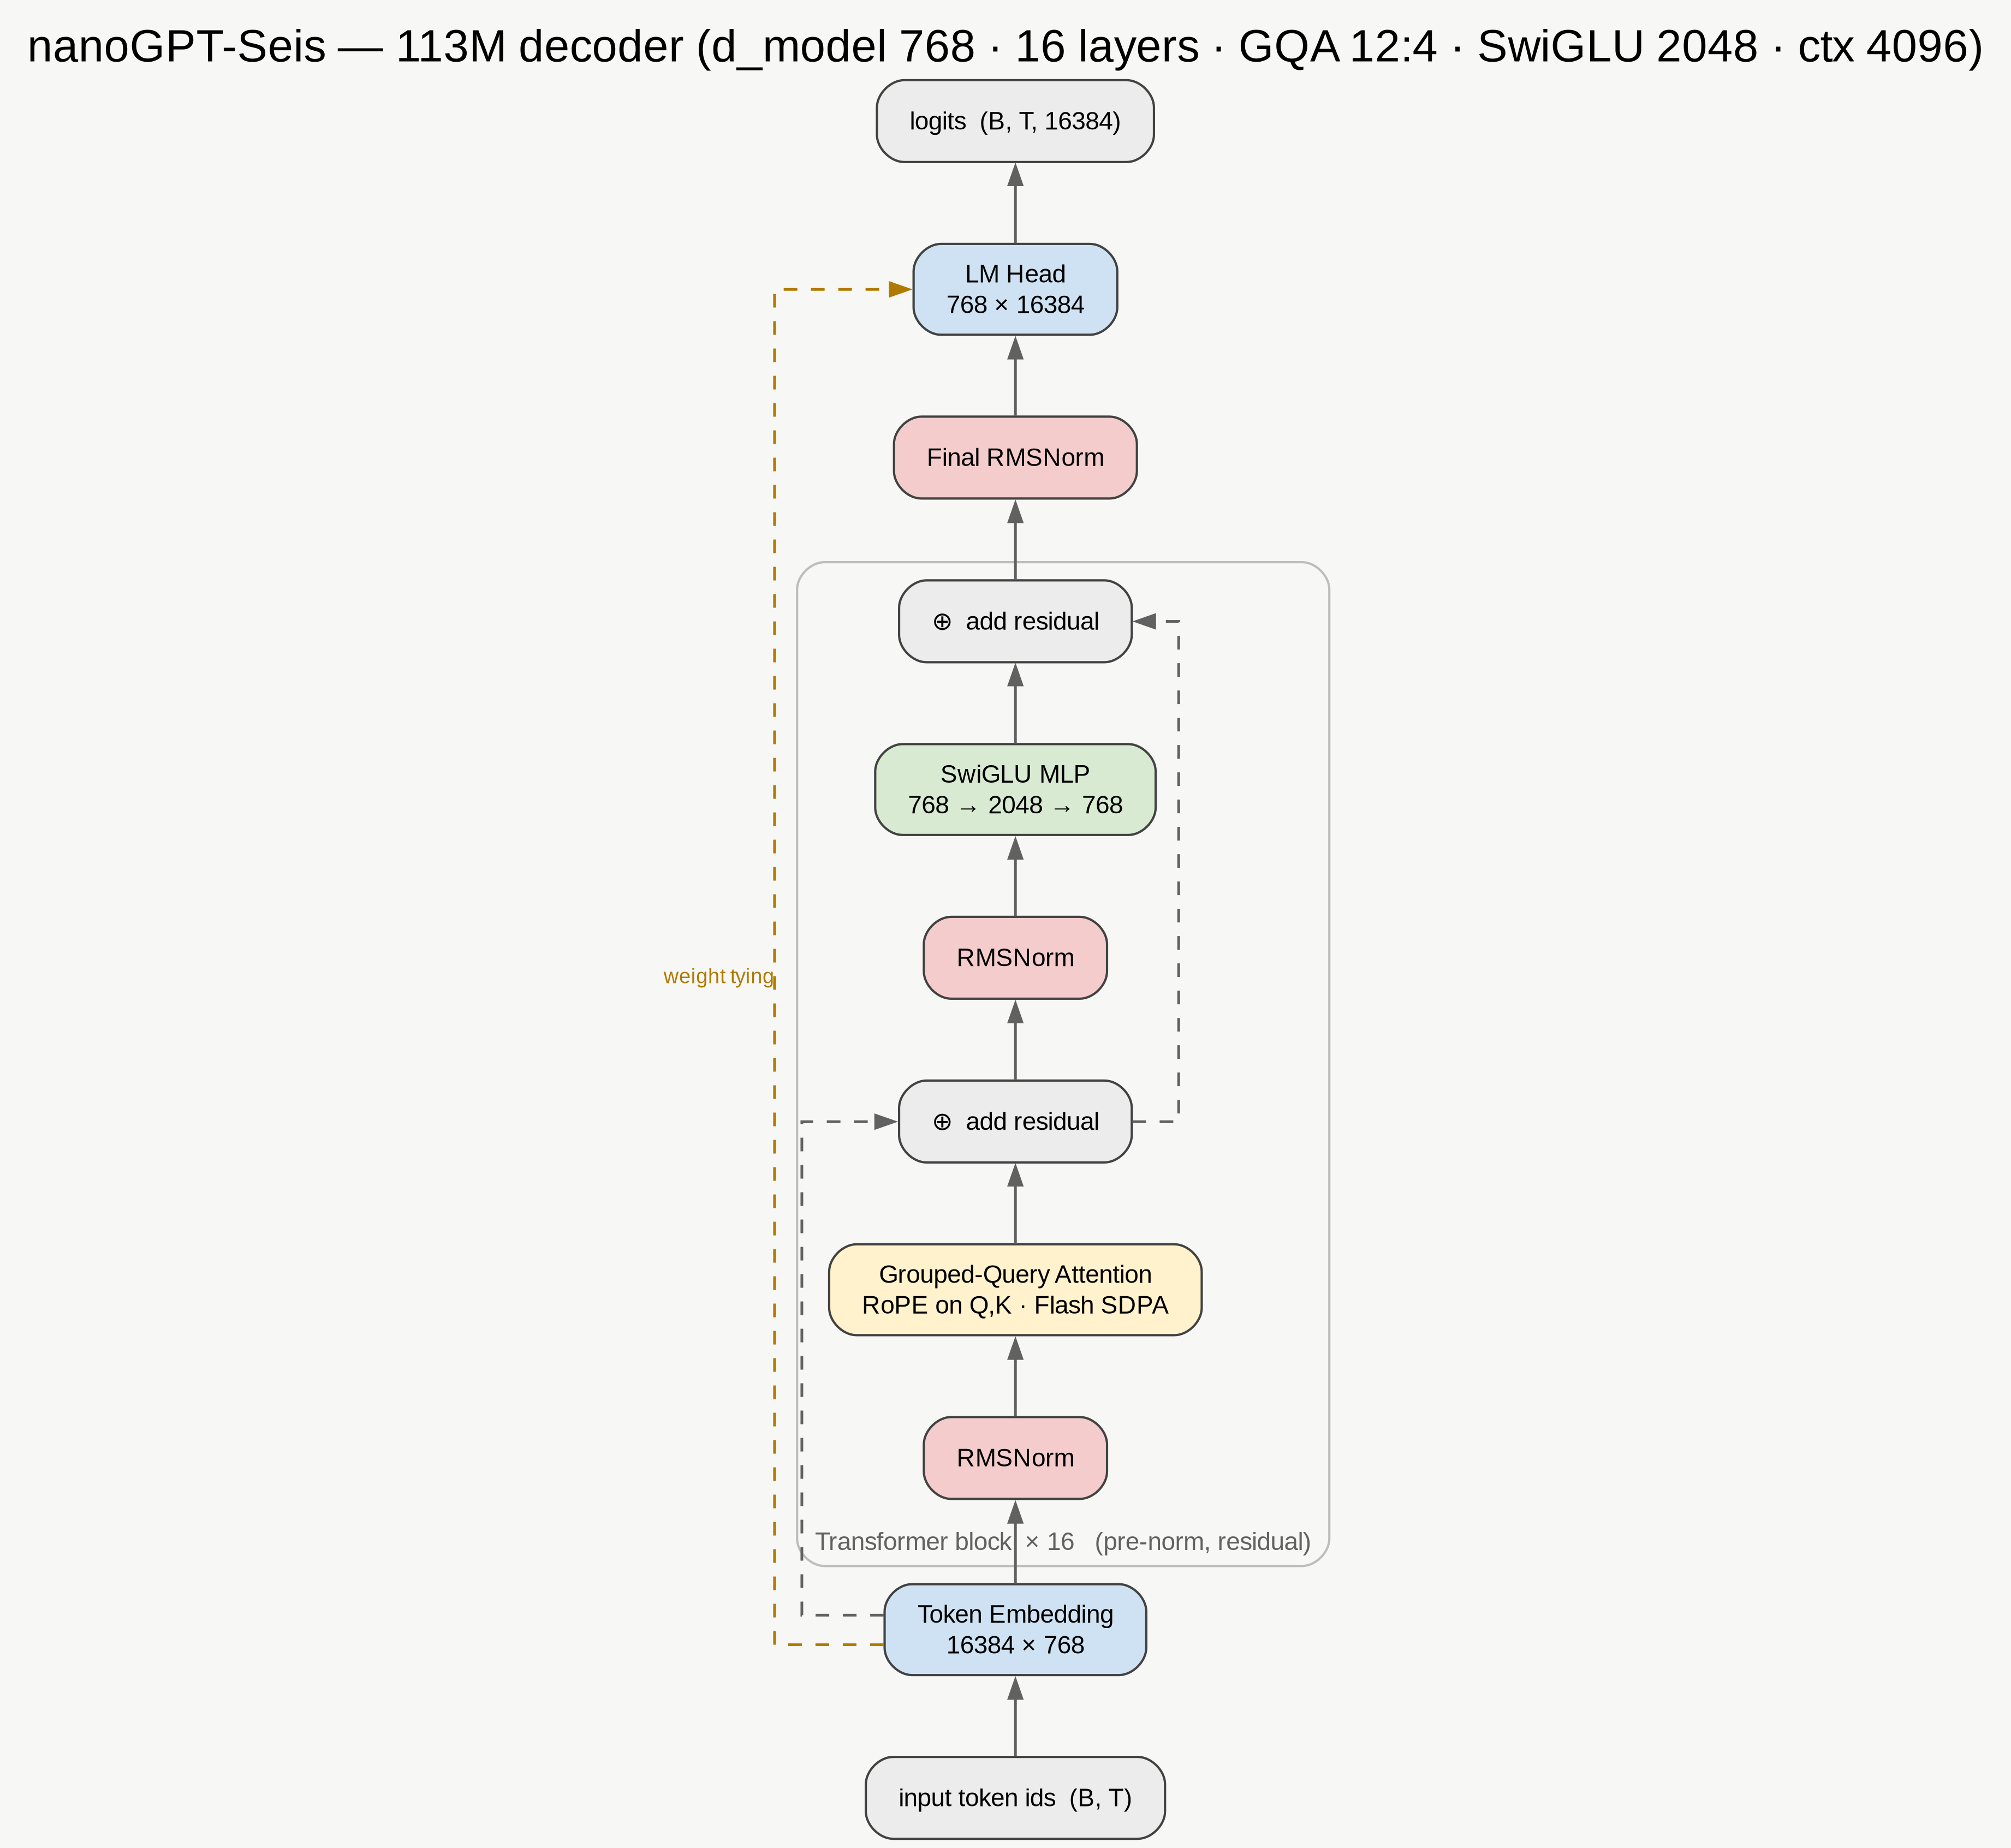
6.1 Why these components
| choice | over the "classic GPT" alternative | why |
|---|---|---|
| RMSNorm (paper) | LayerNorm | fewer ops, no mean-subtraction, same quality - the Llama default |
| RoPE (paper) | learned position embeddings | relative, extrapolates, no position table to learn |
| GQA (paper) | full multi-head attention | 3× smaller KV cache for long-context inference, ~no quality loss |
| SwiGLU (paper) | GELU MLP | gated activation, better quality per parameter |
| weight tying (paper) | separate input/output embeddings | saves 12.6M params on a small model, regularizes |
| no biases | linear layers with bias | biases add little; simpler and slightly faster |
6.2 Attention - queries, keys, and values
Attention is the operation that lets tokens exchange information. Each token's vector is linearly projected into three roles:
- query
q- what this token is looking for; - key
k- what this token offers to others; - value
v- the information it passes on when attended to.
For one head of width d_k, stack these over the sequence into Q, K, V of shape
T × d_k (one row per token). Attention scores every query against every key, turns the
scores into weights, and returns each query's weighted average of the values:
Attention(Q, K, V) = softmax( Q Kᵀ / √d_k + M ) · V
Q Kᵀis theT × Tmatrix of query·key dot products - how strongly token i's query matches token j's key.softmaxover each row makes weights that sum to 1, and multiplying byVaverages the values under those weights.Mis the causal mask:0on and below the diagonal,−∞above, so a token attends only to itself and earlier tokens - it can't peek at the future it is trained to predict.
Why divide by √d_k. q·k is a sum of d_k products; for roughly unit-variance,
independent entries that sum has variance d_k, so raw scores grow like √d_k. Feed
large scores into softmax and it saturates - one weight ≈ 1, the rest ≈ 0 - and its
gradient vanishes, so learning stalls. Dividing by √d_k rescales scores back to ~unit
variance and keeps softmax in a responsive range. (RoPE in §6.3 is applied to q and k
just before this product; GQA in §6.4 shares K/V across heads.)
Why several heads, not one. Instead of one attention over the full d_model width, we
split into h heads of d_k = d_model / h (here 12 × 64), attend independently, and
concatenate. A single head must collapse every kind of relationship - local adjacency,
syntax, long-range coreference - into one weight distribution; separate heads let each
specialise in a different pattern and a different subspace at the same time. Total compute
is unchanged (h · d_k = d_model), and the specialisation is visible in the trained model
(§8.4: some heads are previous-token, some broad, some attention sinks).
Cost. Both Q Kᵀ and the weighting of V are T × T × d_k per head, so attention is
O(T² · d_model) in time and O(T²) in memory for the score matrix - quadratic in
sequence length T. That quadratic is why long context is expensive, and why the next two
subsections matter: GQA shrinks the per-token state that has to be cached, and
FlashAttention removes the O(T²) memory term entirely.
6.3 RoPE - Rotary Position Embeddings
A Transformer is permutation-invariant; it needs to be told token order. RoPE encodes
position by rotating each query/key vector by an angle proportional to its position.
The dot product of a rotated query at position m and key at position n then depends
only on their relative distance m − n - which is exactly what attention should
care about, and it lets the model handle positions it can partly extrapolate to.
The cleanest way to see it: treat each pair of channels as a complex number -
rotating a 2-D vector by angle θ is just multiplying by the unit complex number
e^{iθ}. Precompute e^{i·m·θ_j} for every position m and frequency θ_j, then
encoding position is a single complex multiply:
def precompute_mtheta(dim: int, seqlen: int, base: float = 1e4) -> torch.Tensor:
    theta = 1 / (base ** (torch.arange(0, dim, 2) / dim))    # D/2 frequencies
    m = torch.arange(0, seqlen)                              # S positions
    mtheta = torch.outer(m, theta)                           # S × D/2 angles
    return torch.polar(torch.ones_like(mtheta), mtheta)      # unit complex e^{i·mθ}

def apply_rope(x: torch.Tensor, mtheta: torch.Tensor) -> torch.Tensor:
    # x: (B, S, H, D);  mtheta: (S, D/2)
    x_complex = torch.view_as_complex(x.float().unflatten(-1, (-1, 2)))   # B S H D/2
    mtheta = mtheta[:x.shape[1]].reshape(1, x.shape[1], 1, -1)            # 1 S 1 D/2
    x_rotated = torch.view_as_real(x_complex * mtheta).flatten(3)         # B S H D
    return x_rotated.type_as(x)
Each channel pair (x₂ⱼ, x₂ⱼ₊₁) becomes the complex number x₂ⱼ + i·x₂ⱼ₊₁ and is
rotated by m·θ_j; low-index pairs use large θ_j (rotate fast), high-index pairs
small θ_j (slow). There are no learned parameters, and the rotation preserves norm.
The dot product of a rotated query at m and key at n then depends only on the
relative offset m − n - the whole point.
Our repo implements the algebraically-equivalent real-valued rotate_half form
(same rotation, no complex tensors - friendlier to the compiled / FlashAttention path);
cos/sin are precomputed once and applied to Q and K just before attention:
def _apply_rope(x, cos, sin):          # x: (B, n_head, T, head_dim)
    return x * cos + _rotate_half(x) * sin
(One convention pairs adjacent channels, the other pairs channel j with j + D/2;
both give the same relative-position behavior - just a different weight layout.)
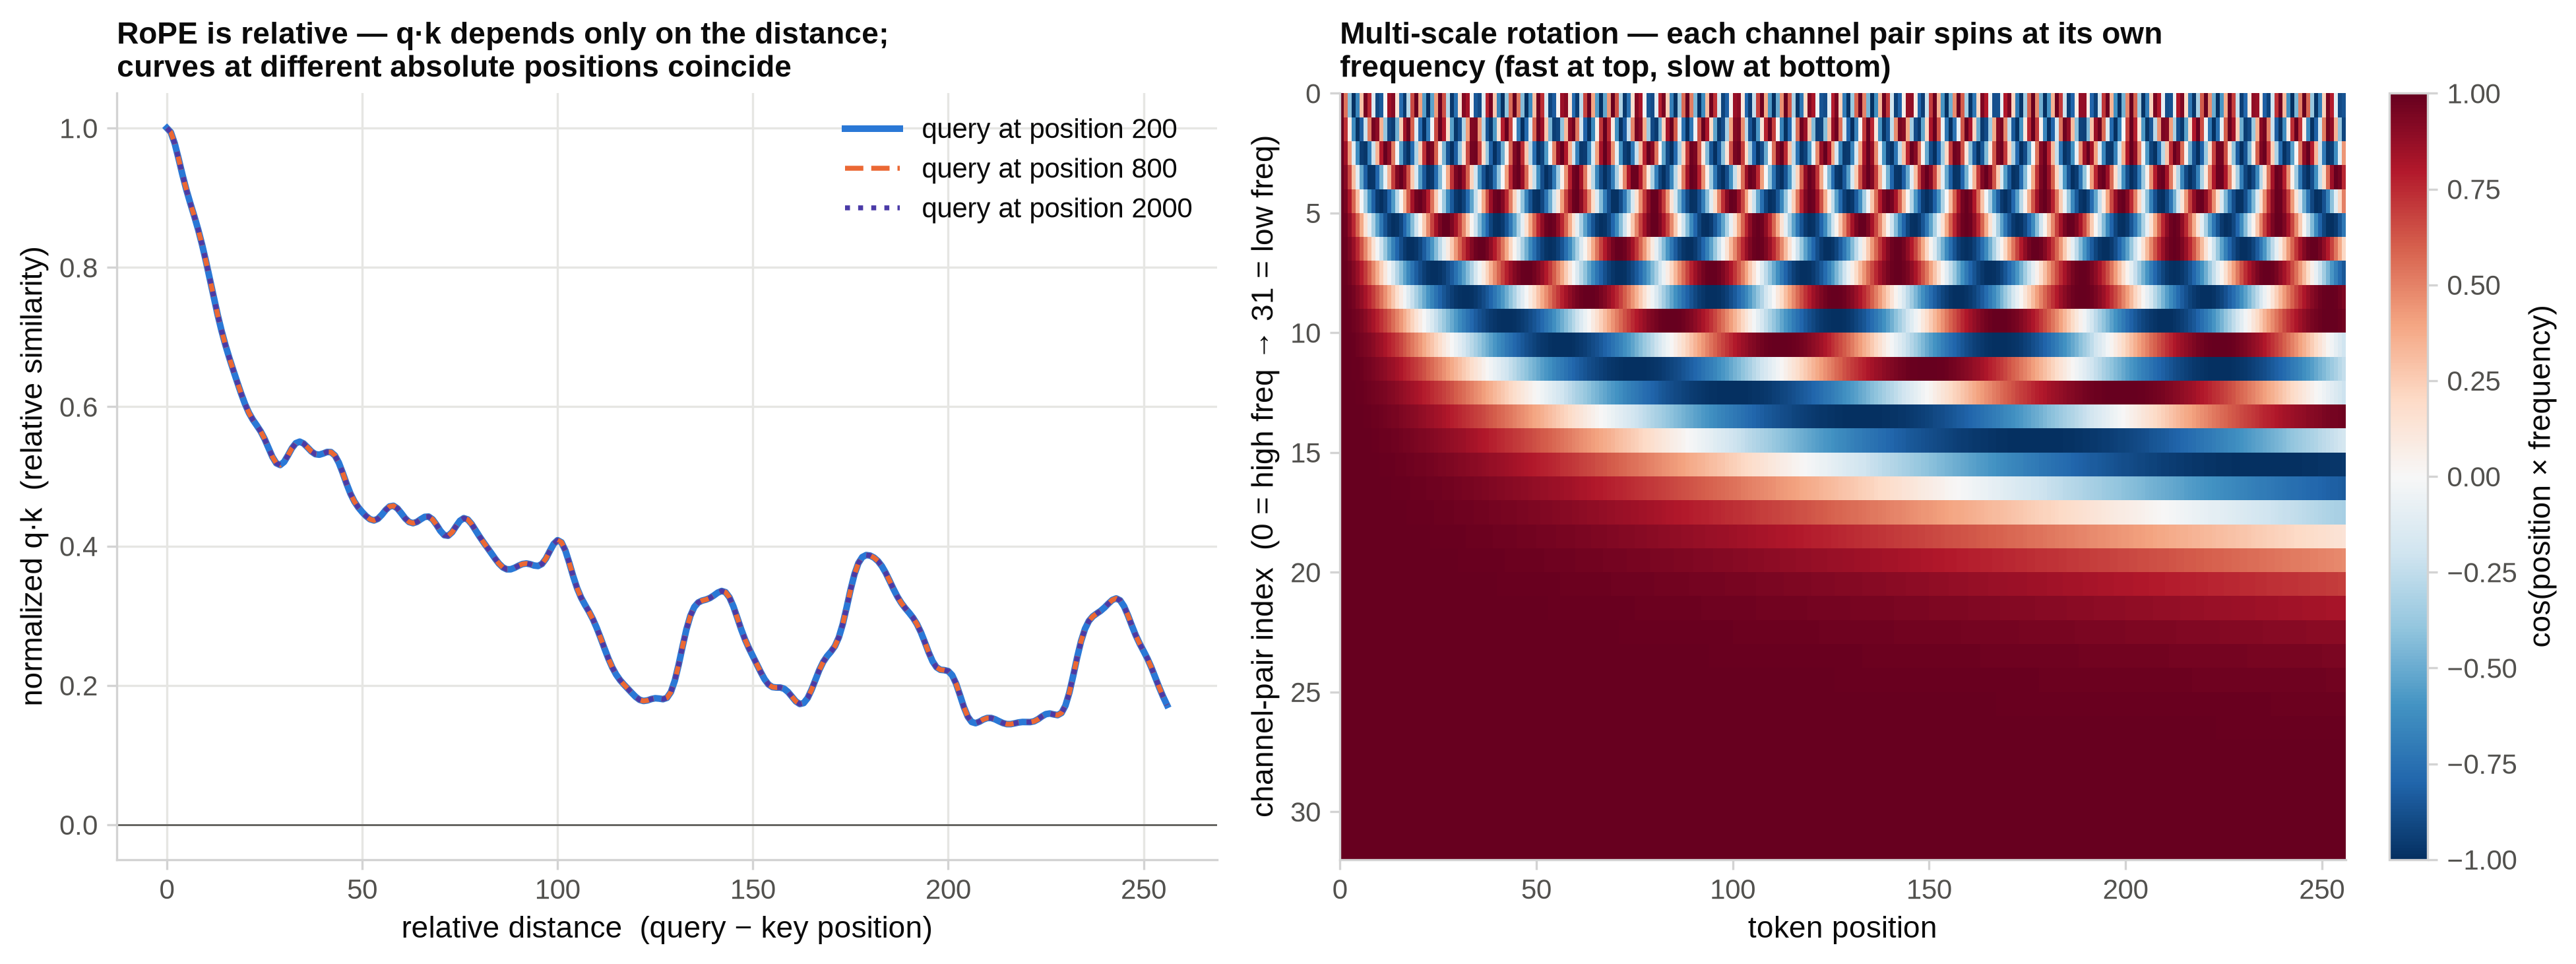
Two consequences (both computed from this model's head_dim=64, θ=10000): the q·k
score depends only on the relative distance - curves for queries at positions
200/800/2000 lie exactly on top of each other (left) - and the channel pairs rotate
at a geometric spread of frequencies, fast to slow (right), so the model can
resolve both nearby and far-apart positions.
6.4 GQA - Grouped-Query Attention
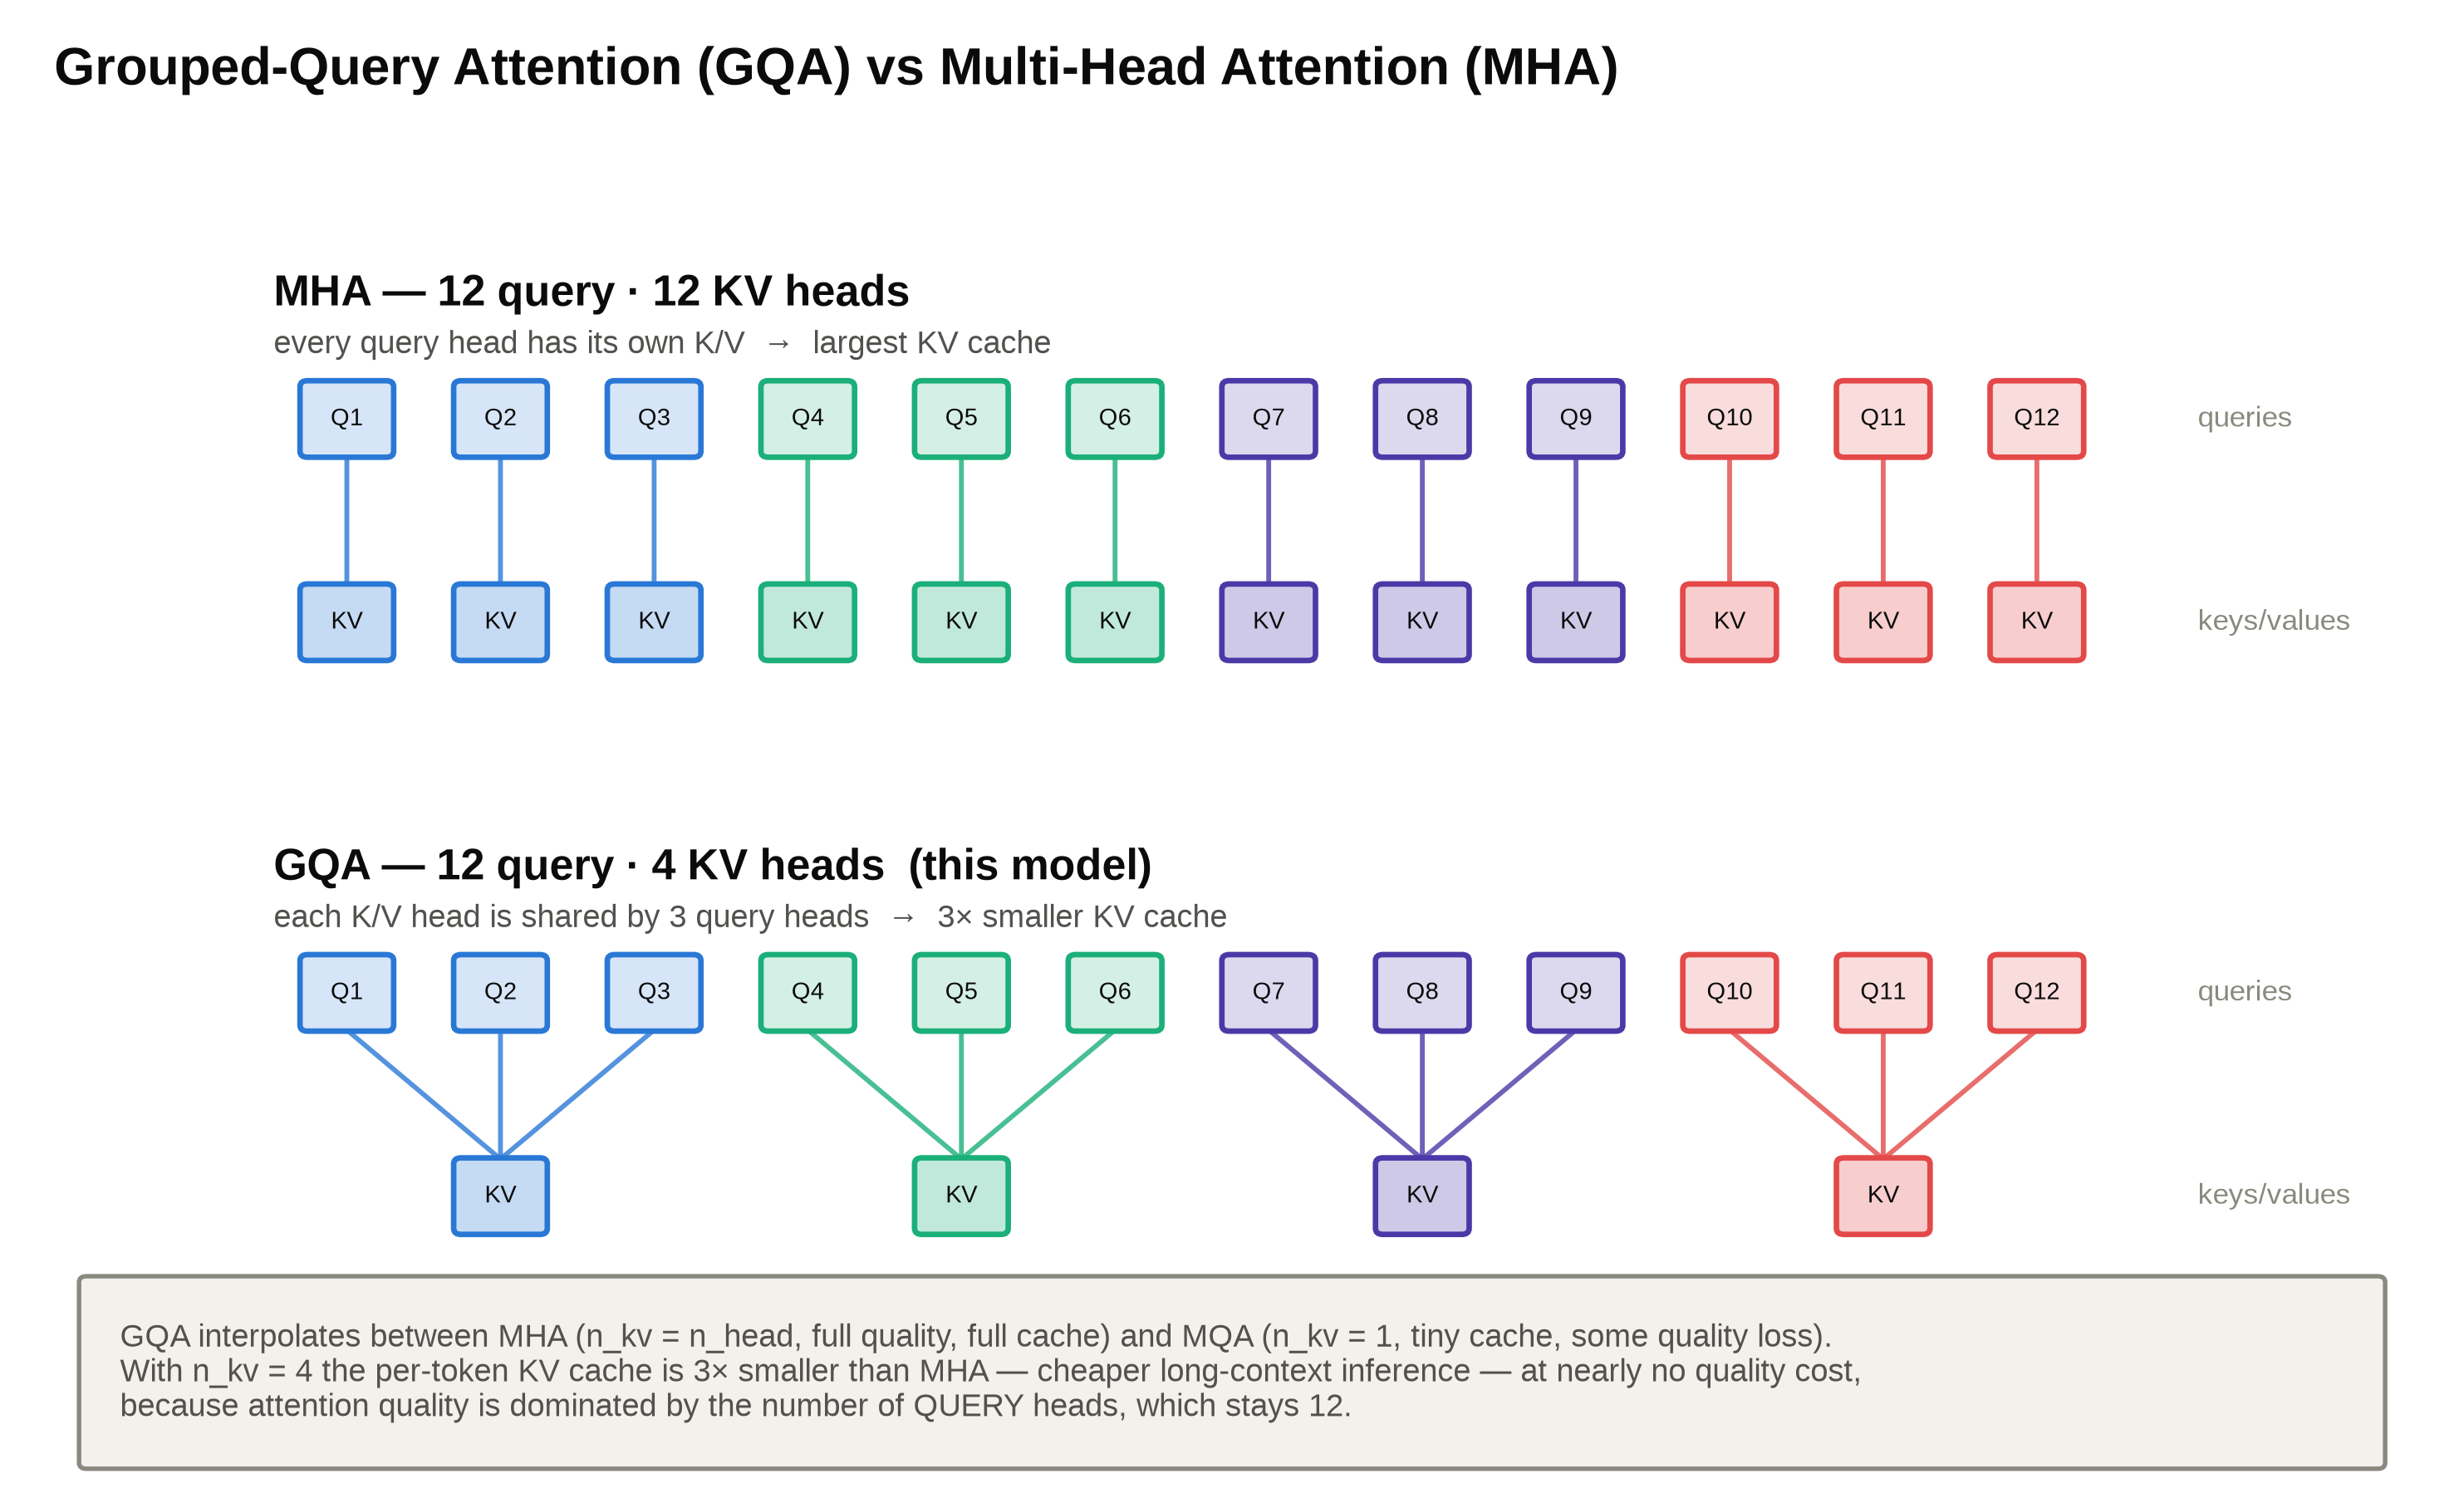
Standard multi-head attention gives every one of the 12 query heads its own key/value head - so at inference the KV cache (the stored keys/values for every past token) holds 12 heads' worth per token. GQA (Ainslie et al., 2023) lets several query heads share a KV head - interpolating between full MHA and multi-query attention (Shazeer, 2019). We use 12 query : 4 KV heads, so the KV cache is 3× smaller - cheaper long-context inference - at nearly no quality cost, because attention quality is dominated by the number of query heads (still 12).
# src/model/gqa_gpt.py — GroupedQueryAttention
# Per-head projection written as an einsum so the contraction is explicit:
#   out[b, h, t, i] = Σ_d  x[b, t, d] · W[h, i, d]
q = torch.einsum("btd,hid->bhti", x, self.wq.weight.view(n_head, hd, d))  # 12 heads
k = torch.einsum("btd,hid->bhti", x, self.wk.weight.view(n_kv,   hd, d))  #  4 heads  ← fewer
v = torch.einsum("btd,hid->bhti", x, self.wv.weight.view(n_kv,   hd, d))  #  4 heads
if n_kv != n_head:                       # broadcast KV heads to match Q for SDPA
    k = k.repeat_interleave(rep, dim=1)  # (the cache itself still stores only n_kv heads)
    v = v.repeat_interleave(rep, dim=1)
y = F.scaled_dot_product_attention(q, k, v, is_causal=True)   # FlashAttention kernel
That one scaled_dot_product_attention call is just the standard attention math -
worth spelling out once. Here is the explicit, non-Flash equivalent (also how
src/figures/attention_map.py recovers the weights, since the fused kernel doesn't
expose them):
import math
# q, k, v: (B, n_head, T, head_dim) — KV already broadcast to n_head above
scores = torch.einsum("bhqd,bhkd->bhqk", q, k) / math.sqrt(head_dim)  # (B,n_head,T,T)
mask = torch.triu(torch.ones(T, T, dtype=torch.bool), diagonal=1)
scores = scores.masked_fill(mask, float("-inf"))                      # causal
attn = torch.softmax(scores, dim=-1)                                  # each row sums to 1
y = torch.einsum("bhqk,bhkd->bhqd", attn, v)                          # (B,n_head,T,head_dim)
The two einsums are the query·key similarity (bhqd,bhkd->bhqk) and the value-weighted
sum (bhqk,bhkd->bhqd) - identical to q @ kᵀ and attn @ v, just with the contracted
axis named.
Why FlashAttention (Dao et al., 2022; FlashAttention-2, 2023). F.scaled_dot_product_attention computes exactly the above
(verified identical to ~1e-7), but attention written this way is memory-bandwidth
bound, not compute bound: the naive version writes the T×T scores and attn
matrices out to the GPU's large-but-slow main memory (HBM) and reads them back, and
shuttling those O(T²) intermediates dominates the wall-clock. FlashAttention never
builds them. It splits Q, K, V into blocks small enough to fit in on-chip SRAM - the
fast per-SM scratchpad (tens of KB, ~10-20× the bandwidth of HBM) - and for each query
block streams over the key/value blocks, accumulating the result tile by tile so the
O(T²) intermediates never leave SRAM. Only the O(T) output is written back to HBM.
The online softmax, in code. The one hard part is the softmax. An ordinary softmax
needs the whole row at once - subtract the row max for numerical stability, exponentiate,
divide by the sum - but a query block only ever sees one key block at a time. The fix is
an online softmax that keeps three running quantities per query row and updates them
block by block: the running max m, the running normaliser l = Σ exp(·), and the
running un-normalised output o. When a new block raises the max, the earlier
accumulators are rescaled by exp(m_old − m_new) to rebase them onto the new max:
import torch, math

class FlashAttention:
    """Tiled attention with an online softmax — the FlashAttention forward pass in
    plain PyTorch. Never materialises the full S×S score matrix, only Br×Bc tiles."""

    def __init__(self, block_q: int, block_kv: int):
        self.Br = block_q        # query-block size (rows of the score matrix)
        self.Bc = block_kv       # key/value-block size (columns)

    def __call__(self, q, k, v):
        # q, k, v: (B, H, S, D)  ->  out: (B, H, S, D)
        B, H, S, D = q.shape
        scale = 1.0 / math.sqrt(D)
        out = torch.zeros_like(q)

        for i in range(0, S, self.Br):                    # outer loop: query blocks
            q_i = q[..., i:i + self.Br, :]                # (B,H,Br,D) — stays in SRAM
            o_i = torch.zeros_like(q_i)                   # running un-normalised output
            l_i = torch.zeros(*q_i.shape[:-1], 1, device=q.device, dtype=q.dtype)  # running Σexp
            m_i = torch.full_like(l_i, float("-inf"))     # running row-max

            for j in range(0, S, self.Bc):                # inner loop: stream K/V blocks
                k_j = k[..., j:j + self.Bc, :]
                v_j = v[..., j:j + self.Bc, :]

                s_ij  = torch.matmul(q_i, k_j.transpose(-2, -1)) * scale   # (B,H,Br,Bc) scores
                m_new = torch.maximum(m_i, s_ij.max(dim=-1, keepdim=True).values)   # new row-max
                p_ij  = torch.exp(s_ij - m_new)           # tile probabilities vs the new max
                corr  = torch.exp(m_i - m_new)            # rescale earlier accumulators (≤ 1)

                l_i = l_i * corr + p_ij.sum(dim=-1, keepdim=True)   # rebase Σexp, add this tile
                o_i = o_i * corr + torch.matmul(p_ij, v_j)          # rebase output, add p·V
                m_i = m_new                               # advance the running max

            out[..., i:i + self.Br, :] = o_i / l_i        # normalise once, write O(T) to HBM

        return out
One inner step reads a Br×Bc score tile s_ij, folds its row-max into the running
max (m_new), forms that tile's probabilities p_ij = exp(s_ij − m_new) against the
new max, and - before adding them in - multiplies the earlier l and o by the
correction corr = exp(m_i − m_new) ≤ 1. That correction is the whole trick: it
retroactively puts the running sum and output on the latest max's scale, so after the
final block o / l is bit-for-bit a full softmax (max abs diff ~1e-15 vs
scaled_dot_product_attention) while nothing larger than one Br×Bc tile is ever held.
The production CUDA kernel is this exact recurrence with the tiles living in
registers/SRAM. For a causal decoder like ours the inner loop simply skips future
key blocks (j > i) and triangular-masks only the diagonal block, so causality roughly
halves the work as well.
Far fewer HBM round-trips → both O(T) memory and a big speedup - which is exactly what makes 4096-token context affordable on a 24 GB card.
6.5 Normalization - RMSNorm, and pre-norm vs post-norm
Every sublayer is wrapped in normalisation. We use RMSNorm: scale each token vector to
unit root-mean-square, then apply a learned per-channel gain g - no mean subtraction, no
bias:
RMSNorm(x) = x / sqrt( mean(x²) + ε ) · g
LayerNorm additionally centres the vector ((x − μ)/σ · γ + β); RMSNorm drops the mean
and the bias, which is cheaper and works as well in practice - the Llama default.
Where the norm sits matters as much as which one. The original Transformer is post-norm - normalise after the residual add; modern decoders (GPT-2, Llama, us) are pre-norm - normalise inside the residual branch, before the sublayer:
post-norm:  x  ←  Norm( x + Sublayer(x) )
pre-norm:   x  ←  x + Sublayer( Norm(x) )
Why pre-norm. In pre-norm the residual path x + … is an unbroken identity highway:
gradients flow from the loss straight back to every layer without passing through a
normaliser, so deep stacks train stably from scratch. Post-norm puts a norm on that main
path, so the gradient is rescaled at every layer on the way down - deep post-norm
Transformers need careful learning-rate warmup and initialisation just to converge. The
price of pre-norm is that the residual stream's variance grows with depth (each block adds
to it without renormalising the sum); we offset that in the weight init (§6.7).
6.6 SwiGLU - the gated feed-forward
Between attention layers, each token is transformed on its own by a feed-forward network.
The classic version is W₂ · GELU(W₁ x): project up, apply a pointwise activation, project
down. We use SwiGLU, a gated variant with three matrices:
SwiGLU(x) = W₂ ( SiLU(W₁ x) ⊙ (W₃ x) ), SiLU(z) = z · sigmoid(z)
The up-projection W₃ x is multiplied element-wise (⊙) by a data-dependent gate
SiLU(W₁ x): the network learns, per token and per hidden unit, how much signal to let
through. That multiplicative interaction is more expressive than a single fixed activation
and gives better quality per parameter. Because SwiGLU uses three matrices instead of two,
its hidden width is set to ≈ 8/3 · d_model (rounded to a multiple of 256) rather than
4 · d_model, so the parameter count matches a plain MLP - the ⌈8/3·d⌉ rule. Code:
src/model/gqa_gpt.py's SwiGLU (w1 gate, w3 up, w2 down).
6.7 Weight initialization
Initialisation decides whether the first steps are stable. Three rules:
- Linear and embedding weights:
Normal(0, 0.02). A small standard deviation keeps activations and the initial logits in a sane range. At init the model should be maximally unsure, so the loss should beln(vocab_size) = ln(16384) ≈ 9.70; ours starts at 9.85 ✓ - the quickest check that the model and loss are wired correctly. - Residual output projections scaled by
1/√(2·n_layer)(the GPT-2 trick): the attentionWoand the SwiGLUW₂- the two matrices that write back into the residual stream - are initialised withstd = 0.02/√(2·n_layer). In a pre-norm net (§6.5) each of the2·n_layersublayers adds to the residual stream without renormalising the sum, so without this its variance would grow with depth and the logits would blow up; shrinking those writes keeps the residual variance roughly constant from the first block to the last. - No biases anywhere, and RMSNorm gains start at
1.
(For the scaling experiments, muP rescales both this init and the learning rate by width; §10.2.)
6.8 Hyperparameters and why
configs/gpt120m_ctx4k.yaml:
n_layer: 16      d_model: 768      n_head: 12   n_kv_head: 4     # GQA 12:4
block_size: 4096   vocab_size: 16384   ffn hidden: 2048 (SwiGLU)
- d_model 768 / 12 heads / 16 layers ≈ GPT-2-small shape → ~113M params, a size that trains comfortably on one node and is big enough to be fluent.
- head_dim 64 (768/12) - the sweet spot FlashAttention is tuned for.
- SwiGLU hidden 2048 - the Llama
⌈8/3·d⌉rule rounded to a multiple of 256.
7. Stage 5 - Training
Code: src/train.py. Data-parallel across both A30s.
7.1 DDP - how two GPUs train one model
We launch with torchrun --nproc_per_node=2, which starts one process per GPU.
DistributedDataParallel keeps a replica of the model on each GPU; each processes a
different micro-batch, and gradients are all-reduced (averaged) across GPUs before
the optimizer step - so both replicas stay identical. The effective batch is the sum
across GPUs.
init_process_group(backend="nccl")
model = torch.compile(model)                       # fuse kernels
model = DDP(model, device_ids=[local_rank])        # replicate + all-reduce grads
Gradient accumulation multiplies the batch further: we run several micro-batches before stepping, and - importantly - only sync gradients on the last one, so the in-between backward passes don't pay the all-reduce cost:
for micro in range(gra

[Content truncated due to size limits]
FAQ
Common questions
Discussion
Questions & comments · 0
Sign In Sign in to leave a comment.