
Run trillion-parameter AI models on CPU with minimal RAM
Portable C99 CPU engine that runs the 2.78-trillion-parameter Kimi K3 in 8.24 GB of RAM by streaming the trunk and experts from disk.
1.1.0Add to Favorites
Why it matters
Enable developers and researchers to run the 2.78-trillion-parameter Kimi K3 language model on ordinary hardware without GPUs, using a portable C99 inference engine that streams the model from disk and operates in as little as 8 GB of RAM while producing identical outputs across all memory configurations.
Outcomes
What it gets done
Execute inference on 2.78T parameter models using only CPU and 8 GB RAM
Stream 1.56 TB model checkpoints from disk with automatic memory-speed tradeoffs
Generate text tokens with byte-identical outputs across 8 GB to 224 GB configurations
Deploy portable C99 inference engine with no dependencies on BLAS, frameworks, or GPUs
Source
Get it from source
Spark does not host a copy of it.
Open sourceReports
Agent outcome reports
No reports yet
Overview
kimi-k3-in-c is an inference engine for Kimi K3 written in portable C99, with no BLAS, framework or GPU. It keeps the dense trunk in memory to a depth you choose, streams the rest from disk and multiplies the routed experts straight from their packed 4-bit form. The 2.78T-parameter model runs at 8.24 GB of measured peak RSS, with byte-identical output from 8 GB up to 224 GB of memory. Use it to run Kimi K3 on a CPU, or to check the engine against a PyTorch reference with make test. It is slow on small machines, 26.5 seconds per token at 8 GB, and needs about 1.7 TB of free storage.
What it does
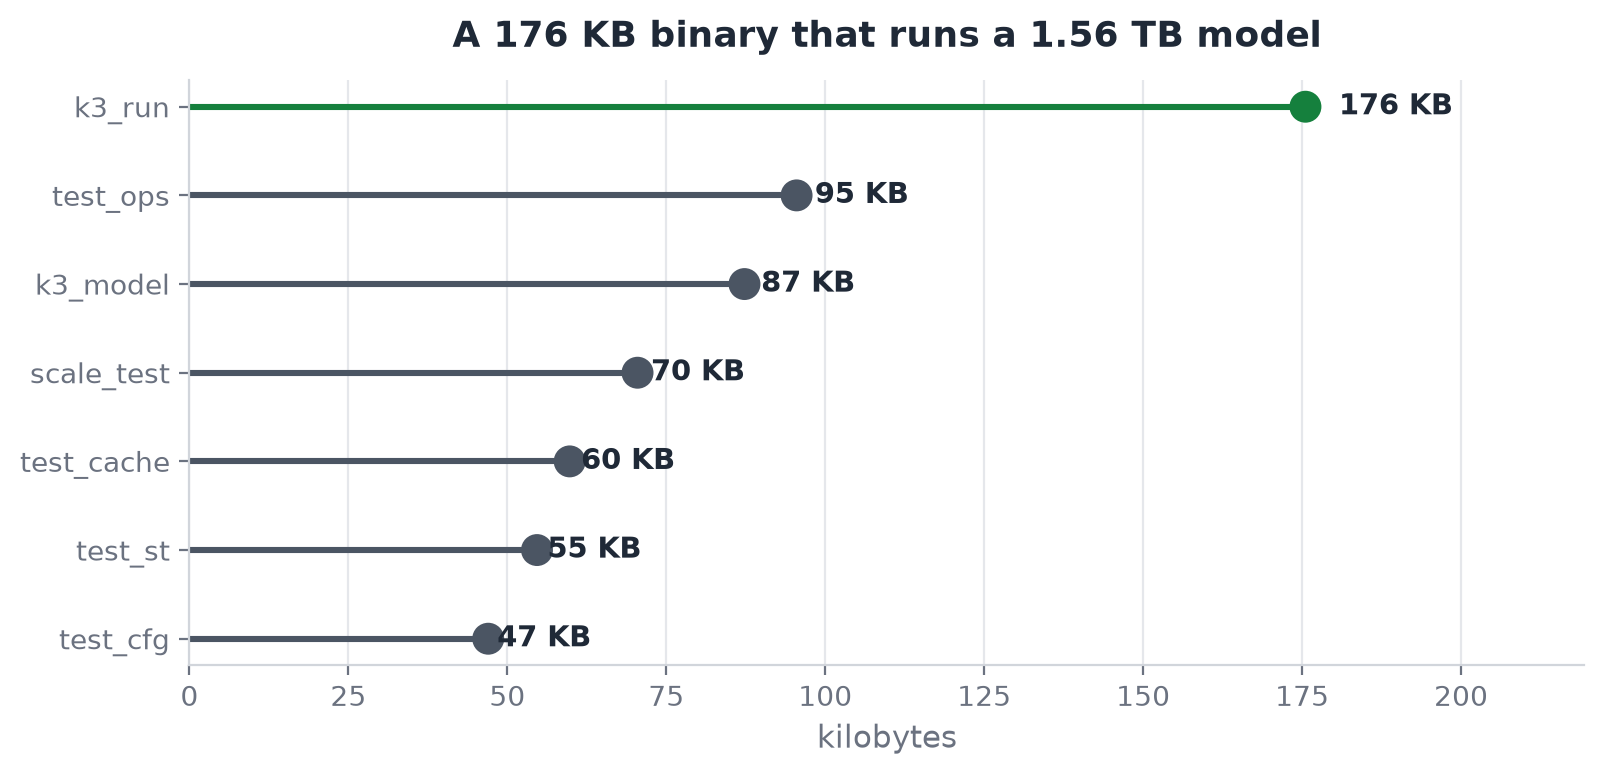
kimi-k3-in-c runs inference for Kimi K3, a model with 2.78 trillion parameters and a 1.56 TB checkpoint, on one CPU. It is portable C99 with no BLAS, no framework and no GPU, and the whole engine is a 176 KB binary. Only 16 of the 896 routed experts fire per layer for a given token, about 104 billion active parameters out of 2.78 trillion, or 3.7 percent. The 82,432 routed experts take 17,547,264 bytes each, 1.447 TB or 93 percent of the checkpoint. They are never resident and are multiplied straight out of their packed 4-bit form. The always-on remainder is 56,743,648,000 parameters, 113.49 GB at bfloat16: 108.81 GB of per-layer dense trunk plus 4.70 GB of embedding table and output head. The dense trunk stays in memory to whatever depth you choose and the rest streams from disk. Measured peak memory on the laptop preset is 8.24 GB, a 675 times reduction from the 5.56 TB bfloat16 model and 189 times from the checkpoint as shipped. Nothing is approximated and no weight is dropped. The ultra preset plans about 3 GB.
The same model produces byte-identical output at every memory budget from 8 GB to 224 GB, and more memory buys speed only. On one 124-core machine with a fast NVMe drive, time per token is 26.5 seconds at 8 GB, 24.2 at 32 GB, 19.8 at 64 GB and 5.6 at 128 GB and above, where the model fits entirely in memory and the disk wait is gone. In the first three cases the model is still read from disk on every step, so a slower drive is slower there. The checkpoint is also chat-capable; use --chat when you want answers and multi-turn history.
The engine reads the model's dimensions from the checkpoint's own config.json and refuses to guess. A missing field or an out-of-range layer index is an error (exit code 2), because a config it cannot fully understand would silently produce a different model. With defaults substituted, an empty attention-layer list would run all 93 layers as Kimi Delta Attention and the 24 global-attention layers would vanish. Kimi K3 has 69 Kimi Delta Attention layers and 24 Gated MLA layers, with 896 experts, top 16 routing and 2 shared experts. Every one of those numbers is read from the file, and the 2 shared experts are counted as resident because they run on every token.
Under the hood the engine reads each safetensors header with a hand-written JSON scan and keeps a hash table of tensor names keyed by FNV-1a, which mixes every byte and so copes with names that share long prefixes. It never reads a shard it does not need, so the 1.56 TB on disk is a catalogue rather than a working set. Reads use O_DIRECT, bypassing the page cache entirely. Only AVX2 and FMA are needed, not AVX-512. It is built with -ffp-contract=off so the scalar, OpenMP and AVX2 paths give bit-identical results. Three invariants guard against a model that runs and emits fluent text but is wrong: A_log is indexed per head, not per channel; MLA uses NoPE, yet the 64 rope dimensions still exist and are cached; and the MoE routing bias steers selection only, while the combining weights come from the unbiased sigmoid scores.
When to use - and when NOT to
Use it to run Kimi K3 on a CPU without a GPU. make test compares a 13-layer model with the same tensor graph as the released one against a PyTorch reference, using bundled fixtures. It needs no checkpoint, no network and no Python, and takes under a minute.
Do not expect interactive speed on a small machine: 26.5 seconds per token at 8 GB, and ultra is a proof-of-life path for 8 GB-class machines, not an interactive-speed preset. Storage is the gate. Plan for about 1.7 TB free, the 1.56 TB checkpoint plus the 109 GB packed trunk, ideally on fast local disk; network volumes run several times slower than local NVMe. The download takes hours, and a partial download does not fail loudly but produces wrong tokens. For generation the whole 1.56 TB is needed; without it only make test and --layers N on partial shard sets work. When throughput is well below the published figures it is almost always storage: python3 tools/devbw.py run on a file on that disk measures the disk with large random O_DIRECT reads at queue depth 1 and 16, which dd does not.
Chat is text-only in version one, with no tools, images, server or context compaction. Prompts may be up to 32768 tokens and generation is capped at 4096. Context costs about 2.37 MB of KV cache per position regardless of budget, the engine computes that up front, and a run that cannot afford it refuses to start, so shorten the request.
Inputs and outputs
Usage is k3 followed by the model directory and then prompt, memory, generation and diagnostics options. The model directory holds the 96 .safetensors shards and config.json (override with --config), and is required for any run except --help, --version and --list-presets. The tokenizer files tiktoken.model and tokenizer_config.json ship with the checkpoint, so --tok points at the model directory. Outside --chat, exactly one of --prompt text, --prompt-file (preferred for non-ASCII, since the shell re-encodes arguments while a file is read verbatim) or --ids token ids is required; none or more than one is a usage error (exit 2). --prompt and --prompt-file require --tok; --ids loads no tokenizer at all.
Generation: --gen N sets the number of tokens (default 8, ceiling 4096). --incremental (off by default) carries the KV cache and recurrent state between tokens instead of re-running the whole prefix, which is O(T^2). Pass it for any generation of length. Both paths are gated on producing identical tokens, so it is a pure speed choice.
Memory: --trunk DIR is the packed trunk directory and is what enables streaming; without it the trunk loads fully resident, around 113.5 GB, whatever preset you ask for. --trunk-gb (default 16) budgets pinned layers plus the streaming ring, and --cache-gb (default 64) budgets the routed-expert LRU cache. A preset sets both numbers as shorthand and a later flag wins, so --preset server --cache-gb 40 gives the server trunk budget with a 40 GB cache. --ultra-low-memory requires --trunk and streams exact embedding rows and lm_head chunks; the ultra preset selects it, and model precision, top-K routing and all 93 layers are unchanged. --list-presets prints trunk and cache budgets in GB:
ultra2.5 and 0.31, about 3 GB planned, slowlaptop3 and 1, 8.2 GB peak RSSdesktop16 and 10, 31.9 GB peakworkstation60 and 30, 95.5 GB peakserver110 and 13, about 128 GB peak, 90 of 93 trunk layers pinned, fastestmax110 and 109, about 224 GB peak, and in these measurements no faster thanserver
Give the trunk memory before the expert cache: at a fixed 128 GB budget that was worth 1.69 times. ./scripts/k3-doctor.sh keys on MemAvailable rather than MemTotal: 192 GB or more picks server, 96 or more workstation, 32 or more desktop, 10 or more laptop.
Chat: --chat uses the official Kimi K3 XTML segments and tokenizer control tokens, with a REPL that accepts /help, /reset and /exit and prints the complete record including think and response blocks. It defaults to --gen 4096 and to greedy decoding. Passing --temperature, --top-p or --seed turns sampling on (temperature 1.0, top-p 0.95 unless given), --greedy forces argmax, and the same transcript with the same --seed is reproducible. Thinking is on by default at maximum effort; --thinking-effort low or high changes it, and --no-think makes the model answer at once with no think block, the largest speed lever on a streamed trunk: in one real run 119 of the 150 tokens of a five-word answer were the think block. With --history FILE the conversation is written as JSONL including the full assistant reasoning; treat that file as sensitive. On restart the transcript is validated, re-rendered and re-prefilled, and no KV, MLA or KDA state is serialized. A supplied --system must exactly match an existing initial system record. Chat fails clearly and keeps the history when the context or KV allocation limit is reached.
Diagnostics: --layers N binds only the first N layers, --out FILE writes JSON results (default k3_run.json), --dump-logits PATH writes float32 logits for the first step, and --dump-cache-trace DIR writes expert_hist.json and expert_trace.bin for tools/sim_cache.py to replay (needs Python and numpy). The run report prints a memory plan, a line per generated token and a summary. Quote PEAK RSS, measured after the run, not the plan. The honest cache figure is TRUE resident hit rate, since the raw hit counter also counts experts the prefetcher just pulled from disk. The first token of any run loads every pinned layer, about 108 GB at the server preset, so it takes far longer than the steady rate; that cost is paid once per run.
Exit codes: 0 success; 1 a tensor failed to bind or a forward pass failed; 2 a usage error or a config that could not be read with confidence; 4 the run finished but at least one routed expert failed to load, so the emitted ids are unsound, which catches silent numerical corruption.
Integrations
Linux on x86-64 is the reference platform. macOS on arm64 (plain make) and Windows on x86-64 (MSYS2 MinGW-w64 GCC, installed with pacman -S mingw-w64-x86_64-gcc and run from the "MSYS2 MinGW x64" shell specifically) also build and pass every gate, and WSL works unmodified. The default build flags include -march=native; make portable targets generic AVX2. It needs AVX2 and FMA (AVX-512 is unnecessary), GCC 9 or newer or Clang 10 or newer, GNU make or CMake, libm and OpenMP. Python 3.9 or newer is used only for the download, pack and analysis tools. Environment variables: HF_TOKEN for the download script (read from the environment, never echoed), OMP_NUM_THREADS for the thread count (default all cores), K3_TOK_FILES for tokenizer tools, naming the directory holding tiktoken.model when it is not in a default location, and K3_MODEL_DIR for tools/budget.py when the checkpoint directory is not passed as an argument.
Setup runs in steps. ./scripts/k3-doctor.sh takes about a minute, measures your disk the way the engine reads it, prints the exact command to run next and exits non-zero if the machine cannot run the model at all. Build with make -j (seconds) or cmake -B build && cmake --build build -j && ctest --test-dir build. ./scripts/download-model.sh ~/k3model needs a Hugging Face token in HF_TOKEN, is resumable, and ends by checking the shard count, the exact byte total and every per-shard size against the published figures; treat a FAIL as a stop. ./scripts/pack-trunk.sh ~/k3model ~/k3trunk takes about four minutes, once, and rewrites the 93 dense layers into one 109 GB file where layer L lives at a known offset and is read in a single call. Then run:
./bin/k3 ~/k3model --trunk ~/k3trunk --preset workstation \
         --tok ~/k3model --prompt "The capital of France is" --gen 8 --incremental
Apache 2.0 licensed.
Source README
kimi-k3-in-c
A 2.78-trillion-parameter model. One CPU. 8 GB of RAM.




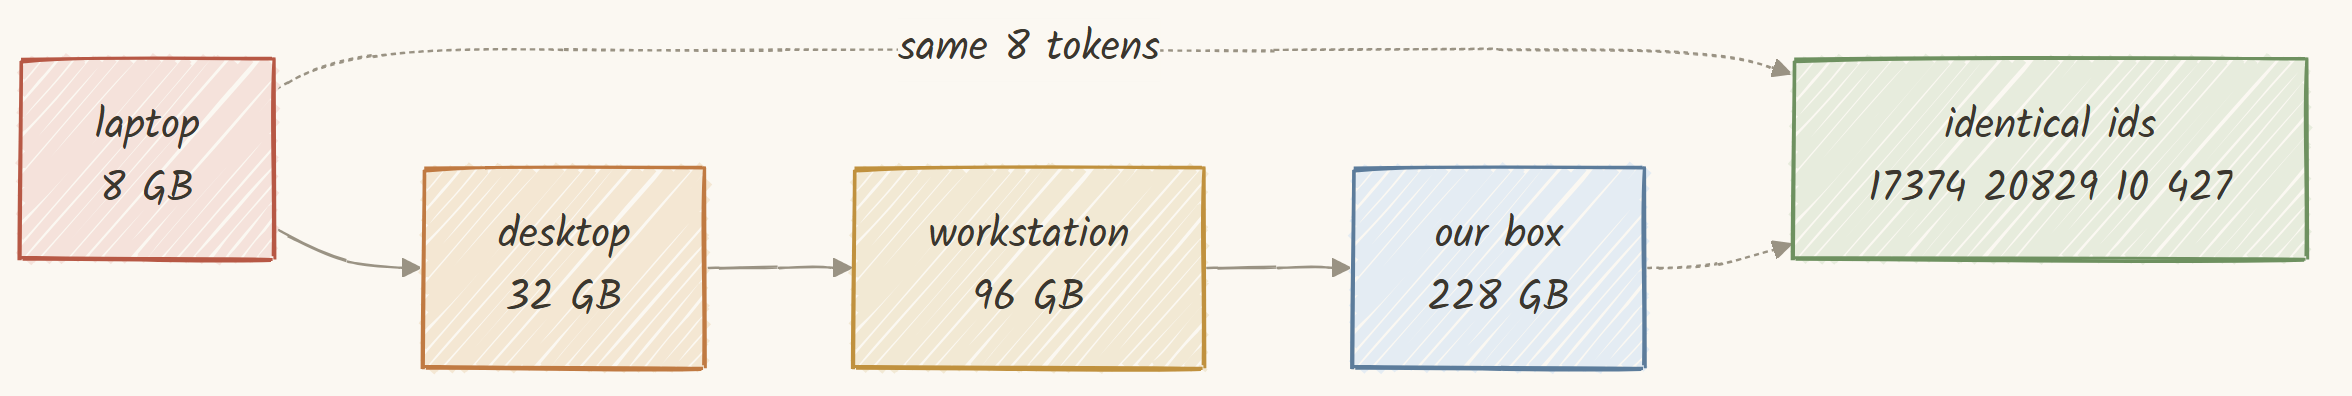
Same short prompt at every size, and the output is byte-identical from the smallest machine to the largest; only the clock changes. One machine, 124 cores, fast NVMe drive: the first three rows still read the model from disk each step, so a slower drive is slower there, while the 128 GB+ row keeps everything in memory and no longer waits on the disk. On that same machine v1.0.0 made the math per token about 8× lighter, a follow-up question in a chat 3.9× faster, and long prompts about half as costly. (A token is roughly a short word-piece; the two runnable demos below are the original captures on a slower drive, so their clock reads a little higher.) Full data in docs/data/.
The macOS, Windows and NEON ports, chat mode, the ultra preset, the faster MXFP4 kernels and a long list of parser fixes came from the people below. Who did what.


$ ./bin/k3 ~/k3model --trunk ~/k3trunk --preset laptop \
          --tok ~/k3model --prompt "The capital of France is" --gen 8 --incremental

--- generated text ---
Paris.",
+            "The Eiffel
----------------------
8 tokens in 261.5 s, 32.69 s/token average
PEAK RSS for the whole run: 8.24 GB
Slow, and answering correctly, in 8.24 GB, from a checkpoint of 1.56 TB. This particular batch command deliberately asks for a raw continuation. The official Kimi K3 checkpoint is also chat-capable; use the XTML REPL below when you want answers and multi-turn history. Give the same batch request more memory and the answer does not change, only the clock:
$ ./bin/k3 ~/k3model --trunk ~/k3trunk --preset server \
           --tok ~/k3model --prompt "def fibonacci(n):" --gen 28 --incremental

--- generated text ---
    if n <= 1:
        return n
    else:
        return fibonacci(n-1) + fibonacci
----------------------
28 tokens in 299.3 s, 10.69 s/token average
PEAK RSS for the whole run: 127.92 GB
Every figure in this document comes from the measurement output in
docs/data/.
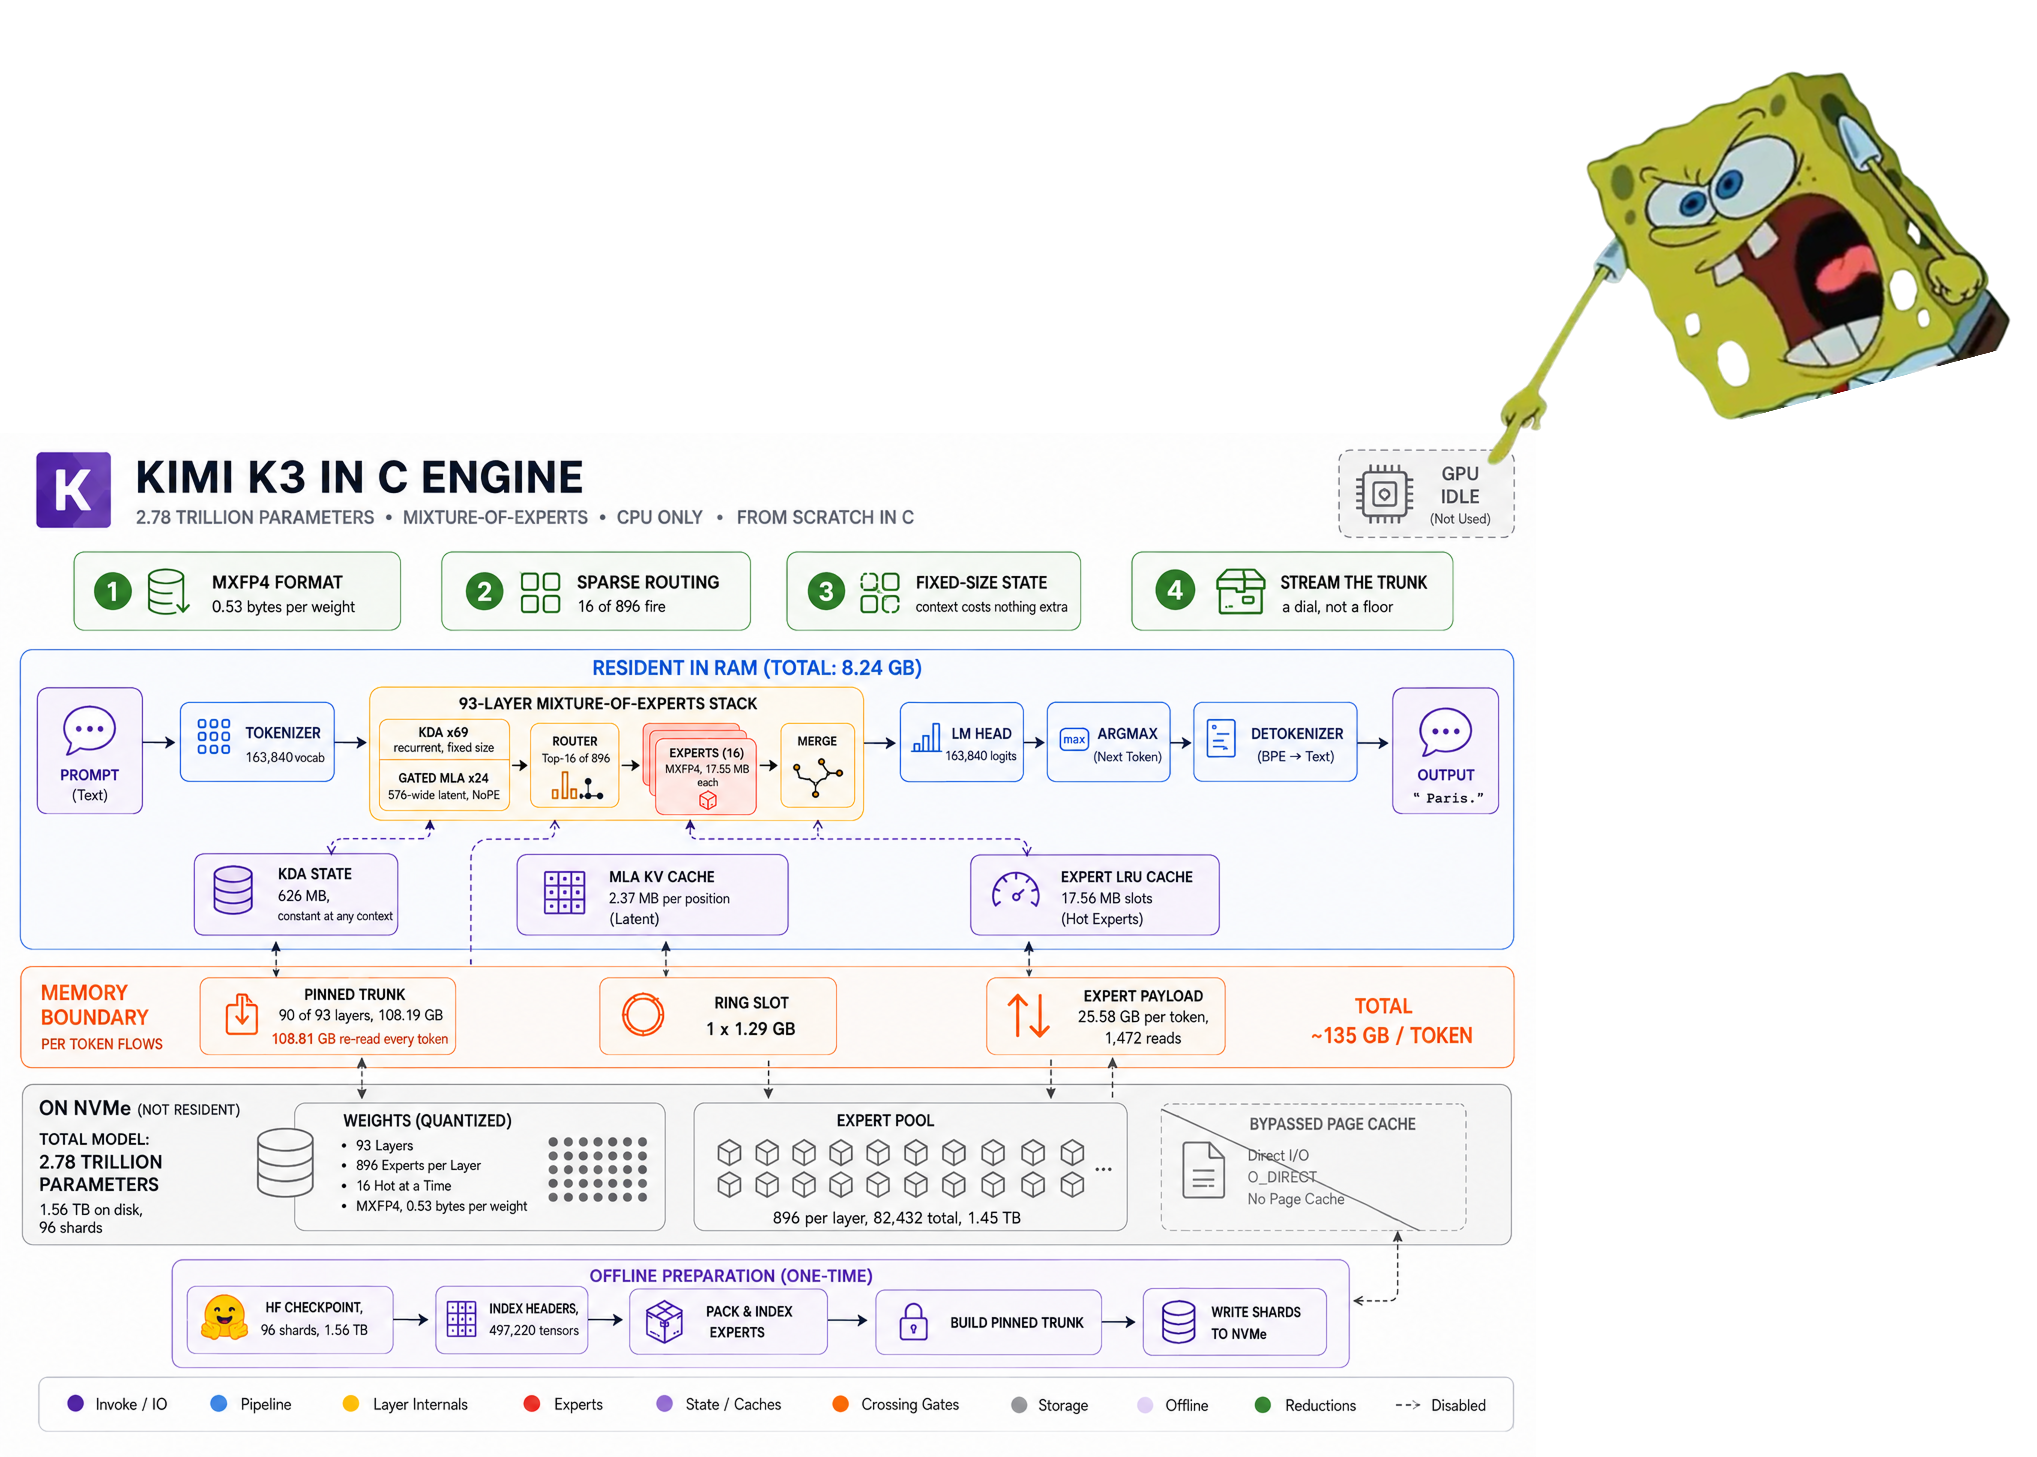
The dense trunk stays in memory to whatever depth you choose and streams the rest; the 1.45 TB of routed experts are never resident, and are multiplied straight out of their packed 4-bit form. The consequence is that the same model runs in 8 GB and in 224 GB and produces byte-identical output at every budget between.
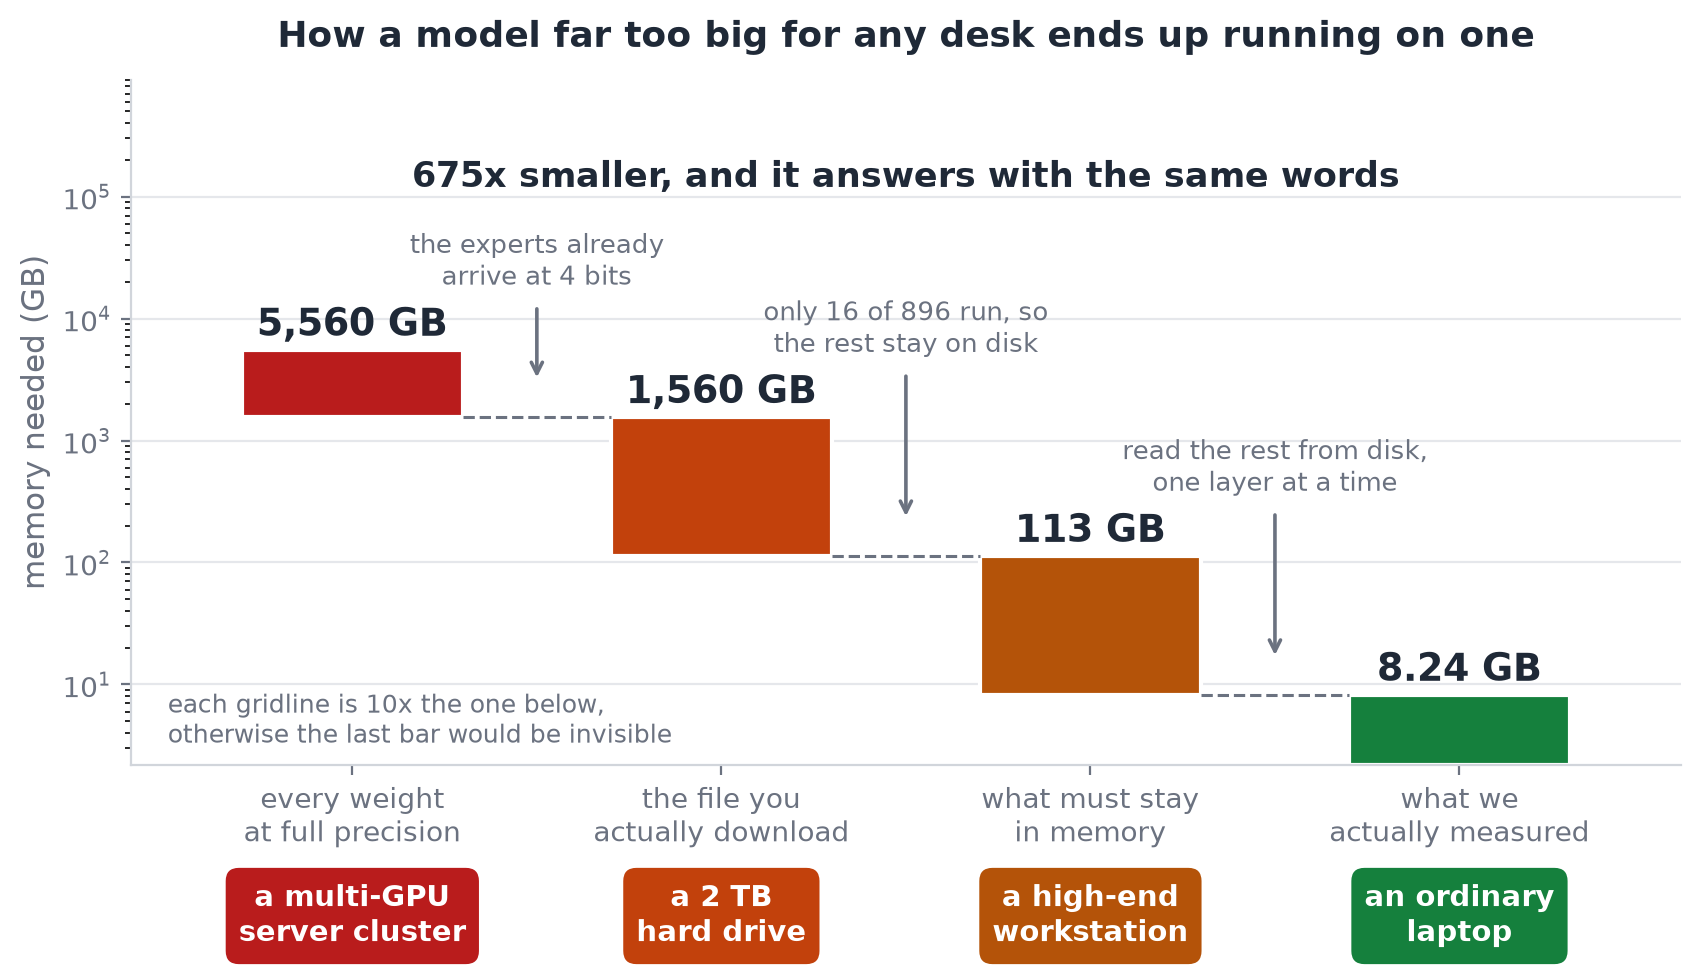
Four decisions about where bytes live take it from a cluster to a laptop, and the answer at the bottom is the same as the answer at the top:
Part II builds every box in both diagrams from scratch, one component at a time.
Contents
- Requirements
- Quick start: clone, build and verify in about a minute, with no model
- Full setup: the whole path to generated text
- Usage
- Choosing a preset
- Reading the run report
- Common questions
- The problem: a model that does not fit
- The four reductions
- The machine, and what it assumes
- The codebase
- Three invariants
- 1. Reading a 1.56 TB checkpoint from its headers
- 2. The config reader that refuses to guess
- 3. The tokenizer, byte for byte
- 4. Reduction one: the experts already ship at half a byte
- 5. Kernels with a floating point contract
- 6. Reduction two: KDA, attention with a memory that never grows
- 7. Reduction three: MLA, one latent instead of ninety-six heads
- 8. Attention residuals: layers that look back
- 9. Picking 16 experts of 896
- 10. Packing the trunk: 93 layers, one read each
- 11. Reduction four: streaming the trunk turns a floor into a dial
- 12. An LRU cache for the experts
- 13. How big should that cache be? Ask the trace
- The gate ladder
- A tiny oracle first
- Proving it on the full checkpoint
- The first tokens
- Sustained generation: text in, text out
- The memory ladder: 8 GB to 224 GB
- The cache that was not participating
- Allocation beats capacity
- Measuring the measurement
- Storage is the whole game
- Why the trunk is not quantised
Part I: Getting started
Requirements
The gate is storage: the checkpoint is 1.56 TB. Everything else is ordinary.
| OS | Linux, x86-64 (reference); macOS/arm64 and Windows/x86-64 also build and pass every gate | uses O_DIRECT, posix_memalign, getrusage -- ported for Windows via MSYS2's MinGW-w64 (see src/io/k3_portable_io.h) |
| CPU | AVX2 + FMA on x86-64, NEON on arm64 | AVX-512 unnecessary. make portable targets generic AVX2 on x86-64 |
| RAM | 8 GB and up | every preset works; more memory is faster, never different |
| Storage | ~1.7 TB free | 1.56 TB checkpoint + 109 GB packed trunk, ideally on fast local disk |
| Toolchain | GCC ≥ 9 or Clang ≥ 10 | GNU make, or CMake |
| Python | 3.9+ | for the download, pack and analysis tools; not for make test |
The tokenizer and config reader are portable C99 and build anywhere. Without a checkpoint you can still do everything in Quick start.
Quick start
Clone, build and run the entire test suite. No checkpoint, no network, no Python. The whole thing takes about a minute.
git clone https://github.com/FareedKhan-dev/kimi-k3-in-c.git
cd kimi-k3-in-c

make -j            # seconds. Seven C files, a compiler and OpenMP
make test          # under a minute
It ends like this, or it failed:
GATE 1  teacher forcing : 32/32 positions match tf_pred
        generated span  : 20/20  <- must be exact
GATE 2  greedy decode   : 20/20 generated tokens match full_ids
GATE 3  incremental    : 20/20 generated tokens match full_ids  <- KV cache + carried KDA state

VERDICT: ENGINE MATCHES THE REFERENCE EXACTLY

ALL WEIGHTLESS TESTS PASSED
That is the whole engine: every kernel, the streaming cache, the safetensors reader, the config reader, the tokenizer, and an end-to-end oracle over a 13-layer model built with the same tensor graph as the released one, checked against a PyTorch reference from fixtures committed to the repository.
One published measurement also replays on the spot, from a trace recorded during a full 93-layer run (this one needs Python 3.9+ and numpy):
python3 tools/sim_cache.py tests/fixtures/expert_trace.bin
100,096 expert requests, reprinting the capacity table in
expert-cache-capacity.txt.
Full setup
Six steps from an empty directory to generated text. Only step 4 is slow.
./scripts/k3-doctor.sh can be run at any point. It checks the toolchain, sizes your RAM
to a preset, measures your storage, and prints the exact command to run next.
Step 0. clone
git clone https://github.com/FareedKhan-dev/kimi-k3-in-c.git
cd kimi-k3-in-c
About 45 MB, most of it the diagrams and the test fixtures.
Step 1. check the machine
./scripts/k3-doctor.sh
Takes about a minute, because it measures your disk the way the engine reads it. It exits non-zero if the machine cannot run the model at all.
Step 2. build
make -j
Seconds. The only dependencies are a C99 compiler, libm and OpenMP. CMake works too:
cmake -B build && cmake --build build -j && ctest --test-dir build
Step 3. verify before downloading anything
make test
This is worth doing before committing to a 1.56 TB download: it proves the engine matches its reference on a model with the same tensor graph, and it needs nothing but the repository.
Step 4. fetch the checkpoint
1.56 TB, so hours rather than minutes. Get a token from huggingface.co/settings/tokens:
export HF_TOKEN=hf_your_token_here          # read from the environment, never echoed
./scripts/download-model.sh ~/k3model       # resumable, re-run to continue
The script finishes by verifying the shard count, the exact byte total, and then every individual per-shard size against the published figures:
verifying…
  shards : 96 (expect 96)
  bytes  : 1560936091448 (expect 1560936091448)
  shards : all 96 match their published sizes individually
  RESULT : byte-exact match
A partial download does not fail loudly; it produces wrong tokens. Treat a FAIL here as
a stop. Checking per shard also turns "re-download 1.56 terabytes" into "re-download this
one 17 gigabyte file", and it catches the one case a total cannot: two shards wrong in
opposite directions by the same amount.
Step 5. pack the trunk
./scripts/pack-trunk.sh ~/k3model ~/k3trunk
About four minutes, once. It rewrites the 93 dense layers into one 109 GB file where layer L lives at a known offset and can be read in a single call. This is what turns the memory requirement into a dial. Put the output on the fastest disk you have.
Step 6. run
./bin/k3 ~/k3model --trunk ~/k3trunk --preset workstation \
         --tok ~/k3model --prompt "The capital of France is" --gen 8 --incremental
The tokenizer ships with the checkpoint, which is why --tok points at the model
directory.
Where everything ends up
kimi-k3-in-c/    ~45 MB   source, docs, images, and bin/k3
~/k3model/      1.56 TB   96 shards · config.json · tiktoken.model · tokenizer_config.json
~/k3trunk/       109 GB   trunk.bin · trunk.json, on the fastest disk you have
The first token of any run loads every pinned layer from disk, about 108 GB at the
server preset, so it takes far longer than the steady rate. That cost is paid once per
run, not once per token.
Usage
Synopsis
k3 <model_dir> [prompt] [memory] [generation] [diagnostics]
<model_dir> is the directory holding the .safetensors shards. It is required for any
run, but --help, --version and --list-presets work without it:
./bin/k3 --help
./bin/k3 --version
./bin/k3 --list-presets
Prompt options
Outside --chat, exactly one of these is required. Passing none, or more than one, is a
usage error (exit 2).
| flag | argument | |
|---|---|---|
--prompt |
TEXT |
tokenize TEXT and run it. Requires --tok. |
--prompt-file |
PATH |
tokenize the file's bytes. Requires --tok. Preferred for anything non-ASCII: the shell re-encodes argv, whereas a file is read verbatim |
--ids |
1,2,3 |
token ids directly. No tokenizer is loaded at all, so this works on a machine with no tokenizer files. The reproducible channel the tests use |
# text in
./bin/k3 ~/k3model --tok ~/k3model --prompt "The capital of France is" ...

# text in, from a file. Use this for CJK, emoji, accents
printf 'La capitale de la France est' > /tmp/p.txt
./bin/k3 ~/k3model --tok ~/k3model --prompt-file /tmp/p.txt ...

# ids in, ids out, no tokenizer needed
./bin/k3 ~/k3model --ids 1008,10484,318,15383,387 ...
Memory options
| flag | argument | default | |
|---|---|---|---|
--preset |
NAME |
none | laptop · desktop · workstation · server · max. Sets both budgets below |
--trunk |
DIR |
off | the packed trunk directory from step 5. This is what enables streaming. Without it the trunk loads fully resident, around 113.5 GB |
--trunk-gb |
X |
16 | budget for pinned layers plus the streaming ring |
--cache-gb |
X |
64 | budget for the routed-expert LRU cache |
--trunk-ring |
N |
2 | streaming ring slots: one layer being computed on, the rest reads in flight. Each extra slot costs one slot of RAM, and the budget still wins if it does not fit |
--threads |
N |
physical cores | OpenMP threads. On Linux the default is the physical core count rather than OpenMP's one thread per logical CPU, which is slower here on SMT parts. OMP_NUM_THREADS, if set, is respected |
--ultra-low-memory |
none | off | stream exact embedding rows and lm_head chunks; full recompute also reuses one recurrent-state slot. Requires --trunk |
The ultra preset selects --ultra-low-memory with a 2.5 GB trunk ring and a
0.31 GB expert cache. It is a proof-of-life path for 8 GB-class machines, not an
interactive-speed preset; model precision, Top-K routing and all 93 layers are unchanged.
--preset and the two -gb flags set the same two numbers, so a preset is just a
shorthand. Order matters if you mix them: a later flag wins, so
--preset server --cache-gb 40 gives you the server trunk budget with a 40 GB cache.
--presetwithout--trunkdoes nothing useful. Every preset assumes the trunk is streamed. Omit--trunkand the engine loads all 113.5 GB resident regardless of the budget you asked for.
Generation options
| flag | argument | default | |
|---|---|---|---|
--gen |
N |
8 | tokens to generate. Ceiling 4096; prompts may be up to 32768 tokens. --gen 0 --incremental --save-state PATH runs only the prefill and saves its exact state, to warm a prefix once and resume it many times |
--stop-id |
N |
off | stop as soon as the model emits id N; repeatable, up to 8. The released checkpoint declares two end ids that disagree (163586 in config.json, 163585 in tokenizer_config.json) and emits both, so pass both |
--incremental |
none | off | carry the KV cache and the recurrent state between tokens instead of re-running the whole prefix |
--tok |
DIR |
none | directory holding tiktoken.model and tokenizer_config.json |
Pass --incremental for any generation of length. Without it every step re-runs the
entire prefix, which is O(T²); with it, step 0 pays for the prompt and every later step
costs the same fixed amount. Both paths are gated on producing identical tokens, so this
is a pure speed choice.
Text chat (official Kimi K3 XTML)
K3 is chat-capable. --chat uses the official XTML segments and tokenizer control tokens;
it does not fall back to ChatML or a handwritten generic prompt. Version one is text-only:
there are no tools, images, server, or context compaction.
./bin/k3 ~/k3model --trunk ~/k3trunk --preset desktop --tok ~/k3model \
  --chat --system "You are a helpful assistant." \
  --history my-session.jsonl --incremental
The REPL accepts ordinary text plus /help, /reset, and /exit. It prints the complete
canonical record, including <think>…</think> and <response>…</response>. When
--history is supplied, it writes a portable, human-readable JSONL file such as:
{"role":"system","content":"You are a helpful assistant."}
{"role":"user","content":"Explain cache locality."}
{"role":"assistant","content":"…","reasoning_content":"…"}
Treat that file as sensitive: it can contain every user message and the complete assistant
reasoning record, which K3 requires to continue a conversation faithfully. On restart the
engine validates, re-renders, and re-prefills the transcript; it deliberately does not
serialize opaque KV, MLA, or KDA state. Within one session under --incremental the
state a turn built is kept, and the next turn prefills only its new tail when the
rendered transcript begins with exactly the ids that state was fed (the REPL prints how
many positions were reused); /reset or any other divergence starts over. A supplied --system must exactly match an existing
initial system record. Literal control-marker text in user messages is encoded as ordinary
text, never as an XTML control token.
Chat defaults to --gen 4096 and, like batch generation, to greedy decoding. Passing any
of --temperature, --top-p or --seed turns sampling on (temperature 1.0, top-p
0.95 unless given); --greedy forces argmax even then. Sampling uses
PCG32; --seed N deterministically derives one stream per assistant turn, so replaying the
same transcript with the same seed is reproducible. The 32K prompt / 4096 generation limits
are existing engine limits, not new chat limits; chat fails clearly and retains the history
when either context or safe KV allocation is reached.
Thinking is on by default with thinking_effort=max, which is exactly what the checkpoint's
own tokenizer does when apply_chat_template is given nothing; --thinking-effort low or
high changes only that setting. --no-think is the encoder's thinking=False: no
thinking-effort system message, prior assistant turns rendered without a think channel, and
a generation prompt that opens the response channel directly, so the model answers at once
and the REPL prints no <think> block. On a streamed trunk this is the largest speed lever
there is: in a real-checkpoint run, 119 of the 150 tokens of a five-word answer were the
think block. Reasoning already stored in the transcript is left in place and is rendered
again the next time the conversation runs with thinking on. Both flags are byte- and
id-exact against the official tokenizer in tests/unit/test_chat.c.
Chat uses the same CPU-only streamed trunk and routed-expert cache as batch mode. --preset,
--trunk-gb, and --cache-gb keep exactly their existing meanings: no experts are preloaded
and the trunk remains disk-streamed unless those existing memory flags ask otherwise.
Diagnostic options
| flag | argument | |
|---|---|---|
--config |
PATH |
model config; defaults to <model_dir>/config.json |
--layers |
N |
bind only the first N layers, for partial shard sets |
--out |
FILE |
JSON results (default k3_run.json) |
--dump-logits |
PATH |
float32 logits for the first step, for elementwise comparison |
--dump-cache-trace |
DIR |
writes expert_hist.json and expert_trace.bin, which tools/sim_cache.py replays |
Exit codes
Scripts can rely on these.
0 |
success |
1 |
a tensor failed to bind, or a forward pass failed |
2 |
usage error, or a config that could not be read with confidence; the engine declines to guess |
3 |
the run finished but the --out file could not be written, so the results a harness reads are missing |
4 |
the run finished, but at least one routed expert failed to load, so the emitted ids are unsound. Distinct from 1 because the process otherwise succeeded, and it is the code that catches silent numerical corruption |
5 |
stopped early by Ctrl-C. The step in flight finished, and the state file, --out and the reports were all written, but the token list is shorter than asked for. A second Ctrl-C kills the process instead |
Environment variables
| variable | used by | |
|---|---|---|
HF_TOKEN |
download-model.sh |
HuggingFace token, read from the environment and never echoed |
OMP_NUM_THREADS |
the engine | thread count. When neither this nor --threads is given, Linux defaults to the physical core count |
K3_TOK_FILES |
tokenizer tools and CI | directory holding tiktoken.model, when it is not in a default location |
K3_MODEL_DIR |
tools/budget.py |
checkpoint directory, when not given as an argument |
Worked examples
# Full-model, one-token proof of life on an 8 GB-class ARM64 machine.
./bin/k3 ~/k3model --trunk ~/k3trunk --preset ultra \
         --tok ~/k3model --prompt "The capital of France is" --gen 1

# Smallest possible run, the 8 GB floor.
./bin/k3 ~/k3model --trunk ~/k3trunk --preset laptop \
         --tok ~/k3model --prompt "Hello! My name is" --gen 16 --incremental

# Fastest per gigabyte. Pins 90 of 93 trunk layers.
./bin/k3 ~/k3model --trunk ~/k3trunk --preset server \
         --tok ~/k3model --prompt "def fibonacci(n):" --gen 28 --incremental

# Hand-tuned split instead of a preset: everything to the trunk.
./bin/k3 ~/k3model --trunk ~/k3trunk --trunk-gb 110 --cache-gb 13 \
         --tok ~/k3model --prompt-file prompt.txt --gen 32 --incremental

# Reproducible: ids in, ids out, no tokenizer, JSON results.
./bin/k3 ~/k3model --trunk ~/k3trunk --preset desktop \
         --ids 1008,10484,318,15383,387 --gen 8 --incremental --out run.json

# Capture a cache trace, then replay it offline at any capacity.
./bin/k3 ~/k3model --trunk ~/k3trunk --preset workstation \
         --ids 1008,10484,318,15383,387 --gen 8 --incremental \
         --dump-cache-trace /tmp/trace
python3 tools/sim_cache.py /tmp/trace/expert_trace.bin

# Elementwise logit comparison against the PyTorch reference.
./bin/k3 ~/k3model --trunk ~/k3trunk --preset server \
         --ids 3,4,5,6,7 --gen 1 --dump-logits /tmp/c_logits.bin
python3 tools/cmp_logits.py /tmp/c_logits.bin ref_logits.json

# Partial shard set: bind only the first 8 layers.
./bin/k3 ~/k3model --trunk ~/k3trunk --layers 8 \
         --ids 1,2,3 --gen 1

# Under a hard memory ceiling, which is how the ladder was measured.
systemd-run --scope --user -q -p MemoryMax=8G -p MemorySwapMax=0 \
  ./bin/k3 ~/k3model --trunk ~/k3trunk --trunk-gb 2.5 --cache-gb 0.5 \
           --ids 1008,10484,318,15383,387 --gen 8 --incremental
Choosing a preset
$ ./bin/k3 --list-presets
presets (trunk / expert-cache, in GB):
  ultra          2.50 / 0.31    ~3 GB planned: streamed model tables, one state slot. Slow.
  laptop         3.00 / 1.00    8.2 GB peak RSS. The ordinary-path floor.
  desktop       16.00 / 10.00   31.9 GB peak RSS.
  workstation   60.00 / 30.00   95.5 GB peak RSS; the expert cache starts to matter here.
  server       110.00 / 13.00   ~128 GB peak RSS; 90 of 93 trunk layers pinned. Fastest.
  max          110.00 / 109.00  ~224 GB peak RSS; trunk pinned and a large expert cache.

All presets stream the trunk, so they need --trunk <packed_dir>.
Run scripts/k3-doctor.sh to see which one this machine fits.
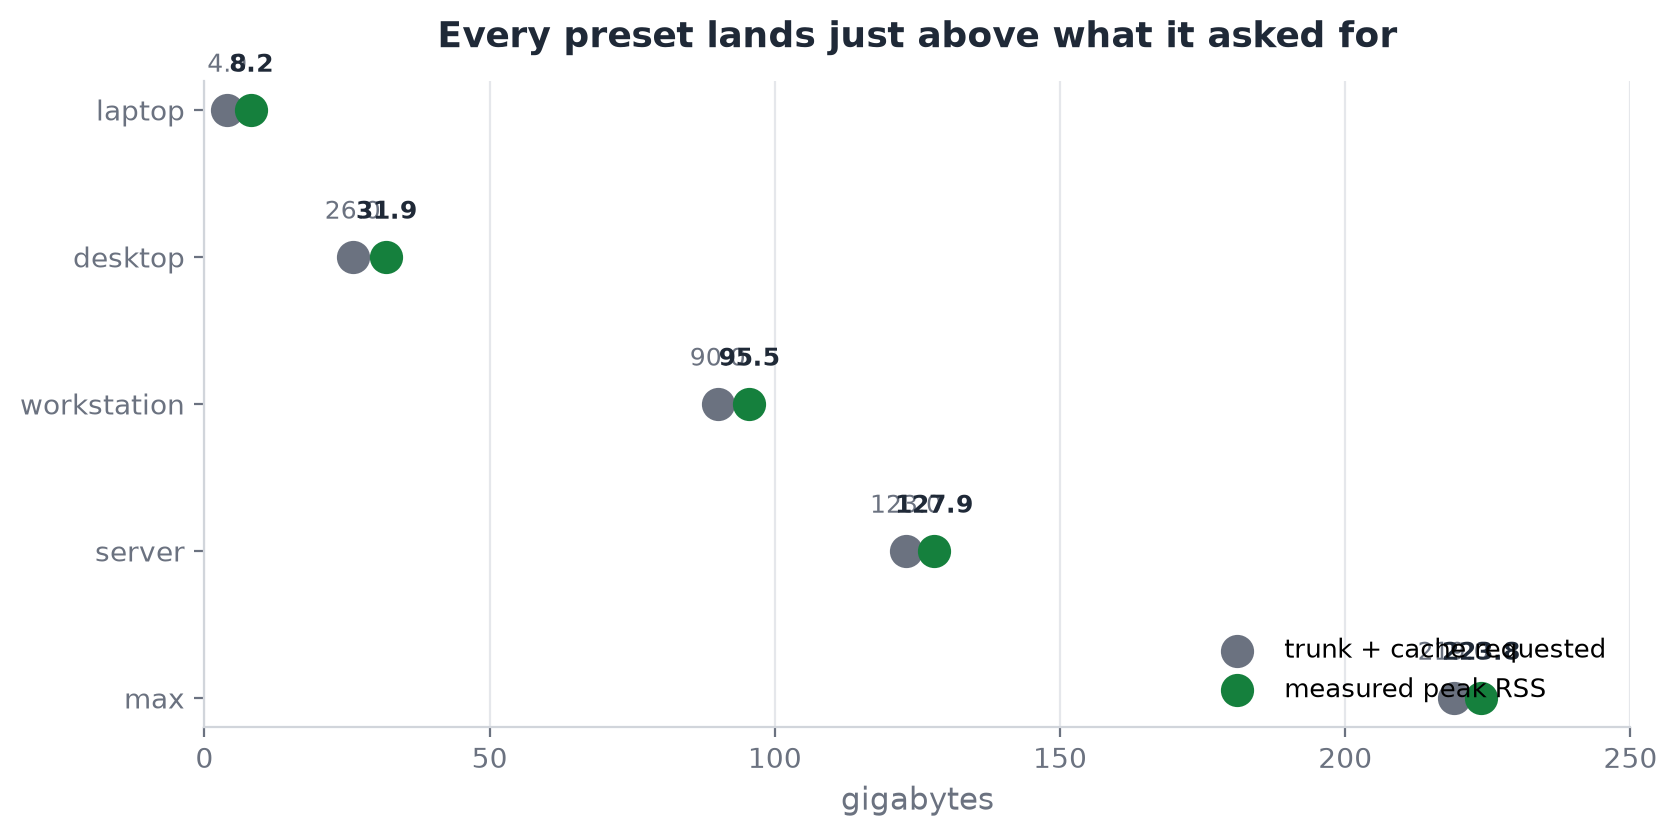
The boundaries come from the measured ladder, and the doctor keys on MemAvailable rather
than MemTotal:
if   [ "$AVAIL_GB" -ge 192 ]; then PRESET=server;      EXPECT="~6 s/token"
elif [ "$AVAIL_GB" -ge  96 ]; then PRESET=workstation; EXPECT="~6-20 s/token"
elif [ "$AVAIL_GB" -ge  32 ]; then PRESET=desktop;     EXPECT="~24 s/token"
elif [ "$AVAIL_GB" -ge  10 ]; then PRESET=laptop;      EXPECT="~27 s/token"
else PRESET=""; fi
Two things worth knowing before you pick:
maxis not faster thanserverin these measurements. The extra 96 GB buys nothing outside the noise floor.- A preset needs a little more free memory than its peak RSS. The engine refuses any
plan above 95% of available memory, to leave room for everything outside the plan, so
serverat about 128 GB needs roughly 135 GB available, not 128. - Give the trunk memory before the expert cache. At a fixed 128 GB budget that was worth 1.69×. Allocation beats capacity has the data.
Reading the run report
The engine prints a memory plan, then a line per generated token, then a summary. Abridged
from a workstation run:
cache [final step]
  requests     : 1472  hits 1472 (100.00%)  misses 0  evictions 729
                 TRUE resident hit rate 50.48%
I/O share of wall clock: 71.1%  (trunk 62.4 s + experts 34.2 s of 135.8 s)
trunk [final]
  pinned 48/93 layers, ring 1 slots
  read 368.65 GB in 62.40 s (5908 MB/s)
PEAK RSS for the whole run: 94.74 GB   <- quote this, not the plan
Three numbers carry the meaning:
TRUE resident hit rate: experts served from RAM. The rawhitscounter also counts experts the prefetcher pulled off disk moments earlier, so it reads 100% at every cache size; the resident figure is printed beneath it.I/O share of wall clock: whole-run disk time against total, measured between 41% and 61% across the ladder.PEAK RSS: fromgetrusage, after the run. This is the memory figure; the up-front plan runs slightly above it.
Common questions
Memory sits near 113 GB even at a small preset. --trunk was omitted. Without a packed
trunk directory the whole trunk is loaded resident; every preset assumes streaming.
A non-ASCII prompt tokenizes oddly. The shell re-encodes argv, so the engine receives
different bytes than you typed. Put the prompt in a file and use --prompt-file, which is
read verbatim.
--prompt/--prompt-file need --tok DIR. The tokenizer ships with the checkpoint, so
add --tok ~/k3model. The engine exits rather than guessing where the vocabulary lives. To
skip the tokenizer entirely, pass token ids with --ids.
Throughput is well below the table. Almost always storage. python3 tools/devbw.py <file-on-that-disk> measures the disk the way the engine reads it, using large random
O_DIRECT reads at queue depth 1 and 16, which dd does not. Network volumes run several
times slower than local NVMe; keep ~/k3trunk local.
The run refused to start over the KV cache. Context costs about 2.37 MB per position
regardless of budget, and the engine computes that up front rather than discovering it an
hour in. Shorten the request, or drop --incremental, which carries no KV cache at all.
Is the whole 1.56 TB needed? For generation, yes. For development, no: make test
needs nothing at all, and --layers N runs against partial shard sets.
scripts/download-model.sh <dest> --layers N fetches only the shards those layers need,
about 7 GB for N=1 and 125 GB for N=8. That is for exercising the pipeline on a small
disk; a layer prefix is not the model and does not produce its output.
Why no BLAS? Because every matmul here has to give the same bits on every machine.
The test suite checks the engine against a PyTorch reference exactly, not to a tolerance,
and that only works if the order in which each dot product is summed is fixed and known.
A BLAS library chooses its own blocking and reduction order, which can differ between
versions, between vendors (OpenBLAS, MKL, Accelerate), and between thread counts on the
same machine. Each of those answers is numerically correct and none of them matches the
others bit for bit. The kernels in src/core/k3_ops.c exist to pin that order: the AVX2
and NEON paths reproduce the scalar reduction exactly, and test_ops checks they do.
It also keeps the build free of a dependency that installs differently on each
platform, for kernels that are not the bottleneck anyway. A run is limited by how fast
the trunk and the experts come off disk, not by arithmetic.
macOS, Windows, WSL? Linux is the reference platform. macOS/arm64 builds with plain
make (see the Makefile's platform block). Windows builds natively too, via MSYS2's
MinGW-w64 GCC (pacman -S mingw-w64-x86_64-gcc, then open the "MSYS2 MinGW x64" shell
specifically -- make, make test, and make test-all all pass every gate unmodified,
including the full-model oracle and tokenizer parity against real Kimi K3 weights.
Four Linux-only calls needed porting -- O_DIRECT, pread, posix_memalign, and
getrusage -- documented in src/io/k3_portable_io.h. One real bug surfaced during the
port and is worth knowing if you extend this code on Windows: _aligned_malloc, which
backs the posix_memalign shim, must be freed with _aligned_free, not plain free;
POSIX's posix_memalign carries no such restriction, so this is easy to get wrong
silently -- it compiles, and Windows terminates the process with STATUS_HEAP_CORRUPTION
only once the corrupted allocator metadata is actually used. make asan/make ubsan
switch to Clang on Windows (pacman -S mingw-w64-clang-x86_64-clang mingw-w64-clang-x86_64-compiler-rt): MinGW-w64's GCC package ships no sanitizer runtime
at all, confirmed directly rather than assumed. WSL works too, unmodified, since it is
just Linux -- the tokenizer and config reader are portable C99 either way and build
anywhere, in CI included.
Part II: How it works
The problem: a model that does not fit
Kimi K3 has 2.78 trillion parameters and is 1.56 terabytes as shipped. No consumer machine can hold it, and waiting for better hardware does not help, because the wall is not speed, it is capacity.
But it is a mixture of experts, so only 16 of its 896 experts per layer fire for any given token and the rest sit asleep on disk. Keep the always-on part in memory, stream the sleeping experts, and it fits in 8.24 gigabytes on one CPU with no GPU.
The naive requirement is the one every parameter count implies.
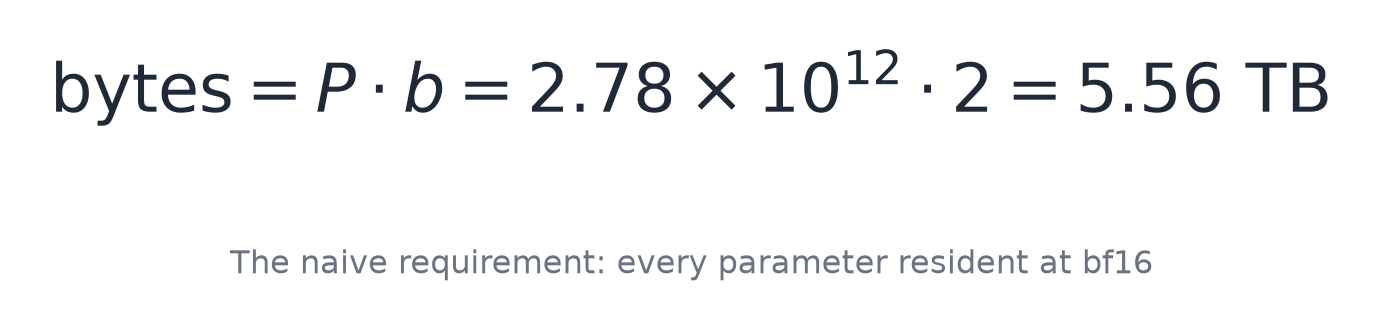
So 5.56 terabytes is the number to beat.
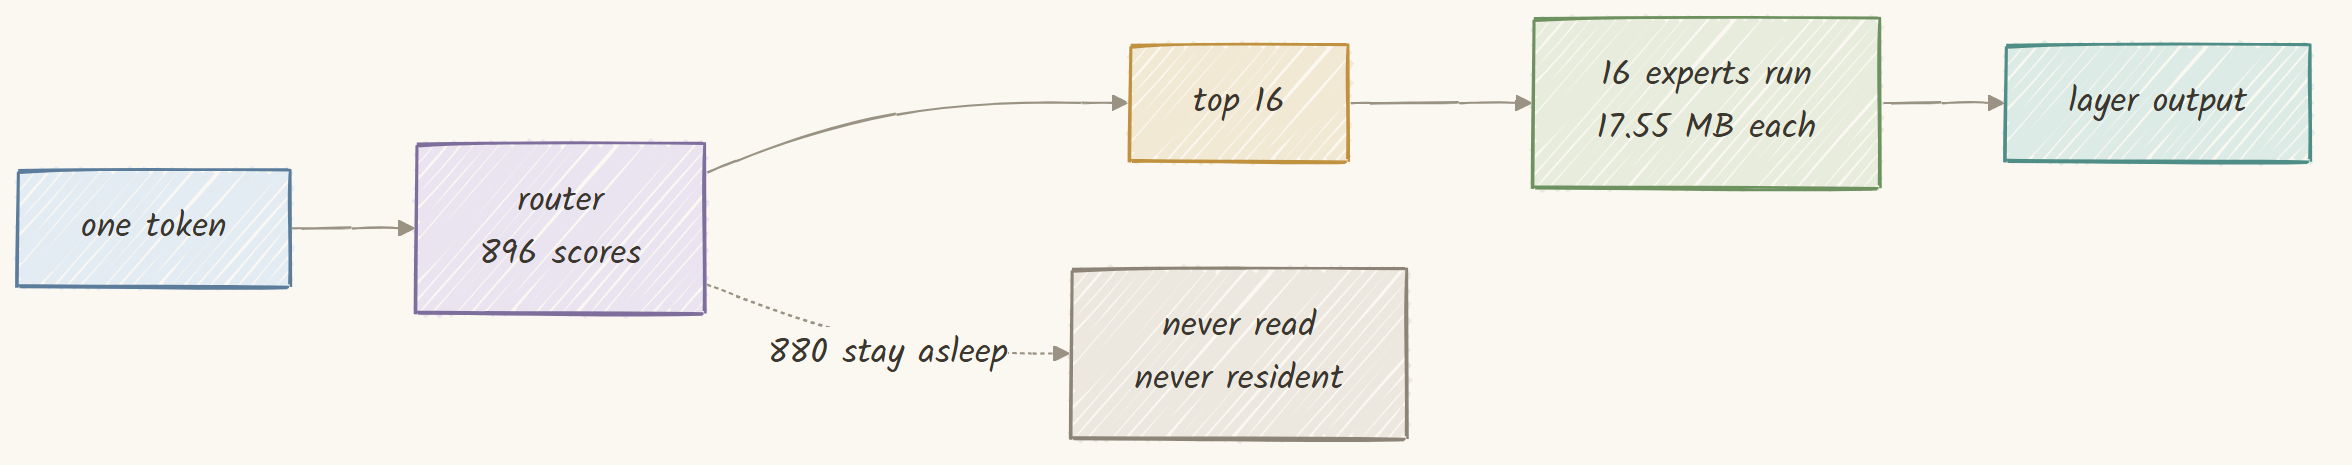
Kimi K3 has 93 layers. Layer 0 is a plain dense feed-forward layer, so the other 92 layers route, and each of those picks the top 16 experts out of 896.
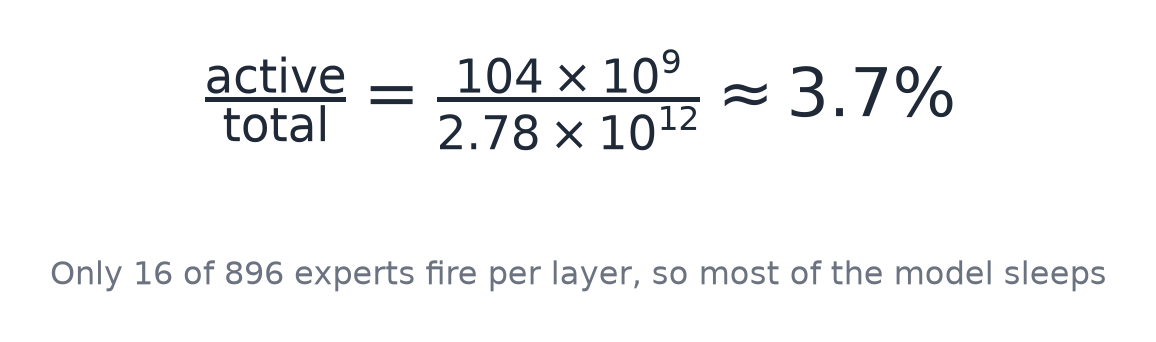
About 104 billion parameters are active for any given token, out of 2.78 trillion, which is 3.7 percent. The other 96.3 percent still has to exist somewhere reachable, but it does not have to be in RAM.
Counting the actual bytes on disk rather than guessing:
=== shard census: what the 1.56 TB actually is ===
shards            : 96
total bytes       : 1560936091448  (1.56 TB)

--- routed experts (the part that is streamed, never resident) ---
  experts total     : 82,432   (896 routed x 92 MoE layers)
  bytes per expert  : 17,547,264  exactly
                      = 33,030,144 params x 0.53125 bytes
                      = 0.5 bytes/nibble + 1/32 byte for the shared E8M0 scale
  routed expert set : 82,432 x 17,547,264 = 1.447 TB
There are 82,432 routed experts, each occupying exactly 17,547,264 bytes. Together they are 1.447 terabytes, which is 93 percent of the entire checkpoint. Everything else (attention projections, routers, norms, embeddings) is the remaining 7 percent.
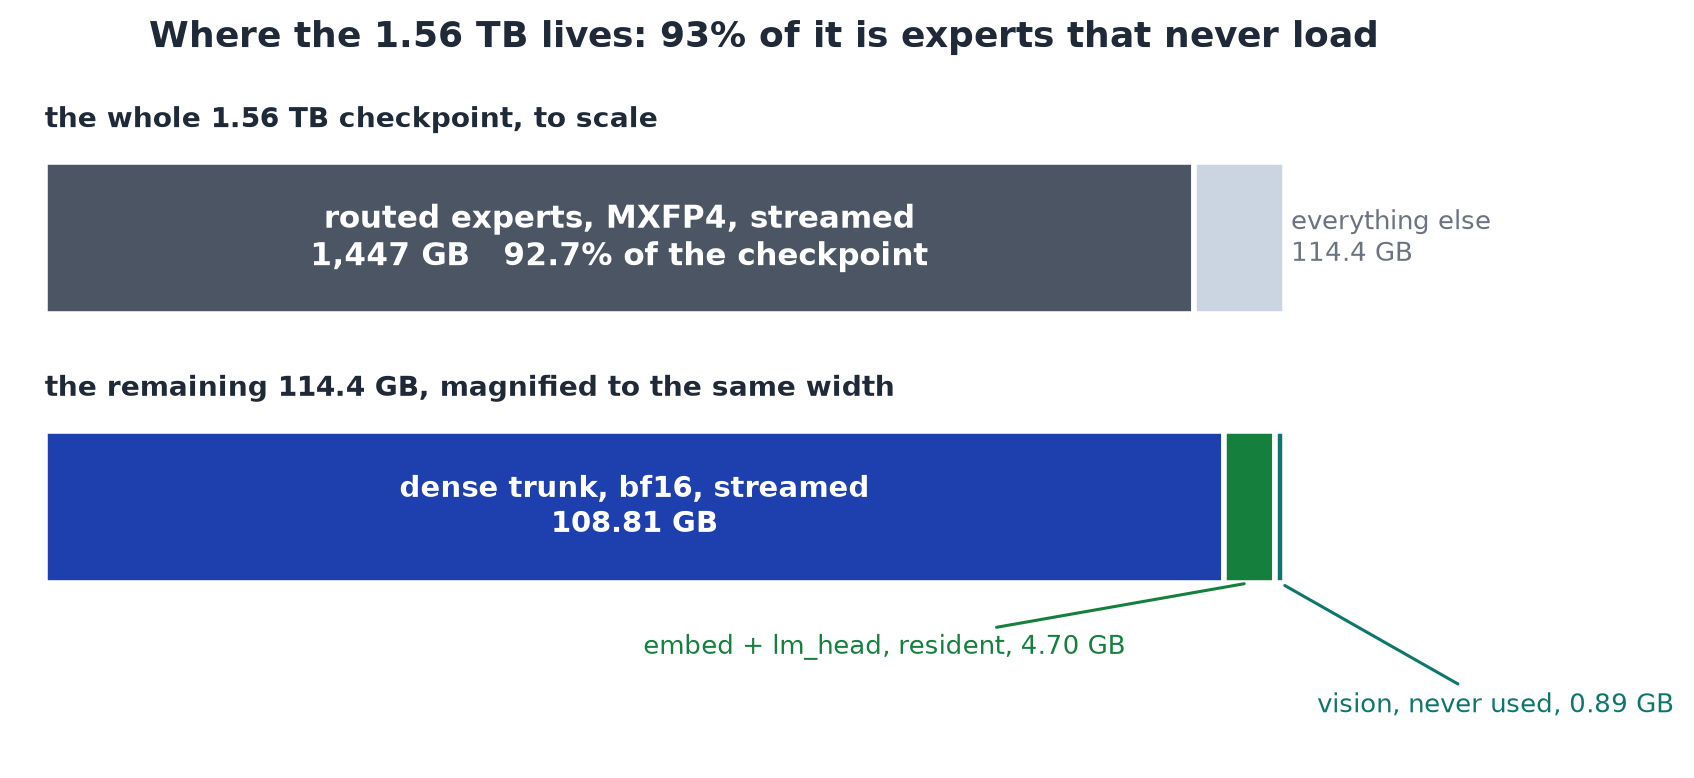
That census is the whole strategy in one picture. If those 1.447 terabytes can be reachable but never resident, the memory problem shrinks by more than an order of magnitude before a single kernel is written.
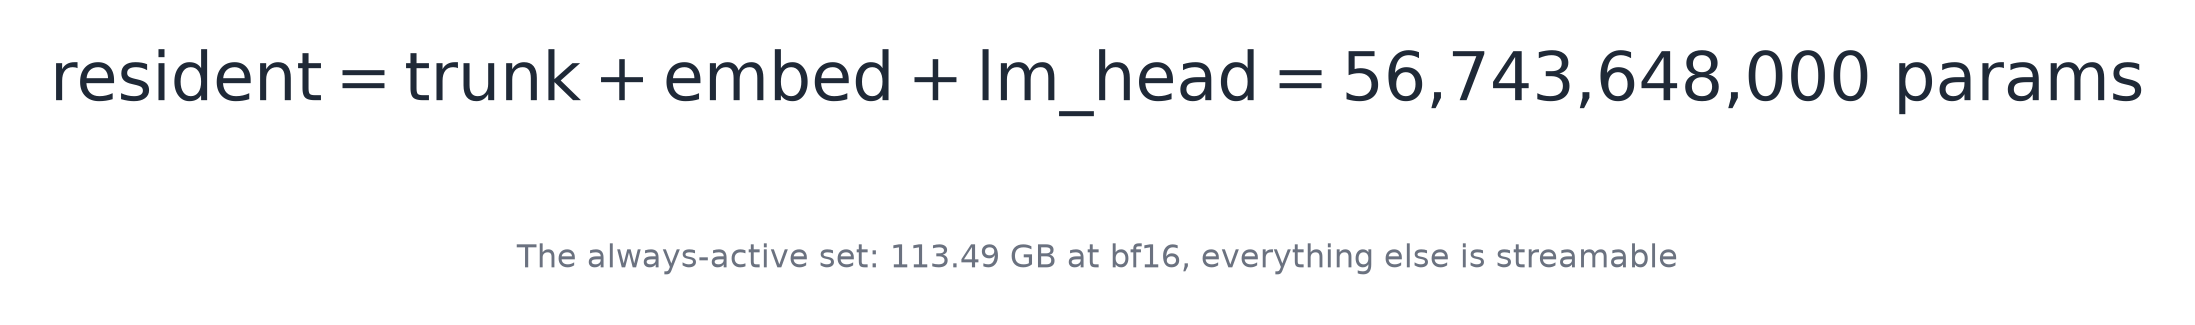
What is left is 56,743,648,000 parameters, or 113.49 gigabytes at bfloat16. Of that, 108.81 GB is the per-layer dense trunk and 4.70 GB is the embedding table plus the output head.
The four reductions
- 5,560 GB: every parameter at bfloat16, where we start.
- 1,560 GB: the checkpoint as shipped, because the experts already arrive at half a byte per weight.
- 113.49 GB: what has to be resident once routing means the experts never load.
- 8.24 GB: what is measured, once the trunk is streamed instead of held.
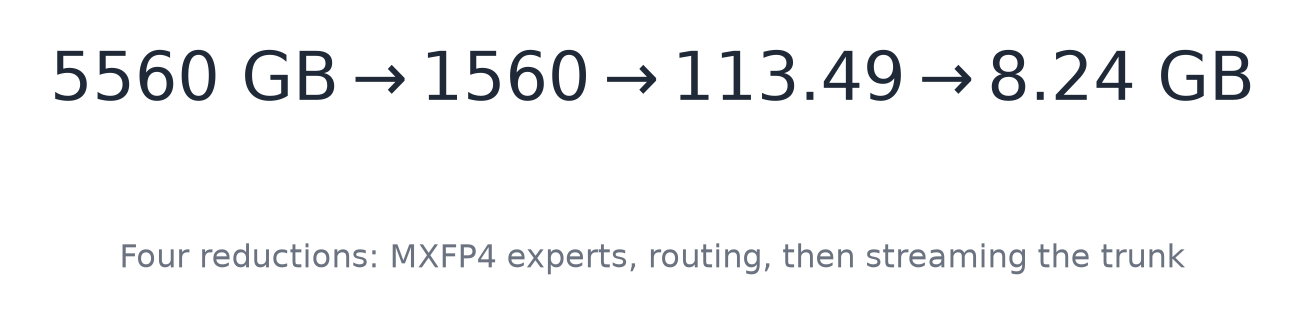
End to end that is a 675× reduction from the bfloat16 model and 189× from the shipped checkpoint. Nothing is approximated and no weight is dropped: the output at the bottom of that ladder is byte for byte the output at the top. The chart at the top of this document is that ledger drawn to scale.
The machine, and what it assumes
Every measurement here comes from one workstation: a two-socket AMD EPYC 7763 with 124 cores and no SMT, 228 GB of RAM, and 3.2 TB of NVMe. It also has four NVIDIA L40 GPUs, which sat completely idle for the entire campaign, because this engine has no GPU path.
--- ISA (note: AVX2 present, AVX-512 ABSENT) ---
avx avx2 fma sse4_2

--- memory ---
Mem:           228Gi       5.1Gi       207Gi       3.1Mi        18Gi       223Gi
MemTotal:       239308464 kB
MemAvailable:   233961008 kB
Hugepagesize:       2048 kB
There is no AVX-512. The engine needs AVX2 and FMA and nothing more, the instruction set on any desktop CPU from the last decade.
The storage numbers matter more than the CPU numbers, and one runs against expectation.
--- storage bandwidth, measured ---
O_DIRECT cold : 3.2 GB/s     (dd bs=4M iflag=direct after drop_caches)
buffered warm : 2.3 GB/s
engine, trunk : 5373-6064 MB/s sustained during runs
NOTE O_DIRECT is FASTER than buffered here. That is the opposite of the usual
expectation, and it is why the engine opens the trunk O_DIRECT.
Reading with O_DIRECT, bypassing the page cache entirely, is faster here than
reading through it. That single measurement decided the whole I/O design.
One piece of hygiene, because a loaded machine is easy to measure badly:
--- measurement hygiene ---
unattended-upgrades: STOPPED and DISABLED before measurement (was using ~63% of a
  core during the smoke run).
apt-daily.timer and apt-daily-upgrade.timer: DISABLED
A background package updater eating most of a core moves a timing by more than most optimisations do, so it goes off before anything is measured.
How much memory does the engine actually need? Multiplying config values by hand gives the
wrong answer in an instructive way, which is why tools/budget.py exists:
# Streamable only if ROUTED. The 2 SHARED experts sit in the same namespace and
# are NOT streamable, which is where hand arithmetic goes wrong.
def classify(name: str) -> str:
    if ".block_sparse_moe.experts." in name:
        return "routed_expert"          # streamable: only 16 of 896 per token
    if ".block_sparse_moe.shared_expert" in name:
        return "shared_expert"          # RESIDENT: runs on every token
    if ".self_attn." in name:
        return "attention"              # resident
    if "embed_tokens" in name or "lm_head" in name:
        return "embedding"              # resident
    return "other"                      # norms, router gates, biases: resident
The two shared experts run on every token, so they belong in the resident set even though their tensor names sit next to the routed experts. Getting that wrong makes the floor look smaller than it is, which is the worst direction to be wrong in.
The codebase
Six C files compiled into one binary. No BLAS, no PyTorch, no ONNX runtime, no GPU library. The only dependencies are libm and OpenMP.
include/k3/
  k3.h              # the public header: config, weights, every kernel prototype
  k3_cfg.h          # config reader, header-only, refuses to substitute defaults
src/
  core/k3_ops.c     # every numeric kernel: RMSNorm, KDA, MLA, MoE, MXFP4 matmul
  io/k3_st.c        # safetensors reader, hand-written JSON scan, O_DIRECT reads
  io/k3_load.c      # locating one expert's bytes inside a shard
  io/k3_trunk.c     # streaming the dense trunk, pinned prefix plus a ring slot
  cache/k3_cache.c  # the routed-expert LRU cache and its batch prefetch
  model/k3_bind.c   # binding checkpoint tensor names to kernel arguments
  tokenizer/k3_tok.h# byte-level BPE loaded from tiktoken.model
  cli/k3_run.c      # the k3 binary: memory plan, decode loop, reporting
tools/              # python: pack the trunk, replay the cache, verify against torch
benchmarks/         # the cgroup memory ladder and the split sweep
tests/              # fixtures, the tiny oracle, the 93-layer conformance run
CFLAGS = -O3 -std=gnu99 -Wall -Wextra -Wpointer-arith -Wshadow -Wvla \
         -march=native -fopenmp -ffp-contract=off
LDFLAGS = -lm -fopenmp
The flag that looks unusual is -ffp-contract=off. By default a compiler may fuse a
multiply and an add into a single FMA, which changes the rounding. That is normally good.
Here it is a problem, because the scalar path, the OpenMP path and the AVX2 path must
produce bit-identical results, so that a performance change can never quietly become
an accuracy change.
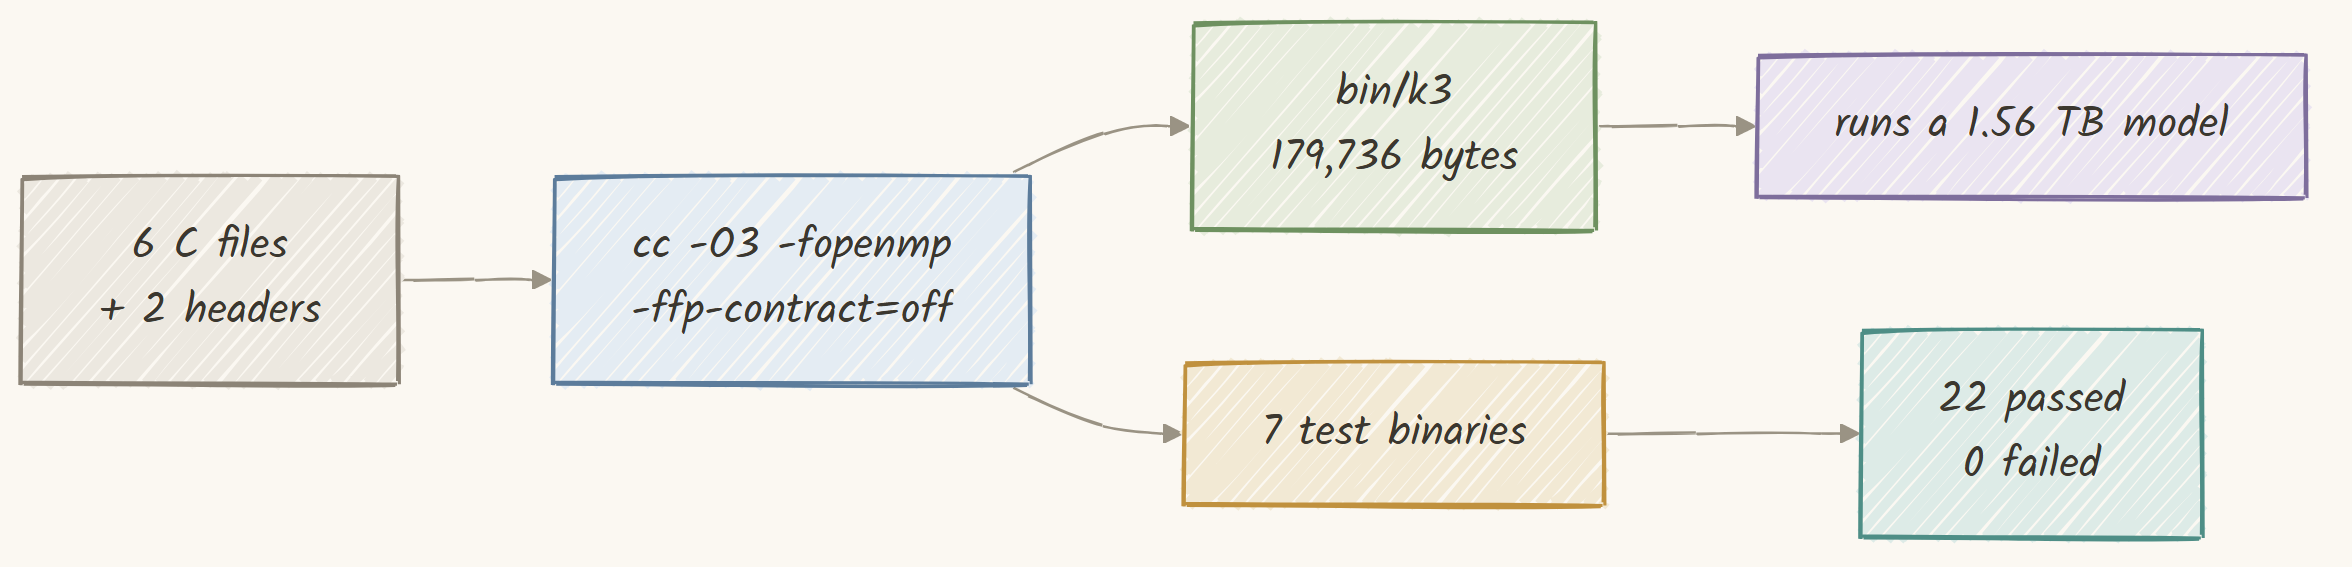
1. build, warnings are failures
  -> clean build, no diagnostics
  test_ops          97784 bytes
  k3_model          89392 bytes
  k3_run           179736 bytes
The whole inference engine is 179,736 bytes, a 176 kilobyte binary whose job is to run a 1.56 terabyte model.
One check crosses machines. The tokenizer was run on the same input file under Windows and under Linux:
=== cross-platform tokenizer determinism ===
  Linux   gcc 13.3.0  x86_64
  Windows gcc 16.1.0  x86_64
  input   src/k3.h (24,499 bytes) -> 6,862 ids
  result  IDENTICAL id streams

  (a naive md5 of stdout DIFFERS by one byte: Windows text-mode stdout writes the
   trailing newline as CRLF. That is the pipe, not the tokenizer.)
Two compilers on two operating systems produce the same 6,862 token ids from the same 24,499 bytes. The md5 sums differ by exactly one byte, and the reason is the line ending the shell added, not anything the tokenizer did.
Three invariants
The public header opens with three invariants that must hold. Each one is a place where a plausible-looking implementation produces a model that runs, emits fluent text, and is wrong, with no crash and no NaN to warn you.
A_logis indexed per head, not per channel. The checkpoint shipshead_dimfloats but only the firstnum_headsare meaningful; the rest are padding.- MLA uses NoPE, yet the 64 rope dimensions still exist and are still cached. Only the rotation is absent; dropping the slots changes the head width.
- The MoE routing bias steers selection only. The combining weights come from the unbiased sigmoid scores.
Each is ticked off below as its component arrives, and each is gated by a fixture chosen
so that getting it wrong changes the output: A_log by a linspace that a per-channel
misindex scrambles, NoPE by asserting the softmax scale is over the full head width, and
the routing bias by a fixture whose bias reorders the top-k on five of its six rows.
This list used to have five entries. The other two, that the UT-transform inverse is
(I + Akk)^-1 and that Aqk keeps its diagonal while Akk does not, describe the
chunked parallel form of the delta rule. This engine does not use it. k3_kda_step runs
the naive sequential recurrence one position at a time, and so does the PyTorch reference
it is checked against, so neither matrix is ever formed. They were claims about an
algorithm rather than about this code, nothing implemented them, and no test could have
caught getting them wrong. They now live in docs/ARCHITECTURE.md
with the rest of the algorithm description. Restoring a chunked KDA path means restoring
them, with the fixtures that gate them.
1. Reading a 1.56 TB checkpoint from its headers
The checkpoint is 96 safetensors files. The format is deliberately simple, which is what makes it possible to treat 1.56 terabytes as an index rather than as data.
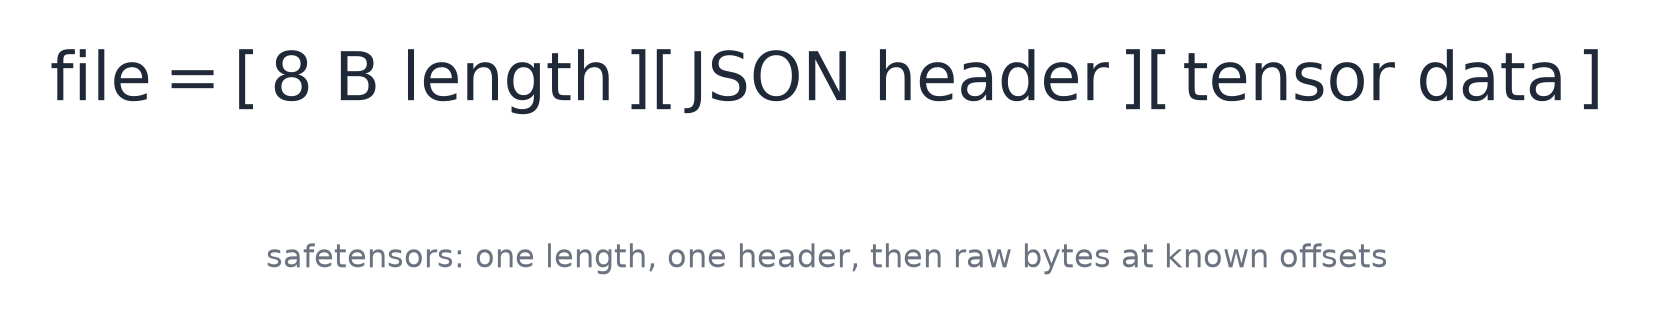
Every file starts with an 8-byte little-endian length, then that many bytes of JSON describing every tensor, then the raw tensor bytes back to back. Nothing is compressed and nothing is interleaved.
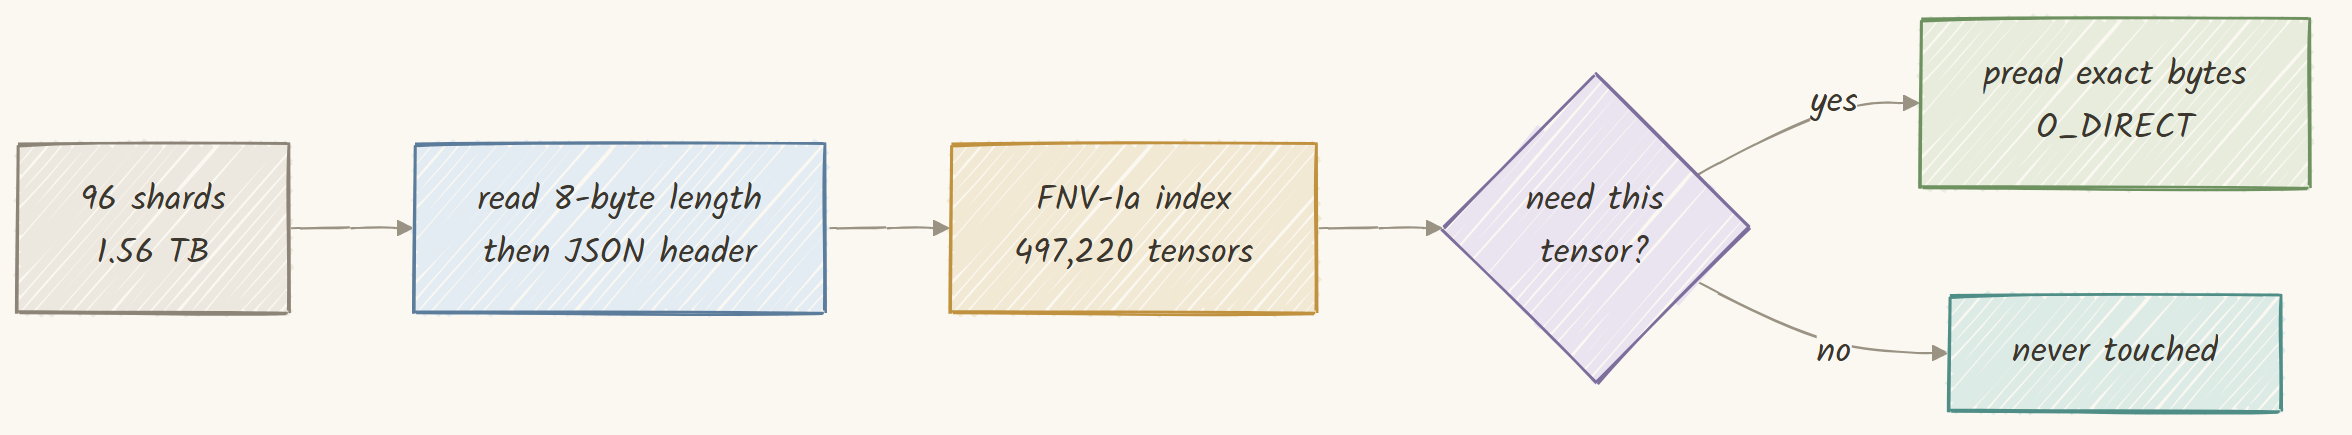
No JSON library is used. The header can be tens of megabytes and only four fields per tensor are wanted, so the reader scans it directly.
/* Walk the header once, copy nothing we do not need. `p` sits just past the
 * opening quote of the tensor name. */
static const char *st_scan_entry(const char *p, const char *end, K3Tensor *t)
{
    const char *q = memchr(p, '"', (size_t)(end - p));
    if (!q || (size_t)(q - p) >= sizeof t->name) return NULL;
    memcpy(t->name, p, (size_t)(q - p));
    t->name[q - p] = '\0';

    const char *d = st_find_key(q, end, "dtype");
    if (!d) return NULL;
    t->dtype = st_dtype_code(d);

    const char *s = st_find_key(q, end, "shape");
    if (!s) return NULL;
    t->rank = 0;
    t->nelem = 1;
    for (const char *c = s; c < end && *c != ']'; c++) {
        if (*c >= '0' && *c <= '9') {
            long v = strtol(c, (char **)&c, 10);
            if (t->rank >= K3_ST_MAXRANK) return NULL;
            t->shape[t->rank++] = v;
            t->nelem *= (size_t)v;
        }
    }

    /* offsets are RELATIVE to the start of the data section */
    const char *o = st_find_key(q, end, "data_offsets");
    if (!o) return NULL;
    t->off  = (size_t)strtoull(o, (char **)&o, 10);
    while (o < end && (*o < '0' || *o > '9')) o++;
    t->nbytes = (size_t)strtoull(o, (char **)&o, 10) - t->off;
    return o;
}
Every tensor goes into a hash table keyed by a hash of its name. The choice of hash is not arbitrary.
/* Names are long and share deep prefixes
 * ("language_model.model.layers.N.block_sparse_moe.experts.M...."), so the hash must
 * mix every byte; a prefix-only or length-only hash would pile every expert of a
 * layer into one bucket. */
static uint64_t fnv1a(const char *s)
{
    uint64_t h = 1469598103934665603ull;
    while (*s) { h ^= (unsigned char)*s++; h *= 1099511628211ull; }
    return h;
}
Half a million tensor names that all begin with the same forty characters is a genuinely hostile input for a hash function. FNV-1a mixes on every byte, so the expert index at the end of the name still moves the result.
Reading a tensor afterwards has one wrinkle: O_DIRECT requires the offset and the length
to be multiples of the block size, and a tensor starts wherever the previous one ended.
int64_t k3_st_read_aligned(const K3St

[Content truncated due to size limits]
FAQ
Common questions
Discussion
Questions & comments · 0
Sign In Sign in to leave a comment.