
Build and debug code with self-improving agentic models
Ornith is an open-weight, self-improving model family for agentic coding and reasoning, benchmarked at 397B, 35B-A3B, and 9B sizes.
1.0.0Add to Favorites
Why it matters
Deploy state-of-the-art open-source coding agents that autonomously generate, debug, and improve code across complex repositories and terminal environments. The models use reinforcement learning to discover better search trajectories and jointly optimize both scaffolding and solution quality.
Outcomes
What it gets done
Generate complete code solutions for repository-level tasks using NL2Repo capabilities
Debug and fix real-world GitHub issues with SWE-bench verification
Execute terminal commands and automate coding workflows with Terminal-Bench agents
Review and test code across multiple languages with multilingual SWE-bench support
Source
Get it from source
Spark does not host a copy of it.
Open sourceReports
Agent outcome reports
No reports yet
Overview
Ornith is a family of self-improving, open-weight models for agentic tasks, released in two generations (1.0 and 1.5) at 397B, 35B-A3B, and 9B sizes. Ornith-1.5 runs a full self-improvement loop: proposing tasks, generating scaffolds, and producing reinforcement-learning rollouts. Reach for it when evaluating open-weight models for agentic coding, reasoning, or tool-use tasks and you want published, size-comparable benchmark numbers against Qwen, Gemma, Claude Opus, and Kimi K3.
What it does
Ornith is a family of self-improving open-source models for agentic tasks, covering two generations. Ornith-1.5 (the latest) extends self-scaffolding into a complete end-to-end self-improvement loop: the model proposes new tasks, generates task-specific scaffolds, and produces solution rollouts for reinforcement learning. Ornith-1.0, the first release, jointly optimizes the scaffold and the resulting solution rollouts. Both generations are MIT licensed, globally accessible, and free from regional limitations, with model weights published on separate HuggingFace collections for each generation.
When to use - and when NOT to
Use it when you need an open-weight model tuned for agentic coding, reasoning, and tool-use tasks - published benchmark results cover coding (Terminal-Bench 2.1, SWE-bench Verified/Pro/Multilingual, NL2Repo), reasoning (HLE, GPQA Diamond), and agentic evaluations (MCP-Atlas, Toolathlon-Verified, WideSearch, BrowseComp, ClawEval). Three sizes are benchmarked - 397B, 35B-A3B, and 9B - so the model can be matched to the available compute.
Capabilities
On the published benchmarks, Ornith-1.5-397B scores 86.1 on Terminal-Bench 2.1 (Terminus-2), 86 on SWE-bench Verified, 65.1 on SWE-bench Pro, 92.8 on GPQA Diamond, 80 on MCP-Atlas, and 86.6 on BrowseComp - consistently ahead of Ornith-1.0-397B on the same benchmarks (77.5, 82.4, 62.2, 88.1, 76.4, and 79.7 respectively) and competitive with DeepSeek-V4-Flash-0731, GLM-5.2, Claude Opus 4.8, and Kimi K3 on the same table. The generation-over-generation gap is largest on DeepSWE (56 vs 8) and Frontier-Bench v0.1 (13.5 vs 2.7) at 397B, where Ornith-1.0 trailed most of the comparison models and Ornith-1.5 moved ahead of several of them.
The smaller sizes follow the same pattern. At 35B-A3B, Ornith-1.5 scores 67.8 on Terminal-Bench 2.1 (Terminus-2) and 79 on SWE-bench Verified versus Ornith-1.0's 64.2 and 75.6, and versus Qwen3.6-35B-A3B's 52.5 and 73.4; on GPQA Diamond it reaches 89.2 and on MCP-Atlas 70.2. At 9B, Ornith-1.5 scores 46.2 on Terminal-Bench 2.1 (Terminus-2) and 70.6 on SWE-bench Verified, against Qwen3.5-9B's 21.3 and 53.2 at the same size, with GPQA Diamond at 86.4 and MCP-Atlas at 54.2. Every size and category reported shows Ornith-1.5 ahead of Ornith-1.0 at the same parameter count. On the SWE-bench Multilingual, NL2Repo, and SWE Atlas - QnA rows the same ordering holds across all three sizes, and on HLE (both with and without tools) Ornith-1.5 also leads its predecessor at every size, though Claude Opus 4.8 still scores higher on the 397B GPQA Diamond and HLE rows.
Who it's for
Teams evaluating or deploying open-weight models for coding agents, tool-use, and agentic reasoning workloads who want published, size-comparable benchmark numbers against both open (Qwen, Gemma) and closed (Claude Opus, Kimi K3) models before choosing a weight class.
Source README
Ornith
Aloha! 🌺 Ornith is a family of self-improving open-source models for agentic tasks. This repo covers both generations:
- 🐦 Ornith-1.5 (latest) - extends self-scaffolding into a complete end-to-end self-improvement loop: the model proposes new tasks, generates task-specific scaffolds, and produces solution rollouts for reinforcement learning. Model weights at HuggingFace, and more details can be found at blog.
- 🐦 Ornith-1.0 - the first release, which jointly optimizes the scaffold and the resulting solution rollouts. Model weights at HuggingFace, and more details can be found at blog.
Both generations are MIT licensed, globally accessible, and free from regional limitations.
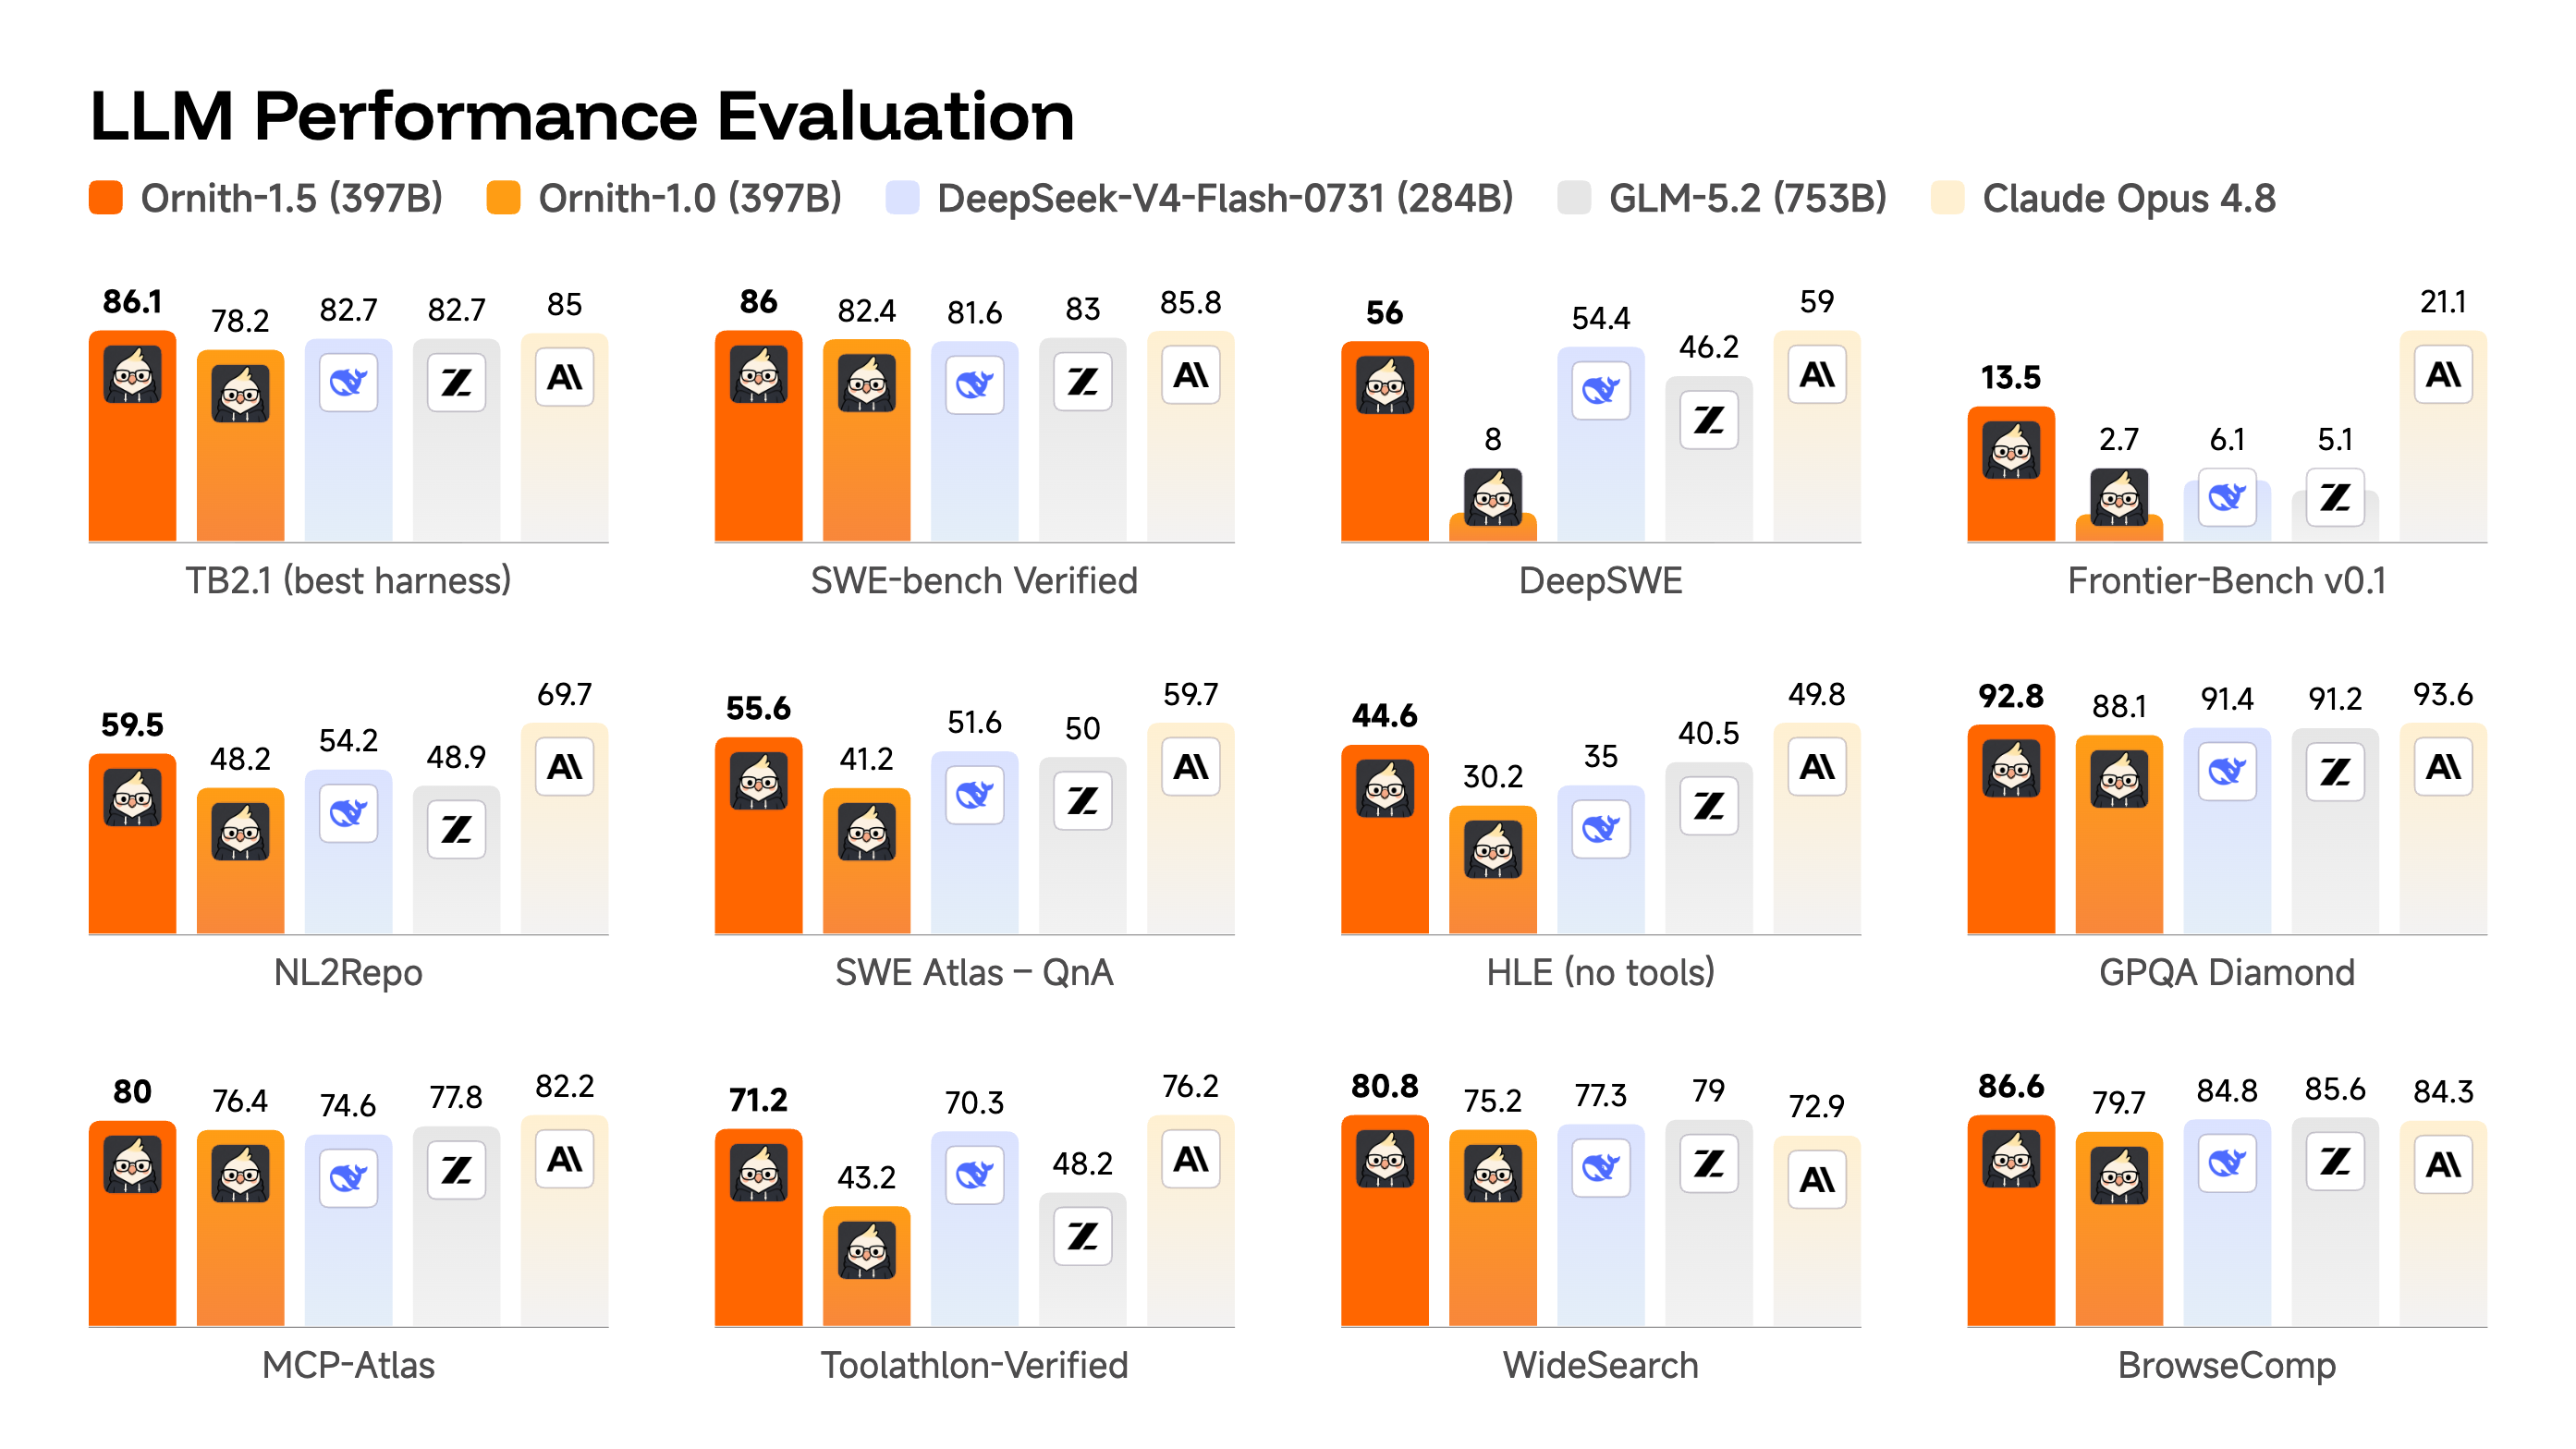
Benchmarks
397B
35B-A3B
9B
FAQ
Common questions
Discussion
Questions & comments · 0
Sign In Sign in to leave a comment.