
Train AI agents to write and optimize RL training jobs
Open-source pipeline where an RL-trained agent writes prime-rl jobs, runs them on Runpod GPUs and earns reward when the small models it trains improve.
0.1Add to Favorites
Why it matters
Automate the creation of reinforcement learning training pipelines by using an RL-trained agent that writes complete training jobs-including environments, rewards, datasets, and hyperparameters-then submits them to GPU infrastructure and iteratively improves based on training outcomes.
Outcomes
What it gets done
Generate complete prime-rl training configurations with environments, reward functions, and hyperparameters
Submit and orchestrate training jobs across distributed GPU pods with validation and retry logic
Evaluate trained model performance on hidden test sets and compute uplift metrics
Iteratively refine training job quality through reinforcement learning feedback loops
Source
Get it from source
Spark does not host a copy of it.
Open sourceReports
Agent outcome reports
No reports yet
Overview
AI Trains AI is a pipeline where an agent receives a task such as teach a model to do X, writes a complete prime-rl training job with environment, reward, dataset and hyperparameters, and submits it to real Runpod GPUs. The agent is then RL-trained on Tinker and rewarded when the models it trains score better on a hidden eval. Use it to reproduce or extend RL training of an agent that trains models, or to reuse its harness, reward code, GPU orchestration and released LoRA adapter. Run agent-written code in a container first when the policy is untrusted or heavily RL-trained.
What it does
AI Trains AI is a pipeline in which an AI agent is handed a training task ("teach a model to do X"), writes a complete prime-rl training job, and submits it to real Runpod GPUs. The job includes the environment, reward, dataset and hyperparameters. Using Tinker, the agent itself is then RL-trained and rewarded when it trains better models. Reward climbed from about 0.0 to a peak near 0.63 over 54 training steps, and the skill transferred to a held-out task family the agent never trained on. Everything is open sourced: the trained agent's weights as a LoRA adapter on Hugging Face, the agent harness, task families, reward code, GPU orchestration, Tinker RL training scripts and retro write-ups of every pilot, failures included.
There are two RL loops with two separate training stacks. In the outer loop the trained agent is Qwen3.6-35B-A3B with LoRA, trained on Tinker and tinker-cookbook with importance-sampling GRPO, and episode reward is the policy-gradient signal. In the inner loop the trained model is a small base model (Qwen3-0.6B or 1.7B), trained by prime-rl with GRPO on Runpod GPUs using the job the agent wrote: a verifiers environment and rubric plus a [prime_rl] config table. The inner model's hidden-eval score flows back up as the outer loop's reward.
One episode is one attempt to produce a valid, high-quality training job:
- Task spec: a description of what to train, hard constraint bounds, the eval tool interface and a handful of dev examples.
- The agent edits a sandboxed workspace with
read_file,write_file,edit_fileandlist_files, and can callget_baseline_scoresto see untrained base models' scores on the hidden eval. submit_jobtriggers a validation probe. Failures are returned and the agent gets capped retries.- A validated job is queued and picked up by a warm pool of Runpod GPU pods that run GRPO training with prime-rl and score the checkpoint before and after on the hidden eval.
- Reward combines validation efficiency with the trained model's uplift over the best untrained baseline.
Every outer-loop batch spawns 40 real inner training jobs across up to 16 GPU pods.
When to use - and when NOT to
Use it to reproduce or extend RL training of a model-training agent, or to reuse pieces of it: the harness, reward code, GPU orchestration or the released adapter.
Agent-written code executes in a timeout-guarded subprocess on the host, not in a container. That is fine for frontier APIs and your own checkpoints on a template contract, but containerise the probe before running untrusted or heavily RL-trained policies.
Current limits: the agent submits one job per episode, and only stateless tool-calling environments are exposed, so it cannot yet train stateful coding agents.
Inputs and outputs
Episode reward is a weighted sum with live weights 0.35 validation, 0.60 job quality and 0.05 train speed. Validation is 1.0 for a first-try valid submission, decaying per extra attempt, and 0 if the episode never validates; an episode with no parseable submission scores -0.1. Job quality is 0.25*post + 0.75*uplift_term, mixing the trained model's post-training score with its signed uplift over best_pre, the best untrained model's frozen baseline; a job that dies on the GPU scores 0 here. Train speed is a small tie-breaker gated on job success. The prompt the agent sees gives a simplified view of this reward, and the published adapter was trained against that prompt.
Six task families are used, all requiring multi-step tool use: calc_chain (0.742 untrained best_pre), multi_hop (0.654), string_pipeline (0.545), ledger (0.242), dispatch (0.323) and triage (0.352). Triage is held out and serves as the generalisation probe. A task file such as the calc_chain one sets the allowed base models, bounds on the training knobs (listed for the fast task file below) and a 1800 second train budget. Its hidden eval scores 0.8 * correct_answer + 0.2 * used_calculator.
Results with LoRA rank 8, learning rate 4e-5 and GRPO group size 8:
- The first rung of reward was process reliability: converting validation failures and jobs that died on the GPU into completed episodes.
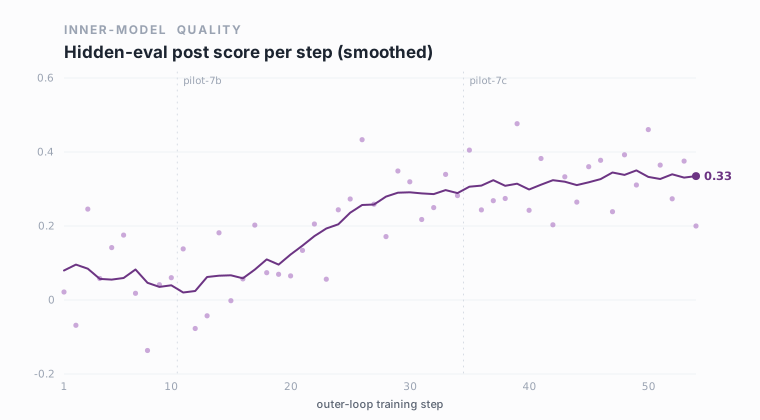
- The second rung was better models: job grade rose from 0.30 to 0.41 and the hidden-eval post-training score went from about 0.04 to a sustained 0.22-0.48.
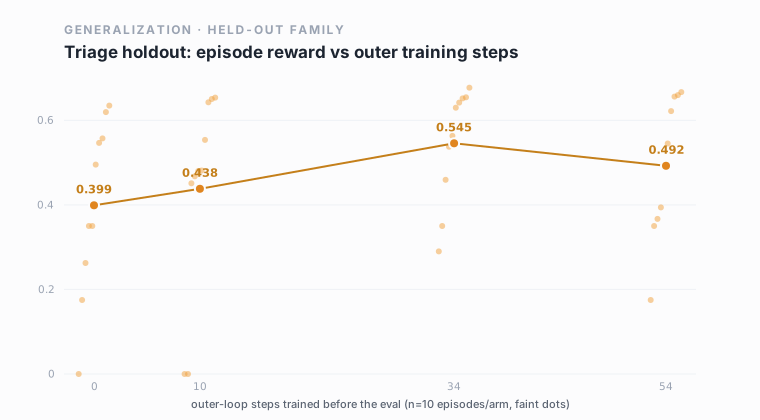
- On the held-out triage family, mean reward went 0.399 at step 0, 0.438 at step 10, 0.545 at step 34 and 0.492 at step 54.
- Early training was model-selection blind, with 77 of 79 episodes choosing the weaker 0.6B model. After
get_baseline_scoresand uplift grading were added, the policy flipped and the 1.7B share of job-writing episodes deepened across the arc from 42% to 95%. Separately, use of the exposed[prime_rl]config surface rose from 21% to about 78% of episodes within one warm-start boundary.
Every episode prints reward, token usage and dollar cost, and writes its trajectory, manifest and the agent's workspace to runs/<run_id>/.
The released model is a LoRA adapter (rank 8, about 560 MB) from the step-34 checkpoint, derived from Qwen3.6-35B-A3B and released under Apache-2.0. Load it with PEFT or serve it with vLLM's LoRA support.
Integrations
Getting started needs a .env with OPENROUTER_API_KEY, plus TINKER_API_KEY for outer RL. Tests run fully offline.
uv sync
uv run pytest
uv run at-episode --task examples/tasks/calc_chain_v1_fast.json --model qwen3.6-27b
With Runpod and Tinker keys, uv run at-worker --max-pods 2 --once drains the job queue on real GPUs, scripts/seed_baselines.py freezes eval baselines (required before RL) and scripts/train_trainer.py smoke=True runs an outer RL smoke test. Do not run baseline seeding while a training run writes the same runs/eval_cache.json.
The stack is Runpod warm pods (up to 16, about 2 minutes from provision to serving, with a file-backed queue moving through queued/, running/ and done/), prime-rl with vLLM for pre and post scoring, and Tinker for the agent's RL. Async off-policy training with max_steps_off_policy=2 stops one slow episode gating a batch. Every LLM call logs tokens and cost to a runs/costs.jsonl ledger enforced against per-episode budgets. The whole headline arc cost about 950 GBP (about 1,275 USD): roughly 605 GBP on Runpod and 345 GBP on Tinker (per-job breakdown in the cost table below).
Infrastructure details. GPU selection is data-driven: a benchmark matrix over GPU and base model found 2x RTX A5000 the cheapest at about 0.10 GBP (about 0.13 USD) per job, and preference ladders are walked at provision time to take whatever is in stock. Across the headline arc of about 1,750 jobs (fewer than the nominal 54 steps times 40 because episodes that fail validation never dispatch a job) the fleet ran mostly on A40 (64 percent, 340 GPU-train-hours) and RTX 4090 (32 percent, 151 hours), with RTX A6000 at 3 percent and RTX A5000 at 1 percent, since the benchmark winner was rarely in stock. Idle pods are reaped, and pods are bootstrap-pinned to exact prime-rl and verifiers revisions so every node is a replica. On the outer loop, Tinker (Thinking Machines' managed RL API) runs the training described above, and a control-inversion bridge runs each episode as a background task behind a queue-backed policy so the harness logic (validation retries, nudges, grading) stays unchanged. With async off-policy training there were zero stale discards across the headline arc. The whole orchestration runs on a CPU box rented from Nebius.
Cost table (loosely measured): one inner training job 0.10-0.15 GBP on short tasks and 0.15-0.22 GBP for long persona-family jobs, one outer-loop episode 0.11-0.19 GBP, one outer-loop batch (all real GPU jobs, see above) 11-17 GBP all-in, a holdout eval arm (n=10) 4-6 GBP. The pilots, GPU benchmarking, baseline seeding and dead ends cost a few hundred GBP more, and benchmark rows on cold pods reached about 0.37 USD per job.
scripts/train_trainer.py defaults: model Qwen/Qwen3.6-35B-A3B, lora_rank 32 (the reported runs used rank 8), learning rate 4e-5, provider (mock by default, runpod for real inner compute), a weights grading preset (smoke by default, or validation or live; a real run uses provider=runpod weights=live max_pods=2), group_size 4, groups_per_batch 8, num_batches 20, pod_idle_timeout_s 600, job_timeout_s two hours (timeouts grade the job 0 without retry, so keep about 2x headroom), max_tokens 8192 and max_trajectory_tokens 49152, save_every 5, and constant-reward groups are dropped because they give zero gradient. smoke=True shrinks the run to the smallest one that exercises sample, reward, forward-backward, checkpoint and resample, with about 1-2 USD of Tinker tokens and mock inner compute. A warm start loads a prior checkpoint and needs a matching lora_rank. scripts/seed_baselines.py serves each base model once with vLLM on its own GPU of a single 2-GPU pod, evaluates every family's hidden eval three times and caches the mean in runs/eval_cache.json, costing about 30-40 minutes of one pod (roughly 0.30-0.50 USD) for the full 2x5 grid. The fast task file calc_chain_v1_fast.json allows the base models Qwen3-0.6B and 1.7B, steps of 10-30 and at least 200 training rows, and its hidden eval uses the harness's own system prompt so the trained model must genuinely call the calculator.
The released adapter is on Hugging Face as Danau5tin/ai-trains-ai-trainer. In the run logs a value of -1.0 is a logging sentinel meaning no post score, not a reward. Task-file bounds in the calc_chain file are learning rate 1e-7 to 5e-4, batch size 4 to 64, group size 4 to 16, sequence length 512 to 4096, rollout turns 4 to 10, LoRA rank 1 to 16 and LoRA alpha 1 to 32. The eval question count is part of the baseline cache key, so fast calibration passes (for example --num-examples 200) land in a separate namespace and cannot pollute the frozen grading baselines.
Source README
🤓 AI Trains AI: Using RL to train an AI agent that trains AI using RL
🔓 Everything is open sourced including: the trained agent's weights (LoRA adapter on 🤗 HF), agent harness, task families, reward code, GPU orchestration, tinker RL training scripts, and retro write-ups of every pilot (including the failures). Jump to Getting started ↓
TL;DR:
- I built a pipeline where an AI agent:
- Leveraging Tinker, I then RL-trained the agent itself, rewarding it when it trained better models.
- Reward climbed from ~0.0 to a ~0.63 peak over 54 training steps. Transferring to a held-out task family it never trained on.

📚 Table of Contents
- 🔁 How it works
- ⚖️ Reward design
- 🧩 Task families
- 📈 Results
- 🖥️ Infrastructure
- 💰 Costs
- 🤗 Model weights
- 🚀 Getting started
- 🔮 Future improvements
- Acknowledgements
🔁 How it works
Two RL loops with two entirely separate training stacks.
| who is being trained | what training looks like | stack | |
|---|---|---|---|
| Outer loop | the trainer agent (Qwen3.6-35B-A3B, LoRA) | episodes of writing training jobs; episode reward is the policy-gradient signal | Tinker + tinker-cookbook (importance-sampling GRPO) |
| Inner loop | a small base model (Qwen3-0.6B / 1.7B) | the job the agent wrote: a verifiers environment + rubric, with a [prime_rl] config table |
prime-rl (GRPO) on Runpod GPUs |
Tinker trains the agent. The agent writes verifiers envs, rubrics, and prime-rl configs. prime-rl trains the small model. The inner model's hidden-eval score flows back up as the outer loop's reward.
The episode
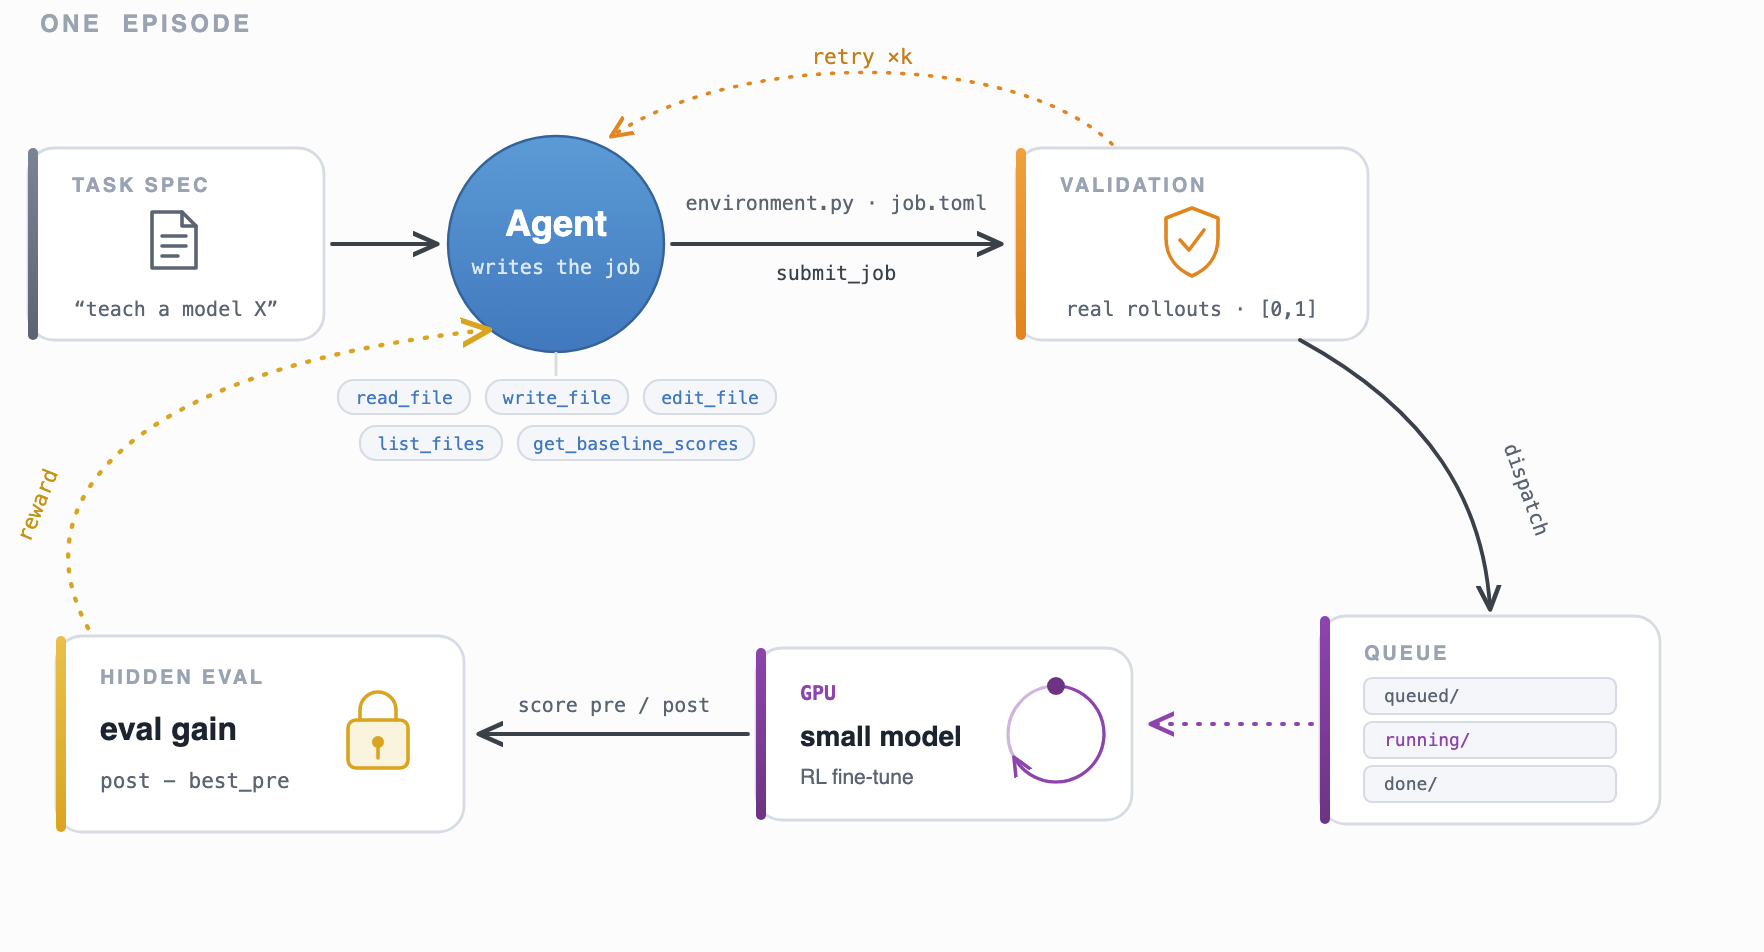
One episode = one attempt by the trainer agent to produce a valid, high-quality training job for a given task:
- Task spec - a description of what to train ("teach a small model to resolve multi-hop persona queries"), hard constraint bounds, the eval tool interface, and a handful of dev examples.
- The agent works - it edits a sandboxed workspace through
read_file/write_file/edit_file/list_files, and can callget_baseline_scoresto see the untrained base models' scores on the hidden eval. submit_job- triggers a validation probe. Any failures are returned and the agent gets capped retries.- Dispatch - a validated job is queued and picked up by a warm pool of Runpod GPU pods, which run GRPO training with prime-rl and score the checkpoint pre/post on the hidden eval.
- Reward - combines validation efficiency with the trained model's uplift over the best untrained baseline.
The outer loop then RL-trains the agent itself on episode reward, using Tinker. Every outer-loop batch spawns 40 real inner training jobs across up to 16 GPU pods.
⚖️ Reward design
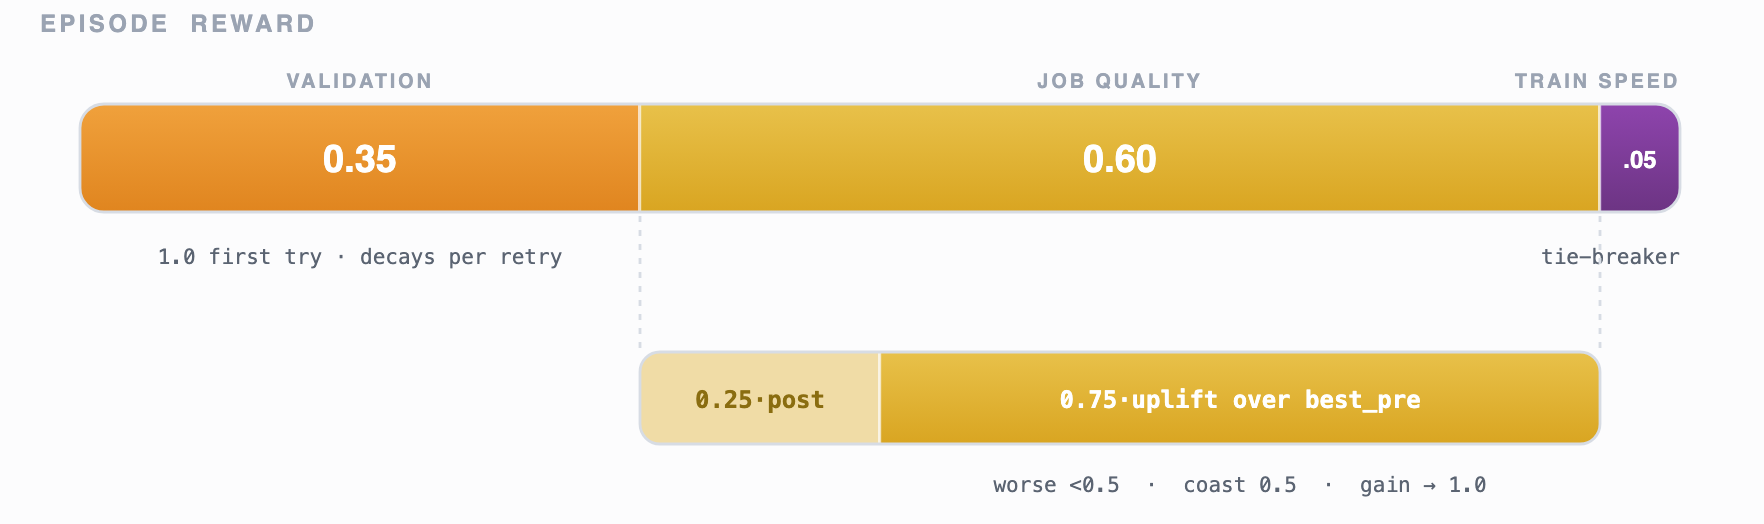
Episode reward is a weighted sum (live weights 0.35 / 0.60 / 0.05):
- Validation - 1.0 for a first-try valid submission, decaying per extra attempt; 0 if the episode never validates. (Separately, the outer loop scores an episode −0.1 when the agent never produces a parseable submission at all. The −1.0 values you'll see in the CSVs are a "no post score" logging sentinel, not a reward.)
- Job quality - a hybrid of the trained model's absolute post-training score and its signed uplift over
best_pre, the best untrained model's frozen baseline:0.25·post + 0.75·uplift_term. A job that dies on the GPU scores 0 here (the episode keeps its validation term). - Train speed - a small tie-breaker for faster jobs, gated on job success.
Note for close readers: the agent-facing prompt (template/INSTRUCTIONS.md) gives the agent a simplified view - the 75/25 uplift/absolute split inside job quality, plus a fewer-attempts nudge - not the full 0.35/0.60/0.05 decomposition. The published adapter was trained against that prompt; the reward actually computed is the one above.
🧩 Task families
Six families of tasks, deliberately built so that the untrained models struggled without training, and all require multi-step tool use and reasoning:
| family | shape | untrained best_pre (n=200) |
|---|---|---|
| calc_chain | chained arithmetic where each step feeds the next | 0.742 |
| multi_hop | persona-world queries needing multiple dependent lookups | 0.654 |
| string_pipeline | composed string transformations | 0.545 |
| ledger | stateful account bookkeeping via tools | 0.242 |
| dispatch | conditional routing decisions | 0.323 |
| triage (held out) | on-call incident triage: correlating services, incidents and deploys across tools | 0.352 |
Five families train the agent; triage is never trained on and serves as the generalisation probe.
📈 Results
Setup: Qwen3.6-35B-A3B trainer agent, LoRA rank 8, lr 4e-5, GRPO with group size 8, up to 16 concurrent GPU pods, ~40 real training jobs per batch. Runs: pilot-7 (10 steps) → 7b (24 steps, warm-started) → 7c (20 steps, warm-started) - 54 steps total.
1. The reward climbed in two distinct rungs
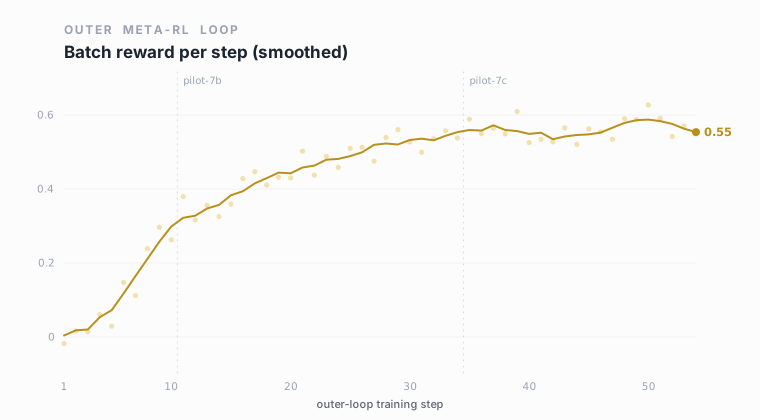
Decomposing the reward shows what was learned, and in what order:
- Rung 1 - process reliability (pilot-7). The entire early gain came from converting validation failures and dead-on-GPU jobs into completed episodes. Job quality stayed flat while total reward rose to ~0.26. Showing GRPO taking the steepest gradient first.
- Rung 2 - making better models (pilot-7b onward). With reliability saturating (~0.75-0.80 validation), job grade rose 0.30 → 0.41 and the hidden-eval post-training score went from ~0.04 noise to a sustained 0.22-0.48. The agent started making better models, not just working ones.
2. The skill transfers to a held-out task family
A task family which the agent never trained on showed performance rises with outer-loop training, then plateaus:
| checkpoint | outer steps | mean reward | validated | inner jobs succeeded | worst episode |
|---|---|---|---|---|---|
| base model | 0 | 0.399 | 9/10 | 5/9 | 0.000 |
| pilot-7 final | 10 | 0.438 | 8/10 | 8/8 | 0.000 |
| pilot-7b final | 34 | 0.545 | 10/10 | 9/10 | 0.290 |
| pilot-7c final | 54 | 0.492 | 10/10 | 8/10 | 0.175 |
3. The agent learned to pick the better base model & better hyperparams
Early training runs were model-selection blind: 77/79 episodes chose the weaker 0.6B model. After introducing the get_baseline_scores tool and uplift grading, the policy flipped and remained so during training, deepening across the arc: 1.7B share of job-writing episodes went 42% → 95%. It also adopted the exposed [prime_rl] config surface (21% → ~78% of episodes within one warm-start boundary), with a sensible key mix: sampling temperature, optimizer choice, algorithm variant, scheduler, loss.
🖥️ Infrastructure
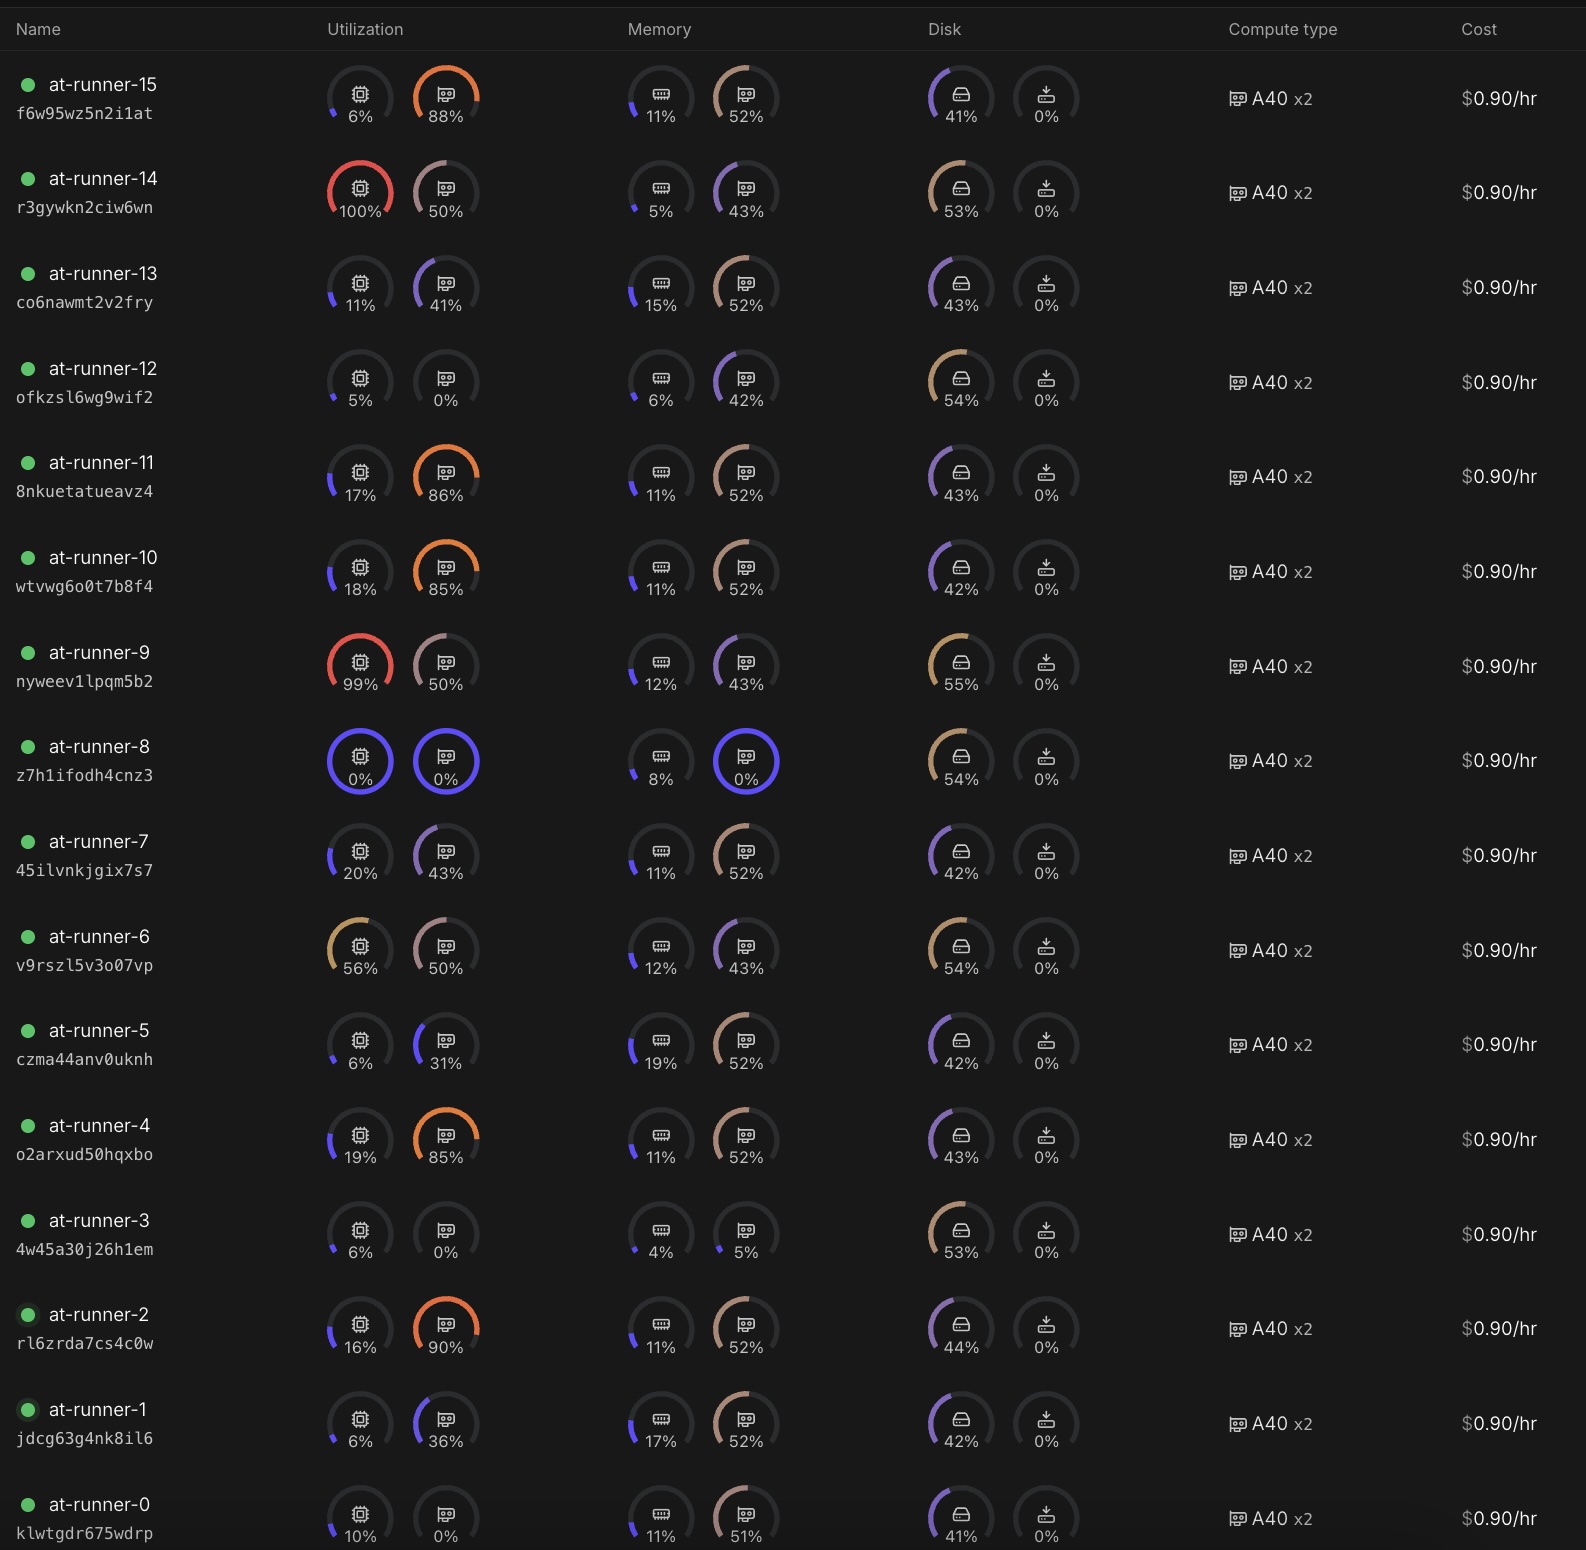
16x warm GPU pods training at any one time:
Inner loop (the jobs the agent writes):
- Runpod warm-pod fleet - a capped pool (up to 16) of pods, bootstrap-pinned to exact prime-rl + verifiers revisions so every node is a replica; ~2 min from provision to serving. Idle pods are reaped; the queue is file-backed (
queued/ → running/ → done/). - GPU selection is data-driven - a benchmark matrix over GPU × base-model found 2× RTX A5000 wins cost at £0.10/job (~$0.13); preference ladders are walked at provision time to take whatever's in stock.
- What the fleet actually ran on (headline arc, ~1,750 jobs - below the nominal 54 steps × 40 because episodes that fail validation never dispatch a job): A40 64% (340 GPU-train-hours) · RTX 4090 32% (151h) · RTX A6000 3% · RTX A5000 1%. The benchmark cost-winner was rarely in stock, so the ladder spent most of the arc on A40s.
- prime-rl (GRPO) trains the small model; checkpoints are scored pre/post on the hidden eval with vLLM.
Outer loop (training the agent):
- Tinker (Thinking Machines' managed RL API) trains Qwen3.6-35B-A3B with LoRA via tinker-cookbook's importance-sampling GRPO. A control-inversion bridge runs each episode as a background task behind a queue-backed policy, so the cookbook loop drives episodes turn-by-turn while all harness logic (validation retries, nudges, grading) stays unchanged.
- Async off-policy (
max_steps_off_policy=2) defeats the straggler barrier - one slow episode no longer gates a whole batch. Zero stale discards across the headline arc. - Everything is metered. Every LLM call logs tokens and USD;
runs/costs.jsonlis a global spend ledger enforced against per-episode budgets.
The whole orchestration runs on a CPU box, rented via Nebius.
💰 Costs
| item | (loosely) measured cost |
|---|---|
| one inner training job (train + pre/post eval) | ~£0.10-0.15 (~$0.13-0.20) benchmarked on short tasks; ~£0.15-0.22 (~$0.20-0.30) for the long persona-family jobs |
| one outer-loop episode (agent tokens, Tinker) | ~£0.11-0.19 (~$0.15-0.25) |
| one outer-loop batch (40 real GPU jobs + agent tokens) | ~£11-17 (~$15-23) all-in |
| holdout eval arm (n=10) | ~£4-6 (~$5-8) |
| Runpod, billed across the arc window | ~£605 (~$810) - includes some concurrent baseline-seeding and GPU-benchmark pods |
| Tinker across the arc (invoiced - all agent sampling & training, incl. the holdout-eval episodes) | ~£345 (~$465) |
| whole headline arc | ~£950 (~$1,275) all-in (~£605 Runpod, ~£345 Tinker) |
Honesty footnote: ~£950 is the headline arc, not the project - the pilots, GPU benchmarking, baseline seeding, and blind alleys that got here (written up in the docs/ retros) cost a few hundred more on top. Benchmark-matrix rows on cold pods ran as high as ~$0.37/job (see benchmarks/REPORT.md); the per-job range above is warm-pool arc jobs. GBP figures at £0.745/$1 (10 Jul 2026).
🤗 Model weights
The trained trainer agent is on Hugging Face: Danau5tin/ai-trains-ai-trainer.
It's the LoRA adapter (rank 8, ~560MB) from the step-34 checkpoint - the held-out transfer peak in the table above - derived from Qwen/Qwen3.6-35B-A3B and released under Apache-2.0 to match the base model. Load it with PEFT or serve it with vLLM's LoRA support; to run full episodes, drive it through this harness. The model card has usage snippets and honesty notes.
🚀 Getting started
If you'd like to reproduce, or extend. The below will get you there!
# .env at repo root with OPENROUTER_API_KEY=... (and TINKER_API_KEY for outer RL)
uv sync
uv run pytest                                        # fully offline: no network, no keys
uv run at-episode --task examples/tasks/calc_chain_v1_fast.json --model qwen3.6-27b   # run one episode with a frontier agent
Each episode prints reward, token usage, and dollar cost, and writes full artifacts (trajectory, manifest, the agent's workspace) to runs/<run_id>/.
With Runpod + Tinker keys:
uv run at-worker --max-pods 2 --once                 # drain the job queue on real GPUs
uv run python scripts/seed_baselines.py              # freeze eval baselines (required before RL)
uv run python scripts/train_trainer.py smoke=True    # outer RL smoke test
Deeper guides: docs/architecture.md (components and contracts), docs/outer-rl-tinker.md (full RL runbook), docs/gpu-runner-spec.md (compute-provider contract), and the retro series in docs/ - every pilot, including the failures, is written up (pilots 4-5 live inside the eval-integrity retro rather than standalone files).
⚠️ Trust model: agent-written code executes in a timeout-guarded subprocess on the host, not a container. Fine for frontier APIs and your own checkpoints on a template contract; containerise the probe before running untrusted or heavily-RL'd policies.
🔮 Future improvements
- 🔄 Iterative experimentation - today the agent submits one job per episode; the natural next rung is letting it read results and submit follow-up experiments, and / or allowing multiple experiments to be dispatched at the same time, i.e. grading multi-job research taste rather than one-shot job quality.
- 🧠 Richer tasks - only stateless tool-calling envs are exposed today; opening verifiers' other env types would let the trainer agent train stateful coding agents.
examples/tasks/calc_chain_v1_fast.json
{
  "id": "calc-chain-v3-fast",
  "family": "calc_chain",
  "title": "Train a chained-arithmetic calculator agent (fixed small budget)",
  "description": "## Task: train a chained-arithmetic calculator agent\n\nDesign a training job that teaches a small model to solve multi-step arithmetic\nchains by composing `calculator` tool calls. Each question describes 3-6\n**dependent** steps — every step operates on the previous result — and **at\nleast one step is a conditional that branches on the running total** (deeper\nchains sometimes carry two), e.g. \"Start with 4741 * 862. Subtract 12409. If\nthe running total is even, divide it by 2; otherwise, subtract 4187. What is\nthe final result?\". Conditions are parity (\"even\") or divisibility by a small\nnumber (3-13). Operands are 3-6 digits, so the model **must use the\ncalculator** — and because of the conditional steps it must work STEP BY STEP:\ncompute the running total, inspect the ACTUAL intermediate value, decide which\nbranch is true, and apply only that branch's operation. A single composed\nexpression cannot encode the branch, and each condition is true ~50% of the\ntime, so always assuming one branch fails half the questions. The target\ninteraction pattern is:\n\n1. system message (you choose it — it must instruct the model to always use the tool)\n2. user message with a chained question\n3. one or more assistant messages calling `calculator` — one call per step,\n   feeding the previous result forward; at a conditional step, check the\n   condition against the real running total and apply the matching branch —\n   each followed by a tool result message\n4. assistant message with only the final number\n\n### How you are graded\n\nAfter training, the model is evaluated on a **hidden, held-out question set** in a\nharness-owned environment you cannot see or modify. You are shown its tool\ninterface and a few dev examples from the same distribution. Your job is to design\ntraining (data, reward, hyperparameters) that transfers to that hidden eval.\n\n**Scoring (disclosed):** each hidden-eval rollout is scored\n`0.8 * correct_answer + 0.2 * used_calculator`. `correct_answer` is exact-match on\nthe final value at the END of the model's last reply; `used_calculator` is 1.0 iff\nthe model makes at least one structured `calculator` tool call during the rollout.\nA model that answers correctly but never calls the tool caps at **0.8** — the\nremaining 0.2 is reachable only through genuine tool calls. The eval runs under\nthe harness's own system prompt (not yours), which instructs the model to\nalways use the tool; your trained model must actually do it.\n\n### Requirements\n\n- Build a `verifiers` ToolEnv exposing exactly one tool matching the eval tool\n  interface: `calculator(expression: str) -> str` — it evaluates +, -, *, / and\n  parentheses and returns the number as a string, or an **error string** on bad\n  input (never crash). **Tool name and parameter name must match the interface\n  exactly.**\n- Generate training data with a **seeded RNG**: chains of 3-6 dependent steps,\n  every question containing at least one conditional step that branches on the\n  running total (parity or divisibility by a small number). Construct chains by\n  EXECUTING them in Python so the generator always knows which branch is live —\n  e.g. nudge the operand of the step feeding a conditional so the intended\n  condition really holds — and balance branch-taken ~50/50 so the model cannot\n  learn \"always take the first branch\". Keep the LIVE path exact: divisions on\n  the live branch and on the straight-line path must land on integers (e.g.\n  choose dividend = divisor * quotient), so every honest intermediate and the\n  final value is an integer; derive the gold answer by executing the chain,\n  never by hand. Rows are dicts with string fields `question` and `answer`.\n  Generate **train data only**.\n- The rubric must produce a reward in [0.0, 1.0] per rollout, rewarding both the\n  correct final number (exact-match) and use of the calculator tool. A correct\n  answer without a tool call should score lower than one that used the tool.\n- Choose GRPO hyperparameters (job.toml) within the given bounds. Chains need\n  several rollout turns — pick rollout max_turns near the top of the allowed\n  range so multi-call solutions are not cut off.\n\n\n### Budget note\n\nThis variant runs under a tight, fixed training budget: max_steps is capped low. Design your data and reward for the biggest improvement per step — you cannot brute-force with a long run.",
  "constraints": {
    "allowed_base_models": [
      "Qwen/Qwen3-0.6B",
      "Qwen/Qwen3-1.7B"
    ],
    "learning_rate": {
      "lo": 1e-07,
      "hi": 0.0005
    },
    "max_steps": {
      "lo": 10,
      "hi": 30
    },
    "batch_size": {
      "lo": 4.0,
      "hi": 64.0
    },
    "group_size": {
      "lo": 4.0,
      "hi": 16.0
    },
    "max_seq_len": {
      "lo": 512.0,
      "hi": 4096.0
    },
    "rollout_max_turns": {
      "lo": 4.0,
      "hi": 10.0
    },
    "lora_rank": {
      "lo": 1.0,
      "hi": 16.0
    },
    "lora_alpha": {
      "lo": 1.0,
      "hi": 32.0
    },
    "min_train_rows": 200
  },
  "eval_env_module": "autonomous_trainer.tasks.eval_envs.calc_chain_eval",
  "tool_interface": {
    "name": "calculator",
    "required_params": [
      "expression"
    ],
    "signature_doc": "calculator(expression: str) -> str — e.g. calculator(expression=\"12 * (3 + 4)\") returns \"84\", or an error string for a bad expression"
  },
  "dev_examples": [
    {
      "question": "Begin with 225455 - 422932. Check the running total: if it is divisible by 7, divide it by 7; if it is not, multiply it by 529. Subtract 705228. What is the final result?",
      "answer": "-733439"
    },
    {
      "question": "First compute 600879 - 780142. When the running total is divisible by 7, multiply it by 30; when it is not, add 291260. Multiply the result by 43. Then add 770869 to the result. What is the final value?",
      "answer": "-230478401"
    },
    {
      "question": "Start with 14608 * 6374. Subtract 263099. If the running total is even, subtract 435354; otherwise, add 983876. Then add 86569 to the result. Add 314484. Now, if the total is divisible by 9, add 954644; if it is not, add 594203. What is the final value?",
      "answer": "95187866"
    },
    {
      "question": "First compute 187681 * 5941. Add 767267. Then add 126891 to the result. Now, if the total is divisible by 3, add 114059; if it is not, subtract 515266. Give the final value.",
      "answer": "1116021038"
    },
    {
      "question": "Take 741839 - 68909 as the starting value. Should the running total be divisible by 3, divide it by 3; else subtract 248952. Next, subtract 197418. Then divide by 18. Give the final value.",
      "answer": "1494"
    },
    {
      "question": "Start with 999383 + 736842. When the running total is even, divide it by 2; when it is not, subtract 286600. Next, subtract 314859. Next, add 70142. Then subtract 560869 from the result. If the running total is divisible by 11, divide it by 11; otherwise, subtract 987932. What is the final value?",
      "answer": "58549"
    },
    {
      "question": "Let the running total be 731484 + 356925. Then subtract 541509 from the result. Subtract 240337. If the running total is even, divide it by 2; otherwise, subtract 785313. What number do you end up with?",
      "answer": "-478750"
    },
    {
      "question": "First compute 774396 + 307795. Check the running total: if it is divisible by 11, divide it by 11; if it is not, add 115759. Next, add 34611. Then subtract 151049 from the result. If the running total is divisible by 13, multiply it by 14; otherwise, multiply it by 687. Then add 201196 to the result. What number do you end up with?",
      "answer": "-51602"
    },
    {
      "question": "Take 482607 - 808647 as the starting value. When the running total is divisible by 11, multiply it by 478; when it is not, subtract 489309. Then subtract 698537 from the result. Then add 272308 to the result. What is the final result?",
      "answer": "-156273349"
    },
    {
      "question": "First compute 964237 - 553197. Check the running total: if it is divisible by 13, add 895283; if it is not, add 23584. Then subtract 922961 from the result. Subtract 316726. Next, if the current total is divisible by 3, add 251508, and if it is not, add 255584. What number do you end up with?",
      "answer": "-549479"
    }
  ],
  "train_time_budget_s": 1800.0
}
scripts/seed_baselines.py
"""Seed the baseline eval cache for every (base model x task family) pair.

Fills runs/eval_cache.json with pre-training scores so the agent's
get_baseline_scores tool is informed from episode one, instead of waiting for
the cache to fill organically as jobs run. One pod is provisioned; each base
model is served once with vLLM and evaluated against every family's hidden
eval env; the pod is torn down at the end.

    uv run python scripts/seed_baselines.py                 # all task JSONs + registry
    uv run python scripts/seed_baselines.py --families lookup,string_op

Do NOT run while a training run is writing the same runs/eval_cache.json.
Cost: ~30-40 min of one 2-GPU pod (~$0.30-0.50) for the full 2x5 grid.
"""

from __future__ import annotations

import argparse
import asyncio
import importlib
import json
import tempfile
import time
from pathlib import Path

import verifiers

from autonomous_trainer.base_models import base_model_info
from autonomous_trainer.jobs.eval_cache import EVAL_NUM_EXAMPLES, EvalCache, cache_key
from autonomous_trainer.jobs.runpod import RunpodComputeProvider, RunpodError
from autonomous_trainer.settings import PROJECT_ROOT, get_settings
from autonomous_trainer.tasks import load_task

RUNNER_DIR = PROJECT_ROOT / "runner"
REMOTE_DIR = "/opt/at/baseline_seed"
PRIME = "cd /opt/at/prime-rl && /root/.local/bin/uv run --no-sync"
# Eval rollouts are stochastic (temperature sampling); the baseline is graded
# against for entire training runs, so measure it as a mean over repeats.
EVAL_REPEATS = 3


def discover_pairs(families: list[str] | None) -> dict[str, set[str]]:
    """base_model -> set of eval_env_modules, from the task JSONs."""
    tasks_dir = PROJECT_ROOT / "examples" / "tasks"
    pairs: dict[str, set[str]] = {}
    for path in sorted(tasks_dir.glob("*.json")):
        task = load_task(str(path))
        family = task.eval_env_module.rsplit(".", 1)[-1].removesuffix("_eval")
        if families and family not in families:
            continue
        for model in task.constraints.allowed_base_models:
            pairs.setdefault(model, set()).add(task.eval_env_module)
    return pairs


async def seed(
    families: list[str] | None,
    gpu_types: list[str] | None = None,
    num_examples: int = EVAL_NUM_EXAMPLES,
    max_concurrent: int = 128,
) -> None:
    settings = get_settings()
    cache = EvalCache(settings.runs_dir / "eval_cache.json")
    pairs = discover_pairs(families)

    todo: dict[str, list[str]] = {}
    for model, envs in pairs.items():
        missing = [
            env for env in sorted(envs)
            if cache.get(cache_key(model, env, verifiers.__version__, num_examples)) is None
        ]
        if missing:
            todo[model] = missing
    if not todo:
        print("nothing to seed — cache already covers every pair")
        return
    for model, envs in todo.items():
        print(f"to measure: {model} x {[e.rsplit('.', 1)[-1] for e in envs]}")

    # One pod for the whole grid. All supported base models run on the same
    # pod class; use the ladder of the largest model present (registry order:
    # later-declared models are larger, so take the last one's ladder).
    largest = sorted(todo)[-1]
    provider = RunpodComputeProvider(pod_name="at-seed", keep_warm=False)
    pod_id, target = None, None
    try:
        provider.gpu_type_ids = list(gpu_types) if gpu_types else list(
            base_model_info(largest).gpu_ladder
        )
        # Machines vary: slow-network pods fail bootstrap fast (pre-flight gate)
        # — reroll onto a different machine instead of dying.
        last_err: Exception | None = None
        for attempt in range(3):
            try:
                pod_id, target = await provider.ensure_warm_pod()
                break
            except Exception as e:
                last_err = e
                print(f"[seed] provision attempt {attempt + 1} failed: {str(e)[-300:]}")
                for pod in await provider.client.list_pods():
                    if pod.get("name") == "at-seed":
                        await provider.client.delete_pod(pod["id"])
                        print(f"[seed] retired pod {pod['id']}")
        else:
            raise RunpodError(f"no usable pod after 3 attempts: {last_err}")
        await provider._ssh(target, f"mkdir -p {REMOTE_DIR}")
        await provider._scp(target, RUNNER_DIR / "eval_model.py", f"{REMOTE_DIR}/eval_model.py")

        # One model per GPU, both grids in parallel (pods are 2-GPU). No
        # between-model pkill needed: the pod is single-use and deleted below.
        assert len(todo) <= 2, "parallel seeding assumes <=2 models (one per GPU)"

        # Push each env file once up front — the per-model tasks would otherwise
        # race concurrent scps of the same target path.
        for env_module in sorted({e for envs in todo.values() for e in envs}):
            mod = importlib.import_module(env_module)
            if not mod.__file__:
                raise RuntimeError(f"eval env module {env_module} has no file path")
            env_name = env_module.rsplit(".", 1)[-1]
            with tempfile.TemporaryDirectory() as td:
                local = Path(td) / f"{env_name}.py"
                local.write_text(Path(mod.__file__).read_text())
                await provider._scp(target, local, f"{REMOTE_DIR}/{env_name}.py")

        async def start_server(model: str, gpu_idx: int) -> int:
            # 8100+: the pod image's own nginx squats parts of the 8000 range
            # (observed: :8001 answering 405s to eval traffic).
            port = 8100 + gpu_idx
            parser = base_model_info(model).tool_call_parser
            print(f"[seed] serving {model} on GPU {gpu_idx} :{port} (parser: {parser})")
            # NB: the env var must directly prefix the uv command — PRIME
            # starts with `cd ... &&`, and `VAR=x cd dir && cmd` binds the var
            # to the cd builtin only. Both models silently landed on GPU 0
            # (0.6B took 90%, 1.7B found 4.4GiB and died) until this bit.
            await provider._ssh(
                target,
                f"nohup bash -c 'export CUDA_VISIBLE_DEVICES={gpu_idx}; {PRIME} vllm serve {model} "
                f"--port {port} "
                f"--gpu-memory-utilization 0.9 --enable-auto-tool-choice "
                f"--tool-call-parser {parser} --enable-prefix-caching' "
                f"> {REMOTE_DIR}/serve.{gpu_idx}.log 2>&1 "
                f"< /dev/null & echo started",
                timeout=60,
            )
            try:
                await _wait_health(provider, target, port)
            except TimeoutError:
                # The pod is deleted on failure — capture the post-mortem now.
                tail = await provider._ssh(
                    target, f"tail -c 1200 {REMOTE_DIR}/serve.{gpu_idx}.log", timeout=20
                )
                raise TimeoutError(
                    f"vLLM for {model} never became healthy; serve log tail:\n{tail}"
                )
            return port

        async def run_model(model: str, envs: list[str], port: int) -> None:
            # Two families in flight per server: measured GPU util is 20-40%
            # at one (client orchestration gaps) — a second grid fills them
            # without starving either. Repeats within a family stay sequential
            # (they're independent draws either way).
            family_sem = asyncio.Semaphore(2)

            async def run_family(env_module: str) -> None:
                async with family_sem:
                    scores = [
                        await _eval_env(
                            provider, target, model, env_module, port,
                            num_examples, max_concurrent,
                        )
                        for _ in range(EVAL_REPEATS)
                    ]
                    mean = sum(scores) / len(scores)
                    cache.put(
                        cache_key(model, env_module, verifiers.__version__, num_examples),
                        round(mean, 4),
                    )
                    print(
                        f"[seed] {model} x {env_module.rsplit('.', 1)[-1]}: "
                        f"{mean:.3f} (mean of {[round(s, 3) for s in scores]}, cached)"
                    )

            await asyncio.gather(*(run_family(env) for env in envs))

        # Serialize STARTUP (concurrent cold vLLM inits in the same project
        # dir kill each other: engine-core init failure / health timeouts,
        # seen on both GPUs), then run the eval grids in parallel — that's
        # where the wall-clock actually is.
        ports = {}
        for gpu_idx, model in enumerate(sorted(todo)):
            ports[model] = await start_server(model, gpu_idx)
        await asyncio.gather(
            *(run_model(m, envs, ports[m]) for m, envs in sorted(todo.items()))
        )
    finally:
        if pod_id:
            await provider.client.delete_pod(pod_id)
            print(f"[seed] pod {pod_id} deleted")
        else:
            # ensure_warm_pod can raise after creating the pod but before
            # returning its id (e.g. bootstrap timeout) — sweep by name so a
            # failed provision never leaks a billing pod.
            for pod in await provider.client.list_pods():
                if pod.get("name") == "at-seed":
                    await provider.client.delete_pod(pod["id"])
                    print(f"[seed] swept leaked pod {pod['id']}")


async def _wait_health(
    provider: RunpodComputeProvider, target, port: int, timeout_s: float = 1200
) -> None:

    deadline = time.time() + timeout_s
    while time.time() < deadline:
        try:
            out = await provider._ssh(
                target, f"curl -sf http://localhost:{port}/health && echo OK", timeout=20
            )
            if "OK" in out:
                return
        except Exception:
            pass
        await asyncio.sleep(10)
    raise TimeoutError("vLLM server never became healthy")


async def _eval_env(
    provider,
    target,
    model: str,
    env_module: str,
    port: int,
    num_examples: int,
    max_concurrent: int = 128,
) -> float:
    env_name = env_module.rsplit(".", 1)[-1]
    # Env files are pushed once by seed() before the parallel grids start.
    # Namespace outputs by port: both models eval the same envs concurrently.
    out_path = f"{REMOTE_DIR}/{env_name}.{port}.result.json"
    await provider._ssh(
        target,
        f"{PRIME} python {REMOTE_DIR}/eval_model.py "
        f"--eval-env {REMOTE_DIR}/{env_name}.py "
        f"--base-url http://localhost:{port}/v1 --model {model} "
        f"--num-examples {num_examples} --max-concurrent {max_concurrent} "
        f"--out {out_path}",
        timeout=1800,
    )
    report = json.loads(await provider._ssh(target, f"cat {out_path}", timeout=30))
    if report["n_errors"] > 0.05 * report["n_rollouts"]:
        raise RuntimeError(f"{model} x {env_name}: {report['n_errors']} rollout errors")
    return float(report["mean_reward"])


def main() -> None:
    parser = argparse.ArgumentParser(description=__doc__)
    parser.add_argument("--families", default=None, help="comma-separated family filter")
    parser.add_argument(
        "--gpu-types",
        default=None,
        help="comma-separated Runpod gpuTypeIds to use instead of the model "
        'ladder, e.g. "NVIDIA H100 80GB HBM3,NVIDIA H100 PCIe"',
    )
    parser.add_argument(
        "--num-examples",
        type=int,
        default=EVAL_NUM_EXAMPLES,
        help="eval question count. The count is part of the cache key, so "
        "fast calibration passes (e.g. 200) land in a separate namespace and "
        "can never pollute the frozen grading baselines (which must stay at "
        f"the grading default, {EVAL_NUM_EXAMPLES}).",
    )
    parser.add_argument(
        "--max-concurrent",
        type=int,
        default=128,
        help="eval client concurrency; 256 saturates H100-class serving",
    )
    args = parser.parse_args()
    families = [f.strip() for f in args.families.split(",")] if args.families else None
    gpu_types = [g.strip() for g in args.gpu_types.split(",")] if args.gpu_types else None
    asyncio.run(seed(families, gpu_types, args.num_examples, args.max_concurrent))


if __name__ == "__main__":
    main()
scripts/train_trainer.py
"""Outer-loop RL: train the trainer agent itself on Tinker.

The trainer model (Qwen3.6-35B-A3B, LoRA) plays full harness episodes — builds
training jobs, gets validated, dispatches to compute, is graded — and its
episode rewards drive importance-sampling policy gradient with GRPO-style
group centering via tinker-cookbook's RL loop.

Smoke test (mock inner compute, 2 tiny batches, ~$1-2 of Tinker tokens):
    uv run python scripts/train_trainer.py smoke=True

Real run against Runpod inner compute:
    uv run python scripts/train_trainer.py provider=runpod weights=live max_pods=2
"""

from __future__ import annotations

import asyncio
import os
from datetime import datetime
from pathlib import Path

import chz
from dotenv import load_dotenv
from tinker_cookbook import cli_utils, model_info
from tinker_cookbook.rl import train

from autonomous_trainer.tinker_rl.dataset import WEIGHT_PRESETS, EpisodeDatasetBuilder

REPO_ROOT = Path(__file__).resolve().parent.parent


@chz.chz
class CLIConfig:
    model_name: str = "Qwen/Qwen3.6-35B-A3B"
    renderer_name: str | None = None  # default: recommended for model (qwen3_5)
    lora_rank: int = 32
    learning_rate: float = 4e-5
    # Warm-start from a prior run's checkpoint (tinker://.../weights/... state
    # path). lora_rank must match the checkpoint's.
    load_checkpoint_path: str | None = None

    # Episode/task parameters
    task_refs: str = str(REPO_ROOT / "examples/tasks/archive/calculator_v1_fast.json")
    provider: str = "mock"  # inner-loop compute: "mock" | "runpod"
    max_pods: int = 1
    weights: str = "smoke"  # grading preset: "validation" | "smoke" | "live"

    # Batch shape
    group_size: int = 4  # episodes per task per GRPO group
    groups_per_batch: int = 8
    num_batches: int = 20
    max_steps: int | None = None
    # Async off-policy training: sampling and training run concurrently, so a
    # straggler episode never gates the whole batch (importance sampling
    # corrects staleness up to this many steps; groups staler than that are
    # dropped). None = fully synchronous. 2 is a sane starting value.
    max_steps_off_policy: int | None = None
    # Tear down inner-loop pods idle longer than this (they bill while warm);
    # re-provision is ~2.5 min. None/0 = keep warm until the run ends.
    pod_idle_timeout_s: float = 600.0
    # Wall-clock cap on each inner job's on-pod train+eval. Timeouts grade
    # job=0 without retry, so keep ~2x headroom over the honest job ceiling.
    job_timeout_s: float = 2 * 3600.0

    # Token budgets
    max_tokens: int = 8192  # per-generation cap (thinking + tool call)
    max_trajectory_tokens: int = 49152  # full-conversation cap (64K context model)

    # Cadence and logging
    eval_every: int = 0
    save_every: int = 5
    log_path: str | None = None
    wandb_project: str | None = None
    wandb_name: str | None = None
    behavior_if_log_dir_exists: cli_utils.LogdirBehavior = "ask"

    # Smoke preset: overrides batch shape to the smallest run that exercises
    # sample -> reward -> forward_backward -> new checkpoint -> resample.
    smoke: bool = False


async def cli_main(cli_config: CLIConfig) -> None:
    load_dotenv(REPO_ROOT / ".env")  # TINKER_API_KEY, WANDB_API_KEY

    c = cli_config
    # Log to wandb by default whenever a key is configured; wandb_project=None
    # (no key) degrades to local jsonl/logtree logging only.
    if c.wandb_project is None and os.environ.get("WANDB_API_KEY"):
        c = chz.replace(c, wandb_project="autonomous-trainer-outer")
    if c.smoke:
        c = chz.replace(
            c,
            group_size=2,
            groups_per_batch=2,
            num_batches=2,
            max_steps=2,
            save_every=1,
            provider="mock",
        )

    if c.weights not in WEIGHT_PRESETS:
        raise ValueError(f"weights must be one of {sorted(WEIGHT_PRESETS)}")

    renderer_name = c.renderer_name or model_info.get_recommended_renderer_name(c.model_name)

    dataset_builder = EpisodeDatasetBuilder(
        model_name=c.model_name,
        renderer_name=renderer_name,
        task_refs=c.task_refs,
        groups_per_batch=c.groups_per_batch,
        group_size=c.group_size,
        num_batches=c.num_batches,
        provider=c.provider,
        max_pods=c.max_pods,
        pod_idle_timeout_s=c.pod_idle_timeout_s,
        job_timeout_s=c.job_timeout_s,
        weights=c.weights,
        max_trajectory_tokens=c.max_trajectory_tokens,
        max_generation_tokens=c.max_tokens,
    )

    stamp = datetime.now().strftime("%Y%m%d-%H%M")
    run_name = (
        f"{'smoke' if cli_config.smoke else 'rl'}-{c.model_name.split('/')[-1].lower()}"
        f"-g{c.group_size}x{c.groups_per_batch}-lr{c.learning_rate}-{stamp}"
    )
    log_path = c.log_path or str(REPO_ROOT / "runs" / "tinker" / run_name)
    cli_utils.check_log_dir(log_path, behavior_if_exists=c.behavior_if_log_dir_exists)

    async_config = None
    if c.max_steps_off_policy is not None:
        async_config = train.AsyncConfig(
            max_steps_off_policy=c.max_steps_off_policy,
            groups_per_batch=c.groups_per_batch,
        )

    config = train.Config(
        learning_rate=c.learning_rate,
        dataset_builder=dataset_builder,
        async_config=async_config,
        model_name=c.model_name,
        load_checkpoint_path=c.load_checkpoint_path,
        recipe_name="autonomous_trainer_outer_rl",
        max_tokens=c.max_tokens,
        log_path=log_path,
        renderer_name=renderer_name,
        lora_rank=c.lora_rank,
        eval_every=c.eval_every,
        save_every=c.save_every,
        max_steps=c.max_steps,
        # All-valid groups on easy tasks are reward-constant -> zero gradient;
        # drop them rather than training on noise.
        remove_constant_reward_groups=True,
        wandb_project=c.wandb_project,
        wandb_name=c.wandb_name or run_name,
    )
    try:
        await train.main(config)
    finally:
        # Tear down any warm Runpod pods the inner loop provisioned.
        from autonomous_trainer.tinker_rl.dataset import ACTIVE_PROVIDERS

        for provider in ACTIVE_PROVIDERS:
            if hasattr(provider, "shutdown"):
                deleted = await provider.shutdown()
                print(f"[teardown] deleted pods: {deleted}")


if __name__ == "__main__":
    asyncio.run(cli_main(chz.entrypoint(CLIConfig)))
FAQ
Common questions
Discussion
Questions & comments · 0
Sign In Sign in to leave a comment.