
Run transformer inference 4.76x faster on Apple Silicon Neural Engine
Swift library and CLI that runs transformer inference directly on the Apple Neural Engine through private APIs, without CoreML in the hot path.
0.9.0Add to Favorites
Why it matters
Accelerate transformer model inference on Apple Silicon by compiling MIL programs directly to the Neural Engine through reverse-engineered private APIs, bypassing CoreML overhead for production-grade speed improvements in on-device AI applications.
Outcomes
What it gets done
Compile transformer models directly to ANE silicon with zero-copy IOSurface buffers
Fuse multi-layer transformer kernels into 2 ANE dispatches instead of 6
Generate tokens at 1.08 ms/token with verified two-token decode steps
Train models on ANE with forward and backward passes plus gradient accumulation
Source
Get it from source
Spark does not host a copy of it.
Open sourceReports
Agent outcome reports
No reports yet
Overview
Espresso is a Swift library and CLI for direct Neural Engine inference of transformers on Apple Silicon. It compiles MIL programs straight to ANE silicon through reverse-engineered private APIs (_ANEClient and _ANEInMemoryModel), with no CoreML in the hot path, no per-token recompilation, IOSurface buffers and fused multi-layer kernels. Use it on Apple Silicon Macs running macOS 15 or later to run or research transformer decoding on the Neural Engine. Apps that use the private ANE APIs will be rejected from the App Store, and iOS and tvOS are not supported out of the box.
What it does
Espresso compiles MIL programs straight to ANE silicon through reverse-engineered private APIs (_ANEClient, _ANEInMemoryModel). There is no CoreML in the hot path and no per-token recompilation. The decode loop compiles once and reuses the program across all steps, with the KV cache kept in IOSurface buffers rather than marshaled through CoreML. It uses fused multi-layer kernels for fewer ANE dispatches per token, zero-copy input and output with NEON-vectorized surface reads, and vDSP or Metal where useful. The core is pure Swift 6.2 with move-only ~Copyable tensors, strict concurrency and typed throws. There are zero required third-party packages: the package graph depends only on Apple system frameworks (Foundation, Accelerate, IOSurface, Metal, CoreML), and a clean clone resolves and builds on macOS 15 and later.
When to use - and when NOT to
Use it to serve or study ANE decoding on Apple Silicon, to reproduce greedy parity, or to embed ANE kernels in a Swift tool.
Qwen2.5-0.5B-Instruct is the parity path: one model, greedy and fp16, and neither a general-model claim nor a speed claim.
Platform limits: apps using the private ANE APIs will be rejected by the App Store, while internal tools, research, sideloaded apps and enterprise distribution are fine. iOS and tvOS are not supported out of the box because private API entitlements differ per platform, and Apple A-series on iOS requires an entitlement and is not App Store safe. Intel Macs have no Neural Engine. The APIs are undocumented and were discovered through runtime introspection, and results are hardware and OS dependent. It is not affiliated with or endorsed by Apple Inc. Experimental configs and distillation scripts that were rejected are not product entry points, and their numbers and flags are not supported behavior.
Inputs and outputs
To try the demo, clone and build:
git clone https://github.com/christopherkarani/Espresso.git
cd Espresso
./espresso doctor   # host readiness check (scripts, ANE, Python)
./espresso prepare  # bootstrap GPT-2 demo weights + tokenizer (network; torch/transformers)
./espresso          # builds if needed, launches the GPT-2 TUI demo
The first demo run also bootstraps assets automatically when they are missing. That step needs network access and a Python with torch and transformers, and Espresso can create a managed venv for it.
Portable .esp model bundles are the retained serving path. These tools run through swift run: swift run espc pack-native /path/to/model /tmp/model.esp --overwrite packs a prepared native model directory into an .esp bundle, swift run esprun inspect /tmp/model.esp and swift run esprun generate /tmp/model.esp "Hello" 32 inspect and generate from a bundle (esprun also resolves bundles), and swift run espresso-generate generate --bundle /tmp/model.esp --max-tokens 32 "Hello" is the same bundle boundary through the full generate and benchmark CLI. A .esp file is the canonical portable model bundle, and a .espc file is a derived, host-local compiled-cache layer.
For chat with Qwen2.5-1.5B-Instruct, scripts/convert_qwen25_05b_to_esp.py --model Qwen/Qwen2.5-1.5B-Instruct converts the local Hugging Face snapshot (downloading it if needed) and packs an .esp bundle; ./espresso chat --model ~/Library/Caches/Espresso/qwen25-15b/Qwen2.5-1.5B-Instruct.esp then chats with that bundle. The converter supports Qwen2.5-0.5B-Instruct (the default) and Qwen2.5-1.5B-Instruct, both Apache-2.0 and ungated. It also takes --output, --native-dir, --source-dir, --max-seq (default 1024, and masks scale as the square of the sequence length), --fp32-sidecars none|all (default none), --force-download, --skip-pack and --no-bootstrap. It needs numpy and creates a managed venv when numpy is missing, unless --no-bootstrap is set, in which case it fails instead. ESPRESSO_HOME and ESPRESSO_CACHE_HOME override the state root and cache root, which default to ~/Library/Application Support/Espresso and ~/Library/Caches/Espresso. Conversion fails with an error if fp16 conversion overflows to infinity for any weight. The converter writes conversion-report.json describing every tensor it wrote, alongside the native model directory and the packed .esp bundle. It rejects --max-seq values of 0 or below, or above the model context or the BLOBFILE mask limit.
Qwen2.5-1.5B-Instruct decodes through the ANE hybrid path, with Q, K, V and the SwiGLU feed-forward network on the Neural Engine, and RoPE, attention and the roughly 467 MB LM head on the CPU by design (cpu_fp16_tiled). ./espresso chat is multi-turn with fallback disabled, keeps Qwen Instruct history across turns, and supports /reset, /retry and /exit, with Ctrl-C cancelling the current completion. Tokens per second, time to first token and joules per token are live footer measurements for that completion in the TUI. ./espresso chat --vs mlx --greedy gives a dual-pane comparison against MLX on the same checkpoint, greedy, fp16 against fp16, with compile excluded from tokens per second.
To reproduce 0.5B greedy parity, run the converter with its default target and then ./espresso generate on the resulting Qwen2.5-0.5B-Instruct bundle with -n 24 and the prompt "The capital of France is", with ESPRESSO_REALMODEL_DISABLE_HYBRID_FALLBACK=1 set.
Optional tooling: ./espresso install puts a PATH shim pointing at the checkout (it does not download weights), ./espresso compare --no-power runs a side-by-side against CoreML on the demo weights, swift run espresso-bench --ane-only --inference --layers 6 runs the benchmark, and swift run espresso-train is an experimental ANE training loop.
Integrations
Espresso is used from Swift Package Manager (from version 0.9.0) with the ANERuntime and ANETypes products. ANEKernel takes MIL text, weights and input and output sizes, eval() runs it on the Neural Engine and outputSurface(at:) reads the result without copying. For end-to-end text generation from prepared weights, use RealModelInference or an .esp bundle rather than hand-writing MIL.
The modules are ANEInterop (an ObjC and C dlopen bridge to _ANEClient and _ANEInMemoryModel with NEON-vectorized I/O), ANETypes (~Copyable tensors, SurfaceIO, weight serialization, model config), MILGenerator (MIL text for forward, backward, decode and fused kernels), CPUOps (RMSNorm, RoPE, embedding, softmax and Adam through Accelerate and vDSP), ANERuntime (compiles MIL to ANE E5 binaries and manages IOSurface buffers and the compile budget), Espresso (generation harnesses, decode, training experiments), RealModelInference (the hybrid serving path used by espresso-generate and the .esp runtime) and ESPBundle with ESPRuntime (portable bundles and runtime resolution).
Requirements are Apple Silicon (M1 or later) with a Neural Engine, macOS 15.0 or later, and Swift 6.0 or later with 6.2 recommended. The M1, M2, M3 and M4 families are tested, with M3 Max as the reference hardware, and the M4 family warms its compile cache faster. swift test runs the unit tests and needs no ANE, and hardware tests are enabled with ANE_HARDWARE_TESTS=1 (ANE_HARDWARE_TESTS=1 swift test --filter "ANERuntimeTests|EspressoTests"); adding OBJC_CROSS_VALIDATION=1 and --filter CrossValidationTests runs the parity cross-validation. It is MIT licensed.
Source README


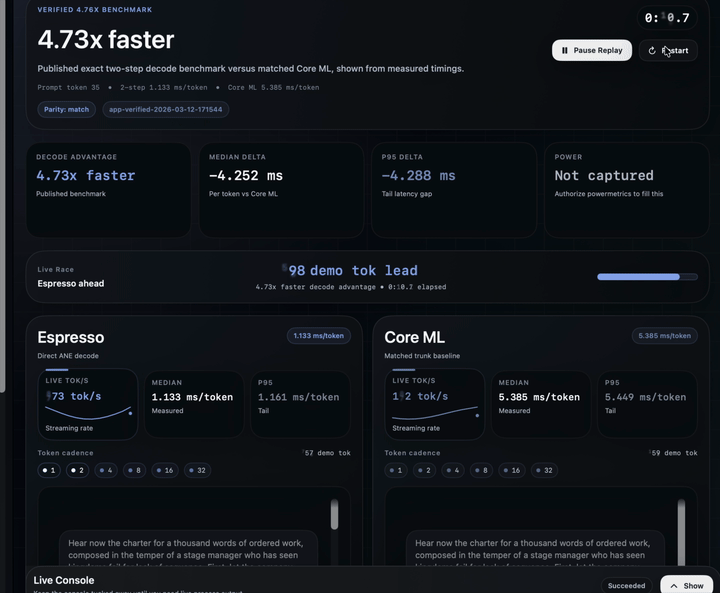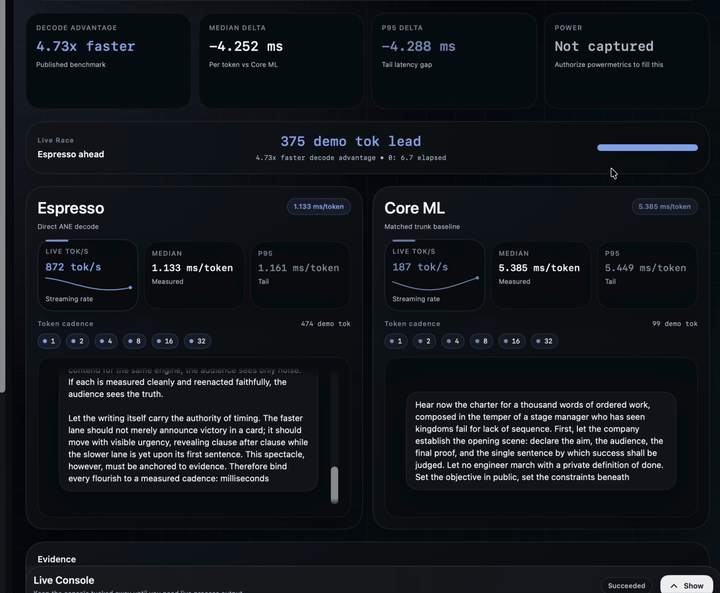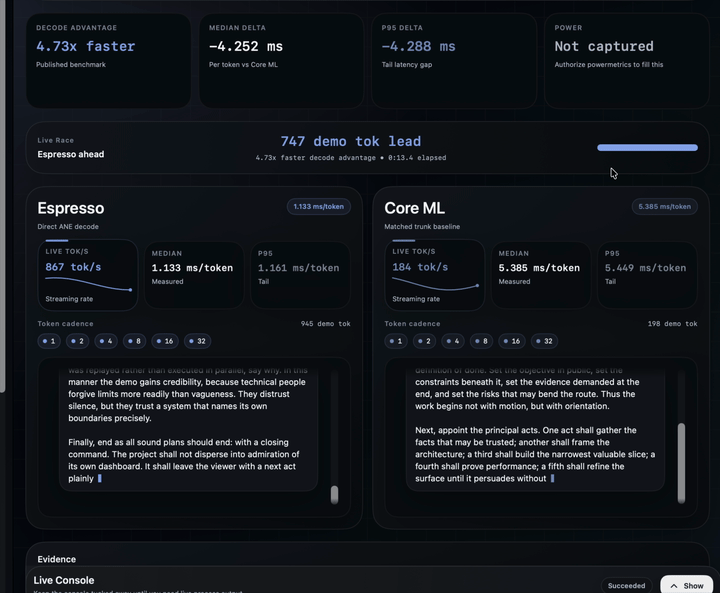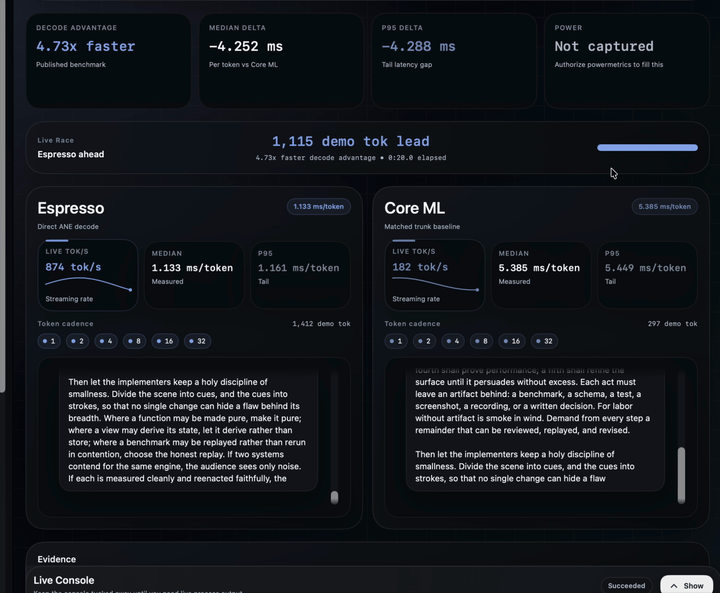
Espresso compiles MIL programs straight to ANE silicon through reverse-engineered private APIs (_ANEClient, _ANEInMemoryModel). No CoreML in the hot path. No per-token recompilation. IOSurface buffers and fused multi-layer kernels for Apple Silicon.
- Direct ANE path - private-API compile once, reuse across decode steps
- Fused multi-layer kernels - fewer ANE dispatches per token
- Zero-copy I/O - NEON-vectorized surface reads, vDSP/Metal where useful
- Pure Swift 6.2 core -
~Copyablemove-only tensors, strict concurrency, typed throws - Zero required third-party packages - clean clone resolves and builds on macOS 15+
Product journeys
Pick one path. Everything else is optional or research.
1. Try it (demo)
git clone https://github.com/christopherkarani/Espresso.git
cd Espresso
./espresso doctor   # host readiness check (scripts, ANE, Python)
./espresso prepare  # bootstrap GPT-2 demo weights + tokenizer (network; torch/transformers)
./espresso          # builds if needed, launches the GPT-2 TUI demo
First demo run also bootstraps assets automatically when they are missing. That step needs
network access and a Python with torch + transformers (Espresso can create a managed venv).
2. Serve a model (.esp bundles)
Portable model bundles are the retained serving path:
# Pack a prepared native model directory into a portable bundle
swift run espc pack-native /path/to/model /tmp/model.esp --overwrite

# Inspect / run
swift run esprun inspect /tmp/model.esp
swift run esprun generate /tmp/model.esp "Hello" 32

# Same bundle boundary via the generate CLI
swift run espresso-generate generate --bundle /tmp/model.esp --max-tokens 32 "Hello"
| Artifact | Role |
|---|---|
.esp |
Canonical portable model bundle |
.espc |
Derived compiled-cache layer (host-local) |
espc |
Pack native model dirs into .esp |
esprun |
Inspect, resolve, generate from bundles |
espresso-generate --bundle |
Full generate/benchmark CLI on the same boundary |
3. Chat with a real open-weight model (Qwen2.5-1.5B-Instruct)
# Convert the local Hugging Face snapshot (or download it) and pack a .esp bundle
python3 scripts/convert_qwen25_05b_to_esp.py --model Qwen/Qwen2.5-1.5B-Instruct

# Multi-turn chat. Fallback is disabled. Live tok/s, TTFT, and J/tok stay in the TUI.
./espresso chat --model ~/Library/Caches/Espresso/qwen25-15b/Qwen2.5-1.5B-Instruct.esp
Qwen2.5-1.5B-Instruct decodes through Espresso's ANE hybrid path: Q/K/V and the SwiGLU
FFN on the Neural Engine; RoPE, attention, and the ~467 MB LM head on the CPU by design
(cpu_fp16_tiled). Chat keeps Qwen Instruct history across turns. Commands: /reset
/retry /exit. Ctrl-C cancels the current completion.
Throughput and energy are live footer measurements for that completion, not README headlines. Optional dual-pane vs MLX (same checkpoint, greedy, fp16 vs fp16; compile excluded from tok/s):
./espresso chat --vs mlx --greedy --model ~/Library/Caches/Espresso/qwen25-15b/Qwen2.5-1.5B-Instruct.esp
See docs/qwen15b-parity.md for the 1.5B greedy contract and
the commands that regenerate it.
4. Reproduce 0.5B greedy parity
# Default converter target remains Qwen2.5-0.5B-Instruct
python3 scripts/convert_qwen25_05b_to_esp.py

ESPRESSO_REALMODEL_DISABLE_HYBRID_FALLBACK=1 \
  ./espresso generate --model ~/Library/Caches/Espresso/qwen25-05b/Qwen2.5-0.5B-Instruct.esp \
  -n 24 "The capital of France is"
Qwen2.5-0.5B-Instruct is the parity/repro path. It reproduces a PyTorch fp32 reference
on a fixed 12-prompt greedy suite: 10 of 12 sequences match token-for-token, 341 of
384 tokens agree. That 10/12 is generate-path evidence (cpu_fp16_tiled LM head). A
separate probe - chained per-layer hidden states plus a NumPy/Python LM head, not the
served tiled classifier - agrees with PyTorch to 9.3e-5 in logits on the fp32 CPU
stack through all 24 layers, and to ~0.96 on the ANE hybrid stack. The two greedy
divergences come from fp16 execution on the ANE (up to ~1 logit of error) and both land
on precisely the reference's runner-up token at top-1/top-2 gaps of 0.027 and 0.069.
That is one model, greedy, fp16, measured - not a general-model claim, and not a speed
claim.
See docs/qwen-parity.md for the per-layer report, the exact
commands, and every ANE limitation hit along the way.
5. Embed the library (ANEKernel)
// Package.swift
.package(url: "https://github.com/christopherkarani/Espresso.git", from: "0.9.0")

import ANERuntime

let kernel = try ANEKernel(
    milText: myMIL,
    weights: blobs,
    inputSizes: [input],
    outputSizes: [output]
)
try kernel.eval()                         // runs on Neural Engine
let result = kernel.outputSurface(at: 0)  // zero-copy read
For end-to-end text generation from prepared weights, use RealModelInference or a .esp bundle rather than hand-writing MIL.
./espresso install                            # PATH shim → this checkout (does not download weights)
./espresso prepare                            # download/convert GPT-2 demo assets
./espresso compare --no-power "Hello"         # side-by-side vs CoreML (demo weights)
swift run espresso-bench --ane-only --inference --layers 6
swift run espresso-train                      # experimental ANE training loop
Rejected experiment configs and distillation scripts live under research/ and are not product entry points.
Benchmark
Numbers below match the checked-in machine-readable results in
benchmarks/results/latest.json
(M3 Max, macOS 15.0, Espresso 1.1.0).
Espresso vs CoreML (local 6-layer Stories artifact)
| Backend | ms/token | tok/s | Notes |
|---|---|---|---|
| Espresso ANE (recurrent fused, 6-layer) | 1.93 | 519 | Fused 3-layer recurrent decode + ANE classifier |
| Espresso ANE (direct transformer, 6-layer) | 6.56 | 153 | Same model without recurrent fusion |
CoreML .cpuAndNeuralEngine |
6.58 | 152 | Apple's standard ANE path |
| Espresso speedup vs CoreML | 3.41× | fused recurrent path |
All Espresso / CoreML numbers: 6-layer local artifact · dim=768 · 12 heads · 32k vocab · seqLen=256 · M3 Max · macOS 15. This is a research / demo artifact family, not a pretrained production model.
What these numbers are not
- Not a claim about full GPT-2 117M or llama.cpp Metal on the same workload
- Not every serving path: retained exact hybrid
.espStories runs can land lower in wall-clock tok/s after compile and full decode accounting - Not trunk-only or partial-pipeline peaks from blog posts - only figures backed by
latest.json(or a PR artifact from the reproduce script) are project claims
RESULTS_DIR=results/$(date +%Y%m%d-%H%M%S) \
REPEATS=5 WARMUP=3 ITERATIONS=20 \
./scripts/reproduce_local_real_artifact_claim.sh
Machine-readable output lands in artifacts/benchmarks/ and is kept out of git.
Update benchmarks/results/latest.json only when you intentionally refresh the public table.
CI fails if the README table drifts from latest.json.
Platform Compatibility
| SoC | Neural Engine | Tested | Notes |
|---|---|---|---|
| M1 / M1 Pro / M1 Max / M1 Ultra | 16-core ANE | ✅ | Full feature set |
| M2 / M2 Pro / M2 Max / M2 Ultra | 16-core ANE | ✅ | Full feature set |
| M3 / M3 Pro / M3 Max | 18-core ANE | ✅ | Reference hardware (M3 Max) |
| M4 / M4 Pro / M4 Max | 38-core ANE | ✅ | Faster compile cache warm-up |
| Intel Mac | - | ❌ | No Neural Engine |
| Apple A-series (iOS) | ✅ | ⚠️ | Requires entitlement; not App Store safe |
macOS 15+ required. iOS / tvOS not supported out of the box (private API entitlements differ per platform).
How It Works
                    ┌─────────────────────┐
                    │   MIL Program Text   │  Generated per-kernel
                    └──────────┬──────────┘
                               ▼
                    ┌─────────────────────┐
                    │  _ANEClient compile  │  Private API (dlopen)
                    └──────────┬──────────┘
                               ▼
                    ┌─────────────────────┐
                    │    ANE E5 Binary     │  Cached by system
                    └──────────┬──────────┘
                               ▼
              ┌────────────────┼────────────────┐
              ▼                ▼                ▼
     ┌──────────────┐ ┌──────────────┐ ┌──────────────┐
     │  IOSurface   │ │  IOSurface   │ │  IOSurface   │
     │   (input)    │ │  (weights)   │ │  (output)    │
     └──────┬───────┘ └──────────────┘ └──────┬───────┘
            │          ANE Hardware            │
            └──────────────eval───────────────┘
The decode loop compiles once and reuses the program across all steps. KV cache lives in IOSurface buffers - not marshaled through CoreML.
Architecture
ANEInterop (ObjC/C — private API bridge)
  └── ANETypes (~Copyable value types, IOSurface I/O)
          ├── MILGenerator (kernel variants)
          │       └── ANERuntime (compile, eval, surface management)
          │               └── Espresso / RealModelInference (serving, decode)
          │                       ├── espresso-generate / esprun (CLI)
          │                       └── ESPBundle (portable .esp)
          └── CPUOps (Accelerate/vDSP kernels)
| Module | What it does |
|---|---|
| ANEInterop | dlopen bridge to _ANEClient and _ANEInMemoryModel. NEON-vectorized I/O. |
| ANETypes | ~Copyable tensors, SurfaceIO, weight serialization, model config. |
| MILGenerator | Generates MIL text for forward, backward, decode, and fused kernels. |
| CPUOps | RMSNorm, RoPE, embedding, softmax, Adam via Accelerate/vDSP. |
| ANERuntime | Compiles MIL to ANE E5 binaries. Manages IOSurface buffers and compile budget. |
| Espresso | Generation harnesses, decode, training experiments. |
| RealModelInference | Hybrid serving path used by espresso-generate / .esp runtime. |
| ESPBundle / ESPRuntime | Portable .esp bundles and runtime resolution. |
SPM Integration
// Package.swift
dependencies: [
    .package(url: "https://github.com/christopherkarani/Espresso.git", from: "0.9.0")
],
targets: [
    .target(name: "MyApp", dependencies: [
        .product(name: "ANERuntime", package: "Espresso"),
        .product(name: "ANETypes",   package: "Espresso"),
    ])
]
import ANERuntime
import ANETypes

let kernel = try ANEKernel(
    milText: milText,
    weights: weightBlobs,
    inputSizes: [inputByteSize],
    outputSizes: [outputByteSize]
)
try kernel.eval()
let output = try kernel.outputSurface(at: 0)
Dependencies
Zero third-party Swift packages. The package graph depends only on Apple system frameworks (Foundation, Accelerate, IOSurface, Metal, CoreML). A clean clone of this repo alone must resolve and build.
Requirements
| Minimum | |
|---|---|
| Hardware | Apple Silicon (M1+) with Neural Engine |
| macOS | 15.0+ |
| Swift | 6.0+ (6.2 recommended) |
| Dependencies | None required - Apple system frameworks only |
Testing
swift test                                                    # unit tests (no ANE needed)
ANE_HARDWARE_TESTS=1 swift test --filter "ANERuntimeTests|EspressoTests"  # hardware tests
OBJC_CROSS_VALIDATION=1 ANE_HARDWARE_TESTS=1 swift test --filter CrossValidationTests  # parity
CI runs non-hardware unit tests including ESP bundle/runtime and RealModelInference unit suites, asserts a zero-dependency default graph, and checks README claim numbers against latest.json. Hardware ANE tests run on self-hosted matrix jobs.
Research vs product
| Path | Location |
|---|---|
| Retained product surface | Sources/, ./espresso, espc / esprun / espresso-generate, public docs |
| Quarantined experiments | research/ - rejected draft/student/future-head configs and tooling |
Do not treat research/ numbers or flags as supported product behavior.
scripts/convert_qwen25_05b_to_esp.py
#!/usr/bin/env python3
"""Convert Qwen2.5 Instruct safetensors into an Espresso `.esp` bundle.
Supported checkpoints (Apache-2.0, ungated):
* Qwen/Qwen2.5-0.5B-Instruct (default)
* Qwen/Qwen2.5-1.5B-Instruct
The model maps onto Espresso's llama-family layer layout with one addition that
plain llama does not have: Qwen2 carries a bias on q/k/v (and only on q/k/v).
Those land as `bq.bin` / `bk.bin` / `bv.bin` next to the projections.
One-command usage (bootstraps its own Python env when numpy is missing):
./scripts/convert_qwen25_05b_to_esp.py
./scripts/convert_qwen25_05b_to_esp.py --model Qwen/Qwen2.5-1.5B-Instruct
Outputs:
* a native model directory (fp16 BLOBFILE tensors + metadata.json + tokenizer)
* a packed `.esp` bundle produced by `swift run espc pack-native`
* `conversion-report.json` describing every tensor that was written
"""
from __future__ import annotations
import argparse
import json
import math
import os
import shutil
import struct
import subprocess
import sys
import urllib.request
from dataclasses import dataclass, field
from pathlib import Path
from typing import TYPE_CHECKING
if TYPE_CHECKING:
import numpy as np
REPO_ROOT = Path(__file__).resolve().parent.parent
DEFAULT_MODEL = "Qwen/Qwen2.5-0.5B-Instruct"
HF_REPO = DEFAULT_MODEL
# Files copied verbatim into the bundle's tokenizer/ directory. `espc pack-native`
# recognizes these names and splits them out of weights/ automatically.
TOKENIZER_FILES = ("tokenizer.json", "tokenizer_config.json", "vocab.json", "merges.txt")
OPTIONAL_SOURCE_FILES = ("generation_config.json", "LICENSE")
REQUIRED_META_FILES = ("config.json",) + TOKENIZER_FILES
WEIGHT_INDEX_NAME = "model.safetensors.index.json"
WEIGHT_SINGLE_NAME = "model.safetensors"
# BLOBFILE payload size is a UInt32, which caps a square causal mask.
MAX_BLOBFILE_DATA_SIZE = 0xFFFF_FFFF
BOOTSTRAP_GUARD_ENV = "ESPRESSO_QWEN_CONVERT_BOOTSTRAPPED"
class ConversionError(RuntimeError):
"""Raised for every failure this script can explain to the caller."""
@dataclass(frozen=True)
class ModelProfile:
repo: str
cache_slug: str
source_slug: str
official: dict[str, int]
rope_theta: float
@property
def short_name(self) -> str:
return self.repo.split("/")[-1]
OFFICIAL_QWEN25_05B_INSTRUCT = {
"n_layer": 24,
"n_head": 14,
"n_kv_head": 2,
"d_model": 896,
"head_dim": 64,
"hidden_dim": 4864,
"vocab": 151936,
}
OFFICIAL_QWEN25_15B_INSTRUCT = {
"n_layer": 28,
"n_head": 12,
"n_kv_head": 2,
"d_model": 1536,
"head_dim": 128,
"hidden_dim": 8960,
"vocab": 151936,
}
OFFICIAL_QWEN25_05B_ROPE_THETA = 1_000_000.0
OFFICIAL_QWEN25_15B_ROPE_THETA = 1_000_000.0
SUPPORTED_MODELS: dict[str, ModelProfile] = {
"Qwen/Qwen2.5-0.5B-Instruct": ModelProfile(
repo="Qwen/Qwen2.5-0.5B-Instruct",
cache_slug="qwen25-05b",
source_slug="qwen25-05b-src",
official=OFFICIAL_QWEN25_05B_INSTRUCT,
rope_theta=OFFICIAL_QWEN25_05B_ROPE_THETA,
),
"Qwen/Qwen2.5-1.5B-Instruct": ModelProfile(
repo="Qwen/Qwen2.5-1.5B-Instruct",
cache_slug="qwen25-15b",
source_slug="qwen25-15b-src",
official=OFFICIAL_QWEN25_15B_INSTRUCT,
rope_theta=OFFICIAL_QWEN25_15B_ROPE_THETA,
),
}
@dataclass(frozen=True)
class DefaultPaths:
bundle: Path
native: Path
source: Path
def default_paths(profile: ModelProfile, cache_root: Path) -> DefaultPaths:
bundle = cache_root / profile.cache_slug / f"{profile.short_name}.esp"
return DefaultPaths(
bundle=bundle,
native=bundle.parent / f"{profile.short_name}-native",
source=cache_root / profile.source_slug,
)
def profile_for_name(name: str) -> ModelProfile:
for profile in SUPPORTED_MODELS.values():
if profile.short_name == name or profile.repo == name:
return profile
accepted = ", ".join(SUPPORTED_MODELS)
raise ConversionError(f"unsupported model {name!r}; accepted: {accepted}")
# ---------------------------------------------------------------------------
# Dependency bootstrap
# ---------------------------------------------------------------------------
def espresso_state_root() -> Path:
override = os.environ.get("ESPRESSO_HOME", "").strip()
if override:
return Path(override).expanduser()
return Path.home() / "Library" / "Application Support" / "Espresso"
def espresso_cache_root() -> Path:
override = os.environ.get("ESPRESSO_CACHE_HOME", "").strip()
if override:
return Path(override).expanduser()
return Path.home() / "Library" / "Caches" / "Espresso"
def ensure_runtime_dependencies(allow_bootstrap: bool) -> None:
"""Re-exec inside a managed venv when numpy is unavailable.
Mirrors the managed-venv convention used by the GPT-2 demo bootstrap:
`<state root>/tools/python/qwen25-tools-<pyver>`.
"""
try:
import numpy # noqa: F401
return
except ImportError:
pass
if os.environ.get(BOOTSTRAP_GUARD_ENV) == "1":
raise ConversionError(
"numpy is still unavailable after bootstrapping a managed venv. "
"Install numpy manually and re-run with --no-bootstrap."
)
if not allow_bootstrap:
raise ConversionError(
"numpy is required. Either install it for this interpreter or drop --no-bootstrap "
"so a managed venv can be created."
)
version_tag = f"{sys.version_info.major}.{sys.version_info.minor}"
venv_dir = espresso_state_root() / "tools" / "python" / f"qwen25-tools-{version_tag}"
venv_python = venv_dir / "bin" / "python3"
if not venv_python.exists():
print(f"[bootstrap] creating managed venv at {venv_dir}", flush=True)
venv_dir.parent.mkdir(parents=True, exist_ok=True)
uv = shutil.which("uv")
if uv:
subprocess.run([uv, "venv", "--python", version_tag, str(venv_dir)], check=True)
else:
subprocess.run([sys.executable, "-m", "venv", str(venv_dir)], check=True)
print("[bootstrap] installing numpy", flush=True)
uv = shutil.which("uv")
if uv:
subprocess.run(
[uv, "pip", "install", "--python", str(venv_python), "numpy"],
check=True,
)
else:
subprocess.run([str(venv_python), "-m", "pip", "install", "--upgrade", "pip"], check=True)
subprocess.run([str(venv_python), "-m", "pip", "install", "numpy"], check=True)
print(f"[bootstrap] re-executing under {venv_python}", flush=True)
env = dict(os.environ)
env[BOOTSTRAP_GUARD_ENV] = "1"
os.execve(str(venv_python), [str(venv_python), str(Path(__file__).resolve()), *sys.argv[1:]], env)
# ---------------------------------------------------------------------------
# Source resolution (Hugging Face snapshot first, then download)
# ---------------------------------------------------------------------------
def huggingface_hub_root() -> Path:
for key in ("HF_HUB_CACHE", "HUGGINGFACE_HUB_CACHE"):
value = os.environ.get(key, "").strip()
if value:
return Path(value).expanduser()
hf_home = os.environ.get("HF_HOME", "").strip()
if hf_home:
return Path(hf_home).expanduser() / "hub"
return Path.home() / ".cache" / "huggingface" / "hub"
def huggingface_snapshot_dir(repo: str, revision: str = "main") -> Path | None:
slug = "models--" + repo.replace("/", "--")
repo_dir = huggingface_hub_root() / slug
ref_file = repo_dir / "refs" / revision
if ref_file.exists():
commit = ref_file.read_text(encoding="utf-8").strip()
snapshot = repo_dir / "snapshots" / commit
if snapshot.is_dir():
return snapshot
snapshot = repo_dir / "snapshots" / revision
if snapshot.is_dir():
return snapshot
return None
def _weight_files_present(source_dir: Path) -> bool:
index_path = source_dir / WEIGHT_INDEX_NAME
if index_path.exists() and index_path.stat().st_size > 0:
try:
weight_map = json.loads(index_path.read_text(encoding="utf-8"))["weight_map"]
except (OSError, KeyError, json.JSONDecodeError):
return False
return all(
(source_dir / name).exists() and (source_dir / name).stat().st_size > 0
for name in set(weight_map.values())
)
single = source_dir / WEIGHT_SINGLE_NAME
return single.exists() and single.stat().st_size > 0
def snapshot_is_complete(source_dir: Path) -> bool:
for name in ("config.json", "tokenizer.json"):
candidate = source_dir / name
if not candidate.exists() or candidate.stat().st_size == 0:
return False
return _weight_files_present(source_dir)
def resolve_source_dir(
repo: str,
explicit: Path | None,
cache_root: Path,
source_slug: str,
force_download: bool,
) -> Path:
if explicit is not None:
return explicit
fallback = cache_root / source_slug
if not force_download:
snapshot = huggingface_snapshot_dir(repo)
if snapshot is not None and snapshot_is_complete(snapshot):
return snapshot
if snapshot_is_complete(fallback):
return fallback
return fallback
def _download_file(base_url: str, source_dir: Path, name: str, force: bool, required: bool) -> bool:
target = source_dir / name
if target.exists() and target.stat().st_size > 0 and not force:
return True
url = f"{base_url}/{name}"
print(f"[download] {name}", flush=True)
tmp = target.with_suffix(target.suffix + ".partial")
try:
with urllib.request.urlopen(url, timeout=120) as response, tmp.open("wb") as handle:
shutil.copyfileobj(response, handle, length=1 << 20)
except OSError as error:
tmp.unlink(missing_ok=True)
if not required:
print(f"[download] optional {name} unavailable ({error})", flush=True)
return False
raise ConversionError(f"failed to download {url}: {error}") from error
tmp.replace(target)
return True
def download_source(repo: str, source_dir: Path, force: bool) -> Path:
source_dir.mkdir(parents=True, exist_ok=True)
base_url = f"https://huggingface.co/{repo}/resolve/main"
for name in REQUIRED_META_FILES:
_download_file(base_url, source_dir, name, force, required=True)
for name in OPTIONAL_SOURCE_FILES:
_download_file(base_url, source_dir, name, force, required=False)
if not force and _weight_files_present(source_dir):
return source_dir
if _download_file(base_url, source_dir, WEIGHT_INDEX_NAME, force, required=False):
weight_map = json.loads((source_dir / WEIGHT_INDEX_NAME).read_text(encoding="utf-8"))["weight_map"]
for shard in sorted(set(weight_map.values())):
_download_file(base_url, source_dir, shard, force, required=True)
return source_dir
_download_file(base_url, source_dir, WEIGHT_SINGLE_NAME, force, required=True)
return source_dir
# ---------------------------------------------------------------------------
# safetensors reading
# ---------------------------------------------------------------------------
@dataclass
class SafetensorsFile:
path: Path
header: dict
data_offset: int
@classmethod
def open(cls, path: Path) -> "SafetensorsFile":
with path.open("rb") as handle:
raw_length = handle.read(8)
if len(raw_length) != 8:
raise ConversionError(f"{path} is too short to be a safetensors file")
header_length = struct.unpack("<Q", raw_length)[0]
header_bytes = handle.read(header_length)
if len(header_bytes) != header_length:
raise ConversionError(f"{path} has a truncated safetensors header")
header = json.loads(header_bytes)
header.pop("__metadata__", None)
return cls(path=path, header=header, data_offset=8 + header_length)
def tensor_names(self) -> list[str]:
return sorted(self.header.keys())
def read(self, name: str) -> np.ndarray:
"""Return a float32 numpy array for `name`, widening bf16 losslessly."""
import numpy as np
entry = self.header.get(name)
if entry is None:
raise ConversionError(f"tensor {name!r} is missing from {self.path.name}")
dtype = entry["dtype"]
begin, end = entry["data_offsets"]
shape = tuple(entry["shape"])
with self.path.open("rb") as handle:
handle.seek(self.data_offset + begin)
payload = handle.read(end - begin)
if len(payload) != end - begin:
raise ConversionError(f"tensor {name!r} is truncated in {self.path.name}")
if dtype == "BF16":
# bf16 shares fp32's exponent field, so a 16-bit left shift is exact.
raw = np.frombuffer(payload, dtype="<u2").astype(np.uint32) << 16
values = raw.view(np.float32)
elif dtype == "F16":
values = np.frombuffer(payload, dtype="<f2").astype(np.float32)
elif dtype == "F32":
values = np.frombuffer(payload, dtype="<f4").astype(np.float32)
else:
raise ConversionError(f"tensor {name!r} has unsupported dtype {dtype}")
expected = math.prod(shape) if shape else 1
if values.size != expected:
raise ConversionError(
f"tensor {name!r} has {values.size} elements but shape {shape} implies {expected}"
)
return values.reshape(shape)
@dataclass
class SafetensorsStore:
files: list[SafetensorsFile]
owners: dict[str, SafetensorsFile]
@classmethod
def open_source(cls, source_dir: Path) -> "SafetensorsStore":
index_path = source_dir / WEIGHT_INDEX_NAME
if index_path.exists() and index_path.stat().st_size > 0:
try:
weight_map = json.loads(index_path.read_text(encoding="utf-8"))["weight_map"]
except (OSError, KeyError, json.JSONDecodeError) as error:
raise ConversionError(f"{index_path} is not a valid safetensors index: {error}") from error
opened: dict[str, SafetensorsFile] = {}
owners: dict[str, SafetensorsFile] = {}
for tensor_name, filename in weight_map.items():
if filename not in opened:
opened[filename] = SafetensorsFile.open(source_dir / filename)
owners[tensor_name] = opened[filename]
return cls(files=list(opened.values()), owners=owners)
single = source_dir / WEIGHT_SINGLE_NAME
if not single.exists() or single.stat().st_size == 0:
raise ConversionError(
f"{source_dir} has neither {WEIGHT_SINGLE_NAME} nor {WEIGHT_INDEX_NAME}"
)
store_file = SafetensorsFile.open(single)
return cls(files=[store_file], owners={name: store_file for name in store_file.tensor_names()})
def tensor_names(self) -> list[str]:
return sorted(self.owners)
def read(self, name: str) -> np.ndarray:
owner = self.owners.get(name)
if owner is None:
raise ConversionError(f"tensor {name!r} is missing from the checkpoint")
return owner.read(name)
# ---------------------------------------------------------------------------
# BLOBFILE writing
# ---------------------------------------------------------------------------
def make_blob_header(data_size: int) -> bytes:
if data_size > MAX_BLOBFILE_DATA_SIZE:
raise ConversionError(f"blob payload {data_size} exceeds BLOBFILE UInt32 size field")
header = bytearray(128)
header[0] = 0x01
header[4] = 0x02
header[64:68] = bytes([0xEF, 0xBE, 0xAD, 0xDE])
header[68] = 0x01
struct.pack_into("<I", header, 72, data_size)
struct.pack_into("<I", header, 80, 128)
return bytes(header)
@dataclass
class TensorRecord:
relative_path: str
source: str
shape: list[int]
count: int
max_abs: float
fp16_overflow: int
fp16_max_abs_error: float
@dataclass
class ConversionStats:
tensors: list[TensorRecord] = field(default_factory=list)
def overflowing(self) -> list[TensorRecord]:
return [record for record in self.tensors if record.fp16_overflow > 0]
def worst_fp16_error(self) -> TensorRecord | None:
if not self.tensors:
return None
return max(self.tensors, key=lambda record: record.fp16_max_abs_error)
def write_blob(
values: np.ndarray,
path: Path,
*,
source: str,
stats: ConversionStats,
write_fp32_sidecar: bool,
) -> None:
"""Write `values` as an fp16 BLOBFILE and record the rounding cost."""
import numpy as np
array = np.ascontiguousarray(values, dtype=np.float32)
half = array.astype(np.float16)
# fp16 has a narrower exponent than bf16, so a large bf16 value can become inf.
# That would be a silent accuracy cliff, so count it and report it.
overflow = int(np.count_nonzero(~np.isfinite(half) & np.isfinite(array)))
finite = np.isfinite(half)
error = float(np.max(np.abs(half[finite].astype(np.float32) - array[finite]))) if finite.any() else 0.0
payload = half.tobytes()
path.parent.mkdir(parents=True, exist_ok=True)
with path.open("wb") as handle:
handle.write(make_blob_header(len(payload)))
handle.write(payload)
if write_fp32_sidecar:
sidecar = path.with_name(path.stem + ".float32.bin")
with sidecar.open("wb") as handle:
handle.write(array.tobytes())
stats.tensors.append(
TensorRecord(
relative_path=str(path),
source=source,
shape=list(array.shape),
count=int(array.size),
max_abs=float(np.max(np.abs(array))) if array.size else 0.0,
fp16_overflow=overflow,
fp16_max_abs_error=error,
)
)
def max_supported_mask_sequence_length() -> int:
return int(math.isqrt(MAX_BLOBFILE_DATA_SIZE // 2))
def write_causal_masks(output_dir: Path, max_seq: int) -> None:
import numpy as np
mask_dir = output_dir / "masks"
mask_dir.mkdir(parents=True, exist_ok=True)
size = 1
while size <= max_seq:
mask = np.zeros((size, size), dtype=np.float16)
mask[np.triu_indices(size, k=1)] = np.float16(-1e4)
payload = mask.tobytes()
with (mask_dir / f"causal_{size}.bin").open("wb") as handle:
handle.write(make_blob_header(len(payload)))
handle.write(payload)
size *= 2
# ---------------------------------------------------------------------------
# Conversion
# ---------------------------------------------------------------------------
@dataclass
class QwenShape:
name: str
n_layer: int
n_head: int
n_kv_head: int
d_model: int
head_dim: int
hidden_dim: int
vocab: int
norm_eps: float
rope_theta: float
eos_token: int
tie_word_embeddings: bool
max_position_embeddings: int
@property
def attention_dim(self) -> int:
return self.n_head * self.head_dim
@property
def kv_dim(self) -> int:
return self.n_kv_head * self.head_dim
def read_shape(source_dir: Path, name: str) -> QwenShape:
config = json.loads((source_dir / "config.json").read_text(encoding="utf-8"))
generation = {}
generation_path = source_dir / "generation_config.json"
if generation_path.exists():
generation = json.loads(generation_path.read_text(encoding="utf-8"))
architectures = config.get("architectures") or []
if "Qwen2ForCausalLM" not in architectures:
raise ConversionError(
f"expected a Qwen2ForCausalLM checkpoint, found architectures={architectures!r}"
)
n_head = int(config["num_attention_heads"])
d_model = int(config["hidden_size"])
head_dim = int(config.get("head_dim", d_model // n_head))
eos = generation.get("eos_token_id", config.get("eos_token_id"))
if isinstance(eos, list):
eos = eos[0]
return QwenShape(
name=name,
n_layer=int(config["num_hidden_layers"]),
n_head=n_head,
n_kv_head=int(config.get("num_key_value_heads", n_head)),
d_model=d_model,
head_dim=head_dim,
hidden_dim=int(config["intermediate_size"]),
vocab=int(config["vocab_size"]),
norm_eps=float(config["rms_norm_eps"]),
rope_theta=float(config.get("rope_theta", 10_000.0)),
eos_token=int(eos),
tie_word_embeddings=bool(config.get("tie_word_embeddings", False)),
max_position_embeddings=int(config["max_position_embeddings"]),
)
def validate_layout(shape: QwenShape) -> None:
if shape.d_model != shape.attention_dim:
raise ConversionError(
f"Espresso requires dModel == nHead * headDim; got {shape.d_model} != {shape.attention_dim}"
)
if shape.n_head % shape.n_kv_head != 0:
raise ConversionError(
f"Espresso requires nHead % nKVHead == 0; got {shape.n_head} % {shape.n_kv_head}"
)
# The ANE wants channel counts aligned to 64. Fail loudly rather than
# discover it as a compile error with no diagnostics.
for label, value in (
("dModel", shape.d_model),
("kvDim", shape.kv_dim),
("hiddenDim", shape.hidden_dim),
):
if value % 64 != 0:
raise ConversionError(
f"{label}={value} is not a multiple of 64; ANE kernels require 64-aligned channels"
)
def validate_shape(shape: QwenShape, profile: ModelProfile | None = None) -> None:
resolved = profile if profile is not None else profile_for_name(shape.name)
mismatches: list[str] = []
for field_name, expected in resolved.official.items():
got = getattr(shape, field_name)
if got != expected:
mismatches.append(f"{field_name}={got} (expected {expected})")
if float(shape.rope_theta) != float(resolved.rope_theta):
mismatches.append(
f"rope_theta={shape.rope_theta} (expected {resolved.rope_theta:g} / 1000000.0)"
)
if mismatches:
raise ConversionError(
f"this converter only accepts {resolved.repo}; checkpoint shape mismatch: "
+ ", ".join(mismatches)
)
validate_layout(shape)
def write_metadata(output_dir: Path, shape: QwenShape, max_seq: int) -> dict:
metadata = {
# `name` must contain "qwen" so `espc pack-native` infers model_family = qwen
# and the qwen-bpe-v1 tokenizer contract.
"name": shape.name,
"nLayer": shape.n_layer,
"nHead": shape.n_head,
"nKVHead": shape.n_kv_head,
"dModel": shape.d_model,
"headDim": shape.head_dim,
"hiddenDim": shape.hidden_dim,
"vocab": shape.vocab,
"maxSeq": max_seq,
"normEps": shape.norm_eps,
# Qwen2.5 uses 1e6, not the llama default of 1e4. Getting this wrong produces
# plausible-but-wrong output rather than an error.
"ropeTheta": shape.rope_theta,
"eosToken": shape.eos_token,
# MultiModelConfig has no `qwen` case; qwen is served by the llama layer family.
"architecture": "llama",
# Declared explicitly because the runtime otherwise routes anything named "qwen" to
# the pure-CPU oracle, which would mean this bundle never touched the ANE.
"preferredDecodePath": "hybrid",
}
(output_dir / "metadata.json").write_text(json.dumps(metadata, indent=2) + "\n", encoding="utf-8")
return metadata
def convert(
source_dir: Path,
output_dir: Path,
shape: QwenShape,
max_seq: int,
write_fp32_sidecars: bool,
) -> ConversionStats:
tensors = SafetensorsStore.open_source(source_dir)
available = set(tensors.tensor_names())
stats = ConversionStats()
# Qwen2.5 has no q_norm/k_norm (that is Qwen3). Assert instead of assuming, because
# the engine treats those files as an optional pair and would silently skip them.
unexpected_norms = sorted(n for n in available if ".q_norm." in n or ".k_norm." in n)
if unexpected_norms:
raise ConversionError(
"checkpoint carries per-head q/k RMSNorm tensors this converter does not export: "
+ ", ".join(unexpected_norms[:4])
)
output_dir.mkdir(parents=True, exist_ok=True)
def emit(source: str, relative: str) -> None:
write_blob(
tensors.read(source),
output_dir / relative,
source=source,
stats=stats,
write_fp32_sidecar=write_fp32_sidecars,
)
print("[convert] embeddings + final norm + lm head", flush=True)
emit("model.embed_tokens.weight", "embeddings/token.bin")
emit("model.norm.weight", "final_norm.bin")
# tie_word_embeddings=true means there is no lm_head.weight tensor. The runtime
# always loads a separate lm_head blob, so materialize the tied copy.
if "lm_head.weight" in available:
emit("lm_head.weight", "lm_head.bin")
elif shape.tie_word_embeddings:
emit("model.embed_tokens.weight", "lm_head.bin")
else:
raise ConversionError("checkpoint has no lm_head.weight and does not tie word embeddings")
for layer in range(shape.n_layer):
print(f"[convert] layer {layer}", flush=True)
prefix = f"model.layers.{layer}"
base = f"layers/{layer}"
emit(f"{prefix}.input_layernorm.weight", f"{base}/rms_att.bin")
emit(f"{prefix}.post_attention_layernorm.weight", f"{base}/rms_ffn.bin")
# HF nn.Linear weights are already row-major (out, in), which is exactly what
# the llama loaders and the ANE WeightBlob packer expect. No transpose.
emit(f"{prefix}.self_attn.q_proj.weight", f"{base}/wq.bin")
emit(f"{prefix}.self_attn.k_proj.weight", f"{base}/wk.bin")
emit(f"{prefix}.self_attn.v_proj.weight", f"{base}/wv.bin")
emit(f"{prefix}.self_attn.o_proj.weight", f"{base}/wo.bin")
# Qwen2 biases q/k/v only; o_proj and the MLP are bias-free.
emit(f"{prefix}.self_attn.q_proj.bias", f"{base}/bq.bin")
emit(f"{prefix}.self_attn.k_proj.bias", f"{base}/bk.bin")
emit(f"{prefix}.self_attn.v_proj.bias", f"{base}/bv.bin")
for banned in ("self_attn.o_proj.bias", "mlp.gate_proj.bias", "mlp.up_proj.bias", "mlp.down_proj.bias"):
if f"{prefix}.{banned}" in available:
raise ConversionError(
f"{prefix}.{banned} exists but the llama/qwen layer layout has nowhere to put it"
)
# Espresso SwiGLU naming: w1 = gate, w3 = up, w2 = down.
emit(f"{prefix}.mlp.gate_proj.weight", f"{base}/w1.bin")
emit(f"{prefix}.mlp.up_proj.weight", f"{base}/w3.bin")
emit(f"{prefix}.mlp.down_proj.weight", f"{base}/w2.bin")
print("[convert] causal masks", flush=True)
write_causal_masks(output_dir, max_seq)
for name in TOKENIZER_FILES:
candidate = source_dir / name
if candidate.exists():
shutil.copy2(candidate, output_dir / name)
return stats
def expected_counts(shape: QwenShape) -> dict[str, int]:
counts = {
"embeddings/token.bin": shape.vocab * shape.d_model,
"final_norm.bin": shape.d_model,
"lm_head.bin": shape.vocab * shape.d_model,
}
for layer in range(shape.n_layer):
base = f"layers/{layer}"
counts.update(
{
f"{base}/rms_att.bin": shape.d_model,
f"{base}/rms_ffn.bin": shape.d_model,
f"{base}/wq.bin": shape.d_model * shape.attention_dim,
f"{base}/wk.bin": shape.d_model * shape.kv_dim,
f"{base}/wv.bin": shape.d_model * shape.kv_dim,
f"{base}/wo.bin": shape.d_model * shape.attention_dim,
f"{base}/bq.bin": shape.attention_dim,
f"{base}/bk.bin": shape.kv_dim,
f"{base}/bv.bin": shape.kv_dim,
f"{base}/w1.bin": shape.hidden_dim * shape.d_model,
f"{base}/w2.bin": shape.d_model * shape.hidden_dim,
f"{base}/w3.bin": shape.hidden_dim * shape.d_model,
}
)
return counts
def verify_native_directory(output_dir: Path, shape: QwenShape) -> None:
"""Re-read every blob header the way the Swift loader does."""
for relative, count in expected_counts(shape).items():
path = output_dir / relative
if not path.exists():
raise ConversionError(f"missing converted tensor {relative}")
with path.open("rb") as handle:
header = handle.read(128)
if len(header) != 128:
raise ConversionError(f"{relative} is shorter than a BLOBFILE header")
magic = struct.unpack_from("<I", header, 64)[0]
if magic != 0xDEADBEEF:
raise ConversionError(f"{relative} has magic {magic:#x}, expected 0xDEADBEEF")
data_offset = struct.unpack_from("<I", header, 80)[0]
if data_offset != 128:
raise ConversionError(f"{relative} has data offset {data_offset}, expected 128")
declared = struct.unpack_from("<I", header, 72)[0]
actual = path.stat().st_size - 128
if declared != actual:
raise ConversionError(f"{relative} declares {declared} payload bytes but holds {actual}")
if declared != count * 2:
raise ConversionError(
f"{relative} holds {declared // 2} fp16 values, expected {count}"
)
# ---------------------------------------------------------------------------
# Bundle packing
# ---------------------------------------------------------------------------
def pack_bundle(native_dir: Path, bundle_path: Path, context_target: int | None) -> None:
if bundle_path.exists():
shutil.rmtree(bundle_path)
command = [
"swift",
"run",
"--disable-sandbox",
"espc",
"pack-native",
str(native_dir),
str(bundle_path),
"--overwrite",
]
if context_target is not None:
command += ["--context-target", str(context_target)]
print(f"[pack] {' '.join(command)}", flush=True)
result = subprocess.run(command, cwd=REPO_ROOT)
if result.returncode != 0:
raise ConversionError(f"`espc pack-native` failed with exit code {result.returncode}")
# ---------------------------------------------------------------------------
# CLI
# ---------------------------------------------------------------------------
def parse_args(argv: list[str]) -> argparse.Namespace:
parser = argparse.ArgumentParser(description=__doc__, formatter_class=argparse.RawDescriptionHelpFormatter)
parser.add_argument(
"--model",
default=DEFAULT_MODEL,
choices=list(SUPPORTED_MODELS),
help=(
"Hugging Face repo to convert "
f"(default: {DEFAULT_MODEL})"
),
)
parser.add_argument(
"--output",
default=None,
help=(
"Path of the .esp bundle to write (default: "
"<cache>/qwen25-05b/Qwen2.5-0.5B-Instruct.esp for the default --model; "
"<cache>/qwen25-15b/Qwen2.5-1.5B-Instruct.esp for 1.5B)"
),
)
parser.add_argument(
"--native-dir",
default=None,
help="Where to stage the native model directory (default: alongside the bundle)",
)
parser.add_argument(
"--source-dir",
default=None,
help=(
"Where to cache downloaded safetensors if no complete Hugging Face snapshot "
"is present (default: <cache>/qwen25-05b-src or <cache>/qwen25-15b-src)"
),
)
parser.add_argument(
"--max-seq",
type=int,
default=1024,
help="Exported context length. Qwen2.5 advertises 32768; masks scale as maxSeq^2 (default: 1024)",
)
parser.add_argument(
"--fp32-sidecars",
choices=("none", "all"),
default="none",
help=(
"Write exact fp32 sidecars next to each fp16 blob. Use 'all' to separate "
"conversion error from fp16 rounding error in the parity report (default: none)"
),
)
parser.add_argument("--force-download", action="store_true", help="Re-download source files")
parser.add_argument("--skip-pack", action="store_true", help="Stop after writing the native directory")
parser.add_argument(
"--no-bootstrap",
action="store_true",
help="Fail instead of creating a managed venv when numpy is missing",
)
return parser.parse_args(argv)
def main(argv: list[str]) -> int:
args = parse_args(argv)
ensure_runtime_dependencies(allow_bootstrap=not args.no_bootstrap)
profile = SUPPORTED_MODELS[args.model]
cache_root = espresso_cache_root()
paths = default_paths(profile, cache_root)
explicit_source = Path(args.source_dir).expanduser() if args.source_dir else None
source_dir = resolve_source_dir(
repo=profile.repo,
explicit=explicit_source,
cache_root=cache_root,
source_slug=profile.source_slug,
force_download=args.force_download,
)
bundle_path = Path(args.output).expanduser() if args.output else paths.bundle
native_dir = Path(args.native_dir).expanduser() if args.native_dir else paths.native
if args.max_seq <= 0:
raise ConversionError("--max-seq must be > 0")
mask_limit = max_supported_mask_sequence_length()
if args.max_seq > mask_limit:
raise ConversionError(f"--max-seq {args.max_seq} exceeds the BLOBFILE mask limit {mask_limit}")
if args.force_download or not snapshot_is_complete(source_dir):
print(f"[source] downloading {profile.repo} into {source_dir}", flush=True)
download_source(profile.repo, source_dir, force=args.force_download)
else:
print(f"[source] {profile.repo} from {source_dir}", flush=True)
shape = read_shape(source_dir, profile.short_name)
validate_shape(shape, profile)
if args.max_seq > shape.max_position_embeddings:
raise ConversionError(
f"--max-seq {args.max_seq} exceeds the model context {shape.max_position_embeddings}"
)
print(
f"[shape] {shape.name}: {shape.n_layer}L d={shape.d_model} heads={shape.n_head}/{shape.n_kv_head} "
f"headDim={shape.head_dim} hidden={shape.hidden_dim} vocab={shape.vocab} "
f"ropeTheta={shape.rope_theta:g} eos={shape.eos_token}",
flush=True,
)
if native_dir.exists():
shutil.rmtree(native_dir)
stats = convert(
source_dir=source_dir,
output_dir=native_dir,
shape=shape,
max_seq=args.max_seq,
write_fp32_sidecars=args.fp32_sidecars == "all",
)
metadata = write_metadata(native_dir, shape, args.max_seq)
verify_native_directory(native_dir, shape)
overflowing = stats.overflowing()
if overflowing:
detail = ", ".join(f"{r.relative_path} ({r.fp16_overflow} values)" for r in overflowing[:4])
raise ConversionError(
"fp16 conversion overflowed to infinity for: " + detail +
". These weights cannot be served in fp16 without rescaling."
)
worst = stats.worst_fp16_error()
report = {
"model": profile.repo,
"metadata": metadata,
"nativeDirect...
FAQ
Common questions
Discussion
Questions & comments · 0
Sign In Sign in to leave a comment.