
Index and recall coding decisions across all AI agents
deja indexes coding-agent session history already on disk into one shared, redacted memory layer any agent can recall from.
0.21.5Add to Favorites
Why it matters
Give every coding agent on your machine shared memory by indexing all their past sessions from disk, so any agent can recall solutions, decisions, and working commands from conversations that happened months ago in different tools-without manual search or starting from scratch.
Outcomes
What it gets done
Index gigabytes of agent session history retroactively with millisecond lookup performance
Surface relevant past decisions automatically before file edits or command execution
Retrieve working command invocations when the same error occurs again
Provide cross-agent recall via MCP so Claude remembers what you solved in Cursor
Source
Get it from source
Spark does not host a copy of it.
Open sourceReports
Agent outcome reports
No reports yet
Capabilities
Tools your agent gets
MCP tool that retrieves relevant memory from agent history to answer questions
MCP tool that stores explicit facts and decisions in the notes source
Overview
deja-vu (deja) indexes the session history already written to disk by 25+ coding agents into one shared, redacted local memory layer, recalling automatically at session start, before risky actions, and after failed commands via an MCP recall tool, with lifecycle tracking for rejected decisions and cross-machine sync. Use it whenever an agent might re-solve something already settled in a prior session, in the same agent or a different one - it works from the binary alone, with MCP wiring and auto-recall as an optional install step.
What it does
deja indexes the session history that Claude Code, Codex, Cursor, and roughly twenty-two other coding agents already write to local disk, turning it into one shared memory layer any of them can read - starting full from day one rather than empty, since it indexes everything already on disk including sessions from before deja was installed. Its MCP recall tool answers "we fixed this three weeks ago" in whichever agent asks, regardless of which agent originally solved it, and recall arrives automatically at session start, on every prompt, before a file is edited or a command runs, and after a command fails - nobody has to search for it. It indexes the actual work, not just the conversation: which files each turn opened, which commands ran and their exit status, and the exact text spans an edit replaced, the parts a session summary throws away. Measured over 43 real compactions, a session summary keeps 77% of decisions and 0.2% of the commands that were run; deja hands back the other 99.8%. Published benchmarks: 85.3% hit@1 on LongMemEval-S, 69.6% on LoCoMo, both harnesses shipped in the repo and runnable on public datasets; on a real store of 1,551 sessions and 143k messages across 5.2GB and nine harnesses, a lookup runs about 0.4ms median in-process and an end-to-end query about 0.2s, with an index that's incrementally updated so only a changed session file gets re-read, sized at about 160MB, roughly 3% of the corpus.
When to use - and when NOT to
Use it whenever an agent is about to re-solve, re-debug, or re-explain something already settled in a prior session, in the same agent or a different one - it's meant to make cross-agent recall automatic rather than something the user has to remember to ask for. It stores a decision's lifecycle explicitly rather than deleting anything: marking a decision rejected records that it was tried and reverted, with the reason, and every later hit for that session shows it, while an accepted mark reverses that. A hit also reports when the ground has shifted, such as files touched this session having changed since, and stays silent rather than claiming something is unchanged when it can't tell. Semantic, embedding-based recall is optional: pointing deja embed at a local Ollama, LM Studio, or OpenAI-compatible endpoint via DEJA_EMBED_URL lets rephrased queries still hit, but lexical search and MCP recall work unchanged with no embedding runtime configured at all - a remote embedding endpoint receives only redacted, truncated indexed text, never raw source files, and OPENAI_API_KEY is only ever sent automatically to api.openai.com, never to a local or third-party endpoint.
Capabilities
The MCP server exposes one tool, deja, parameterized by a mode of recall, context, blame, fix, how, or remember (six older individual tool names still work for anything already wired to them). The CLI covers retroactive natural-language search across all indexed history, deja blame <path> for which sessions discussed a file and why, deja files <topic> for the reverse lookup, deja how <tool> for the actual invocation this machine has run before, deja fix <error> for what ran after that same error last time, and deja friction for errors that hit three or more separate sessions. Credentials are redacted at index time - AWS keys, api_key=/token= assignments, bearer tokens, raw JWTs, PEM blocks, provider tokens, credential-bearing URLs, and high-entropy unknown-shape values all become a redacted placeholder while the surrounding text stays searchable; sharing and export commands reapply that redaction on the way out. A forget command removes a session and writes a tombstone so a later reindex can't silently restore it, with an unforget option to lift it, and a config file holds one project-exclusion pattern per line. A sync command moves memory between machines append-only with no cloud in between, and a handoff command packages live context to continue work in a different agent. Twenty-five harnesses are supported in total, with matrix-documented per-harness support for MCP recall, auto-recall, a loadable skill, a CLI command, session resume, and handoff. deja stats --card draws a year of agent activity as a terminal heatmap, and can write it to an SVG file for a profile README or convert it to a PNG on the project's own web page; deja view renders the whole indexed history as one local, server-free HTML page.
How to install
curl -fsSL https://raw.githubusercontent.com/vshulcz/deja-vu/main/install.sh | sh
deja install --auto
The second command wires MCP recall into every detected agent, turns on session-start auto-recall where supported, and builds the first index. Alternative installs: brew install deja-vu, go install github.com/vshulcz/deja-vu/cmd/deja@latest, npx @vshulcz/deja-vu "query" to try without installing, scoop install deja-vu on Windows since the shell installer itself exits with an unsupported-OS error there, or each supported harness's own plugin marketplace. Indexing, search, and redaction all work from the binary alone with nothing wired in; the doctor command correctly reports every MCP target as not wired in that configuration, which is expected. Networking is used only for updates, machine-to-machine sync, and a version check - indexing and search stay entirely local otherwise.
Who it's for
Anyone running more than one coding agent, or the same agent across many project sessions, who is tired of re-explaining or re-debugging something already solved months earlier - especially useful for switching agents mid-project, recovering context after a crash or a session-history cleanup, or auditing what an agent actually did, such as files touched, commands run, and exit codes, rather than what a session summary claims it did. MIT licensed.
Source README
curl -fsSL https://raw.githubusercontent.com/vshulcz/deja-vu/main/install.sh | sh
deja install --auto


Highlights
- Starts full. Months of history from before you installed it are searchable on day one:
deja "connection pool exhausted"over gigabytes. - One memory, every agent. A fix found in Codex comes back in Claude Code, Cursor or opencode; all thirty-five agents read the same index.
- Nobody has to ask. Recall arrives at session start, before a file is edited or a command runs, and after a command fails.
- Survives compaction. Over 43 measured compactions the summary kept 77% of the decisions and 0.2% of the commands; deja hands back the rest (how).
- Indexes the work, not just the talk. The files each turn opened, the commands with their exit status, the exact spans an edit replaced.
- Knows what held.
deja promote <id> --state rejectedmarks a reverted decision, and every later hit says it was tried and why it was dropped;--state acceptedtakes the mark back. - Says when the ground moved. A hit reports 4 files this session touched have changed since, and stays quiet when it cannot tell.
- Local and private. No model, no embeddings, no server. Keys and tokens are stripped as the index is built (privacy).
- Moves with you.
deja sync ssh laptopbetween machines, no cloud in between;deja handoff --to codexto continue in another agent. - One Go binary. macOS, Linux and Windows, through Homebrew, Scoop, winget, npm or
go install.
Your own work, wrapped
deja stats --card draws it in the terminal; give it a filename and it writes an
SVG for a profile README. To post it anywhere else, turn it into a
PNG - that page converts it in your own
browser.

The full feature reference lives in the docs.
Install
The two commands at the top are the whole install on macOS and Linux:
curl -fsSL https://raw.githubusercontent.com/vshulcz/deja-vu/main/install.sh | sh
deja install --auto
Ten seconds to install, about ten to index, and it is useful. The second command wires MCP recall into every agent it finds, turns on session-start recall where the agent supports it, and builds the first index so the next session does not pay for it.
Start a new agent session and ask it something you worked on months ago:
have we dealt with jwt refresh rotation before? check your memory
It does not have to be asked, either - with auto-recall the agent already knows what you solved in that project when the session opens.
brew install deja-vu, go install github.com/vshulcz/deja-vu/cmd/deja@latest,
or npx @vshulcz/deja-vu "query" to try it without installing anything. Desktop apps that
take MCP servers as bundles can open the .mcpb from the
latest release; it carries the binary.
Claude Code, Cursor, Qwen and OpenClaw can take the same plugin bundle from
their own marketplaces instead (Codex has a bundle of its own, in the table under
Harnesses with a package of their own).
Copilot CLI installs it too but takes only the skill, so use deja install copilot-auto there:
claude plugin marketplace add vshulcz/deja-vu && claude plugin install deja-vu@deja-vu
On Windows the install script exits with unsupported OS - it is a shell script. Use
Scoop, from the main bucket every Scoop install already has, or winget, which ships with Windows:
scoop install deja-vu
winget install vshulcz.deja-vu
Or take deja-vu_<version>_windows_amd64.zip from the
latest release and put deja.exe on
your PATH, e.g. in %USERPROFILE%\.local\bin.
The binary alone is a complete install for searching: index, search, show, ctx, blame,
--json and redaction need nothing else. deja install is what wires MCP into your agents
and turns on session-start recall - worth having, and optional. On a binary-only setup
deja doctor reports every MCP target as not-wired, which is that setup working as
intended. deja warmup also leaves a skill at ~/.agents/skills/deja-search/SKILL.md
that teaches an agent the CLI contract - deja search --json, ctx, blame, how to read
tier and total - so it knows history is searchable without MCP. The copy in the repo is
skills/deja-search/SKILL.md.
deja install --all is --auto without the session-start recall: agents answer from memory
when they decide to call it, rather than starting each session with it. The
agent setup guide covers what each
harness supports, aider's read-only context file, and the Windows cmd /c deja mcp wrapper.
Install also writes user-level guidance for the harnesses it detects: Claude Code, Codex, opencode, Gemini CLI, Antigravity, Qwen, Kimi Code, pi, Senpi, Copilot, VS Code Copilot Chat, Cursor, Goose, OpenClaw, Hermes, Roo Code, omp, Amp, prime-agent, DeepSeek Harness, Continue, Crush and Zed each get it in their own guidance file (or under the configured XDG_CONFIG_HOME). Re-run rewrites deja's skill or marked block without changing surrounding user content. Use deja install --all --no-guidance to opt out; Grok Build gets the shared skill in ~/.agents/skills, which is what it reads; the ~/.grok/GROK.md written beside it is for the unrelated community CLI that shares that directory. Cursor has no user-level instructions file, so it gets the shared skill in ~/.agents/skills - one of the four places Cursor reads skills from - read only when something looks relevant rather than every session. Kilo Code, gajae-code, Command Code, Cherry Studio and Reasonix get the skill, and Kiro a steering file, from their own install target.
CLI
$ deja "jwt refresh token"
[claude] api        · Jul 8 · 8f31c0a9 — 2 matches
  login started failing after refresh token rotation; jwt kid mismatch in tests
  fixed by reloading jwks cache after rotateKey and adding a clock-skew test
[codex]  web        · Jul 1 · b77d91e2 — 1 match
  refresh token cookie needed SameSite=Lax in local callback flow
Ask your history
| Command | What it does |
|---|---|
deja <query> |
Search every history. Multi-word is AND and quoted phrases require contiguous text; a query with no exact match then tries word forms and close spellings, which is where a substring reaches its word (code finds opencode). |
deja |
With an index and a terminal: today's sessions, recalls served, a question you asked in more than one session, and a wall your agents keep hitting. |
deja wip |
What the last session in this directory was doing: the task, what it settled, the files in flight, the last command and whether it failed - derived from the transcript, not from a note someone remembered to write. |
deja blame <path>[:line] |
Which sessions discussed a file, what was decided, and why. With a line: the commit that last changed it, and the session that wrote that line or the text the commit replaced. --attribution prints the line answer alone, as JSON with --json, and --git-note records it in refs/notes/deja. |
deja files <topic> |
The other direction: which files the work on a subject actually touched. |
deja how <tool> |
How this machine actually runs a thing, with the real flags, from what agents ran before. |
deja fix <error> |
What this machine ran after that same error before, when the error did not come back. Never a merge, a force push or a deletion. |
deja friction |
Errors that hit three or more separate sessions, with the harnesses named. |
Use what it finds
| Command | What it does |
|---|---|
deja ctx <query> |
Markdown digest of the best match, ready to pipe into a prompt. |
deja resume <id> |
Reopen a found session in its native harness. |
deja restore <path> |
Hand back a span an agent replaced, from the old_string its edit recorded. Never writes over the original. |
deja promote <id> |
Distill a session into a curated note with provenance, tags and a lifecycle state. Notes outrank raw transcripts. |
deja share <id> |
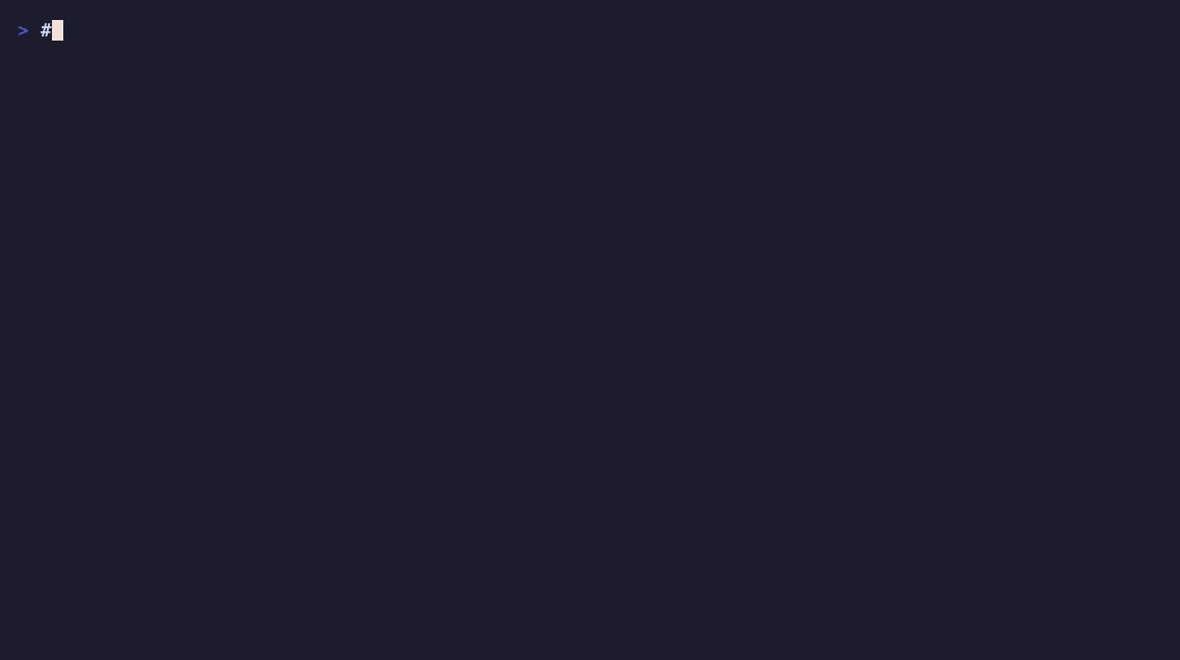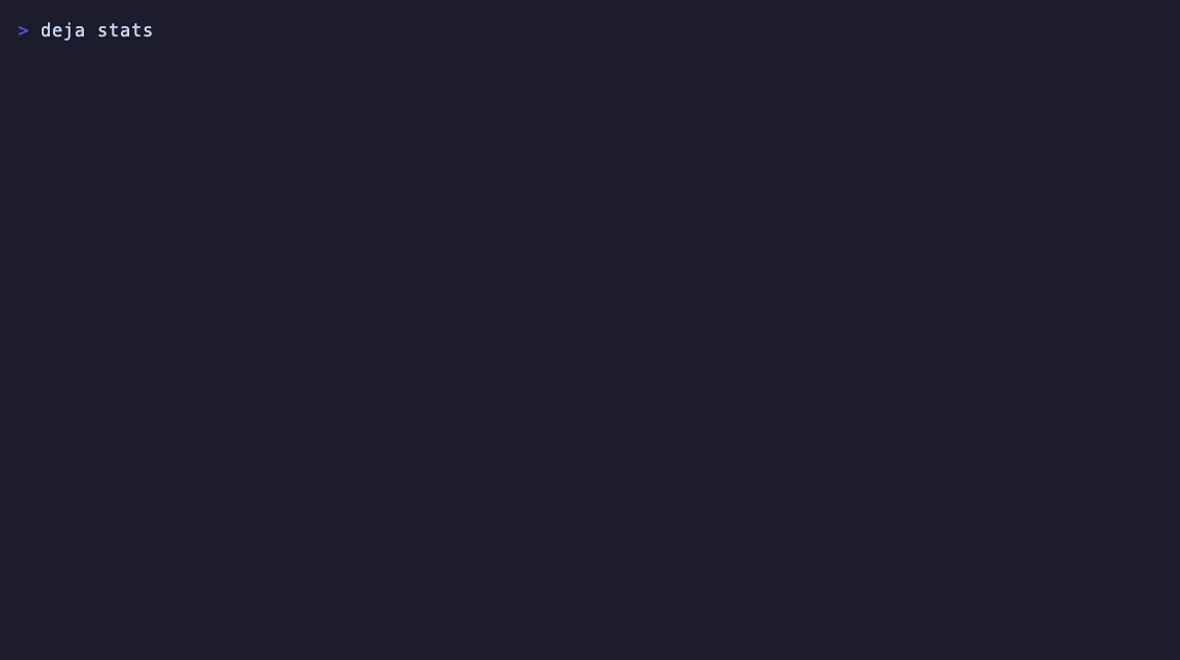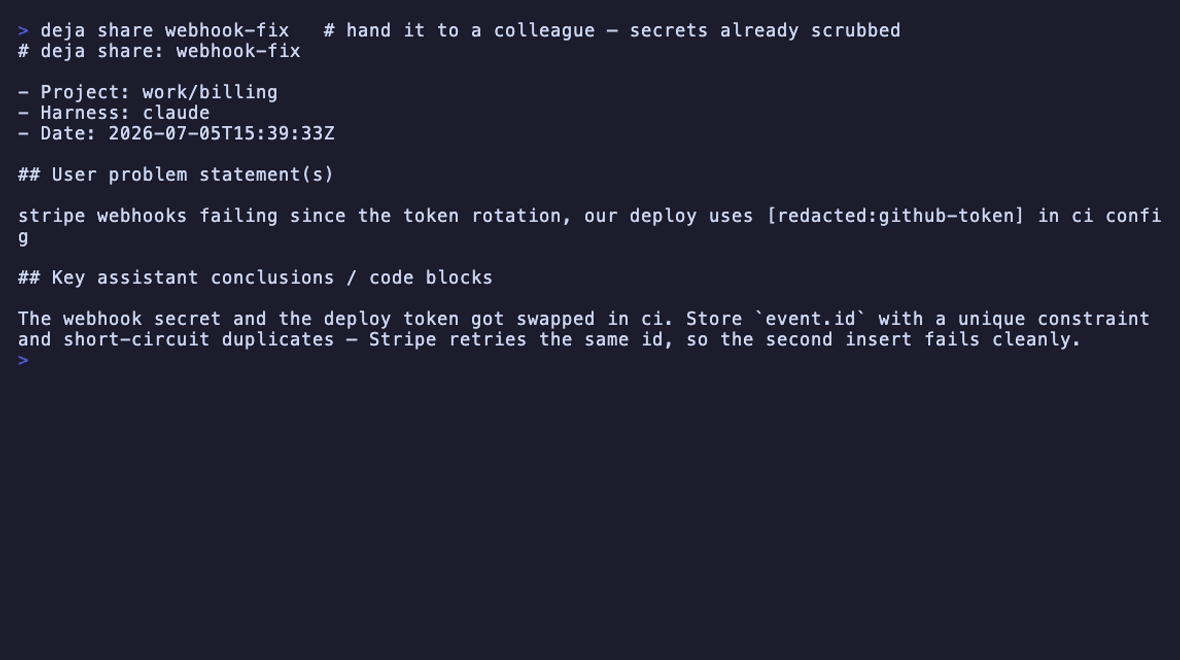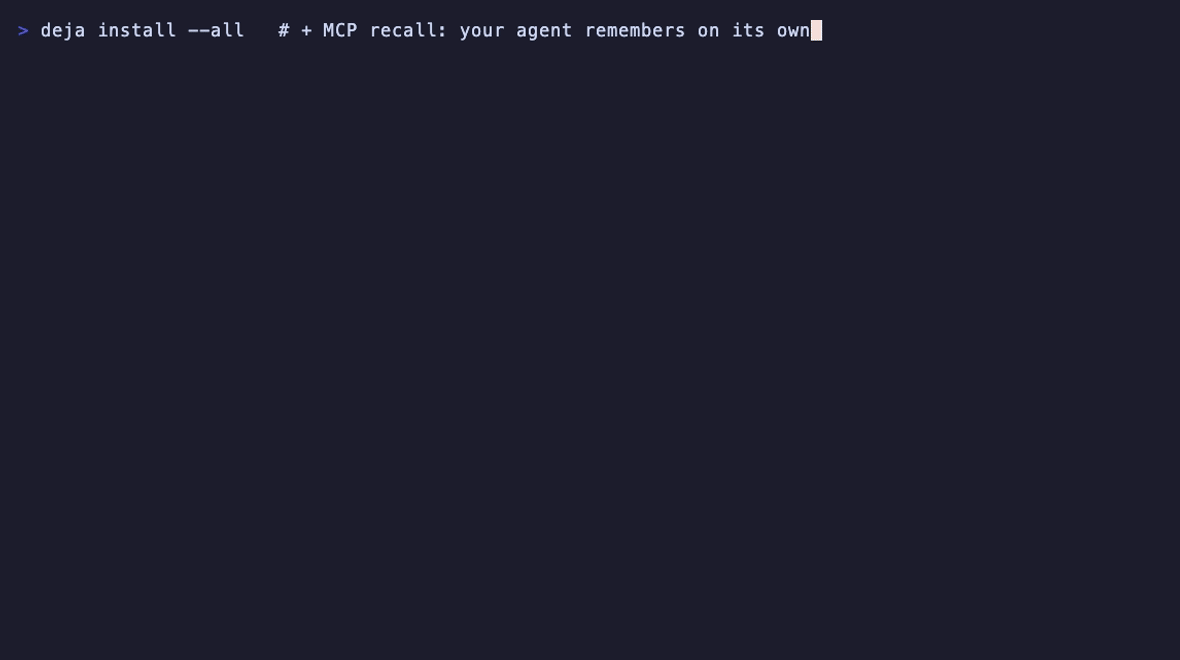
A sanitized session digest for a colleague, with secrets already scrubbed. |
Move it and check it
| Command | What it does |
|---|---|
deja sync export/import/ssh |
Move memory between machines. Watermarked, append-only, idempotent. |
deja view |
Your whole memory as one local HTML file. No server, and the file never leaves the machine. |
deja stats |
Your agent work, wrapped. --card draws it in the terminal, --card <file>.svg writes one for a profile, --html a browsable timeline. |
deja secrets [--scrub] |
Which sessions' source transcripts carry credentials, and what kind. Never prints a value. --scrub rewrites the ones it can, original kept beside the file. |
deja rules [sync] |
Keep your standing rules in ~/.config/deja/rules.md; sync copies them as a marked block into every installed agent's global rules file. |
deja rules candidates [--json] [--limit n] [--since 90d] |
The turns where you corrected an agent, across every tool, numbered with their session. Ask your agent to suggest rules and it groups them; nothing is written until you pick. |
deja doctor [--deep] |
Self-diagnosis, and with --deep, proof of the index against the sources. |
deja mcp |
The stdio MCP server, which is what deja install wires in. |
Full reference: commands and JSON output.
MCP tools
The server exposes one tool, deja, with a mode; deja install wires it in. One tool
costs 477 tokens of definitions a turn, against 8,283 for the largest of the seven servers
measured in day zero. The six
older tool names (recall, recall_context, blame, fix, how, remember) still answer.
| Tool | Arguments | Returns |
|---|---|---|
deja |
mode, q, harness?, project?, limit? |
Depends on the mode, below. |
q carries whatever the mode asks about. The per-mode names below are still
accepted; they are no longer declared, because the schema is read every turn
whether or not the tool is called.
| Mode | q is |
Also reads | Returns |
|---|---|---|---|
recall |
the question, or an exact error string, name or flag | harness?, limit?, offset? |
Dense matching snippets, capped at 4KB. |
context |
the same as recall | harness? |
Markdown digest of the best-matching session. |
blame |
a file path | harness?, project?, since?, limit?, all? |
Sessions that discussed a file. |
fix |
the failing output, verbatim | limit? |
What this machine ran, or changed, after that same error before. |
how |
the tool or target, e.g. go test |
project?, limit? |
The real invocation, from what agents ran here. |
orient |
nothing - it asks about the project | project?, limit? |
The commands past sessions ran here and the files they worked in. |
remember |
one durable fact or decision | project?, tags? |
Stores a durable decision for later recall. |
Supported harnesses
aider · Amp · Antigravity · Claude Code · Cline · Codex CLI · Copilot CLI · VS Code Copilot Chat · Cursor · DeepSeek Harness · Gemini CLI · Goose · Grok Build · Hermes · Kimi Code · omp (Oh My Pi) · OpenClaw · opencode · Continue · Crush · pi · prime-agent (PrimeIntellect) · Qwen Code · Cherry Studio · Senpi · gajae-code · Kimchi Coding · Command Code · ZCode · Kiro · Kilo Code · Roo Code · Zed · CodeWhale · Reasonix.
| Harness | MCP recall | Auto-recall | Skill | Command | Resume | Handoff | Needs |
|---|---|---|---|---|---|---|---|
| aider | ⚠ | ✅ | ✕ | ⚠ | ✕ | ✅ | deja aider |
| Amp | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | - |
| Antigravity | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | - |
| Claude Code | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | - |
| Cline | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | - |
| Codex CLI | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | - |
| Copilot CLI | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | - |
| VS Code Copilot Chat | ✅ | ✕ | ✅ | ✅ | ✕ | paste | - |
| Cursor | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | sqlite3 (IDE chats, CLI tool output) |
| DeepSeek Harness | ✅ | ✅ | ✅ | ✅ | ✕ | paste | zstd |
| Gemini CLI | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | - |
| Goose | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | deja goose |
| Grok Build | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | sqlite3 (grok-dev store) |
| Hermes | ✅ | ✅ | ✅ | ✅ | ✅ | paste | sqlite3 |
| Kimi Code | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | - |
| omp (Oh My Pi) | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | - |
| OpenClaw | ✅ | ✅ | ✅ | ✅ | ✅ | paste | sqlite3 (2026.8+ store); zstd for .zst archives |
| opencode | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | sqlite3 |
| Continue | ✅ | ⚠ | ✅ | ✅ | ✅ | paste | - |
| Crush | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | sqlite3 |
| pi | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | - |
| prime-agent (PrimeIntellect) | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | - |
| Qwen Code | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | - |
| Cherry Studio | ✅ | ✕ | ✅ | ✕ | ✕ | paste | import the server once in Settings -> MCP; enable the skill for the agent |
| Senpi | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | none |
| gajae-code | ✅ | ✅ | ✅ | ✅ | ✅ | paste | none |
| Kimchi Coding | ✅ | ⚠ | ⚠ | ⚠ | ✅ | paste | none |
| Command Code | ✅ | ✅ | ✅ | ✅ | ✅ | paste | none |
| ZCode | ✅ | ✅ | ? | ? | ✅ | paste | sqlite3 for the CLI database |
| Kiro | ✅ | ⚠ | ✕ | ? | ✅ | paste | sqlite3 for the CLI database |
| Kilo Code | ✅ | ⚠ | ✅ | ✅ | ✅ | paste | sqlite3 for the CLI store |
| Roo Code | ✅ | ⚠ | ✅ | ✅ | ✅ | paste | roo CLI (editor tasks reopen in the editor) |
| Zed | ✅ | ✕ | ✅ | ✅ | ✕ | paste | sqlite3 + zstd |
| CodeWhale | - | - | ? | ? | ✅ | paste | none |
| Reasonix | ✅ | ✅ | ✅ | ✅ | ✅ | paste | zstd for 1.x sessions |
✅ works · - possible, not built yet · ✕ the harness has no such mechanism · ⚠ waiting on the harness itself · ? not investigated
Custom store locations go through DEJA_*_ROOT variables, and each agent's own relocation
variable is honored too. The
session format registry documents
the observed paths, record schemas and role mapping per harness, with synthetic fixtures
keeping those descriptions checked against the parsers.
Harnesses with a package of their own
deja install --auto wires every one of these like every other harness, and
that stays the shortest path. They also have a package in their own ecosystem,
for people who install extensions there rather than from a CLI:
| Harness | Package | Install |
|---|---|---|
| opencode | npm opencode-deja |
opencode plugin opencode-deja |
| DeepSeek Harness | npm dsh-deja |
dsh plugin --profile web add dsh-deja |
| Zed | deja-context-server |
Zed → Extensions → deja |
| Kimi Code | plugin deja |
/plugins install https://github.com/vshulcz/deja-vu |
| Codex CLI | plugin deja-vu |
codex plugin marketplace add https://github.com/vshulcz/deja-vu then codex plugin add deja-vu@deja-vu |
| Grok Build | plugin deja |
grok plugin marketplace add xai-org/plugin-marketplace then grok plugin install deja |
| OpenClaw | ClawHub and npm @vshulcz/openclaw-deja |
openclaw plugins install clawhub:@vshulcz/openclaw-deja |
| pi (and omp) | npm @vshulcz/pi-deja |
pi install npm:@vshulcz/pi-deja |
| Hermes | memory provider deja-memory, in the Hermes plugin catalog |
hermes plugins install deja-vu, or from GitHub: hermes plugins install vshulcz/deja-vu/extensions/hermes |
Either path works alone, and both together double nothing: each package reads what
deja install already wrote and uses the deja you already have.
The same search is also a skill, for any agent that loads a SKILL.md:
npx skills add https://github.com/vshulcz/deja-vu --skill deja-search   # skills CLI: Claude Code, Cursor, Goose, Copilot…
openclaw skills install @vshulcz/deja-search                            # ClawHub
hermes skills install vshulcz/deja-vu/skills/deja-search                # Hermes
The skill drives the deja binary from the install step above; it does not bundle one.
Semantic recall (optional)
Point deja embed at a local Ollama, LM Studio or OpenAI-compatible endpoint with
DEJA_EMBED_URL and rephrased queries still hit. Without a reachable runtime, lexical
search and MCP recall continue unchanged. OpenAI Platform works with its standard key:
export OPENAI_API_KEY='sk-...'
export DEJA_EMBED_URL='https://api.openai.com/v1/embeddings'
export DEJA_EMBED_MODEL='text-embedding-3-small'
deja embed
With no DEJA_EMBED_URL set, deja probes localhost:11434 and localhost:1234,
so a machine already running Ollama or LM Studio is picked up without being asked.
DEJA_EMBED_OFF=1, or DEJA_EMBED_URL=off, turns that probe off - any other
configured DEJA_EMBED_URL still wins.
For another authenticated OpenAI-compatible endpoint, set DEJA_EMBED_KEY explicitly:
export DEJA_EMBED_URL='https://example.com/v1/embeddings'
export DEJA_EMBED_MODEL='embedding-model'
export DEJA_EMBED_KEY='...'
deja embed
DEJA_EMBED_KEY takes precedence. OPENAI_API_KEY is used automatically only for an
HTTPS api.openai.com URL; it is never implicitly sent to local or third-party endpoints.
The sidecar sits beside the index as .vectors.bin, not inside index.db. Float32 vectors
cost roughly 4 MB per 1k messages for a 1,024 dimension model. A remote endpoint receives
the redacted indexed text, truncated to about 2k characters, but never raw source files.
With Ollama or LM Studio, embedding stays local and needs no key.
Proof
Millisecond lookups, and on LongMemEval-S 88.1% hit@1 (470-question cleaned set) and 87.4% hit@1 on all 500 questions; on LoCoMo retrieval, 70.5% hit@1. On a task this machine had already solved, 58% fewer tokens: eleven runs an arm, 53,558 against 126,222 with nothing wired, and 52,815 against 103,443 on a later build with the arms alternated. Both retrieval harnesses ship in this repo and run on the public datasets in minutes: benchmarks · what one task costs.
The rest is measured by deja bench:
deja bench recall     # ranking floor: 100 queries, half Russian, CI fails if recall drops
deja bench context    # 30 seeded task chains plus five negative controls
deja bench block      # does the answer survive into what deja hands over
deja bench prompt     # what the per-prompt hook fires on, and what it fires on wrongly
deja bench ingest     # what an update costs: unchanged, a turn, a new transcript, a rename, a rewrite
deja bench read       # what it costs to read a database-backed store, and what one long value does to it
bench block asks the question the others cannot: with the right session in
hand, does the block carry what that session settled. Eight sessions discuss each
subject and one of them settles it, in the middle of its own transcript rather
than at the end - so the baseline arm, the newest turns of the top hit, scores
zero and an arm above zero had to choose.
| Arm | Carries the answer | Median tokens |
|---|---|---|
deja-block (session-start block) |
1.00 | 665 |
deja-digest (context digest) |
1.00 | 1656 |
newest-turn (baseline) |
0.00 | 289 |
cold |
0.00 | 0 |
The context experiment compares deja-recall against full-history, naive grep and cold context. With the default seed:
| Arm | Median tokens | Median coverage | Negative-control tokens |
|---|---|---|---|
| deja-recall | 1,096 | 1.00 | 0 |
| full-history | 80,547 | 1.00 | 78,145 |
| naive-grep | 273,238 | 1.00 | 0 |
| cold | 0 | 0.00 | 0 |
Same fact coverage as grepping the raw logs for about 250x fewer tokens, and about 70x fewer than replaying the matched sessions in full, while injecting nothing on the chains where no prior fact is relevant. The corpus generator and the relevance labels are ordinary reviewed Go. Audit what "relevant" means before trusting any figure, ours included.
Measured on a real store of 2,419 sessions and 179k messages, 1.9 GB of transcripts:
| Measurement | Result |
|---|---|
| Lookup, in process | 0.7-0.8 ms median (deja bench recall, 100 queries, half of them Russian), ~15 ms on the LongMemEval-S haystacks |
deja <query>, end to end |
~0.2 s median on that store: process start, the freshness check over every store, ranking, printing |
| Freshness check alone | ~50 ms when nothing changed |
| Index size | 200 MB, ~10% of corpus |
The same store has since grown to 2,754 sessions, 358k messages and 5.7 GB. A cold full build over it takes 71 s and writes a 232 MB index - 4% of the corpus, because the share falls as transcripts repeat themselves - and the end-to-end median is unchanged at 0.25 s.
The index is incremental. When a session file grows, only that file is re-read.
How it works
Local inverted index in ~/.cache/deja: parse the JSONL and SQLite stores, redact
credentials, write records.bin plus token buckets, and track per-file state in
manifest.gob so repeat runs only ingest what changed. The MCP server, stats, share and
sync all read that one index. Details in docs/ARCHITECTURE.md.
FAQ
No, unless you ask it to. See the data flows.
They stay in the original harness files, which
are your agent's data; deja secrets names the sessions that carry them so you can rotate
and delete, and --scrub rewrites the transcripts it can reach. Known shapes - AWS keys, api_key=/token= assignments, bearer
tokens and bare JWTs, PEM blocks, provider tokens, high-entropy values - are stripped as
the index is built, so they do not reach digests, shares or sync exports. Pattern matching
is not secret detection: a shape it does not know can pass through. See the
security model.
A recall is a lexical lookup against a local index: 0.7-0.8 ms median, and nothing waits on a model. A hook adds the process start and a freshness check over your stores on top of that - tens of milliseconds on a store of a few gigabytes.
No. The agent calls recall itself, and with auto-recall it already knows the project's prior decisions when the session opens.
| deja | Memory platforms (Mem0, Letta, memU) | Session search (cass) | |
|---|---|---|---|
| Knows work from before you installed it | yes | no | yes |
| Capture step | none, the transcripts are the memory | the agent or your code writes facts | none |
| Needs an LLM or embedding key | no | yes | optional |
| Recalls without being asked | at session start and before a tool runs | no | no |
engram is the strongest of the record-forward tools and worth your time if that model fits you; it still starts empty and knows only what an agent chose to save. The full comparison covers 15 of them.
Under
~/.claude/projects, one JSONL file per session; Codex keeps ~/.codex/sessions, Cursor a
SQLite state.vscdb. deja search reads them all in place, deja last lists the recent
sessions of every agent, and deja view opens the whole history as one local page. Paths
for each agent: where sessions are stored.
Claude Code deletes transcripts
older than 30 days (cleanupPeriodDays in ~/.claude/settings.json), and claude --resume lists
only what is left. A session deja indexed before the cleanup stays searchable after the
file is gone. Details: session files on disk.
Builds exist and CI runs the suite there. macOS and Linux are the battle-tested paths. Field reports welcome in #9.
deja uninstall --all
rm -rf ~/.cache/deja
Guides
Written for the situation rather than the feature:
- Does your agent remember previous conversations? - what each agent keeps between sessions, and what it drops
- Session files on disk - how big
~/.claude/projectsgets, and what deleting it costs - The agent lost the context you had - after a crash, a clear, or a session that came back empty
- The context window is full - what compaction keeps, measured, and what to do instead
- Resuming yesterday's session - find it across every agent, reopen it in the one that owns it
- The agent repeats a mistake you already fixed
- Finding the session where you solved it
- Why agents forget between sessions · Where each agent keeps its history
- What compaction drops · Switching agents · Auditing an agent · Exporting a conversation · Across machines · What memory costs
Per harness: opencode · DeepSeek Harness · Kimi Code · Zed · Grok Build · Gemini CLI · Qwen Code · OpenClaw · Goose · Cline · pi and omp · Hermes
Try it on your own history
curl -fsSL https://raw.githubusercontent.com/vshulcz/deja-vu/main/install.sh | sh
deja install --auto
Ten seconds to install, about ten to index. The next session your agent opens, it already knows what you solved in that project - including everything from before you installed this.
FAQ
Common questions
Discussion
Questions & comments · 0
Sign In Sign in to leave a comment.