
Manage Apache Druid Clusters with AI
MCP server for Apache Druid with profile-based tools to query, operate and diagnose clusters: SQL, ingestion, compaction, retention and health checks.
2.0.1Add to Favorites
Why it matters
Leverage AI assistants to manage and analyze your Apache Druid clusters. This asset provides a comprehensive Model Context Protocol (MCP) server with tools for data analysis, cluster management, and operational tasks.
Outcomes
What it gets done
List and detail Druid datasources and segments.
Execute SQL queries against Druid.
Manage Druid retention rules and compaction configurations.
Securely connect to Druid services with OAuth 2.0.
Source
Get it from source
Spark does not host a copy of it.
Open sourceReports
Agent outcome reports
No reports yet
Capabilities
Tools your agent gets
List all available Druid datasource names
Show detailed information for a specific datasource, including column information
Permanently delete a datasource, removing all data and metadata
List all available Druid lookups from the coordinator
Get the configuration for a specific lookup
Update the configuration for a specific lookup
List all segments across all datasources
Get metadata for specific segments
Overview
Druid MCP Server is a Model Context Protocol server for Apache Druid, providing tools, resources and prompts for managing and analyzing Druid clusters. It follows an intent-based architecture in which profiles map to areas of Druid usage, and tools are activated by the active Spring profiles: query, ops, permissions and health. Use it when an assistant should explore Druid data, troubleshoot ingestion, manage compaction and retention or check cluster health. The default query profile is read-only; the ops and permissions profiles can change the cluster.
What it does
The server exposes Apache Druid to AI assistants through three MCP component types: tools (executable functions), resources (data providers) and prompts (AI-assisted guidance templates). It follows an intent-based architecture in which profiles map to areas of Druid usage, and tools are activated by the active Spring profiles, set with SPRING_PROFILES_ACTIVE. It is pure Java on the Spring AI MCP server framework, generates JSON schemas for its tools automatically, supports STDIO, SSE and Streamable HTTP transports including OAuth, and offers customizable prompt templates. Ypipe (formerly Data-Philter), a local desktop application, uses this server as its conversational interface to a Druid cluster and works out of the box with the development Druid installation described below.
When to use - and when NOT to
Use it when an assistant needs to query or manage Apache Druid. The default query profile gives safe, read-only data querying and browsing. Enable ops for administrative control of ingestion specs, tasks, streaming supervisors, retention rules and compaction, health for active health checking, cluster status, diagnostics and doctor recommendation scans, and permissions for basic security authentication and authorization administration. The default profile set is stdio,query.
Take care with the write-capable profiles. In ops, manageDatasourceOrSegment can permanently drop a datasource (KILL_DATASOURCE) or disable segments, manageSupervisor can terminate a supervisor, shutdownTask kills a task, and manageCompaction, manageLookup and manageRetentionRules update or delete cluster configuration. The permissions tools can create and delete users and roles and set passwords. They are activated only when the permissions profile is on and the coordinator URL (druid.coordinator.url) is set and non-empty.
Streamable HTTP and SSE are secured with OAuth 2.0 by default, and clients must send a valid bearer token in the Authorization header. Setting DRUID_MCP_SECURITY_OAUTH2_ENABLED to false disables OAuth2, after which clients can access the server without tokens. In the Docker Streamable HTTP setup, a token comes from the client-credentials grant at /oauth2/token with the default client oidc-client and the secret secret. For enterprise SSO integration (OpenID Connect, Azure AD, Keycloak and others), send an inquiry to iunera. SSE is deprecated, is no longer the default and may be removed in a future version. The server collects anonymous usage metrics; set druid.mcp.metrics.enabled to false to opt out.
Capabilities
queryprofile:getDatasources(list datasources, or the schema of one),getLookups,getSegments,getSegmentLoadQueueandqueryDruidSql.opsprofile: compaction (getCompactionConfig,getCompactionStatus,manageCompactionwith UPSERT or DELETE),manageDatasourceOrSegment(ENABLE_SEGMENT, DISABLE_SEGMENT, KILL_DATASOURCE), lookups (manageLookup), multi-stage queries (queryDruidMultiStage, a variant taking a context JSON, and status and cancel tools), retention rules (getRetentionRules,manageRetentionRules),submitIngestion(submit a spec or generate a simple batch template), supervisors (getSupervisors,manageSupervisorwith SUSPEND, RESUME or TERMINATE), and tasks (getTasksfiltered by state,getTaskDetailsfor status, raw details, spec, reports or log, andshutdownTask). The fourhealthtools below are also part ofops.healthprofile:getClusterStatus,getNodesStatus,diagnoseCluster(COMPREHENSIVE, QUICK, PERFORMANCE or CONFIGURATION mode) andcheckFunctionalityHealth.permissionsprofile:manageAuthentication,manageAuthorizationandmanageSecurityAssignmentsfor users, roles, permissions and role assignments.
Resources use the URIs druid://datasource/{datasourceName}, its /details form with schema, druid://lookup/{tier}/{lookupName} and druid://segment/{segmentId}. Prompts cover data exploration, query optimization, health check, cluster overview, ingestion troubleshooting and setup, retention management, compaction suggestions and troubleshooting, emergency response and maintenance mode.
Automatic SQL syntax correction is on by default (DRUID_MCP_SQL_SYNTAX_CORRECTION_ENABLED): it formats queries, corrects casing and quotes identifiers, using cached table and column metadata whose TTL defaults to 300000 ms (DRUID_MCP_SQL_SYNTAX_CORRECTION_CACHE_TTL_MS).
Any prompt template can be overridden with a Java system property such as -Dprompts.druid-data-exploration.template=..., or through an additional properties file loaded with -Dspring.config.additional-location. Templates accept the variables {environment}, {organizationName}, {contactInfo}, {watermark}, {datasource} and {query}. Individual prompts are disabled with flags such as mcp.prompts.data-exploration.enabled=false, and all prompts with mcp.prompts.enabled=false.
How to install
A Druid cluster with the router on port 8888 must be running. Configuration is by environment variables, recommended for production: DRUID_ROUTER_URL, DRUID_COORDINATOR_URL, DRUID_AUTH_USERNAME, DRUID_AUTH_PASSWORD, DRUID_SSL_ENABLED and DRUID_SSL_SKIP_VERIFICATION. The same settings can be passed as JVM system properties such as -Ddruid.router.url. Credentials are sent as HTTP Basic authentication, Base64-encoded, with each request. For an SSL cluster use an HTTPS router URL with DRUID_SSL_ENABLED true; the system default truststore validates certificates, and DRUID_SSL_SKIP_VERIFICATION should be true only for testing.
Docker in STDIO mode, the default:
docker run --rm -i \
  -e DRUID_ROUTER_URL=http://your-druid-router:8888 \
  -e DRUID_COORDINATOR_URL=http://your-druid-coordinator:8081 \
  iunera/druid-mcp-server:latest
JBang is the recommended STDIO path for MCP clients: it manages the Java environment and downloads the required version, and the direct run is jbang druid-mcp-server@iunera/druid-mcp-server with the connection variables exported first. For HTTP mode with Docker, publish port 8080 and set SPRING_PROFILES_ACTIVE=http,query; this serves a single /mcp endpoint following MCP 2025-06-18, with concurrent clients, optional SSE streaming, Origin header validation, fallback for older MCP clients and configurable keep-alive. The server listens on port 8080 by default (SERVER_PORT). Further environment variables: SPRING_AI_MCP_SERVER_NAME sets the MCP server name and SPRING_AI_MCP_SERVER_PROTOCOL the protocol (for example streamable); SERVER_SERVLET_SESSION_COOKIE_NAME sets the session cookie name; SPRING_APPLICATION_NAME sets the application name; SPRING_CONFIG_IMPORT imports additional configuration files; SPRING_MAIN_BANNER_MODE sets the startup banner mode (for example off); LOGGING_FILE_NAME sets the log file name; LOGGING_LEVEL_ORG_SPRINGFRAMEWORK_SECURITY sets the Spring Security log level (for example DEBUG). To build from source, use Java 25 and Maven 3.6 or newer with mvn clean package -DskipTests and run the resulting JAR; the JAR can also be downloaded from Maven Central and needs only a Java 25 JRE. Apache License 2.0 licensed.
For local development and learning, the recommended way to get a full Druid cluster is the Docker Compose installer iunera/druid-local-cluster-installer. It runs the Coordinator, Broker, Historical, MiddleManager and Router services, installs with one command on macOS, Linux and Windows, ships sensible defaults and has basic security enabled with a pre-configured admin user (password password).
Source README
Druid MCP Server
A comprehensive Model Context Protocol (MCP) server for Apache Druid that provides extensive tools, resources, and prompts for managing and analyzing Druid clusters.
Developed by iunera - Advanced AI and Data Analytics Solutions
Overview
This MCP server implements a intend-based architecture where profiles picture their usaae intend and the corresponding area of Druid usage. The server provides three main types of MCP components:
- Tools - Executable functions for performing operations
- Resources - Data providers for accessing information
- Prompts - AI-assisted guidance templates
Video Walkthrough
Learn how to integrate AI agents with Apache Druid using the MCP server. This tutorial demonstrates time series data exploration, statistical analysis, and data ingestion using natural language with AI assistants like Claude, ChatGPT, and Gemini.

Click the thumbnail above to watch the video on YouTube
🌊 Y̊pipe: AI-Powered UI for Druid
Experience your data like never before with Y̊pipe (formerly Data-Philter), a local desktop application that makes offline AI practical, designed by iunera. It leverages this Druid MCP Server to provide a seamless, conversational interface for your Druid cluster.
- Natural Language Queries: Ask questions in plain English and get results instantly.
- Local & Secure: Runs completely locally with support for offline models (CPU/GPU).
- Plug & Play: Works out-of-the-box with the Development Druid Installation.

The easiest way to test iunera/druid-mcp-server is ypipe.com / https://github.com/iunera/ypipe
📋 Ypipe Integration Blueprint
For seamless integration, we provide a predefined Ypipe integration blueprint file:
- Blueprint File: druid.ypipe
- Configuration Guide: Ypipe Example Documentation
This blueprint allows you to easily connect and configure the Druid MCP server in Ypipe through a visual workspace.
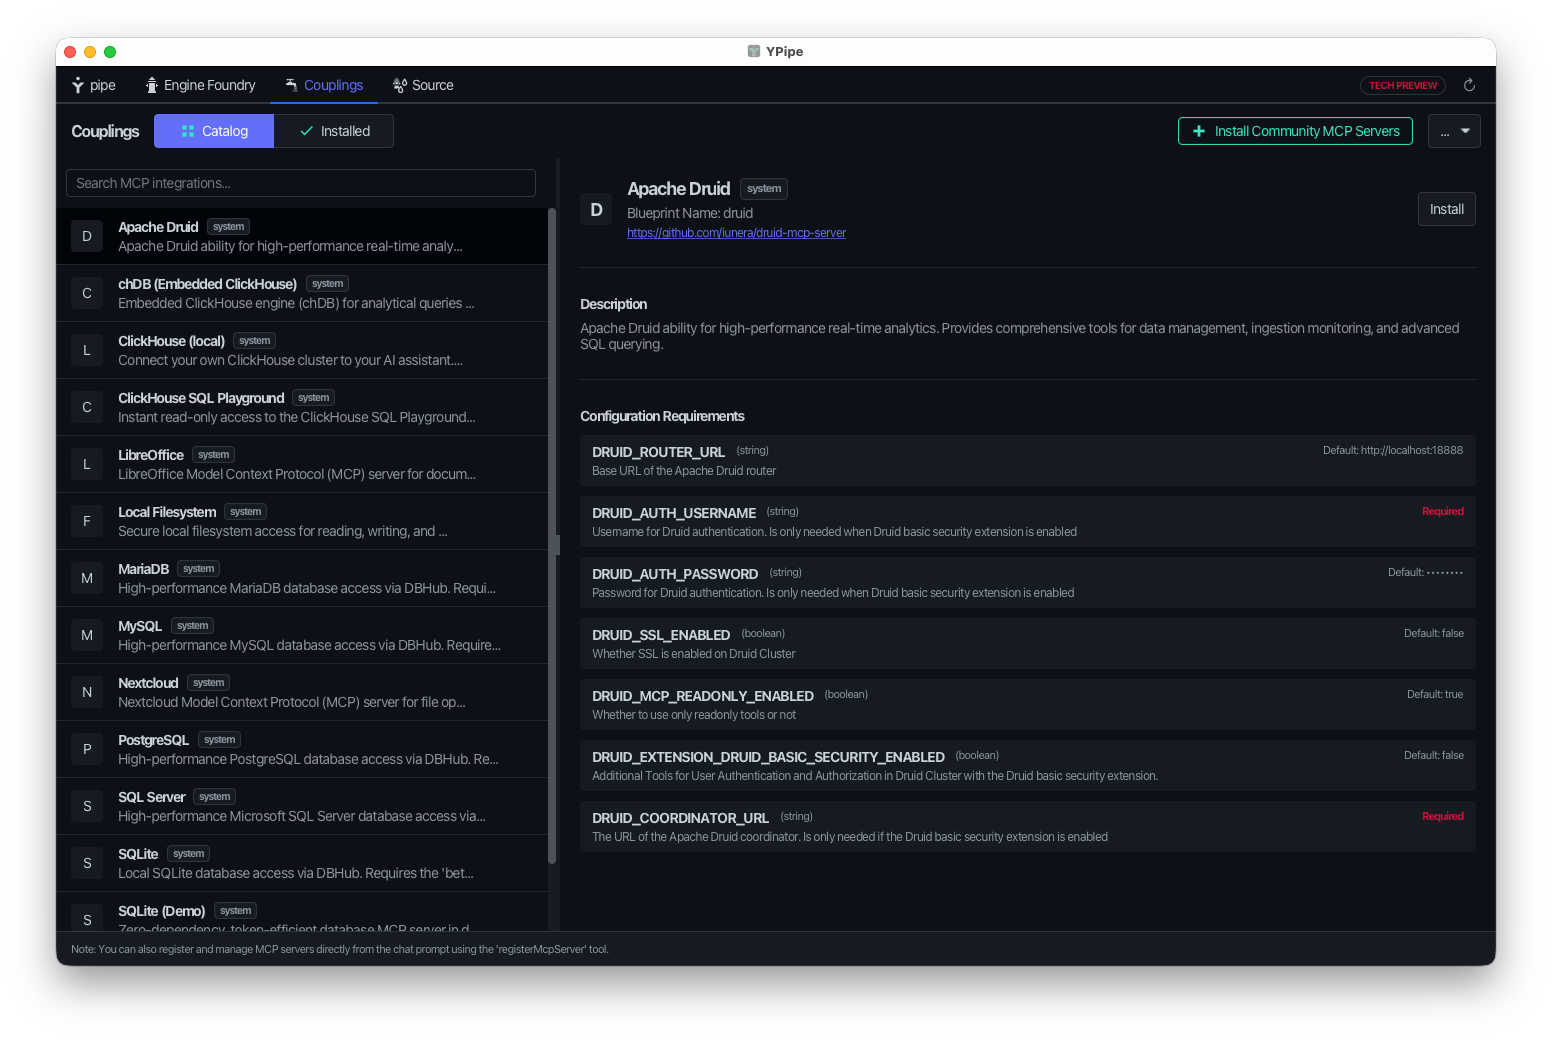
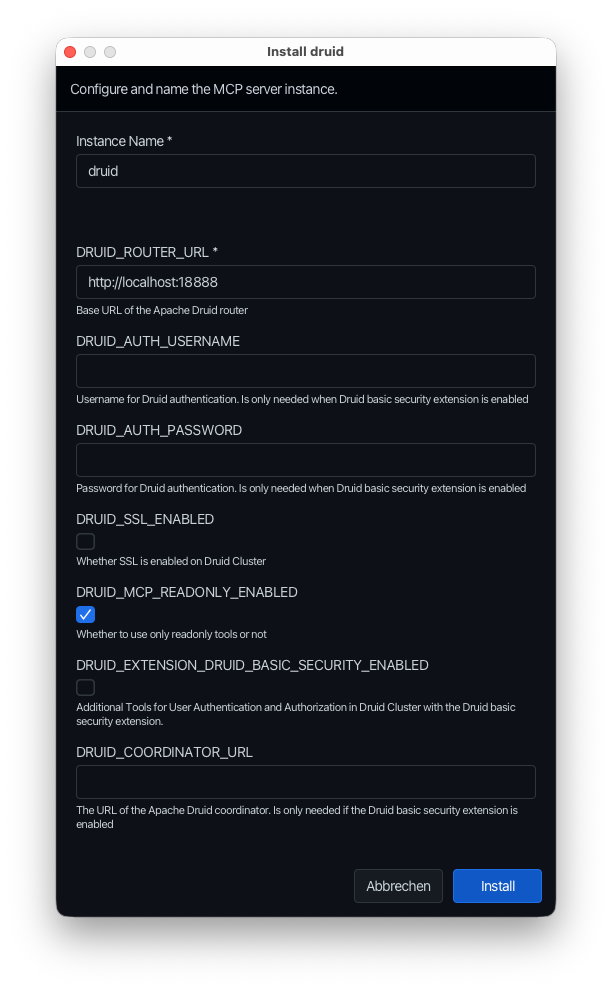
| Ypipe Workspace Flow | Druid Node Configuration |
|---|---|
 |
 |
Features
- Pure Java
- Spring AI MCP Server integration
- Tool-based architecture for MCP protocol compliance
- Tool-based Architecture: Complete MCP protocol compliance with automatic JSON schema generation
- Multiple Transport Modes: STDIO, SSE, and Streamable HTTP support including Oauth
- Real-time Communication: Server-Sent Events with streaming capabilities
- Comprehensive error handling
- Customizable Prompt Templates: AI-assisted guidance with template customization
- Comprehensive Error Handling: Graceful error handling with meaningful responses
- Enterprise Ready: Production-grade configuration and security features
MCP Inspector Interface
When connected to an MCP client, you can inspect the available tools, resources, and prompts through the MCP inspector interface:
Available Tools
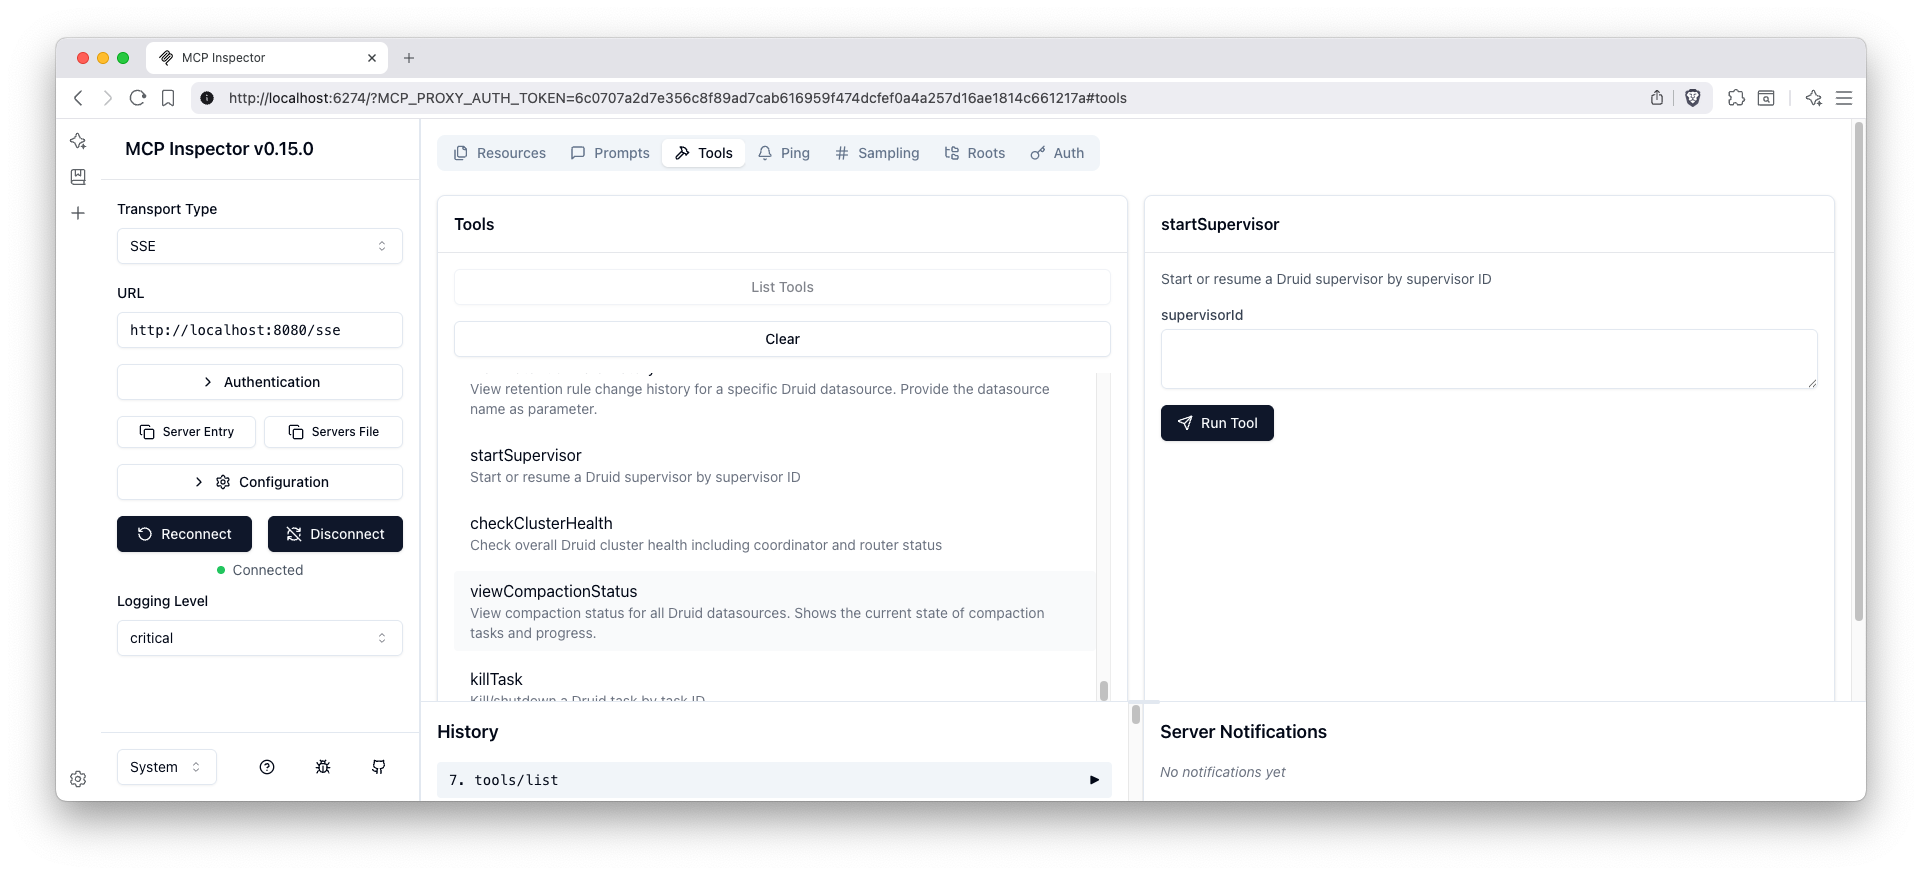
The tools interface shows all available Druid management functions organized by feature areas including data management, ingestion management, and monitoring & health.
Available Resources
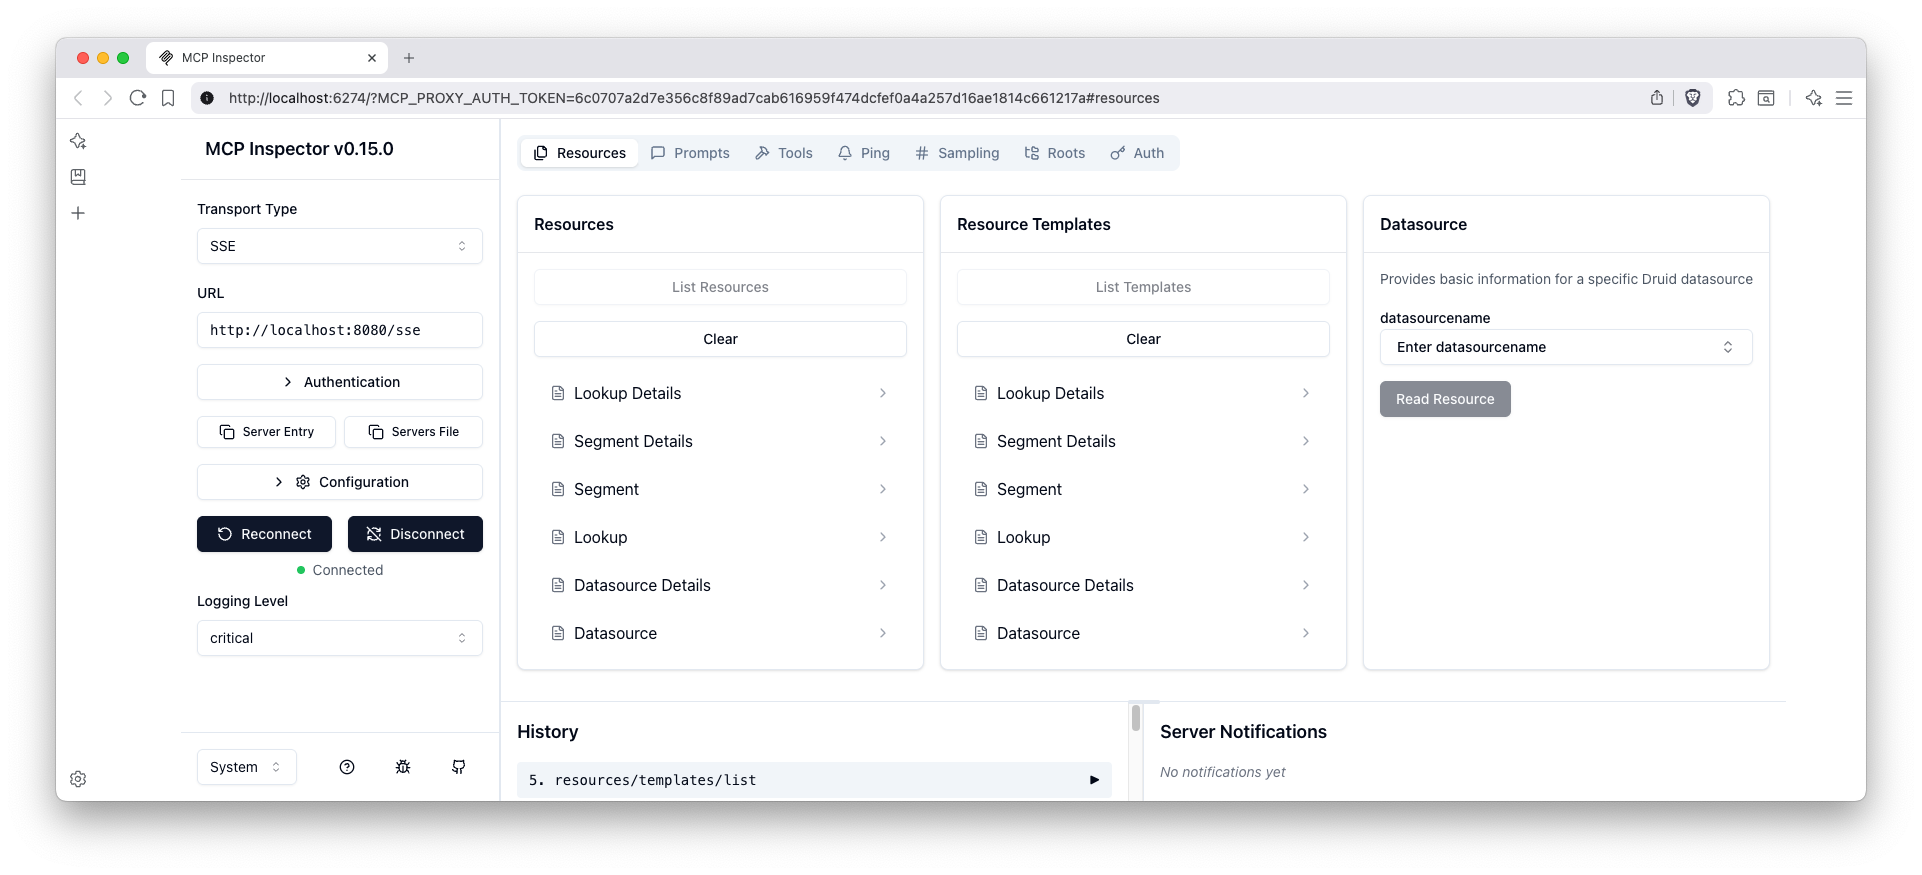
The resources interface displays all accessible Druid data sources and metadata that can be retrieved through the MCP protocol.
Available Prompts
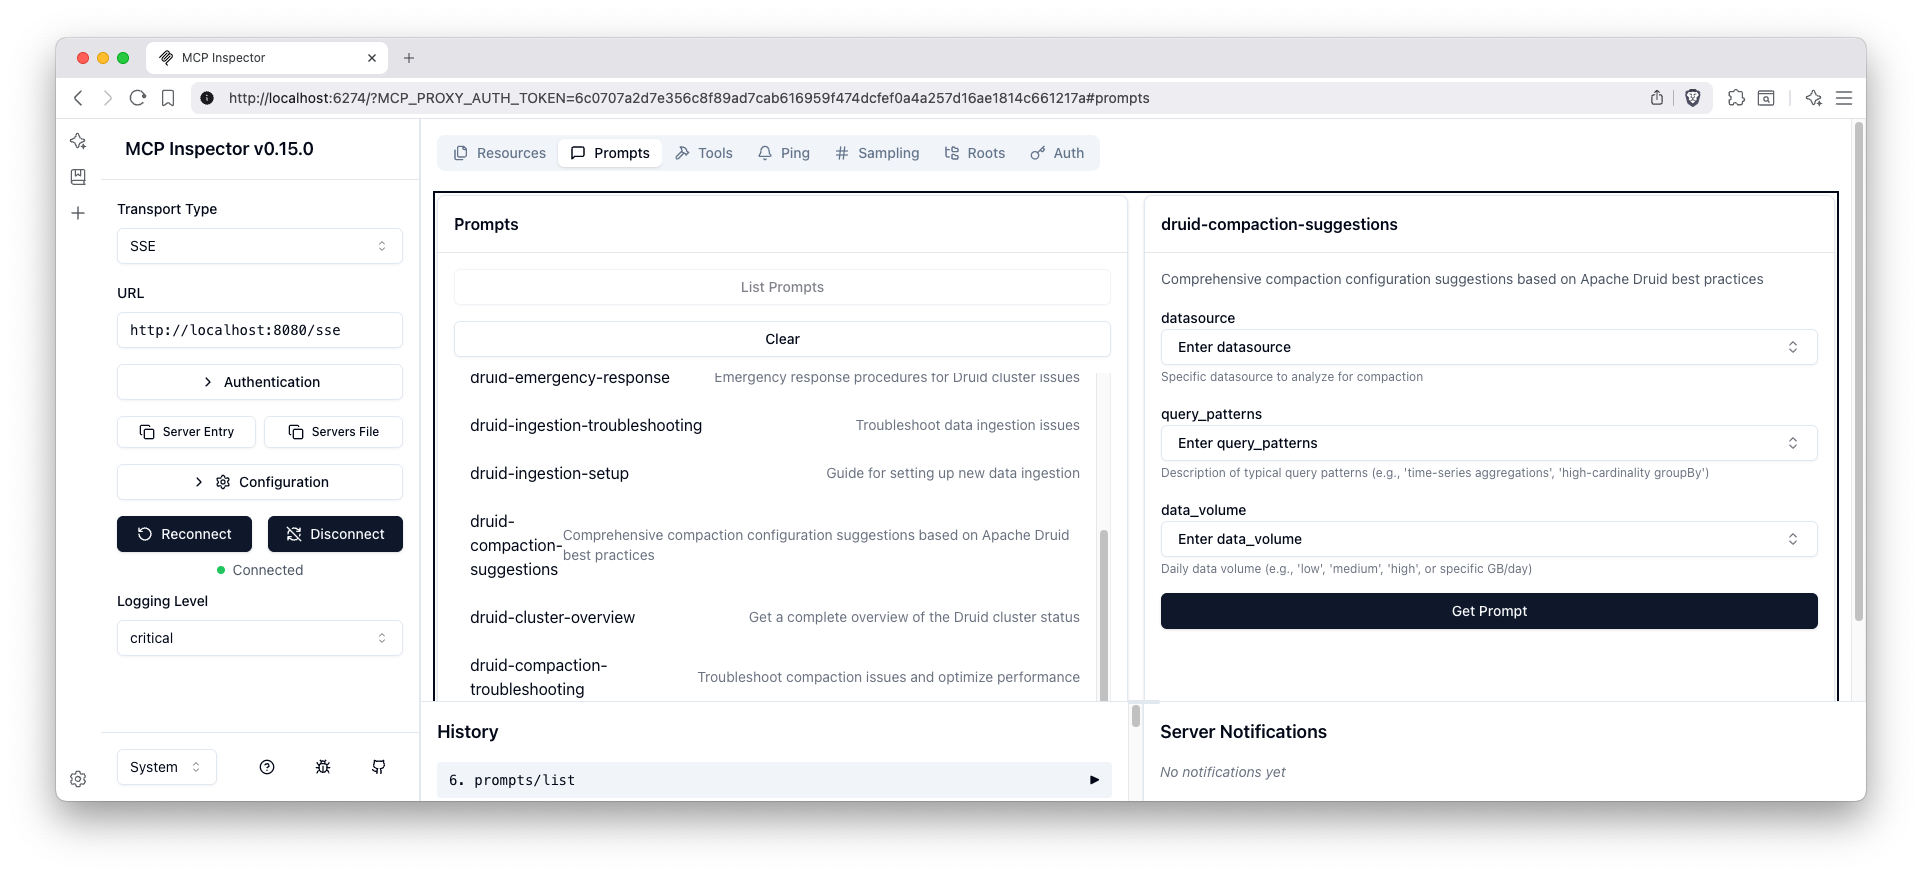
The prompts interface shows all AI-assisted guidance templates available for various Druid management tasks and data analysis workflows.
Quick Start
MCP Configuration for LLMs
A ready-to-use MCP configuration file is provided at mcp-servers-config.json that can be used with LLM clients to connect to this Druid MCP server.
Examples
The configuration includes multiple integration and transport options:
- STDIO (default): see examples/stdio/README.md - server is spawned by the MCP client over STDIO.
- Streamable HTTP (profile: http): see examples/streamable-http/README.md - single /mcp endpoint per MCP 2025-06-18.
- Ypipe Blueprint: see examples/ypipe/README.md - configure and run the Druid MCP Server inside the Ypipe desktop client using the druid.ypipe blueprint.
Docker examples using environment variables:
# STDIO mode (default)
docker run --rm -i \
  -e DRUID_ROUTER_URL=http://your-druid-router:8888 \
  -e DRUID_COORDINATOR_URL=http://your-druid-coordinator:8081 \
  iunera/druid-mcp-server:latest

# HTTP mode (enable profile 'http' and expose /mcp)
docker run -p 8080:8080 \
  -e SPRING_PROFILES_ACTIVE=http,query \
  -e DRUID_ROUTER_URL=http://your-druid-router:8888 \
  -e DRUID_COORDINATOR_URL=http://your-druid-coordinator:8081 \
  iunera/druid-mcp-server:latest
Note on Spring profiles:
- Default profile: stdio,query
- HTTP profile: set SPRING_PROFILES_ACTIVE=http,query to enable Streamable HTTP at /mcp
Prerequisites
- Java 25
- Maven 3.6+
- Apache Druid cluster running with router on port 8888
Build and Run
# Build the application
mvn clean package -DskipTests

# Run the application
java -jar target/druid-mcp-server-2.0.1.jar
The server will start on port 8080 by default.
For detailed build instructions, testing, Docker setup, and development guidelines, see development.md.
Security & Authentication
- Streamable HTTP and SSE transports are secured with OAuth 2.0 by default.
- Clients must send a valid Bearer token in the Authorization header when connecting.
- Example: Authorization: Bearer YOUR_JWT_TOKEN
Environment Variables
DRUID_MCP_SECURITY_OAUTH2_ENABLED:- Description: Enables or disables OAuth2 security for client authentication.
- Type: Boolean
- Default:
true(OAuth2 is enabled by default as per the text above) - Usage: Set to
falseto disable OAuth2 authentication. When disabled, clients can access the server without providing OAuth2 tokens.
- For enterprise SSO integration (OpenID Connect, Azure AD, Keycloak, etc.), please send an inquiry to consulting@iunera.com and see Contact & Support.
Installation from Maven Central
If you prefer to use the pre-built JAR without building from source, you can download and run it directly from Maven Central.
Prerequisites
- Java 25 JRE only
Download and Run
Download the JAR from Maven Central https://repo.maven.apache.org/maven2/com/iunera/druid-mcp-server/
# STDIO mode (default)
java -jar target/druid-mcp-server-2.0.1.jar

# HTTP mode (profile: http) - exposes /mcp on port 8080
java -Dspring.profiles.active=http \
     -jar target/druid-mcp-server-2.0.1.jar
For Developers
For detailed development information including build instructions, testing guidelines, architecture details, and contributing guidelines, see development.md.
Available Tools by Feature
The MCP server activates tools dynamically based on active Spring profiles (SPRING_PROFILES_ACTIVE). The default configuration runs the server in STDIO mode with the query profile enabled.
Profile: query (Default Active Profile)
Provides safe, read-only data querying and browsing capabilities.
| Tool | Description | Parameters | Druid API Endpoint / Functionality |
|---|---|---|---|
getDatasources |
List all available Apache Druid datasources or get detailed schema for a specific datasource. | datasourceName (String, optional), detailed (Boolean, optional) |
/druid/v2/sql (queries system catalogs like INFORMATION_SCHEMA.TABLES & COLUMNS) |
getLookups |
Get configuration or status of lookups for all or a specific tier. | tier (String, optional), lookupName (String, optional), includeStatus (Boolean, optional) |
/druid/coordinator/v1/lookups/config & /status endpoints |
getSegments |
Fetch segments metadata or details for a specific segment. | datasource (String, optional), segmentId (String, optional), detailed (Boolean, optional), metadataOnly (Boolean, optional) |
/druid/coordinator/v1/datasources/{ds}/segments & system tables (sys.segments via /druid/v2/sql) |
getSegmentLoadQueue |
Get the load queue status showing segments currently being loaded. | serverName (String, optional) |
/druid/coordinator/v1/loadqueue |
queryDruidSql |
Execute a SQL query against Druid datasources. | sqlQuery (String, required) |
/druid/v2/sql (Router / Broker SQL endpoint) |
Profile: ops
Provides administrative control over ingestion specs, tasks, streaming supervisors, retention rules, and compaction.
| Tool | Description | Parameters | Druid API Endpoint / Functionality |
|---|---|---|---|
getCompactionConfig |
View compaction configuration or configuration change history for datasources. | datasource (String, optional), includeHistory (Boolean, optional) |
/druid/coordinator/v1/config/compaction endpoints |
getCompactionStatus |
Retrieve the current status of compaction runs and progress. | datasource (String, optional) |
/druid/coordinator/v1/compaction/status |
manageCompaction |
Add, update, or remove a compaction configuration. | action (Enum: UPSERT, DELETE, required), datasource (String, required), configJson (String, optional) |
/druid/coordinator/v1/config/compaction (POST/DELETE) |
manageDatasourceOrSegment |
Modify segment states or permanently drop a datasource. | action (Enum: ENABLE_SEGMENT, DISABLE_SEGMENT, KILL_DATASOURCE, required), datasource (String, required), segmentId (String, optional), interval (String, optional) |
/druid/coordinator/v1/datasources & segment POST/DELETE |
manageLookup |
Create, update, or delete a lookup configuration. | action (Enum: UPSERT, DELETE, required), tier (String, required), lookupName (String, required), configJson (String, optional) |
/druid/coordinator/v1/lookups/config (POST/DELETE) |
queryDruidMultiStage |
Execute a multi-stage SQL query (MSQ) against Druid datasources as a task. | sqlQuery (String, required) |
/druid/v2/sql/task (MSQ execution endpoint) |
queryDruidMultiStageWithContext |
Execute a multi-stage SQL query with custom context parameters. | sqlQuery (String, required), contextJson (String, optional) |
/druid/v2/sql/task with context configurations |
getMultiStageQueryTaskStatus |
Get the status of a multi-stage query task. | taskId (String, required) |
/druid/indexer/v1/task/{taskId}/status |
cancelMultiStageQueryTask |
Cancel a running multi-stage query task. | taskId (String, required) |
/druid/indexer/v1/task/{taskId}/shutdown (POST) |
getRetentionRules |
Retrieve retention rules or audit history for a specific datasource or all datasources. | datasource (String, optional), includeHistory (Boolean, optional) |
/druid/coordinator/v1/rules |
manageRetentionRules |
Update retention rules configuration for a specific datasource. | datasource (String, required), rulesJson (String, required) |
/druid/coordinator/v1/rules |
submitIngestion |
Submit a Druid ingestion specification or generate a simple batch template. | action (Enum: SUBMIT_SPEC, GENERATE_TEMPLATE, required), payloadJson (String, optional), datasourceName (String, optional), inputSourceType (String, optional), inputSourcePath (String, optional) |
/druid/indexer/v1/task (POST) |
getSupervisors |
List all supervisors or query details of a specific supervisor. | supervisorId (String, optional) |
/druid/indexer/v1/supervisor |
manageSupervisor |
Suspend, resume, or terminate a supervisor's execution. | supervisorId (String, required), action (Enum: SUSPEND, RESUME, TERMINATE, required) |
/druid/indexer/v1/supervisor/{id}/(suspend/resume/terminate) |
getTasks |
List ingestion tasks matching specific states. | state (Enum: RUNNING, PENDING, WAITING, COMPLETED, optional) |
/druid/indexer/v1/runningTasks, pendingTasks, waitingTasks, completeTasks |
getTaskDetails |
Fetch detailed information, specifications, execution reports, or execution logs for a task. | taskId (String, required), aspect (Enum: STATUS, RAW_DETAILS, SPEC, REPORTS, LOG, required), logOffset (Long, optional) |
/druid/indexer/v1/task/{id} spec, status, reports, and log endpoints |
shutdownTask |
Kill/shutdown a Druid task. | taskId (String, required) |
/druid/indexer/v1/task/{id}/shutdown (POST) |
getClusterStatus |
Check overall health or fetch specific metadata/properties from coordinators or routers. | aspect (Enum: OVERALL, COORDINATOR, ROUTER, LEADER, METADATA, PROPERTIES, SELF_DISCOVERY_COORDINATOR, SELF_DISCOVERY_ROUTER, optional) |
/status/health, /status/selfDiscovered, /druid/coordinator/v1/leader, /druid/coordinator/v1/config |
getNodesStatus |
List registered servers, their detailed status, or single node status. | serverName (String, optional), detailed (Boolean, optional) |
/druid/coordinator/v1/servers & /status |
diagnoseCluster |
Perform automated diagnostic health checks, configuration audits, or query performance analysis. | mode (Enum: COMPREHENSIVE, QUICK, PERFORMANCE, CONFIGURATION, required) |
Orchestrates diagnostic sweeps over active tasks, servers status, segment counts, and APIs |
checkFunctionalityHealth |
Validate operations of ingestion systems, supervisor state transitions, and historical query latency. | component (Enum: ALL, SUPERVISORS, HISTORICALS, INGESTION, optional), quick (Boolean, optional) |
Orchestrates checks over task execution logs and supervisor statuses |
Profile: permissions
Provides basic security authentication and authorization administration.
| Tool | Description | Parameters | Druid API Endpoint / Functionality |
|---|---|---|---|
manageAuthentication |
Administer basic security users and credentials. | authenticator (String, required), action (Enum: LIST, GET, CREATE, DELETE, SET_PASSWORD, required), username (String, optional), password (String, optional) |
/druid-ext/basic-security/authentication/db/... |
manageAuthorization |
Manage security authorization properties, roles, and resource access policies. | authorizer (String, required), action (Enum: LIST_USERS, GET_USER, CREATE_USER, DELETE_USER, LIST_ROLES, GET_ROLE, CREATE_ROLE, DELETE_ROLE, SET_PERMISSIONS, required), name (String, optional), permissionsJson (String, optional) |
/druid-ext/basic-security/authorization/db/... |
manageSecurityAssignments |
Configure mapping rules assigning roles to users, or retrieve the configured authenticator chains. | authorizer (String, required), action (Enum: ASSIGN_ROLE, UNASSIGN_ROLE, GET_CHAIN, required), username (String, optional), roleName (String, optional) |
/druid-ext/basic-security/authorization/db/... & /status/properties |
Profile: health
Provides active health checking, cluster status, diagnostics, and doctor recommendation scans.
| Tool | Description | Parameters | Druid API Endpoint / Functionality |
|---|---|---|---|
getClusterStatus |
Check overall health or fetch specific metadata/properties from coordinators or routers. | aspect (Enum: OVERALL, COORDINATOR, ROUTER, LEADER, METADATA, PROPERTIES, SELF_DISCOVERY_COORDINATOR, SELF_DISCOVERY_ROUTER, optional) |
/status/health, /status/selfDiscovered, /druid/coordinator/v1/leader, /druid/coordinator/v1/config |
getNodesStatus |
List registered servers, their detailed status, or single node status. | serverName (String, optional), detailed (Boolean, optional) |
/druid/coordinator/v1/servers & /status |
diagnoseCluster |
Perform automated diagnostic health checks, configuration audits, or query performance analysis. | mode (Enum: COMPREHENSIVE, QUICK, PERFORMANCE, CONFIGURATION, required) |
Orchestrates diagnostic sweeps over active tasks, servers status, segment counts, and APIs |
checkFunctionalityHealth |
Validate operations of ingestion systems, supervisor state transitions, and historical query latency. | component (Enum: ALL, SUPERVISORS, HISTORICALS, INGESTION, optional), quick (Boolean, optional) |
Orchestrates checks over task execution logs and supervisor statuses |
Available Resources by Feature
| Feature | Resource URI Pattern | Description | Parameters |
|---|---|---|---|
| Datasource | druid://datasource/{datasourceName} |
Access datasource information and metadata | datasourceName (String) |
| Datasource | druid://datasource/{datasourceName}/details |
Access detailed datasource information including schema | datasourceName (String) |
| Lookup | druid://lookup/{tier}/{lookupName} |
Access lookup configuration and data | tier (String), lookupName (String) |
| Segments | druid://segment/{segmentId} |
Access segment metadata and information | segmentId (String) |
Available Prompts by Feature
| Feature | Prompt Name | Description | Parameters |
|---|---|---|---|
| Data Analysis | data-exploration |
Guide for exploring data in Druid datasources | datasource (String, optional) |
| Data Analysis | query-optimization |
Help optimize Druid SQL queries for better performance | query (String) |
| Cluster Management | health-check |
Comprehensive cluster health assessment guidance | None |
| Cluster Management | cluster-overview |
Overview and analysis of cluster status | None |
| Ingestion Management | ingestion-troubleshooting |
Troubleshoot ingestion issues | issue (String, optional) |
| Ingestion Management | ingestion-setup |
Guide for setting up new ingestion pipelines | dataSource (String, optional) |
| Retention Management | retention-management |
Manage data retention policies | datasource (String, optional) |
| Compaction | compaction-suggestions |
Optimize segment compaction configuration | datasource (String, optional), currentConfig (String, optional), performanceMetrics (String, optional) |
| Compaction | compaction-troubleshooting |
Troubleshoot compaction issues | issue (String), datasource (String, optional) |
| Operations | emergency-response |
Emergency response procedures and guidance | None |
| Operations | maintenance-mode |
Cluster maintenance procedures | None |
Environment Variables Configuration
The application can be configured using environment variables, which is the recommended approach for production environments. Below is a comprehensive list of supported environment variables derived from the application.yaml configuration file.
Druid Connection
DRUID_ROUTER_URL: The URL of the Druid router.DRUID_AUTH_USERNAME: The username for Druid authentication.DRUID_AUTH_PASSWORD: The password for Druid authentication.DRUID_SSL_ENABLED: Enables or disables SSL for Druid connections (true/false).DRUID_SSL_SKIP_VERIFICATION: Skips SSL certificate verification (true/false).DRUID_MCP_SQL_SYNTAX_CORRECTION_ENABLED: Enables or disables automatic SQL syntax correction (default:true). When enabled, automatically formats queries, corrects casing, and quotes identifiers for Druid.DRUID_MCP_SQL_SYNTAX_CORRECTION_CACHE_TTL_MS: The Time-To-Live (TTL) in milliseconds for the cached table and column metadata loaded from Druid (default:300000/ 5 minutes).
MCP Server Configuration
DRUID_MCP_SECURITY_OAUTH2_ENABLED: Enables or disables OAuth2 security for HTTP client authentication (true/false).SPRING_PROFILES_ACTIVE: Comma-separated list of profiles to activate (e.g.query,ops,permissions,healthfor tools capabilities, orhttpto enable HTTP server transport instead of default STDIO).SPRING_AI_MCP_SERVER_NAME: The name of the MCP server.SPRING_AI_MCP_SERVER_PROTOCOL: The protocol used by the MCP server (e.g.,streamable).
General Server Configuration
SERVER_PORT: The port the server listens on.SERVER_SERVLET_SESSION_COOKIE_NAME: The name of the session cookie.SPRING_APPLICATION_NAME: The name of the application.SPRING_CONFIG_IMPORT: Imports additional configuration files.SPRING_MAIN_BANNER_MODE: The mode for the startup banner (e.g.,off).
Logging
LOGGING_FILE_NAME: The name of the log file.LOGGING_LEVEL_ORG_SPRINGFRAMEWORK_SECURITY: The log level for Spring Security (e.g.,DEBUG).
SSL-Encrypted Cluster with Authentication
This section provides comprehensive guidance on connecting to SSL-encrypted Druid clusters with username and password authentication.
Prerequisites
- SSL-enabled Druid cluster with HTTPS endpoints
- Valid username and password credentials for Druid authentication
- SSL certificates properly configured (or ability to skip verification for testing)
Configuration Methods
Method 1: Environment Variables (Recommended for Production)
Set the following environment variables before starting the MCP server:
# Druid cluster URL with HTTPS
export DRUID_ROUTER_URL="https://your-druid-cluster.example.com:8888"

# Authentication credentials
export DRUID_AUTH_USERNAME="your-username"
export DRUID_AUTH_PASSWORD="your-password"

# SSL configuration
export DRUID_SSL_ENABLED="true"
export DRUID_SSL_SKIP_VERIFICATION="false"  # Use "true" only for testing

# Start the MCP server
java -jar target/druid-mcp-server-2.0.1.jar
Method 2: Runtime System Properties
Pass configuration as JVM system properties:
java -Ddruid.router.url="http://localhost:8888" \
     -Ddruid.auth.username="admin" \
     -Ddruid.auth.password="password" \
     -jar target/druid-mcp-server-2.0.1.jar
SSL Configuration Options
Production SSL Setup
For production environments with valid SSL certificates:
export DRUID_ROUTER_URL="https://druid-prod.company.com:8888"
export DRUID_SSL_ENABLED="true"
export DRUID_SSL_SKIP_VERIFICATION="false"
The server will use the system's default truststore to validate SSL certificates.
Authentication Methods
The MCP server supports HTTP Basic Authentication with username and password:
- Username: Set via
DRUID_AUTH_USERNAMEordruid.auth.username - Password: Set via
DRUID_AUTH_PASSWORDordruid.auth.password
The credentials are automatically encoded using Base64 and sent with each request using the Authorization: Basic header.
MCP Client Configuration with SSL
Update your mcp-servers-config.json to include environment variables:
{
  "mcpServers": {
    "druid-mcp-server": {
      "command": "docker",
      "args": [
        "run",
        "--rm",
        "-i",
        "-e",
        "DRUID_ROUTER_URL",
        "-e",
        "DRUID_COORDINATOR_URL",
        "-e",
        "DRUID_AUTH_USERNAME",
        "-e",
        "DRUID_AUTH_PASSWORD",
        "-e",
        "DRUID_SSL_ENABLED",
        "-e",
        "DRUID_SSL_SKIP_VERIFICATION",
        "iunera/druid-mcp-server:2.0.1"
      ],
      "env": {
        "DRUID_ROUTER_URL": "http://host.docker.internal:8888",
        "DRUID_COORDINATOR_URL": "http://host.docker.internal:8081",
        "DRUID_AUTH_USERNAME": "",
        "DRUID_AUTH_PASSWORD": "",
        "DRUID_SSL_ENABLED": "false",
        "DRUID_SSL_SKIP_VERIFICATION": "true"
      }
    }
  }
}
MCP Prompt Customization
The server provides extensive prompt customization capabilities through the prompts.properties file located in src/main/resources/.
Prompt Configuration Structure
The prompts.properties file contains:
- Global Settings: Enable/disable prompts and set watermarks
- Feature Toggles: Control which prompts are available
- Custom Variables: Organization-specific information
- Template Definitions: Full prompt templates for each feature
Overriding Prompts
You can override any prompt template using Java system properties with the -D flag:
Method 1: System Properties (Runtime Override)
java -Dprompts.druid-data-exploration.template="Your custom template here" \
     -jar target/druid-mcp-server-2.0.1.jar
Method 2: Custom Properties File
- Create a custom properties file (e.g.,
custom-prompts.properties):
# Custom prompt template
prompts.druid-data-exploration.template=My custom data exploration prompt:\n\
1. Custom step one\n\
2. Custom step two\n\
{datasource_section}\n\
Environment: {environment}
- Load it at runtime:
java -Dspring.config.additional-location=classpath:custom-prompts.properties \
     -jar target/druid-mcp-server-2.0.1.jar
Available Prompt Variables
All prompt templates support these variables:
| Variable | Description | Example |
|---|---|---|
{environment} |
Current environment name | production, staging, dev |
{organizationName} |
Organization name | Your Organization |
{contactInfo} |
Contact information | your-team@company.com |
{watermark} |
Generated watermark | Generated by Druid MCP Server v1.0.0 |
{datasource} |
Datasource name (context-specific) | sales_data |
{query} |
SQL query (context-specific) | SELECT * FROM sales_data |
Prompt Template Examples
Custom Data Exploration Prompt
prompts.druid-data-exploration.template=Welcome to {organizationName} Druid Analysis!\n\n\
Please help me explore our data:\n\
{datasource_section}\n\
Environment: {environment}\n\
Contact: {contactInfo}\n\n\
{watermark}
Custom Query Optimization Prompt
prompts.druid-query-optimization.template=Query Performance Analysis for {organizationName}\n\n\
Query to optimize: {query}\n\n\
Please provide:\n\
1. Performance bottleneck analysis\n\
2. Optimization recommendations\n\
3. Best practices for our {environment} environment\n\n\
{watermark}
Disabling Specific Prompts
You can disable individual prompts by setting their enabled flag to false:
mcp.prompts.data-exploration.enabled=false
mcp.prompts.query-optimization.enabled=false
Or disable all prompts globally:
mcp.prompts.enabled=false
MCP Integration
This server uses Spring AI's MCP Server framework and supports both STDIO and SSE transports. The tools, resources, and prompts are automatically registered and exposed through the MCP protocol.
Transport Modes
The Druid MCP Server supports multiple transport modes compliant with MCP 2025-06-18 specification:
Streamable HTTP Transport (Recommended)
The new Streamable HTTP transport provides enhanced performance and scalability with support for multiple concurrent clients:
# Default configuration with Streamable HTTP

java -Dspring.profiles.active=http \
     -jar target/druid-mcp-server-2.0.1.jar
# Server available at http://localhost:8080/mcp (configurable endpoint)
Features:
- Single Endpoint: One HTTP endpoint handles both POST and GET requests
- Multiple Clients: Support for concurrent client connections
- Optional SSE Streaming: Server-Sent Events for real-time updates
- Enhanced Security: Origin header validation and authentication
- Backwards Compatibility: Automatic fallback for older MCP clients
- Keep-alive: Configurable connection health monitoring
Security
- The Streamable HTTP and SSE modes are secured with OAuth by default. Your MCP client must obtain and send a valid bearer token when connecting.
- For enterprise SSO integration (OpenID Connect, Azure AD, Keycloak, etc.), please send an inquiry to consulting@iunera.com and see Contact & Support.
STDIO Transport (Command-line Integration)
Perfect for LLM clients and desktop applications:
java -jar target/druid-mcp-server-2.0.1.jar
Legacy SSE Transport (Deprecated)
Still supported for backwards compatibility. It is no longer the default and may be removed in a future version.
Note: The SSE endpoint is secured with OAuth by default. Clients must include a valid bearer token when connecting. For SSO integration support, see Contact & Support.
Metrics Collection
To enhance the product and understand usage patterns, this server collects anonymous usage metrics. This data helps prioritize new features and improvements. You can opt-out of anonymous metrics collection by setting the druid.mcp.metrics.enabled to `false.
🐳 Development Druid Installation
For local development, testing, and learning, a complete Docker Compose setup for running a full Apache Druid cluster is available at iunera/druid-local-cluster-installer.
This setup is the recommended way to get a Druid cluster running for use with this MCP server.
Key Features:
- Complete Druid Cluster: Includes all core Druid services (Coordinator, Broker, Historical, MiddleManager, Router).
- One-Command Install: Automated scripts for macOS, Linux, and Windows.
- Cross-Platform: Runs anywhere Docker is available.
- Pre-configured: Sensible defaults for local development.
- Basic Security Enabled: Pre-configured admin user (
admin/password). - Ready for Ypipe: Designed to work out-of-the-box with
iunera/ypipe.
Related Projects
This Druid MCP Server is part of a comprehensive ecosystem of Apache Druid tools and extensions developed by iunera. These complementary projects enhance different aspects of Druid cluster management and data ingestion:
🔧 Druid Cluster Configuration
Advanced configuration management and deployment tools for Apache Druid clusters. This project provides:
- Automated Cluster Setup: Streamlined configuration templates for different deployment scenarios
- Configuration Management: Best practices and templates for production Druid clusters
- Deployment Automation: Tools and scripts for consistent cluster deployments
- Environment-Specific Configs: Optimized configurations for development, staging, and production environments
Integration with Druid MCP Server: The cluster configurations provided by this project work seamlessly with the monitoring and management capabilities of the Druid MCP Server, enabling comprehensive cluster lifecycle management.
📊 Code Ingestion Druid Extension
A specialized Apache Druid extension for ingesting and analyzing code-related data and metrics. This extension enables:
- Code Metrics Ingestion: Specialized parsers for code analysis data and software metrics
- Developer Analytics: Tools for analyzing code quality, complexity, and development patterns
- CI/CD Integration: Seamless integration with continuous integration and deployment pipelines
- Custom Data Formats: Support for various code analysis tools and formats
Integration with Druid MCP Server: This extension expands the ingestion capabilities that can be managed through the MCP server's ingestion management tools, providing specialized support for code analytics use cases.
Why Use These Together?
- Complete Ecosystem: From cluster setup to specialized data ingestion and management
- Consistent Architecture: All projects follow similar design principles and integration patterns
- Enhanced Capabilities: Each project extends different aspects of the Druid ecosystem
- Production Ready: Battle-tested configurations and extensions for enterprise deployments
Roadmap
- Druid Auto Compaction: Intelligent automatic compaction configuration
- MCP Auto Completion: Enhanced autocomplete functionality with sampling using McpComplete
- MCP Notifications: Real-time notifications for MCP operations
- Proper Observability: Comprehensive metrics and tracing
- Enhanced Monitoring: Advanced cluster monitoring and alerting capabilities
- Advanced Analytics: Machine learning-powered insights and recommendations
- Kubernetes Support: Proper deployment on Kubernetes
About iunera
This Druid MCP Server is developed and maintained by iunera, a leading provider of advanced AI and data analytics solutions.
iunera specializes in:
- AI-Powered Analytics: Cutting-edge artificial intelligence solutions for data analysis
- Enterprise Data Platforms: Scalable data infrastructure and analytics platforms (Druid, Flink, Kubernetes, Kafka, Spring)
- Model Context Protocol (MCP) Solutions: Advanced MCP server implementations for various data systems
- Custom AI Development: Tailored AI solutions for enterprise needs
As veterans in Apache Druid iunera deployed and maintained a large number of solutions based on Apache Druid in productive enterprise grade scenarios.
Need Expert Apache Druid Consulting?
Maximize your return on data with professional Druid implementation and optimization services. From architecture design to performance tuning and AI integration, our experts help you navigate Druid's complexity and unlock its full potential.
Need Enterprise MCP Server Development Consulting?
ENTERPRISE AI INTEGRATION & CUSTOM MCP (MODEL CONTEXT PROTOCOL) SERVER DEVELOPMENT
Iunera specializes in developing production-grade AI agents and enterprise-grade LLM solutions, helping businesses move beyond generic AI chatbots. They build secure, scalable, and future-ready AI infrastructure, underpinned by the Model Context Protocol (MCP), to connect proprietary data, legacy systems, and external APIs to advanced AI models.
Get Enterprise MCP Server Development Consulting →
For more information about our services and solutions, visit www.iunera.com.
examples/ypipe/README.md
Ypipe Integration Blueprint for Apache Druid
This folder contains the integration blueprint and configuration details for using this Druid MCP Server within Ypipe.
Ypipe is an AI-powered desktop client that lets you interact with your Apache Druid cluster in natural language, running models locally and securely.
What is druid.ypipe?
The druid.ypipe file is a predefined MCP Integration Blueprint (McpIntegrationBlueprint). It specifies how Ypipe should configure, run, and communicate with the Druid MCP Server. It details:
- Environment variables (e.g.,
DRUID_ROUTER_URL,DRUID_AUTH_USERNAME,DRUID_AUTH_PASSWORD) needed for connection. - Service specifications to auto-build or download the server and map port options.
- Client schemas to facilitate smooth communication.
Screenshots
Below is the visual flow of the Druid MCP Integration inside Ypipe:
1. Integration Workspace Flow
This screenshot shows the workflow layout and integration nodes within the Ypipe dashboard.

2. Druid Node Details
This screenshot shows the configuration panel for the Apache Druid integration node in Ypipe, showing the host URL and authentication parameters.

How to Use
- Ensure you have Ypipe installed.
- Import or reference the druid.ypipe blueprint in your Ypipe configuration directory.
- Configure your Druid connection details (such as your router URL and basic credentials) through the visual node setup in the Ypipe interface.
- Interact with your Druid cluster using natural language chat, tools, resources, and custom prompts!
examples/stdio/README.md
STDIO Examples (JBang & Docker)
This folder contains examples for running the Druid MCP Server with the STDIO transport. These examples are designed to be used by MCP clients (e.g., Claude Desktop) that spawn the server process and communicate over STDIO.
Option 1: Running with JBang (Recommended)
JBang is the easiest way to run the server as it automatically manages the Java environment and downloads the required version.
Quick use with MCP client
Point your MCP client to this config file:
The JBang configuration in that file allows the client to start the server directly using the Maven GAV.
Direct JBang run (optional)
export DRUID_ROUTER_URL=http://localhost:8888
export DRUID_AUTH_USERNAME=admin
export DRUID_AUTH_PASSWORD=password
jbang druid-mcp-server@iunera/druid-mcp-server
Option 2: Running with Docker
Docker is a great alternative if you prefer containerized execution.
Quick use with MCP client
Point your MCP client to this config file:
Direct Docker run (optional)
If your client does not support spawning via config, you can also run the server manually and point the client to the spawned process (stdin/stdout attached):
docker run --rm -i \
  -e DRUID_ROUTER_URL=http://host.docker.internal:8888 \
  -e DRUID_COORDINATOR_URL=http://host.docker.internal:8081 \
  -e DRUID_AUTH_USERNAME=admin \
  -e DRUID_AUTH_PASSWORD=password \
  iunera/druid-mcp-server:2.0.1
Tip: Replace DRUID_ROUTER_URL and add DRUID_AUTH_USERNAME/DRUID_AUTH_PASSWORD and TLS flags when connecting to a secured Druid.
examples/streamable-http/README.md
Streamable HTTP (Docker) Examples
This folder contains Docker-focused examples for running the Druid MCP Server with the Streamable HTTP transport (MCP 2025-06-18). Clients connect over HTTP to a single /mcp endpoint.
We focus on environment variable configuration. No Java/JAR commands are required.
Quick use with MCP client
Point your MCP client to this config file:
This tells your client to connect to the Streamable HTTP endpoint. You must run the server container separately (see below).
Optional: Enable OAuth2 protection
- Start the server with OAuth2 enabled:
docker run --rm -p 8080:8080 \
  -e SPRING_PROFILES_ACTIVE=http \
  -e DRUID_ROUTER_URL=http://host.docker.internal:8888 \
  -e DRUID_COORDINATOR_URL=http://host.docker.internal:8081 \
  -e DRUID_AUTH_USERNAME=admin \
  -e DRUID_AUTH_PASSWORD=password \
  iunera/druid-mcp-server:2.0.1
- Obtain a token using client-credentials grant (default client:
oidc-client/secret):
export MCP_OAUTH_TOKEN=$(curl -s -XPOST "http://localhost:8080/oauth2/token" \
  --data grant_type=client_credentials \
  --user "oidc-client:secret" | jq -r ".access_token")
The provided mcpservers-streamable-http.json will forward the token using the Authorization: Bearer header.
Streamable HTTP endpoint will be available at:
Adjust -p 8080:8080 if you need a different port.
FAQ
Common questions
Discussion
Questions & comments · 0
Sign In Sign in to leave a comment.