
Extract text and structure from images and PDFs via OCR
PaddleOCR's MCP server exposes OCR, layout parsing, and VLM-based document conversion as three tools, with local, cloud, and self-hosted inference.
3.7.0Add to Favorites
Why it matters
Extract text, tables, formulas, and layout structure from images and PDF documents using PaddleOCR's recognition models, enabling AI applications to process visual documents and convert them into editable formats like Markdown, Word, or Excel.
Outcomes
What it gets done
Recognize and extract text from handwritten notes, scanned documents, and images
Parse document layouts to identify titles, paragraphs, tables, and images
Convert complex PDFs with tables and formulas into editable Markdown or structured formats
Process multilingual documents using PP-OCRv5, PP-OCRv6, or VLM-based models
Source
Get it from source
Spark does not host a copy of it.
Open sourceReports
Agent outcome reports
No reports yet
Capabilities
Tools your agent gets
Performs text detection and recognition on images and PDF files.
Identifies and extracts text blocks, titles, paragraphs, images, tables from images or PDFs, converting to Markdown.
Performs layout parsing with VLM-based approach and converts input into Markdown documents.
Overview
PaddleOCR
The PaddleOCR MCP server exposes PaddleOCR's OCR, layout parsing, and document-conversion pipelines as three MCP tools: ocr, pp_structurev3, and paddleocr_vl. It supports four inference backends, local, PaddleOCR's Official API, Baidu's Qianfan API, and a self-hosted PaddleOCR serving instance, selected via the PADDLEOCR_MCP_PPOCR_SOURCE environment variable. Known limitations include no support for Base64-encoded PDFs under local inference and higher token usage when image content is returned by PP-StructureV3 or PaddleOCR-VL. Use it when an MCP host needs to pull text, tables, formulas, or handwritten content out of images and PDFs into Markdown or other editable formats. Local inference does not accept Base64-encoded PDF input, and returning image content from PP-StructureV3 or PaddleOCR-VL raises token usage, so exclude image content via prompts when it isn't needed.
What it does
PaddleOCR's MCP server is a lightweight Model Context Protocol server that exposes PaddleOCR's text recognition, layout parsing, and document-conversion capabilities to MCP hosts such as Claude for Desktop. It ships three tools tied to specific model families: ocr (PP-OCRv5, PP-OCRv5-latin, PP-OCRv6) performs text detection and recognition on images and PDFs; pp_structurev3 (PP-StructureV3) identifies text blocks, titles, paragraphs, images, and tables and converts the input into Markdown; paddleocr_vl (PaddleOCR-VL, PaddleOCR-VL-1.5, PaddleOCR-VL-1.6) performs VLM-based layout parsing and also converts input into Markdown. Inference can run four ways: local, PaddleOCR's Official API, Baidu AI Cloud's Qianfan API, or a self-hosted PaddleOCR serving instance, selected with the PADDLEOCR_MCP_PPOCR_SOURCE environment variable.
When to use - and when NOT to
Use it when an MCP host needs to turn images or PDFs containing text, tables, formulas, or handwriting into structured Markdown, editable documents, or spreadsheets: documented use cases include note-to-Notion transcription, handwritten pseudocode converted to runnable Python, and PDF-to-Word or image-to-Excel conversion. Do NOT assume every model works on every inference source: the Qianfan API supports only PP-StructureV3 and PaddleOCR-VL, not PP-OCRv5/PP-OCRv6, and the self-hosted API currently supports only the basic PaddleOCR serving solution. If image content isn't needed in the output, exclude it via prompts, since PP-StructureV3 and PaddleOCR-VL responses that include images can significantly increase token usage.
Capabilities
- Three MCP tools (
ocr,pp_structurev3,paddleocr_vl) covering plain OCR, layout-aware document parsing, and VLM-based document conversion. - Four inference sources:
local,aistudio(Official API),qianfan(Qianfan API), andself_hosted, each configured throughPADDLEOCR_MCP_MODELandPADDLEOCR_MCP_PPOCR_SOURCE. - A CLI (
paddleocr_mcp) that also supports Streamable HTTP transport via--http,--host, and--portfor remote deployment and multiple clients, in addition to the default stdio transport. - For local inference, the pipeline configuration can be tuned to disable unused features (such as formula, seal, table, or chart recognition) or swap in lightweight
mobilemodels to cut inference time and memory use. - Known limitations: local inference can't process Base64-encoded PDFs, it doesn't infer file type from the model's
file_typeprompt for some complex URLs, and returning image content from PP-StructureV3 or PaddleOCR-VL can significantly increase token usage.
How to install
Requires Python 3.10 or later.
pip install -U paddleocr-mcp
Local inference needs the optional paddleocr-mcp[local] or paddleocr-mcp[local-cpu] extras; Official API, Qianfan API, and self-hosted modes need no extra PaddleOCR install. Verify the install with paddleocr_mcp --help. It can also run without installation via uvx. Configure the server through PADDLEOCR_MCP_MODEL (defaults to "PP-OCRv6") and PADDLEOCR_MCP_PPOCR_SOURCE (defaults to "local"), plus source-specific variables such as PADDLEOCR_MCP_AISTUDIO_ACCESS_TOKEN, PADDLEOCR_MCP_QIANFAN_API_KEY, or PADDLEOCR_MCP_SELF_HOSTED_BASE_URL.
Who it's for
Teams building MCP-connected apps that need document and image understanding, extracting text, tables, formulas, or handwriting from images and PDFs. PaddleOCR's Official API suits quick, no-code experimentation and solution validation; local inference suits offline use and strict data-privacy needs; and self-hosted inference suits deployments that need customized service configuration alongside that same data-privacy bar.
Source README
PaddleOCR MCP Server


PaddleOCR provides a lightweight Model Context Protocol (MCP) server designed to integrate PaddleOCR’s text recognition, layout parsing, and other capabilities into various large-model applications.
Key features include:
Currently Supported Models
Model MCP tool name Description PP-OCRv5,PP-OCRv5-latin,PP-OCRv6ocrPerforms text detection and recognition on images and PDF files. PP-StructureV3pp_structurev3Identifies and extracts text blocks, titles, paragraphs, images, tables, and other layout elements from images or PDF files, converting the input into Markdown documents. PaddleOCR-VL,PaddleOCR-VL-1.5,PaddleOCR-VL-1.6paddleocr_vlPerforms layout parsing with a VLM-based approach and converts the input into Markdown documents. Supported Inference Methods
- Local Inference: Runs PaddleOCR pipelines directly on the local machine. This method has certain requirements for the local environment and hardware performance, and is suitable for offline use and scenarios with strict data privacy requirements.
- Official API: Invokes the PaddleOCR Official API. This method is suitable for quickly trying out features, validating solutions, and other no-code development scenarios.
- Qianfan API: Calls the API provided by Baidu AI Cloud's Qianfan platform.
- Self-hosted API: Invokes the user's self-hosted PaddleOCR inference service. This method offers serving advantages and high flexibility, suitable for scenarios requiring customized service configurations, as well as those with strict data privacy requirements. Currently, only the basic serving solution is supported.
Examples:
The following showcases creative use cases built with the PaddleOCR MCP server combined with other tools:
Demo 1
In Claude for Desktop, extract handwritten content from images and save to note-taking software Notion. The PaddleOCR MCP server extracts text, formulas and other information from images while preserving document structure.
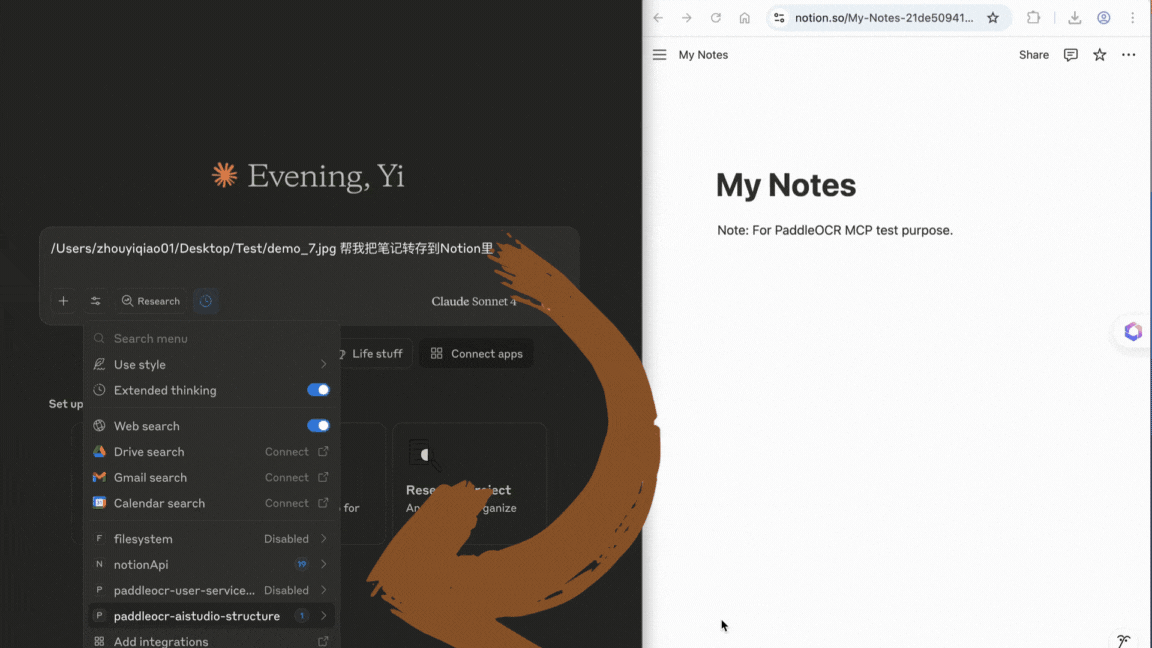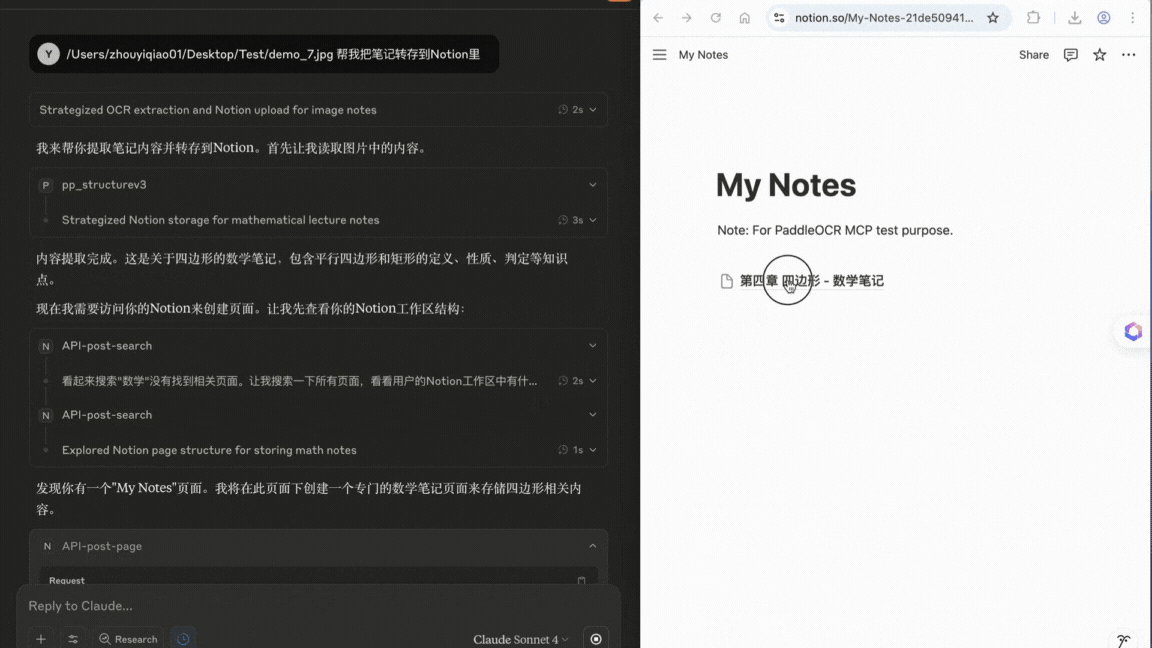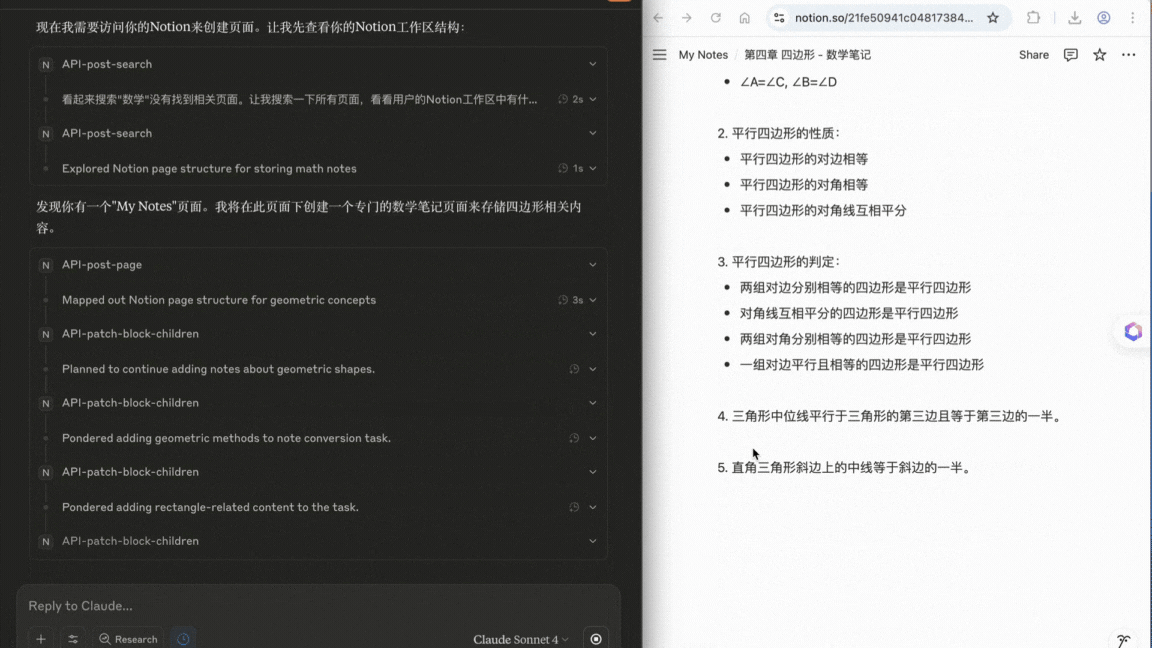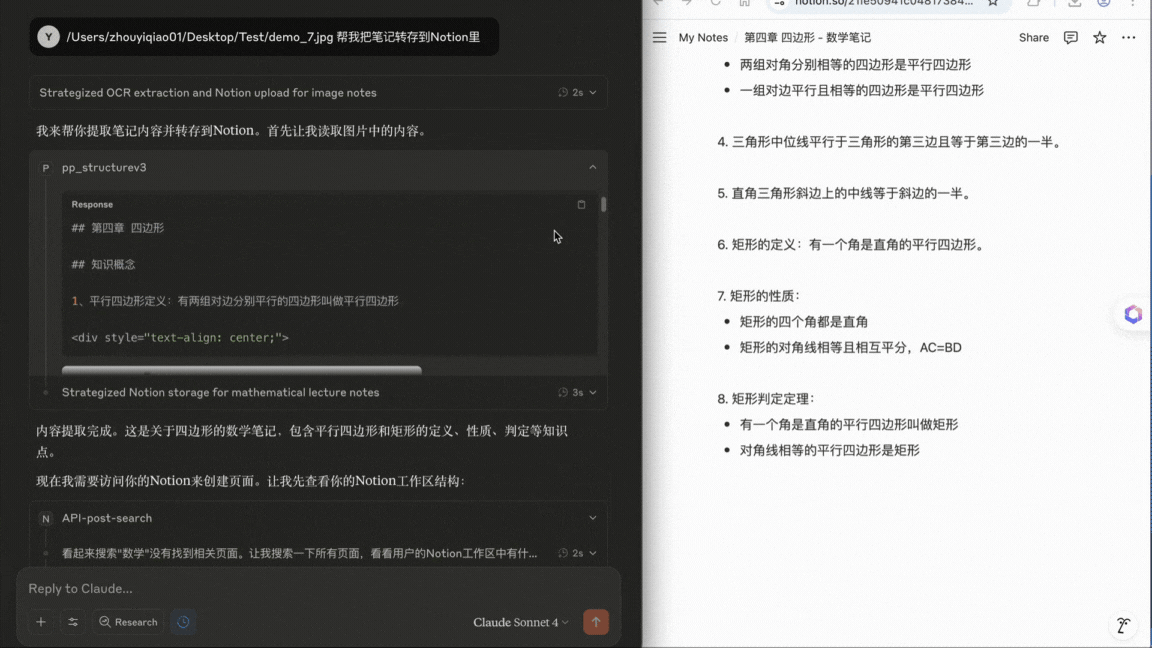
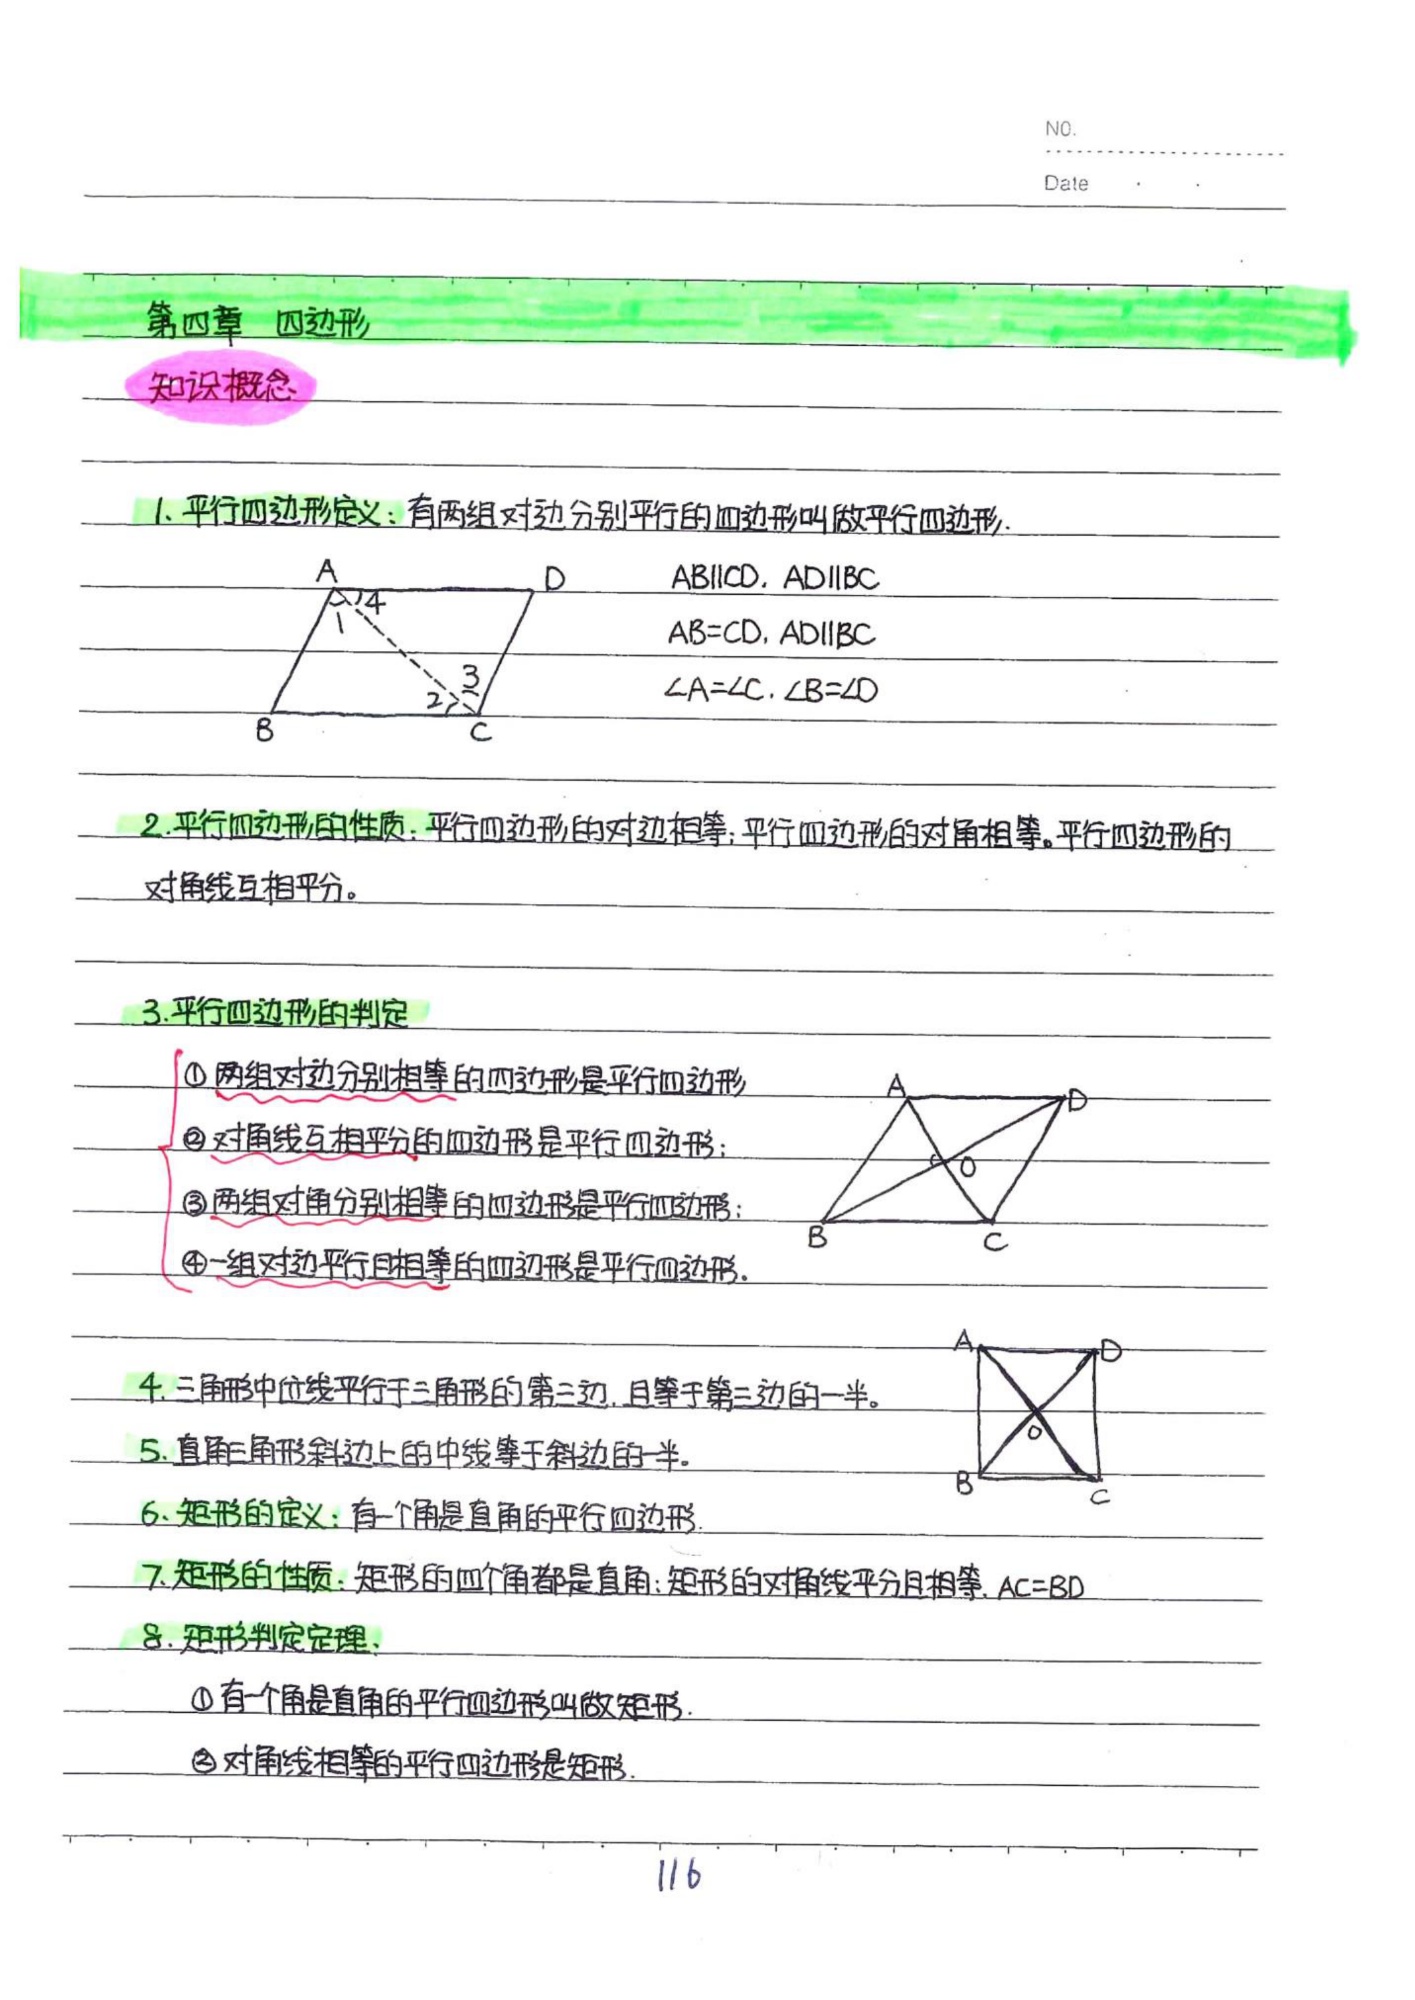
- Note: In addition to the PaddleOCR MCP server, this demo also uses the Notion MCP server.
Demo 2
In VSCode, convert handwritten ideas or pseudocode into runnable Python scripts that comply with project coding standards with one click, and upload them to GitHub repositories. The PaddleOCR MCP server extracts explicitly handwritten code from images for subsequent processing.
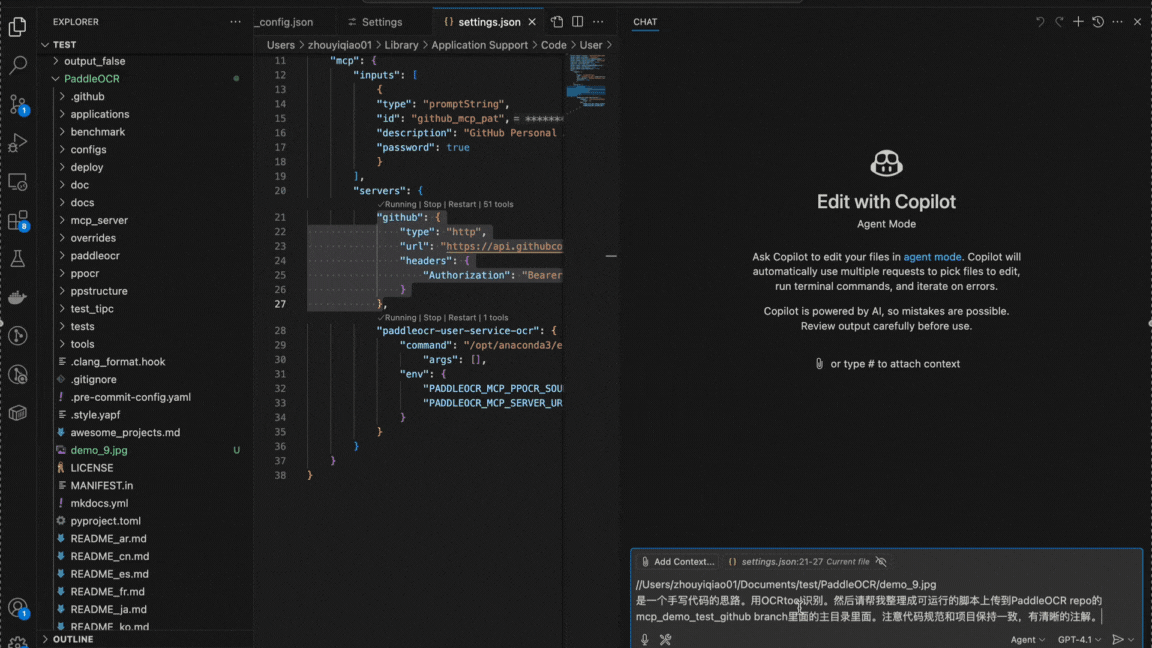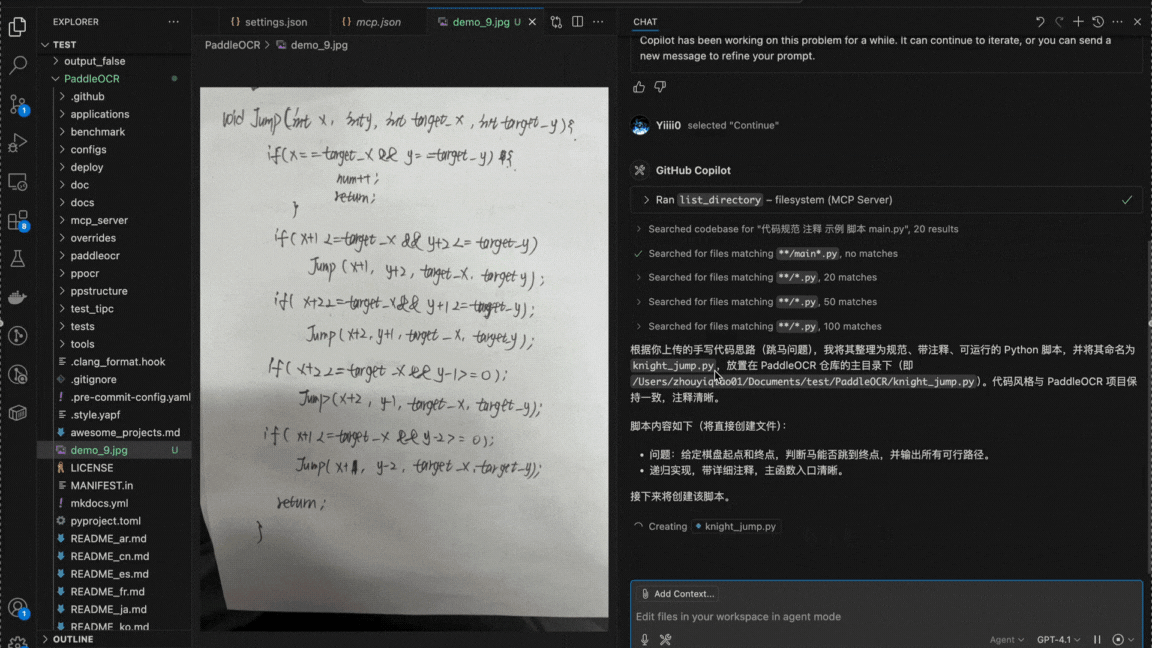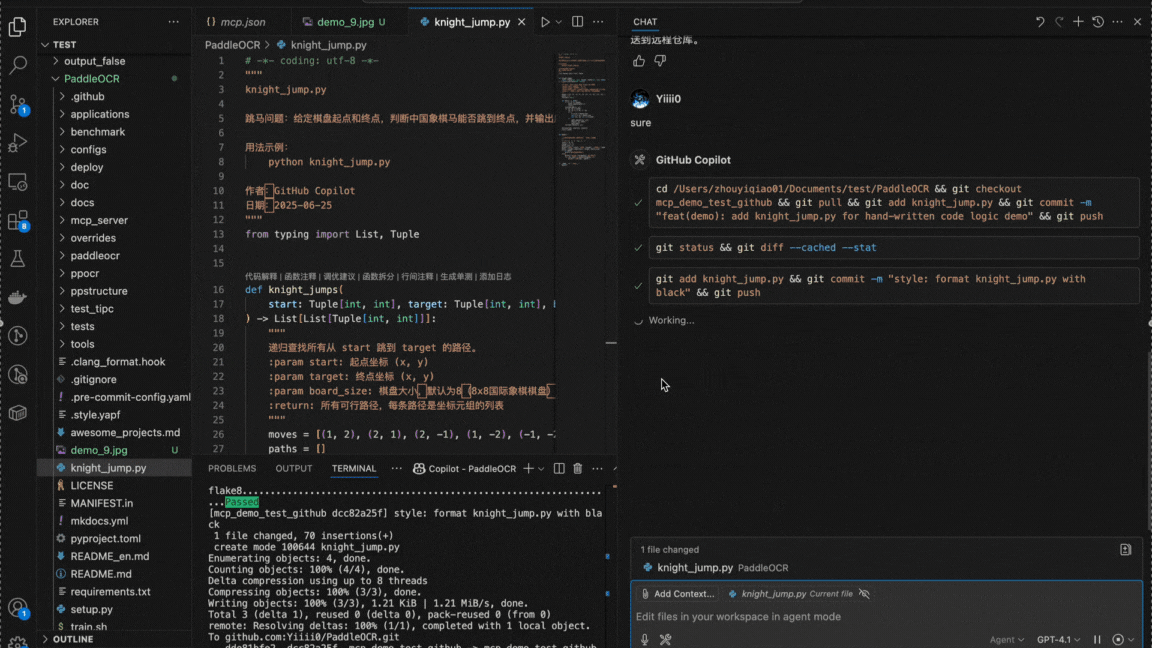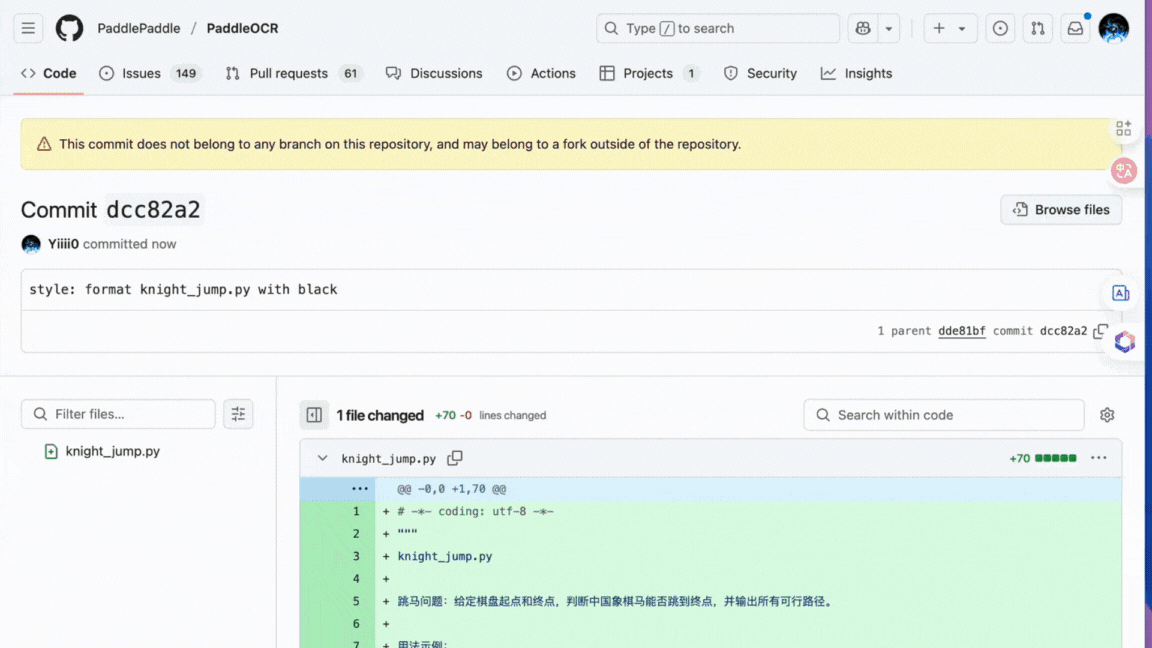
- In addition to the PaddleOCR MCP server, this demo also uses the filesystem MCP server.
Demo 3
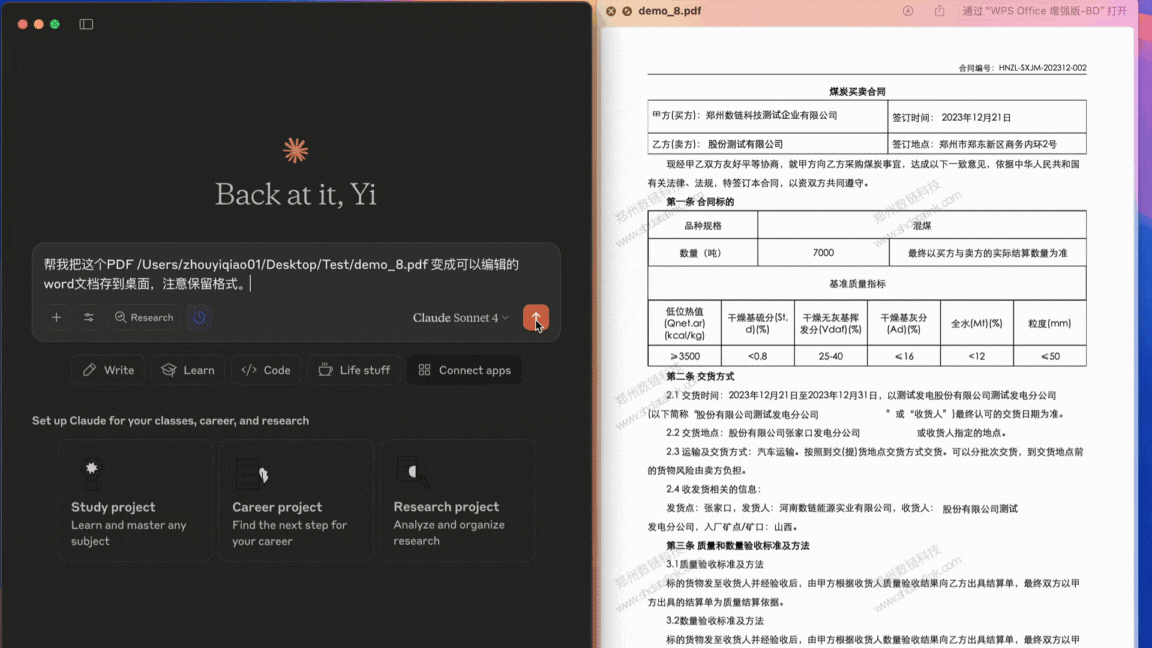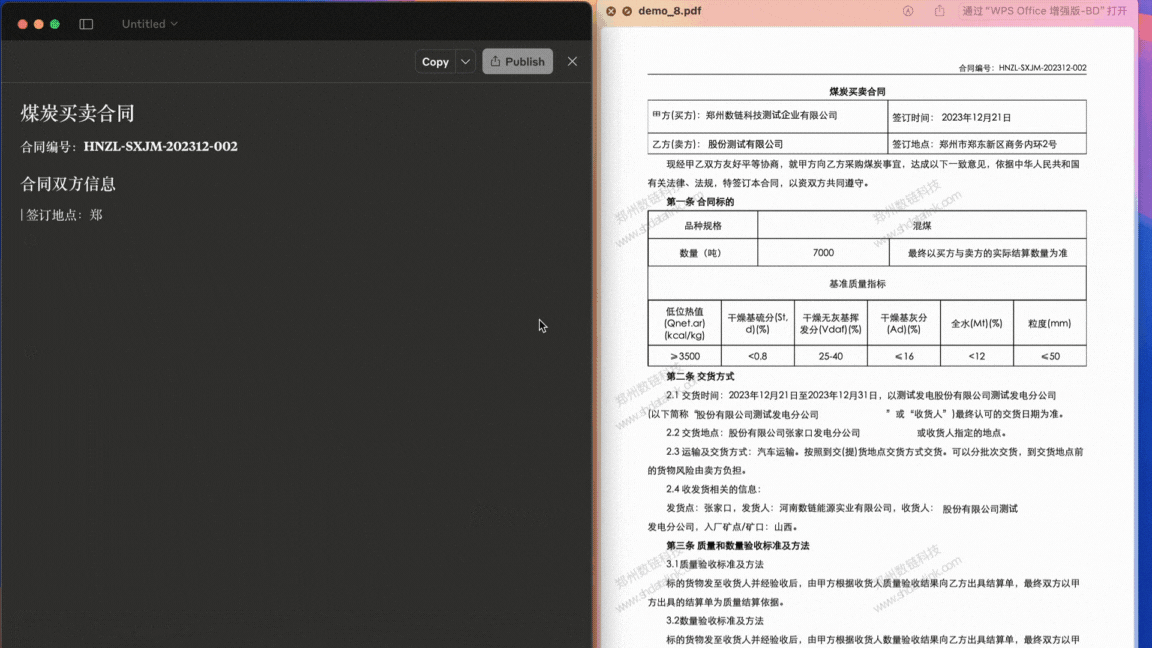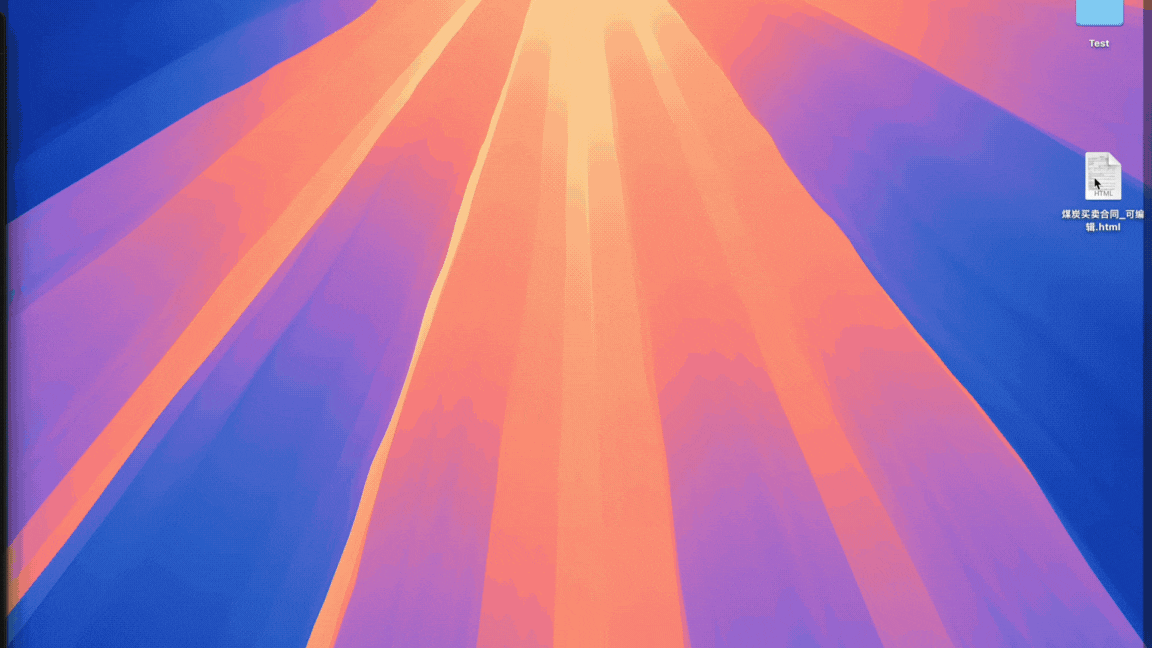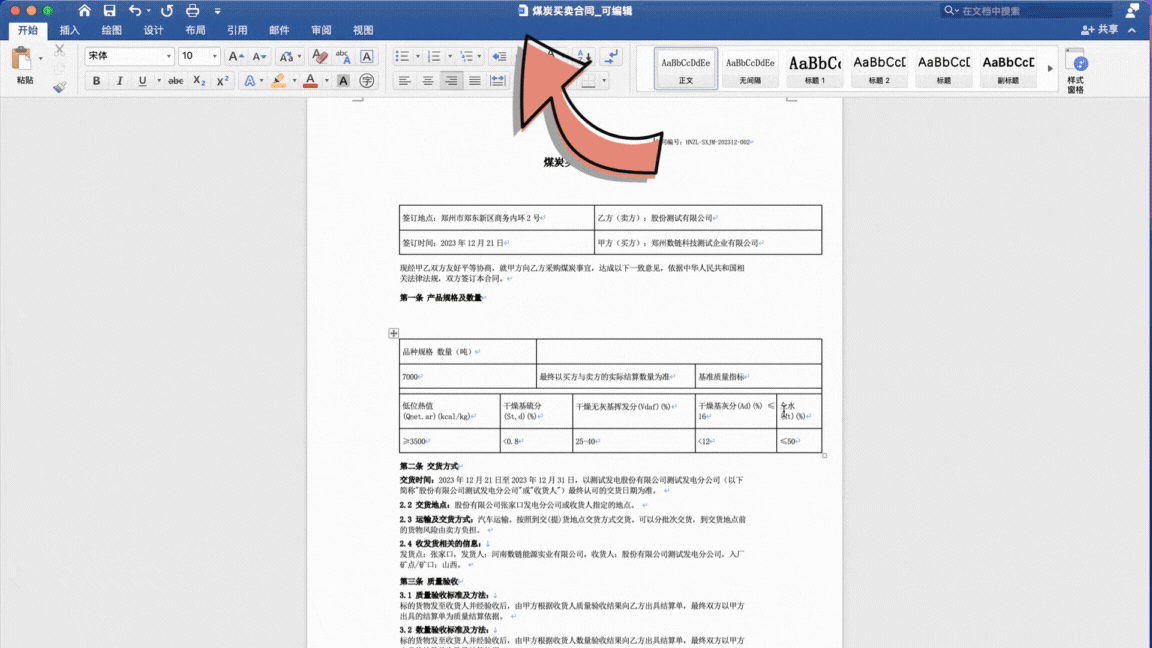
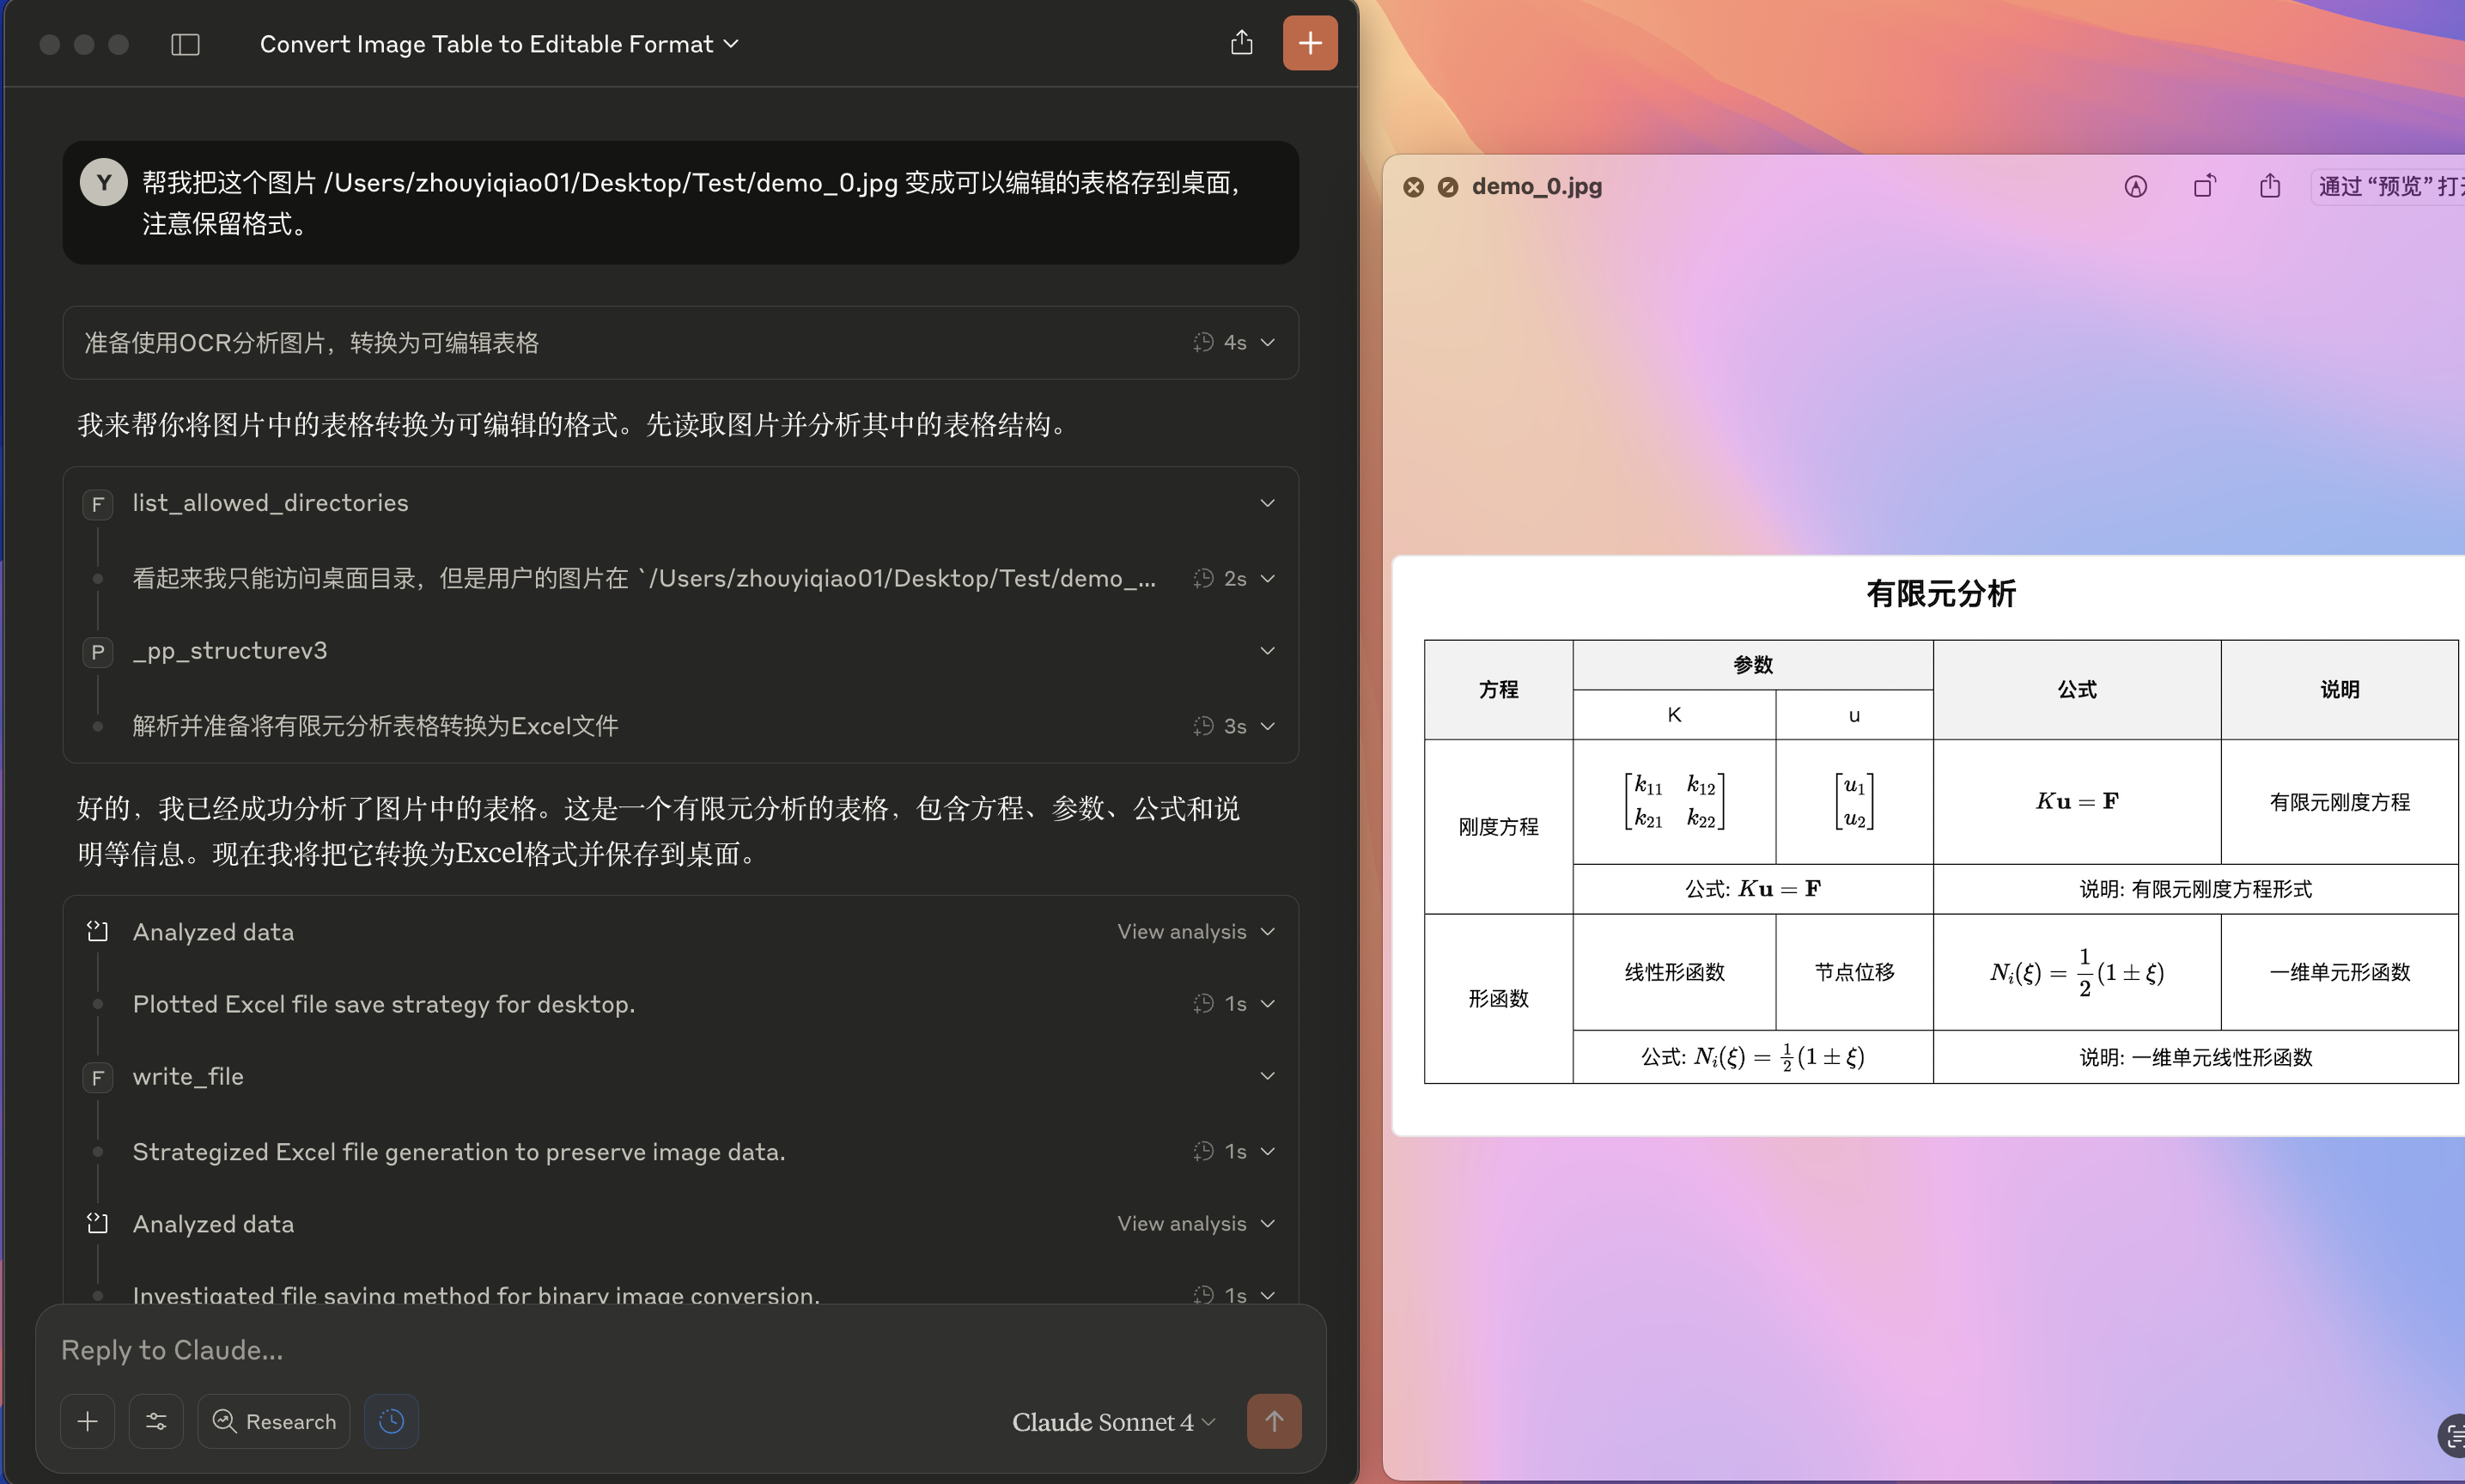
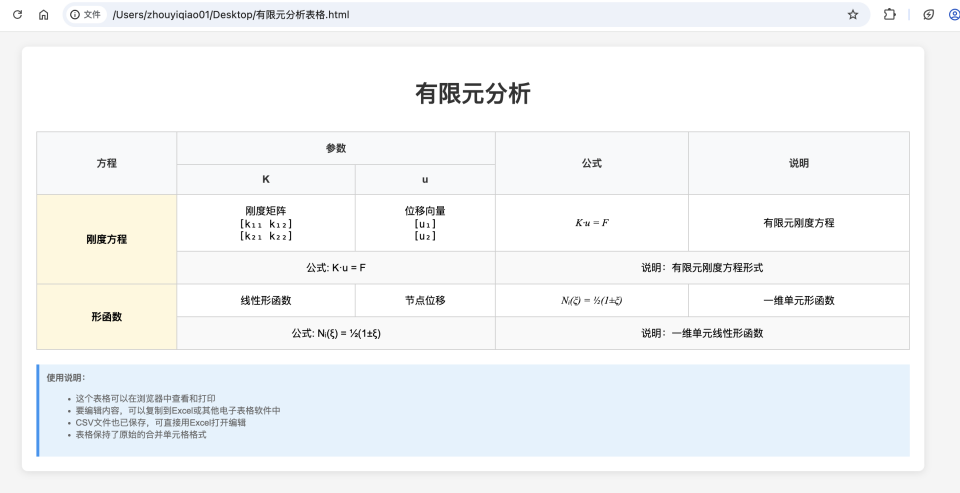
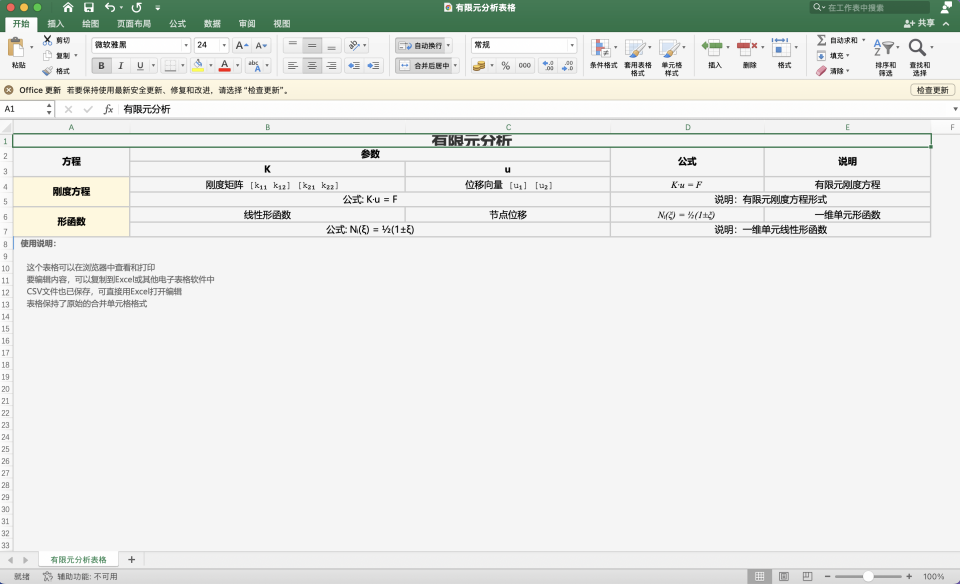
In Claude for Desktop, convert PDF documents or images containing complex tables, formulas, handwritten text and other content into locally editable files.
Demo 3.1
Convert complex PDF documents with tables and watermarks to editable doc/Word format:
Demo 3.2
Convert images containing formulas and tables to editable csv/Excel format:
- In addition to the PaddleOCR MCP server, this demo also uses the filesystem MCP server.
Table of Contents
- Table of Contents
- 1. Installation
- 2. Using with Claude for Desktop
- 3. Running the Server
- 4. Parameter Reference
- 5. Known Limitations
1. Installation
This section explains how to install the paddleocr-mcp library via pip.
paddleocr-mcp requires Python 3.10 or later.paddleocr-mcp depends on paddleocr>=3.7.0 by default, so Official API, Qianfan API, and self-hosted API modes do not require installing PaddleOCR separately. Local inference additionally requires the document-parsing dependencies and an inference engine required to run PaddleOCR pipelines locally; see Method 1: Local Inference for details.
Install from PyPI:
pip install -U paddleocr-mcp
Install from source:
git clone https://github.com/PaddlePaddle/PaddleOCR.git
pip install -e mcp_server
For local inference, install the optional extras described in Method 1: Local Inference.
To verify successful installation:
paddleocr_mcp --help
If help information is printed after running the command above, the installation succeeded.
PaddleOCR also supports running the server without installation through methods like uvx; for details, see 2. Using with Claude for Desktop.
2. Using with Claude for Desktop
This section explains how to use the PaddleOCR MCP server within Claude for Desktop. The steps are also applicable to other MCP hosts with minor adjustments.
2.1 Quick Start
The following quick start uses Official API inference as an example to get you started.
Install
paddleocr-mcpRefer to 1. Installation.
Obtain an Access Token
Obtain your access token from the AI Studio Access Token page.
Add MCP Server Configuration
Locate the
claude_desktop_config.jsonconfiguration file:- macOS:
~/Library/Application Support/Claude/claude_desktop_config.json - Windows:
%APPDATA%\Claude\claude_desktop_config.json - Linux:
~/.config/Claude/claude_desktop_config.json
Open the
claude_desktop_config.jsonfile, adjust the configuration according to the example below, and fill it intoclaude_desktop_config.json.{ "mcpServers": { "paddleocr": { "command": "paddleocr_mcp", "args": [], "env": { "PADDLEOCR_MCP_MODEL": "PP-OCRv5", "PADDLEOCR_MCP_PPOCR_SOURCE": "aistudio", "PADDLEOCR_MCP_AISTUDIO_ACCESS_TOKEN": "<your-access-token>" } } } }Notes:
- Replace
<your-access-token>with your access token. - To use a custom service address, set the
PADDLEOCR_MCP_AISTUDIO_BASE_URLenvironment variable.
Important:
- Do not expose your access token.
- If
paddleocr_mcpis not in your system'sPATH, setcommandto the absolute path of the executable.
- macOS:
Restart the MCP Host
Restart Claude for Desktop. The
paddleocrserver should now be available in the application.
2.2 MCP Host Configuration Details
In the configuration file for Claude for Desktop, you need to define how the MCP server is started. The key fields are as follows:
command:paddleocr_mcp(if the executable can be found in thePATH) or the absolute path.args: Configurable command-line arguments, such as["--verbose"]. See 4. Parameter Reference for details.env: Configurable environment variables. See 4. Parameter Reference for details.
2.3 Inference Methods
You can configure the MCP server according to your requirements to use different inference methods. The operational procedures vary for different methods, which will be explained in detail below.
Method 1: Local Inference {#method-1-local-inference}
Install
paddleocr-mcpand the local inference dependencies.paddleocr-mcpalready depends on PaddleOCR; local inference additionally requires the document-parsing dependencies and an inference engine. You can install them manually by referring to the PaddleOCR installation guide, or use the corresponding optional dependencies:paddleocr-mcp[local]: includespaddleocr[doc-parser]>=3.7.0(without the inference engine).paddleocr-mcp[local-cpu]: based onlocal, additionally includes the CPU PaddlePaddle inference engine (paddlepaddle>=3.2.1).
# Install document-parsing dependencies for local inference (inference engine not included):
pip install "paddleocr-mcp[local]"
# Install the CPU PaddlePaddle framework in addition to local:
pip install "paddleocr-mcp[local-cpu]"
To avoid dependency conflicts, it is strongly recommended to install in an isolated virtual environment.
Refer to the configuration example below to modify the
claude_desktop_config.jsonfile.Restart the MCP host.
Configuration example:
{
  "mcpServers": {
    "paddleocr": {
      "command": "paddleocr_mcp",
      "args": [],
      "env": {
        "PADDLEOCR_MCP_MODEL": "PP-OCRv5",
        "PADDLEOCR_MCP_PPOCR_SOURCE": "local"
      }
    }
  }
}
Notes:
PADDLEOCR_MCP_MODELshould be set to the model name. See Section 4 for details.PADDLEOCR_MCP_PIPELINE_CONFIGis optional. If not set, the default pipeline configuration is used. To adjust the configuration, such as changing models, refer to the PaddleOCR documentation to export the pipeline configuration file, and setPADDLEOCR_MCP_PIPELINE_CONFIGto the absolute path of this file.Inference Performance Tips:
If you encounter long inference time or insufficient memory, consider adjusting the pipeline configuration:
PP-StructureV3 Pipeline:
- Disable unused features, such as setting
use_formula_recognitiontoFalseto disable formula recognition. - Use lightweight models, such as replacing the OCR model with the
mobileversion or switching to a lightweight formula recognition model like PP-FormulaNet-S.
The following sample code exports a PP-StructureV3 pipeline configuration with most optional features disabled and some key models replaced with lightweight versions.
from paddleocr import PPStructureV3 pipeline = PPStructureV3( use_doc_orientation_classify=False, # Disable document image orientation classification use_doc_unwarping=False, # Disable text image unwarping use_textline_orientation=False, # Disable text line orientation classification use_formula_recognition=False, # Disable formula recognition use_seal_recognition=False, # Disable seal text recognition use_table_recognition=False, # Disable table recognition use_chart_recognition=False, # Disable chart parsing # Use lightweight models text_detection_model_name="PP-OCRv5_mobile_det", text_recognition_model_name="PP-OCRv5_mobile_rec", layout_detection_model_name="PP-DocLayout-S", ) # The configuration file is saved to `PP-StructureV3.yaml` pipeline.export_paddlex_config_to_yaml("PP-StructureV3.yaml")- Disable unused features, such as setting
For PaddleOCR-VL series, CPU inference is not recommended.
Method 2: Official API
Refer to 2.1 Quick Start.
For tasks other than text recognition, set PADDLEOCR_MCP_MODEL correctly (see Section 4 for parameter details).
Method 3: Qianfan API
- Install
paddleocr-mcp. - Obtain an API key by referring to the Qianfan Platform Official Documentation.
- Refer to the configuration example below to modify the
claude_desktop_config.jsonfile. - Restart the MCP host.
Configuration example:
{
  "mcpServers": {
    "paddleocr": {
      "command": "paddleocr_mcp",
      "args": [],
      "env": {
        "PADDLEOCR_MCP_MODEL": "PaddleOCR-VL",
        "PADDLEOCR_MCP_PPOCR_SOURCE": "qianfan",
        "PADDLEOCR_MCP_QIANFAN_API_KEY": "<your-api-key>"
      }
    }
  }
}
Notes:
PADDLEOCR_MCP_MODELshould be set to the model name. Qianfan supports onlyPP-StructureV3andPaddleOCR-VL.PADDLEOCR_MCP_QIANFAN_BASE_URLis the Qianfan API base URL (optional).PADDLEOCR_MCP_QIANFAN_API_KEYis your Qianfan API key for authentication.
Method 4: Self-hosted API
- In the environment where you need to run the PaddleOCR inference server, refer to the PaddleOCR serving documentation to run the inference server.
- Install
paddleocr-mcpin the environment where you need to run the MCP server. - Refer to the configuration example below to modify the
claude_desktop_config.jsonfile. - Restart the MCP host.
Configuration example:
{
  "mcpServers": {
    "paddleocr": {
      "command": "paddleocr_mcp",
      "args": [],
      "env": {
        "PADDLEOCR_MCP_MODEL": "PP-OCRv5",
        "PADDLEOCR_MCP_PPOCR_SOURCE": "self_hosted",
        "PADDLEOCR_MCP_SELF_HOSTED_BASE_URL": "<your-server-url>"
      }
    }
  }
}
Notes:
PADDLEOCR_MCP_MODELshould be set to the model name. See Section 4 for details.- Replace
<your-server-url>with the underlying service base URL (e.g.http://127.0.0.1:8080, without path suffixes such as/ocror/layout-parsing; MCP appends them by pipeline).
2.4 Using uvx
PaddleOCR also supports starting the MCP server via uvx. With this approach, manual installation of paddleocr-mcp is not required. The main steps are as follows:
- Install uv.
- Modify
claude_desktop_config.json. Examples:
Self-hosted API inference example:
{
  "mcpServers": {
   "paddleocr": {
    "command": "uvx",
    "args": [
      "--from",
      "paddleocr-mcp",
      "paddleocr_mcp"
    ],
    "env": {
      "PADDLEOCR_MCP_MODEL": "PP-OCRv5",
      "PADDLEOCR_MCP_PPOCR_SOURCE": "self_hosted",
      "PADDLEOCR_MCP_SELF_HOSTED_BASE_URL": "<your-server-url>"
    }
   }
  }
}
Local inference (CPU inference, using the optional local-cpu extra) example:
{
  "mcpServers": {
   "paddleocr": {
    "command": "uvx",
    "args": [
      "--from",
      "paddleocr-mcp[local-cpu]",
      "paddleocr_mcp"
    ],
    "env": {
      "PADDLEOCR_MCP_MODEL": "PP-OCRv5",
      "PADDLEOCR_MCP_PPOCR_SOURCE": "local"
    }
   }
  }
}
For local inference dependencies, performance tuning, and pipeline configuration, refer to Method 1: Local Inference.
Due to the use of a different startup method, the command and args settings in the configuration file differ from the previously described approach. However, the command-line arguments and environment variables supported by the MCP service (such as PADDLEOCR_MCP_SELF_HOSTED_BASE_URL) can still be set in the same way.
3. Running the Server
In addition to MCP hosts like Claude for Desktop, you can also run the PaddleOCR MCP server via the CLI.
Run the following command to print help information:
paddleocr_mcp --help
Example commands:
# PP-OCRv5 + Official API + stdio
PADDLEOCR_MCP_AISTUDIO_ACCESS_TOKEN=xxxxxx paddleocr_mcp --model PP-OCRv5 --ppocr_source aistudio

# PP-OCRv6 + Official API + stdio
paddleocr_mcp --model PP-OCRv6 --ppocr_source aistudio

# PP-StructureV3 + Local Inference + stdio
paddleocr_mcp --model PP-StructureV3 --ppocr_source local

# OCR + Self-hosted API + Streamable HTTP
paddleocr_mcp --model PP-OCRv5 --ppocr_source self_hosted --self-hosted-base-url http://127.0.0.1:8080 --http
See 4. Parameter Reference for all parameters supported by the PaddleOCR MCP server.
4. Parameter Reference
You can control the MCP server via environment variables or CLI arguments.
| Environment Variable | CLI Argument | Type | Description | Options | Default |
|---|---|---|---|---|---|
PADDLEOCR_MCP_MODEL |
--model |
str |
Model to run. MCP selects the tool automatically from the model. | "PP-OCRv5", "PP-OCRv5-latin", "PP-OCRv6", "PP-StructureV3", "PaddleOCR-VL", "PaddleOCR-VL-1.5", "PaddleOCR-VL-1.6" |
"PP-OCRv6" |
PADDLEOCR_MCP_PPOCR_SOURCE |
--ppocr_source |
str |
Source of PaddleOCR capabilities. | "local" (local inference), "aistudio" (Official API), "qianfan" (Qianfan API), "self_hosted" (self-hosted API) |
"local" |
PADDLEOCR_MCP_AISTUDIO_BASE_URL |
--aistudio-base-url |
str |
AI Studio API base URL (optional for aistudio source). |
- | None |
PADDLEOCR_MCP_QIANFAN_BASE_URL |
--qianfan-base-url |
str |
Qianfan API base URL (optional for qianfan source). |
- | https://qianfan.baidubce.com/v2/ocr |
PADDLEOCR_MCP_SELF_HOSTED_BASE_URL |
--self-hosted-base-url |
str |
Self-hosted PaddleX serve base URL (required for self_hosted source). |
- | None |
PADDLEOCR_MCP_QIANFAN_API_KEY |
--qianfan_api_key |
str |
Qianfan API authentication key (required for qianfan source). |
- | None |
PADDLEOCR_MCP_AISTUDIO_ACCESS_TOKEN |
--aistudio_access_token |
str |
AI Studio access token (required for aistudio source). |
- | None |
PADDLEOCR_MCP_HTTP_TIMEOUT |
--http-timeout |
int |
HTTP read timeout in seconds for synchronous APIs (qianfan, self_hosted). |
- | 600 |
PADDLEOCR_MCP_AISTUDIO_REQUEST_TIMEOUT |
--aistudio-request-timeout |
int |
Per-request HTTP timeout in seconds for AI Studio API calls (job submission, status checks, etc.). | - | 120 |
PADDLEOCR_MCP_AISTUDIO_POLL_TIMEOUT |
--aistudio-poll-timeout |
int |
Total job polling timeout in seconds for AI Studio. | - | 600 |
PADDLEOCR_MCP_DEVICE |
--device |
str |
Device for inference (only effective for local source). |
- | None |
PADDLEOCR_MCP_PIPELINE_CONFIG |
--pipeline_config |
str |
PaddleOCR pipeline configuration file path (only effective for local source). |
- | None |
| - | --http |
bool |
Use Streamable HTTP transport instead of stdio (for remote deployment and multiple clients). | - | False |
| - | --host |
str |
Host address for Streamable HTTP mode. | - | "127.0.0.1" |
| - | --port |
int |
Port for Streamable HTTP mode. | - | 8000 |
| - | --verbose |
bool |
Enable verbose logging for debugging. | - | False |
5. Known Limitations
- Under local inference, the exposed MCP tool cannot process PDF document inputs that are Base64 encoded.
- Under local inference, the exposed MCP tool does not infer file type from the model's
file_typeprompt; some complex URLs may fail to process. - For the PP-StructureV3 and PaddleOCR-VL series, if the input file contains images, the returned results may significantly increase token usage. If image content is not needed, you can explicitly exclude it through prompts to reduce resource consumption.
FAQ
Common questions
Discussion
Questions & comments · 0
Sign In Sign in to leave a comment.